News for hackers. Stuff that matters.
Re:Meta Llama 3 by bbig on Thursday April 18, 2024 @12:06PM (#40077643)
They've got a console for it as well, https://www.meta.ai/

And announcing a lot of integration across the Meta product suite, https://about.fb.com/news/2024/04/meta-ai-assistant-built-wi...

Neglected to include comparisons against GPT-4-Turbo or Claude Opus, so I guess it's far from being a frontier model. We'll see how it fares in the LLM Arena.

Re:Meta Llama 3 by CuriouslyC on Thursday April 18, 2024 @12:22PM (#40077832)
They didn't compare against the best models because they were trying to do "in class" comparisons, and the 70B model is in the same class as Sonnet (which they do compare against) and GPT3.5 (which is much worse than sonnet). If they're beating sonnet that means they're going to be within stabbing distance of opus and gpt4 for most tasks, with the only major difference probably arising in extremely difficult reasoning benchmarks.

Since llama is open source, we're going to see fine tunes and LoRAs though, unlike opus.

Re:Meta Llama 3 by observationist on Thursday April 18, 2024 @12:35PM (#40078025)
https://github.com/meta-llama/llama3/blob/main/LICENSE

Llama is not open source. It's corporate freeware with some generous allowances.

Open source licenses are a well defined thing. Meta marketing saying otherwise doesn't mean they get to usurp the meaning of a well understood and commonly used understanding of the term "open source."

https://opensource.org/license

Nothing about Meta's license is open source. It's a carefully constructed legal agreement intended to prevent any meaningful encroachment by anyone, ever, into any potential Meta profit, and to disavow liability to prevent reputational harm in the case of someone using their freeware for something embarrassing.

If you use it against the license anyway, you'll just have to hope you never get successful enough that it becomes more profitable to sue you and take your product away than it would be annoying to prosecute you under their legal rights. When the threshold between annoying and profitable is crossed, Meta's lawyers will start sniping and acquiring users of their IP.

Re:Meta Llama 3 by jph00 on Thursday April 18, 2024 @01:11PM (#40078449)
> "Nothing about Meta's license is open source. It's a carefully constructed legal agreement intended to prevent any meaningful encroachment by anyone, ever, into any potential Meta profit, and to disavow liability to prevent reputational harm in the case of someone using their freeware for something embarrassing."

You seem to be making claims that have little connection to the actual license.

The license states you can't use the model if, at the time Llama 3 was released, you had >700 million customers. It also says you can't use it for illegal/military/etc uses. Other than that, you can use it as you wish.

Re:Meta Llama 3 by wantsanagent on Thursday April 18, 2024 @02:08PM (#40079013)
That "etc" is doing a lot of work here. The point of OSI licenses like MIT, Apache 2.0 is to remove the "etc". The licensing company gives up its right to impose acceptable use policies. More restrictive, but still OSI approved, licenses are as clear as they possibly can be about allowed uses and the language is as unambiguous as possible. Neither is the case for the Llama AUP.
Re:Meta Llama 3 by simonw on Thursday April 18, 2024 @01:35PM (#40078669)
Those additional restrictions mean it's not an open source license by the OSI definition, which matters if you care about words sometimes having unambiguous meanings.

I call models like this "openly licensed" but not "open source licensed".

Re:Meta Llama 3 by jph00 on Thursday April 18, 2024 @01:55PM (#40078864)
The OSI definition applies to source code -- I'm not sure the term "open source" makes much sense applied to model weights.

Whilst I agree the term isn't ideal, I don't agree with the other comments in the post I originally replied to.

Re:Meta Llama 3 by HarHarVeryFunny on Thursday April 18, 2024 @07:44PM (#40081910)
Call it what you will, but it'd be silly if Meta let these 700M+ customer mega-corps (Amazon, Google, etc) just take Meta models and sell access to them without sharing revenue with Meta.

You should be happy that Meta find ways to make money from their models, otherwise it's unlikely that they'd be giving you free access (until your startup reaches 700M+ customers, when the free ride ends).

Re:Meta Llama 3 by krisoft on Thursday April 18, 2024 @08:33PM (#40082216)
> until your startup reaches 700M+ customers, when the free ride ends

No it doesn’t. The licence terms talk about that those who on the release date of llama3 had 700M+ customers need an extra licence to use it. It doesn’t say that you loose access to it if in the future you gain that many users.

Re:Meta Llama 3 by HarHarVeryFunny on Thursday April 18, 2024 @08:51PM (#40082346)
You don't lose access, but the free ride ends. It seems that new licence will include payment terms. Zuckerberg discusses this on the Dwarkesh interview.
Re:Meta Llama 3 by krisoft on Thursday April 18, 2024 @09:10PM (#40082455)
What does the “free ride ends” mean? If you mean you can’t use the next model they might release after you have reached that many users, sure that might be true. It is not true that you have to pay for the already released llama 3.

I don’t care what Zuckerberg says. I care what the licence says. I recommend you to read it. It is shorter and more approachable than the usual rental agreement of a flat.

Re:Meta Llama 3 by HarHarVeryFunny on Thursday April 18, 2024 @09:50PM (#40082710)
Here is the relevant Llama 3 license section, below, in it's entirety. It says that if you have 700M+ users then you'll need a new license, which Meta may or may not choose to grant to you. It does not say what the terms of that new license will be, but if you are interested you can watch the Dwarkesh interview, or just believe me when I tell you that Zuck said it'll be a commercial license - you will pay.

**

2. Additional Commercial Terms. If, on the Meta Llama 3 version release date, the monthly active users of the products or services made available by or for Licensee, or Licensee’s affiliates, is greater than 700 million monthly active users in the preceding calendar month, you must request a license from Meta, which Meta may grant to you in its sole discretion, and you are not authorized to exercise any of the rights under this Agreement unless or until Meta otherwise expressly grants you such rights.

Re:Meta Llama 3 by RexM on Thursday April 18, 2024 @10:36PM (#40082935)
It seems pretty clear cut that it’s monthly active users when Llama 3 is released.

> If, on the Meta Llama 3 version release date, the monthly active users … is greater than 700 million monthly active users in the preceding calendar month …

If that’s not true then the free license applies to you.

Re:Meta Llama 3 by simonw on Thursday April 18, 2024 @11:59PM (#40083310)
What happens if your startup is in negotiations to be acquired by a company that had more than 700m users before that date?
Re:Meta Llama 3 by krisoft on Friday April 19, 2024 @04:59AM (#40084643)
Now that I would argue puts you at a risk!
Re:Meta Llama 3 by HarHarVeryFunny on Friday April 19, 2024 @07:42AM (#40085567)
Presumably megacorp's laywers are engaged with you doing due diligence before the acquisition, will be looking into this, and evaluating the license. Maybe they have prior licensing agreements with Meta, or plan to replace your use of Llama with something different, who knows.

OTOH if you are being acquired by Elon Musk, then there may be no due diligence, he will tear up any existing license agreements, spend the next year bickering with Meta on Twitter, then be sued to comply.

Re:Meta Llama 3 by krisoft on Friday April 19, 2024 @05:32AM (#40084794)
> Here is the relevant Llama 3 license section, below, in it's entirety.

I agree too that this is the relevant section.

> It says that if you have 700M+ users then you'll need a new license

It does not say that. It says that if you or your affiliate had 700M+ users on the day of llama3's release date then you need an other licence.

This does not trigger if you just gain 700M+ users. Simply it does not. It does trigger if you become affiliated by someone who in that past date already had 700M+ (for example if google buys you up, or if you become a strategic partner of google).

The key here is "on the Meta Llama 3 version release date" which sets the exact date for when the monthly active users of the products or services should be counted.

> It does not say what the terms of that new license will be

Correct. And I assume the terms would be highly onerous. That I do not dispute.

> or just believe me when I tell you that Zuck said it'll be a commercial license

I believe you on that. That is not what we disagree on. The bit we seem to disagree on is when exactly do you need this extra licence. You state that you need it if your company gains in a future date 700M+ users. That is simply not supported by the very section you quoted above.

Re:Meta Llama 3 by HarHarVeryFunny on Friday April 19, 2024 @07:49AM (#40085625)
In practice this isn't a matter of how you or I interpret this license - it's a matter of how watertight it is legally.

There's no reason to suppose that terms of any commercial licensing agreement would be onerous. At this stage at least these models are all pretty fungible and could be swapped out without much effort, so Meta would be competing with other companies for your business, if they want it. If they don't want your business (e.g. maybe you're a FaceBook competitor), then they have reserved right not to license it to you.

In any case, don't argue it with me. In practice this would be your lawyers engaged with Meta and their lawyers, and product licensing team.

Re:Meta Llama 3 by krisoft on Friday April 19, 2024 @12:24PM (#40088744)
> In any case, don't argue it with me

No argument here. You can either read it or you can't. :)

Re:Meta Llama 3 by HarHarVeryFunny on Friday April 19, 2024 @02:36PM (#40090463)
I can read it, and I can also see the holes in it.
Re:Meta Llama 3 by boppo1 on Thursday April 18, 2024 @09:55PM (#40082739)
>You should be happy that Meta find ways to make money from their models,

I am, this is unambiguously great. Just don't call it open source.

Re:Meta Llama 3 by pama on Friday April 19, 2024 @12:04AM (#40083328)
Isn’t a simple interpretation of this type of license that some people get the open source license and others get the commercial license? Almost like a switch statement for licenses. If you belong in the category that gets the commercial one, you cannot call it open source for sure, but if you belong to the other category then it seems like an open source license to me. There is no guarantee about future licenses, and some (reasonable) restrictions but all open source licenses have some terms attached.
Re:Meta Llama 3 by mensetmanusman on Thursday April 18, 2024 @07:25PM (#40081789)
That's convenient because I only have 699,999,999 customers.
Re:Meta Llama 3 by xyproto on Thursday April 18, 2024 @08:08PM (#40082056)
Simultaneously.
Re:Meta Llama 3 by asadotzler on Thursday April 18, 2024 @11:03PM (#40083074)
any scale restrictions plus the "etc." means it's not open source.
Re:Meta Llama 3 by freehorse on Thursday April 18, 2024 @03:24PM (#40079820)
What are the practical use cases where the license prohibits people from using llama models? There are plenty of startups and companies that already build their business on llamas (eg phind.com). I do not see the issues that you assume exist.

If you get that successful that you cannot use it anymore (have 10% of earth's population as clients) probably you can train your own models already.

Re:Meta Llama 3 by aurbxyajwur on Sunday April 28, 2024 @10:45AM (#40188970)
The license prohibits Snap from using it. Meta knows that it would be useful to Snap and that they don’t have the resources to train their own model.
Re:Meta Llama 3 by CuriouslyC on Thursday April 18, 2024 @12:44PM (#40078135)
Models are mostly fungible, if meta decided to play games it's not too hard to switch models. I think this is mostly a CYA play.
Re:Meta Llama 3 by robertlagrant on Thursday April 18, 2024 @12:40PM (#40078093)
What is "source" regarding an LLM? Public training data and initial parameters?
Re:Meta Llama 3 by blackeyeblitzar on Thursday April 18, 2024 @12:59PM (#40078321)
See this discussion and blog post about a model called OLMo from AI2 (https://news.ycombinator.com/item?id=39974374). They try to be more truly open, although here are nuances even with them that make it not fully open. Just like with open source software, an open source model should provide everything you need to reproduce the final output, and with transparency. That means you need the training source code, the data sets, the evaluation suites, the inference code, and more.

Most of these other models, like Llama, are open weight not open source - and open weight is just openwashing, since you’re just getting the final output like a compiled executable. But even with OLMo (and others like Databrick’s DBRX) there are issues with proprietary licenses being used for some things, which prevent truly free use. For some reason in the AI world there is heavy resistance to using OSI-approved licenses like Apache or MIT.

Finally, there is still a lack of openness and transparency on the training data sets even with models that release those data sets. This is because they do a lot of filtering to produce those data sets that happen without any transparency. For example AI2’s OLMo uses a dataset that has been filtered to remove “toxic” content or “hateful” content, with input from “ethics experts” - and this is of course a key input into the overall model that can heavily bias its performance, accuracy, and neutrality.

Unfortunately, there is a lot missing from the current AI landscape as far as openness.

Re:Meta Llama 3 by sunandcoffee on Thursday April 18, 2024 @02:31PM (#40079272)
what are you thoughts on projects like these: https://www.llm360.ai/

seems like they make everything available.

Re:Meta Llama 3 by observationist on Thursday April 18, 2024 @12:51PM (#40078227)
The parameters and the license. Mistral uses Apache 2.0, a neatly permissive open source license. As such, it's an open source model.

Models are similar to code you might run on a compiled vm or native operating system. Llama.cpp is to a model as Python is to a python script. The license lays out the rights and responsibilities of the users of the software, or the model, in this case. The training data, process, pipeline to build the model in the first place is a distinct and separate thing from the models themselves. It'd be nice if those were open, too, but when dealing with just the model:

If it uses an OSI recognized open source license, it is an open source model. If it doesn't use an OSI recognized open source license, it's not.

Llama is not open source. It's corporate freeware.

Re:Meta Llama 3 by littlestymaar on Thursday April 18, 2024 @01:59PM (#40078907)
Mistral is not “open source” either since we cannot reproduce it (the training data is not published). Both are open weight models, and they are both released under a license whose legal basis is unclear: it's not actually clear if they own any intellectual property over the model at all. Of course they claim such IP, but no court has ruled on this yet AFAIK and legislators could also enact laws that make these public domain altogether.
Re:Meta Llama 3 by jiggawatts on Thursday April 18, 2024 @04:56PM (#40080628)
Is “reproducibility” actually the right term here?

It’s a bit like arguing that Linux is not open source because you don’t have every email Linus and the maintainers ever received. Or that you don’t know what lectures Linus attended or what books he’s read.

The weights “are the thing” in the same sense that the “code is the thing”. You can modify open code and recompile it. You can similarly modify weights with fine tuning or even architectural changes. You don’t need to go “back to the beginning” in the same sense that Linux would continue to be open source even without the Git history and the LKM mailing list.

Re:Meta Llama 3 by littlestymaar on Thursday April 18, 2024 @05:09PM (#40080748)
> It’s a bit like arguing that Linux is not open source because you don’t have every email Linus and the maintainers ever received. Or that you don’t know what lectures Linus attended or what books he’s read.

Linux is open source, because you can actually compile it yourself! You don't need Linus's email for that (and if you needed some secret cryptographic key on Linus' laptop to decrypt and compile the kernel, then it wouldn't make sense to call it open-source either).

A language model isn't a piece of code, it's a huge binary blob that's being executed by a small piece of code that contains little of the added value, everything that matters is in the blob. Sharing only the compiled blob and the code to run makes it unsuitable for an “open source qualifier” (It's kind of the same thing as proprietary Java code: the VM is open-source but the bytecode you run on it isn't).

And yes, you can fine-tune and change things in the model weights themselves the same way you can edit the binary of a proprietary game to disable DRMs, that doesn't make it open-source either. Fine tuning doesn't give you the same level of control over the behavior of the model as the initial training does, like binary hacking doesn't give you the same control as having the source code to edit and rebuild.

Re:Meta Llama 3 by mensetmanusman on Thursday April 18, 2024 @07:27PM (#40081802)
It's a blob that costs over $10,000,000 in electricity costs to compile. Even if they released everything only the rich could push go.
Re:Meta Llama 3 by soulofmischief on Thursday April 18, 2024 @07:46PM (#40081926)
There is an argument to be made about the importance of archeological preservation of the provenance of models, especially the first few important LLMs, for study by future generations.

In general, software rot is a huge issue, and many projects which may be of future archeological importance are increasingly non-reproducible as dependencies are often not vendored and checked into source, but instead downloaded at compile time from servers which lack strong guarantees about future availability.

Re:Meta Llama 3 by bschmidt1 on Thursday April 18, 2024 @11:04PM (#40083078)
This is comment is cooler than my Arctic Vault badge on GitHub.

Who were the countless unknown contemporaries of Giotto and Cimabue? Of Da Vinci and Michelangelo? Most of what we know about Renaissance art comes from 1 guy - Giorgio Vasari. We have more diverse information about ancient Egypt than the much more recent Italian Renaissance because of, essentially, better preservation techniques.

Compliance, interoperability, and publishing platforms for all this work (HuggingFace, Ollama, GitHub, HN) are our cathedrals and clay tablets. Who knows what works will fill the museums of tomorrow.

Re:Meta Llama 3 by HarHarVeryFunny on Thursday April 18, 2024 @07:52PM (#40081967)
In today's Dwarkesh interview, Zuckerberg talks about energy becoming a limit for future models before cost or access to hardware does. Apparently current largest datacenters consume about 100MW, but Zuck is considering future ones consuming 1GW which is the output of typical nuclear reactor!

So, yeah, unless you own your own world-class datacenter, complete with the nuclear reactor necessary to power the training run, then training is not an option.

Re:Meta Llama 3 by krisoft on Thursday April 18, 2024 @08:40PM (#40082264)
On a sufficiently large time scale the real limit on everything is energy. “Cost” and “access to hardware” are mere proxies for energy available to you. This is the idea behind the Kardashev scale.
Re:Meta Llama 3 by HarHarVeryFunny on Friday April 19, 2024 @02:26PM (#40090359)
A bit odd to see this downvoted... I'm not exactly a HN newbie, but still haven't fully grasped the reasons people often downvote here - simply not liking something (regardless of relevance or correctness) seems to often be the case, and perhaps sometimes even more petty reasons.

I think Zuck's discussion of energy being the limiting factor was one of the more interesting and surprising things to come out of the Dwarkesh interview. We're used to discussion of the $1B, $10B, $100B training runs becoming unsustainable, and chip shortages as an issue, but (to me at least!) it was interesting to see Zuck say that energy usage will be a disruptor before those do (partly because of lead times and regulations in expanding power supply, and bringing it in to new data centers). The sheer magnitude of projected power consumption needed is also interesting.

Re:Meta Llama 3 by robertlagrant on Saturday April 20, 2024 @05:23AM (#40095995)
There is an odd contingent or set of contingents on here that do seem to down vote by ideology rather than lack of facts or lack of courtesy. It's a bit of a shame, but I'm not sure there's much to be done.
Re:Meta Llama 3 by jiggawatts on Thursday April 18, 2024 @10:58PM (#40083059)
> the same way you can edit the binary of a proprietary game to disable DRMs, that doesn't make it open-source either

This is where I have to disagree. Continuing the training of an open model is the same process as the original training run. It's not a fundamentally different operation.

Re:Meta Llama 3 by littlestymaar on Friday April 19, 2024 @03:30AM (#40084249)
> Continuing the training of an open model is the same process as the original training run. It's not a fundamentally different operation.

In practice it's not (because LoRA) but that doesn't matter: continuing the training is just a patch on top of the initial training, it doesn't matter if this patch is applied through gradient descent as well, you are completely dependent on how the previous training was done, and your ability to overwrite the model's behavior is limited.

For instance, Meta could backdoor the model with specially crafted group of rare tokens to which the model would respond a pre-determined response (say “This is Llama 3 from Meta” as some kind of watermark), and you'd have no way to figure out and get rid of it during fine-tuning. This kind of things does not happen when you have access to the sources.

Re:Meta Llama 3 by jiggawatts on Friday April 19, 2024 @05:01AM (#40084654)
> (because LoRA)

That's one of many techniques, and is popular because it's cheap to implement. The training of a full model can be continued with full updates, the same as the original training run.

> completely dependent on how the previous training was done, and your ability to overwrite the model's behavior is limited.

Not necessarily. You can even alter the architecture! There have been many papers about various approaches such as extending token window sizes, or adding additional skip connections, quantization, sparsity, or whatever.

> specially crafted group of rare tokens

The analogy here is that some Linux kernel developer could have left a back door in the Linux kernel source. You're arguing that Linux would only be open source if you could personally go back to the time when it was an empty folder on Linus Torvald's computer and then reproduce every step it took to get to today's tarball of the source, including every Google search done, every book referenced, every email read, etc...

That's not what open source is. The code is open, not the process that it took to get there.

Linux development may have used information from copyrighted textbooks. The source code doesn't contain the text of those textbooks, and in some sense could not be "reproduced" without the copyrighted text.

Similarly, AIs are often trained on copyrighted textbooks but the end result is open source.

Re:Meta Llama 3 by littlestymaar on Friday April 19, 2024 @05:11AM (#40084700)
> Not necessarily. You can even alter the architecture!

You can alter the architecture, but you're still playing with an opaque blob of binary *you don't know what it's made of*.

> The analogy here is that some Linux kernel developer could have left a back door in the Linux kernel source. You're arguing that Linux would only be open source if you could personally go back to the time when it was an empty folder on Linus Torvald's computer and then reproduce every step it took to get to today's tarball of the source, including every Google search done, every book referenced, every email read, etc...

No, it is just a bad analogy. To be sure that there's no backdoor in the Linux kernel, the code itself suffice. That doesn't mean there can be no backdoor since it's complex enough to hide things in it, but it's not the same thing as a backdoor hidden in a binary blob you cannot inspect even if you had a trillion dollar to spend on a million of developers.

> The code is open, not the process that it took to get there.

The code is by definition a part of a process that gets you a piece of software (which is the actually useful binary), and it's the part of the process that contains most of the value. Model weights are binary, and they are akin to the compiled binary of the software (training from data being a compute-intensive like compilation from source code, but orders of magnitude more intensive).

> Similarly, AIs are often trained on copyrighted textbooks but the end result is open source.

Court decisions are pending on the mere legality of such training, and it has nothing to do with being open-source, what's at stake is whether or not these models can be open-weight or if it is copyright infringement to publish the models.

Re:Meta Llama 3 by touisteur on Thursday April 18, 2024 @04:58PM (#40080640)
I have a hard time about the "cannot reproduce" categorization.

There are places (e.g. in the Linux kernel? AMD drivers?) where lots of generated code is pushed and (apart from the rants of huge unwieldy commits and complaints that it would be better engineering-wise to get their hands on the code generator, it seems no one is saying the AMD drivers aren't GPL compliant or OSI-compliant?

There are probably lots of OSS that is filled with constants and code they probably couldn't rederive easily, and we still call them OSS?

Re:Meta Llama 3 by littlestymaar on Thursday April 18, 2024 @05:19PM (#40080833)
But with generated code what you end up with is still code, that can be edited by whoever needs. If AMD stopped maintaining their drivers then people would be maintaining the generated code, it wouldn't be a nice situation but it would work, whereas model weights are akin to the binary blobs you get in the Android world, binary blobs that nobody call open-source…
Re:Meta Llama 3 by pama on Friday April 19, 2024 @12:10AM (#40083359)
I personally think that the model artifacts are simply programs with tons of constants. Many math routines have constants in their approximations and I don’t expect the source to include the full derivation for these constants all the time. I see LLMs as a same category but with (much) larger sets of parameters. What is better about the LLMs than some of the mathematical constants in complicated function approximations, is that I can go and keep training an LLM whereas the math/engineering libraries might not make it easy for me to modify them without also figuring out the details that led to those particular parameter choices.
Re:Meta Llama 3 by J_cst on Thursday April 18, 2024 @12:48PM (#40078184)
Not an expert, but often weights are mentioned as not being open sourced. Happy to get corrected, as I'm not really sure.
Re:Meta Llama 3 by blackeyeblitzar on Thursday April 18, 2024 @01:07PM (#40078409)
Weights aren’t source because the goal of having open source software is that you can know how the software you’re consuming works, and you can produce the final software (the executable) using the source yourself. When you only have weights, you are getting something like the executable. Sure you can tweak it, but you don’t have the things you need to reproduce it or to examine how it works and validate it for your purposes. As such open weights are not in the spirit of open source.
Re:Meta Llama 3 by robertlagrant on Thursday April 18, 2024 @02:09PM (#40079023)
I don't think the previous commenter was saying that it's okay to only release the weights.
Re:Meta Llama 3 by PeterisP on Thursday April 18, 2024 @07:10PM (#40081708)
I think the proper way is to start the consideration from the perspective of what the user can do, for example, from the four freedoms of FSF (https://www.gnu.org/philosophy/free-sw.html.en#four-freedoms)

The starting point is the ability to run the LLM as you wish, for any purpose - so if a license prohibits some uses and you have to start any usage with thinking whether it's permitted or not, that's a fail.

Then the freedom where "source" matters is the practical freedom to change the behavior so it does your computing as you wish. And that's a bit tricky - since one interpretation would require having the training data, training code and parameters; but for current LLMs the training hardware and cost of running it is a major practical limitation, so much that one could argue that the ability to change the behavior (which is the core freedom that we'd like) is separate from the ability to recreate the model, and would be more relevant in the context of the "instruction training" which happens after the main training, is the main determiner of behavior (as opposed to capability), and so the main "source would be the data for that (instruct training data, and the model weights before that finetuning) so that you can fine-tune the model on different instructions, which requires much less resources than training it from scratch, and don't have to start with the instructions and values imposed on the LLM by someone else.

Re:Meta Llama 3 by tarruda on Thursday April 18, 2024 @12:48PM (#40078181)
> When the threshold between annoying and profitable is crossed, Meta's lawyers will start sniping and acquiring users of their IP.

I'm curious: given that the model will probably be hosted in a private server, how would meta know or prove that someone is using their model against the license?

Re:Meta Llama 3 by not2b on Thursday April 18, 2024 @12:57PM (#40078297)
If they can develop any evidence at all (perhaps from a whistleblower, perhaps from some characteristic unique to their model), they can sue and then there's they get to do "discovery", which would force the sued party to reveal details.
Re:Meta Llama 3 by stale2002 on Thursday April 18, 2024 @01:03PM (#40078358)
Yes or no, do you conceed that for almost everyone, none of what you said matters, and almost everyone can use llama 3 for their use case, and that basically nobody is going to have to worry about being sued, other than maybe like Google, or equivalent?

You are using all these scary words without saying the obvious, which is that for almost everyone, none of that matters.

Re:Meta Llama 3 by sebastiennight on Thursday April 18, 2024 @03:48PM (#40080005)
I don't support GP's claims, but you have to realize that you're "almost everyone" up until you build something very successful with lots of capital at stake, and then you definitely become "someone special" and have to think ahead about how the licenses of your models impact you.

Of course random individuals don't care much about the licenses on their personal AI projects. But if you intend to grow something significant, you better read the label from the start.

Re:Meta Llama 3 by oceanplexian on Thursday April 18, 2024 @10:13PM (#40082820)
Or you could out play nice and pay Meta for the privilege at the point you are on the radar? I mean 99% of YC startups out there are building their business on some kind of proprietary cloud API. The fact that you can even run this..on your own servers is a massive departure from the entire tech ecosystem of the last 10-12 years.
Re:Meta Llama 3 by EamonnMR on Thursday April 18, 2024 @03:50PM (#40080023)
Would you then say that in general Open Source doesn't matter for almost everyone? Most people running Linux aren't serving 700 million customers or operating military killbots with it after all.
Re:Meta Llama 3 by stale2002 on Thursday April 18, 2024 @04:49PM (#40080571)
> in general Open Source doesn't matter for almost everyone?

Most of the qualities that come with open source (which also come with llama 3), matter a lot.

But no, it is not a binary, yes or no thing, where something is either open source and useful or not.

Instead, there is a very wide spectrum is licensing agreements. And even if something does not fit the very specific and exact definition of open source, it can still be "almost" there and therefore be basically as useful.

I am objecting to the idea that any slight deviation from the highly specific definition of open source means that it no longer "counts".

Even though, If something is 99.9% the same as open source, then you get 99.9% of the benefits, and it is dishonest to say that it is significantly different than open source.

Re:Meta Llama 3 by BytesAndGears on Thursday April 18, 2024 @06:48PM (#40081560)
If I build a train, put it into service, and say to the passengers “this has 99.9% of the required parts from the design”, would you ride on that train? Would you consider that train 99.9% as good at being a train? Or is it all-or-nothing?

I don’t necessarily disagree with your point about there still being value in mostly-open software, but I want to challenge your notion that you still get most of the benefit. I think it being less than 100% open does significantly decay the value, since now you will always feel uneasy adopting these models, especially into an older existing company.

You can imagine a big legacy bank having no problem adopting MIT code in their tech. But something with an esoteric license? Even if it’s probably fine to use? It’s a giant barrier to their adoption, due to the risk to their business.

That’s also not to say I’m taking it for granted. I’m incredibly thankful that this exists, and that I can download it and use it personally without worry. And the huge advancement that we’re getting, and the public is able to benefit from. But it’s still not the same as true 100% open licensing.

Re:Meta Llama 3 by stale2002 on Thursday April 18, 2024 @07:06PM (#40081686)
> If I build a train, put it into service, and say to the passengers “this has 99.9% of the required parts from the design”, would you ride on that train?

Well if the missing piece is a cup holder on the train, yes absolutely! It would absolutely be as good as the binary "contains a cup holder" train design.

So the point stands. For almost everyone, these almost open source licenses are good enough for their usecase and the limitations apply to almost noone.

And you have chosen a wonderful example that exactly proves my point. In your example, the incorrect people are claiming that "99.9%" of a train is dangerous to ride in, while ignoring the fact that the missing .1% is the cup holders.

> You can imagine a big legacy bank

Fortunately, most people aren't running a big legacy bank. So the point stands, once again.

> It’s a giant barrier to their adoption

Only if you are at a big legacy bank, in your example, or similar. If you aren't in that very small percentage of the market, you are fine.

Re:Meta Llama 3 by bevekspldnw on Thursday April 18, 2024 @09:04PM (#40082426)
I don’t understand how the idea of open source become some sort of pseudo-legalistic purity test on everything.

Models aren’t code, some of the concepts of open source code don’t map 1:1 to freely available models.

In spirit I think this is “open source”, and I think that’s how the majority of people think.

Turning everything into some sort of theological debate takes away a lot of credit that Meta deserves. Google isn’t doing this. OpenAI sure as fuck isn’t.

Re:Meta Llama 3 by fragmede on Friday April 19, 2024 @12:09AM (#40083350)
> In spirit I think this is “open source”, and I think that’s how the majority of people think.

No, it isn't. You do, but, as evidenced by other comments, there's clearly people that don't. Thinking that you're with the majority and it's just a vocal minority is one thing, but it could just as easily be said that the vocal groups objecting to your characterization are representative of the mainstream view.

If we look at these models as the output of a compiler, that we don't have the inputs to, but that we are free (ish) to use and modify and redistribute, it's a nice grant from the copyright holder, but that very much doesn't look like open source. Open source, applied to AI models would mean giving us (a reference to) the dataset and the code used to train the model so we could tweak it to train the model slightly differently. To be less apologetic or something by default, instead of having to give it additional system instructions.

Model Available(MA) is freer than Model unavailable, and it's more generous than model unavailable, but it's very much not in the spirit of open source. I can't train my own model using what Meta has given us here.

And just to note, Google Gemma is the one they are releasing weights for. They are doing this and deserve credit for it.

Re:Meta Llama 3 by skybrian on Thursday April 18, 2024 @09:30PM (#40082588)
It doesn’t mean it’s a bad license, just that it doesn’t meet the definition. There are legitimate reasons for companies to use source-available licenses. You still get to see the source code and do some useful things with it, but read the terms to see what you can do.

Meanwhile, there are also good reasons not to water down a well-defined term so it becomes meaningless like “agile” or “open.”

This gets confusing because people want to use “open source” as a sort of marketing term that just means it’s good, so if you say it’s not open source that’s taken to imply it’s bad.

Re:Meta Llama 3 by bevekspldnw on Friday April 19, 2024 @12:07AM (#40083342)
But it’s also a bit absurd in a sense - let’s say you have all of Meta’s code and training data. Ok, now what? Even if you also had a couple spare data centers, unlimited money, and an army of engineers, you can’t even find enough NVIDIA cards to do the training run. This isn’t some homebrew shit, it’s millions upon millions of dollars of computational power devoted to building this thing.

I think at a fundamental level people have to start thinking a little differently about what this is, what open really means, and the like.

Re:Meta Llama 3 by fragmede on Friday April 19, 2024 @12:17AM (#40083386)
People are thinking what open really means, and they're telling you this isn't open. it definitely isn't Open Source, as defined by the OSI.

Open Source has a specific meaning and this doesn't meet it. It's generous of Meta to give us these models and grant us access to them, and let us modify them, fine tune them, and further redistribute them. It's really great! But we're still in the dark as to how they came about the weights. It's a closed, proprietary process, of which we have some details, which is interesting and all, but that's not the same as having access to the actual mechanism used to generate the model.

Re:Meta Llama 3 by foota on Friday April 19, 2024 @07:11AM (#40085350)
This is like saying an image is or isn't open source. The model itself isn't a program, so asking whether it's open source or not is a bit of a category error.

So it's a bit silly for anyone to claim a model is open source, but it's not silly to say a model is open. What open means isn't well defined when it comes to a model in the same way that source code is.

Imo if someone reveals the model's architecture and makes the weights available with minimal limitations, it's probably reasonable to call it open. I don't know that that would apply to llama though since I believe there are limitations on how you can use the model.

Re:Meta Llama 3 by nomel on Thursday April 18, 2024 @09:29PM (#40082574)
> Turning everything into some sort of theological debate takes away a lot of credit that Meta deserves.

It's not theological, it's the misuse of a specific legal definition that we all have interest in maintaining. "Freely available models" or "open license" are accurate.

Other companies keeping things for themselves doesn't warp reality, or the existing definitions we use to describe it. Giving them the credit they deserve, especially in comparison to the others, should be enough.

Re:Meta Llama 3 by bevekspldnw on Friday April 19, 2024 @12:18AM (#40083391)
Hate to break it to you but there’s a thousand court cases a day precisely because “specific legal definition” is a surprisingly flexible concept depending on context. Likewise when new technologies emerge it often requires reappraisal and interpretation of existing laws, even if that reappraisal is simply extending the old law to the new context.
Re:Meta Llama 3 by nomel on Friday April 19, 2024 @03:40PM (#40091147)
This isn't a problem with interpretation, as I would guess those are. This is a term that clearly describes requirements for a category, with the these models licenses purposefully and directly excluding themselves from that category.
Re:Meta Llama 3 by observationist on Friday April 19, 2024 @12:27PM (#40088775)
I think you're conferring one hell of a lot of credit to Meta that is entirely undeserved. This is not a charitable, net benefit to humanity organization. These are not the good guys. These people are responsible for one hell of a lot of harm, and imagining they have good intentions is naive at best. I don't doubt the individual software engineers and researchers are good people. It's the corporation that's in charge of the llama product, however, and it's the lawyers, executives, and middle management that will start cracking down on technicalities and violations of the license. The precise instant that it becomes more profitable and less annoying to sue someone for violation of the license, Meta's lawyers will do so, because that's what companies are obligated to do. The second some group of shareholders start pointing out blatant violations of the license in products using llama, the lawyers will be obligated to crack down.

Meta is a corporation, and not subject to rational, good faith human judgment. It's a construct that boils down to an algorithmic implementation of the rules, regulations, internal policies, communication channels, and all those complex interactions that effectively prevent sensible, good faith human intervention at any given stage that would even allow the company to just let people continue to violate their stated license. Like trademarks, if you don't enforce a contract, the inaction dissipates your ability to enforce it later on. They don't pay these lawyers to come up with these licenses and contracts for shits and giggles.

The license is not the outcome of a happy weekend brainstorm session tacked on ad hoc just to maximize the benefit to humanity and blissfully join the wide world of open source.

The license is intended to prevent any serious competitive use of their AI models by third parties. It was crafted deliberately and carefully and expensively. They didn't use existing open source licenses because no license offered them the particular mix of rights and restrictions that fit their overall strategy. It's for PR, the ability to stifle competition, to get free beta testing and market research, and 100% of every part of the license is intentional and an insidious perversion of the idea of "open."

Meta doesn't deserve credit, they deserve condemnation. They could have gone with any number of open source licenses, using GPL or CC licensing with specific provisions to protect their interests and prevent commercial exploitation, or use dual licensing to incentivize different tiers of access. They deliberately and with a high level of effort pursued their own invented license. They are using weasel words and claiming they are open source all over the place in order to foster good will.

The argument "but nobody has been sued" is more than a little silly. There's simply no product known to use their models currently on the market that's both a blatant enough violation and worth enough money to sacrifice the good will they've been fostering. There's no human in organizations that size with the capacity to step in and prevent the lawsuits from happening. It'll be a collective, rules and policies decision completely out of anyone's hands to prevent, even if Zuck himself wanted to intervene. The shareholders' interests reign supreme.

Meta isn't a moral institution. It's a ruthlessly profitable one.

Re:Meta Llama 3 by KingOfCoders on Friday April 19, 2024 @12:11AM (#40083362)
"Llama is not open source."

This is interesting. Can you point me to an OSI discussion what would constitute an open source license for LLMs? Obviously they have "source" (network definitions) and "training data" and "weights".

I'm not aware of any such discussion.

Re:Meta Llama 3 by TaylorAlexander on Friday April 19, 2024 @12:21AM (#40083399)
Actually right now the OSI is hosting ongoing discussion this year on what it means for AI to be open source. Here is their latest blog post on the subject:

https://opensource.org/blog/open-source-ai-definition-weekly...

Here is the latest draft definition:

https://hackmd.io/@opensourceinitiative/osaid-0-0-7

And a discussion about the draft:

https://discuss.opensource.org/t/draft-v-0-0-7-of-the-open-s...

Re:Meta Llama 3 by KingOfCoders on Friday April 19, 2024 @12:58PM (#40089193)
Thanks!
Re:Meta Llama 3 by dang on Friday April 19, 2024 @12:43AM (#40083493)
(We detached this subthread from https://news.ycombinator.com/item?id=40077832)
Re:Meta Llama 3 by blackeyeblitzar on Thursday April 18, 2024 @01:00PM (#40078327)
Llama is open weight, not open source. They don’t release all the things you need to reproduce their weights.
Re:Meta Llama 3 by mananaysiempre on Thursday April 18, 2024 @01:10PM (#40078440)
Not really that either, if we assume that “open weight” means something similar to the standard meaning of “open source”—section 2 of the license discriminates against some users, and the entirety of the AUP against some uses, in contravention of FSD #0 (“The freedom to run the program as you wish, for any purpose”) as well as DFSG #5&6 = OSD #5&6 (“No Discrimination Against Persons or Groups” and “... Fields of Endeavor”, the text under those titles is identical in both cases). Section 7 of the license is a choice of jurisdiction, which (in addition to being void in many places) I believe was considered to be against or at least skirting the DFSG in other licenses. At best it’s weight-available and redistributable.
Re:Meta Llama 3 by blackeyeblitzar on Thursday April 18, 2024 @04:00PM (#40080109)
Those are all great points and these companies need to really be called out for open washing
Re:Meta Llama 3 by amitport on Friday April 19, 2024 @01:43AM (#40083764)
It's a good balance IMHO. I appreciate what they have released.
Re:Meta Llama 3 by ikurei on Friday April 19, 2024 @06:29AM (#40085074)
I appreciate it too, and they're of course going to call it "open weights", but I reckon we (the technically informed public) should call it "weights-available".
Re:Meta Llama 3 by lumost on Friday April 19, 2024 @01:14AM (#40083626)
Has anyone tested how close you need to be to the weights for copyright purposes?
Re:Meta Llama 3 by tdullien on Friday April 19, 2024 @01:53PM (#40089932)
It's not even clear if weights are copyrightable in the first place, so no.
Re:Meta Llama 3 by ktzar on Friday April 19, 2024 @05:21AM (#40084741)
even if they released them, wouldn't it be prohibitively expensive to reproduce the weights?
Re:Meta Llama 3 by lawlessone on Friday April 19, 2024 @10:38AM (#40087390)
1.3 million GPU hrs for the 8b model. Take you around 130 years to train on a desktop lol.
Re:Meta Llama 3 by iamlearningai on Tuesday April 23, 2024 @08:18AM (#40131064)
Interesting. LLAMA is trained using 16K GPUs so it would have taken around a quarter for them. An hour of GPU use costs $2-$3 so training a custom solution using LLAMA should be atleast $15K to $1M. I am trying to get started with this thing. A few guys suggested 2 GPUs were a good start but I think that would only be good for 10K training samples.
Re:Meta Llama 3 by zingelshuher on Saturday April 20, 2024 @02:05PM (#40099371)
It's impossible. Meta itself cannot reproduce the model. Because training is randomized and that info is lost. First samples a coming at random. Second there are often drop-out layers, they generate random pattern which exists only on GPU during training for the duration of a single sample. Nobody saves them, it would take much more than training data. If someone tries to re-train the patterns will be different, which results in different weight and divergence from the beginning. Model will converge to something completely different. With close behavior if training was stable. LLMs are stable.

So, no way to reproduce the model. This requirement for 'open source' is absurd. It cannot be reliably done even for small models due to GPU internal randomness. Only the smallest trained on CPU in single thread. Only academia will be interested.

Re:Meta Llama 3 by throwaway4good on Friday April 19, 2024 @11:15AM (#40087870)
Which large model projects are open source in that sense? That its full source code including training material is published.
Re:Meta Llama 3 by soccernee on Friday April 19, 2024 @11:55AM (#40088389)
Olmo from AI2. They released the model weights plus training data and training code.

link: https://allenai.org/olmo

Re:Meta Llama 3 by whiplash451 on Sunday April 21, 2024 @03:11PM (#40108315)
Is it really useful to make an LLM open source when it takes millions of $ to train it?

At that scale, open weights with permissive license is much more useful than open source.

Re:Meta Llama 3 by htrp on Thursday April 18, 2024 @12:46PM (#40078158)
ML Twitter was saying that they're working on a 400B parameter version?
Re:Meta Llama 3 by mkl on Thursday April 18, 2024 @06:15PM (#40081328)
Meta themselves are saying that: https://ai.meta.com/blog/meta-llama-3/
Re:Meta Llama 3 by wiz21c on Friday April 19, 2024 @03:32AM (#40084258)
"within stabbing distance"

dunno if english is your mother tongue, but this sounds really good (although a tad aggressive :-) )) !

Re:Meta Llama 3 by waffletower on Friday April 19, 2024 @05:29PM (#40092118)
As Mike Judge's historical documents show, this enhanced aggression will seem normal in a few years or even months.
Re:Meta Llama 3 by danielhanchen on Friday April 19, 2024 @03:33AM (#40084267)
On the topic of LoRAs and finetuning, have a Colab for LoRA finetuning Llama-3 8B :) https://colab.research.google.com/drive/135ced7oHytdxu3N2DNe...
Re:Meta Llama 3 by resource_waste on Thursday April 18, 2024 @12:30PM (#40077940)
Blocked me for asking how to make Feet soft.

lmaooo.

I was asking scientifically too. I mean, I had intentions, but I wasnt doing anything outright bad.

Re:Meta Llama 3 by freedomben on Thursday April 18, 2024 @03:13PM (#40079727)
I haven't tried Llama 3 yet, but Llama 2 is indeed extremely "safe." (I'm old enough to remember when AI safety was about not having AI take over the world and kill all humans, not when it might offend a Puritan's sexual sensibilities or hurt somebody's feelings, so I hate using the word "safe" for it, but I can't think of a better word that others would understand).

It's not quite as bad as Gemini, but in the same class where it's almost not useful because so often it refuses to do anything except lecture. Still very grateful for it, but I suspect the most useful model hasn't happened yet.

Re:Meta Llama 3 by jasonfarnon on Thursday April 18, 2024 @07:08PM (#40081698)
So whereabouts are you that a "Puritan's sexual sensibilities" holds any sway?
Re:Meta Llama 3 by ben_w on Friday April 19, 2024 @02:12AM (#40083884)
I think the point is Silicon Valley is such a place.

"Visible nipples? The defining characteristic of all mammals, which infants necessarily have to put in their mouths to feed? On this website? Your account has been banned!"

Meanwhile in Berlin, topless calendars in shopping malls and spinning-cube billboards for Dildo King all over the place.

Re:Meta Llama 3 by zzzzzzzzzz10 on Friday April 19, 2024 @04:50AM (#40084605)
Sex macht schön - Dildo King
Re:Meta Llama 3 by resource_waste on Friday April 19, 2024 @08:15AM (#40085815)
TO be fair, its one of the most popular terms people search...

So, lets not pretend its something that isnt arousing.

Re:Meta Llama 3 by computerfriend on Friday April 19, 2024 @10:22AM (#40087186)
I personally search for lots of things that aren't arousing to me.
Re:Meta Llama 3 by oblio on Friday April 19, 2024 @12:02PM (#40088474)
Even if it's arousing, who cares?

Ankles were arousing in 1800s Britain. They might still be in some places.

Re:Meta Llama 3 by SV_BubbleTime on Friday April 19, 2024 @01:35PM (#40089708)
It’s everywhere. The entire USA has been devolving into New Puritan nonsense in many ways since the sexual revolution… which is bizarre.
Re:Meta Llama 3 by int_19h on Thursday April 18, 2024 @07:38PM (#40081871)
"Censored" is the word that you're looking for, and is generally what you see when these models are discussed on Reddit etc.

Not to worry - uncensored finetunes will be coming shortly.

Re:Meta Llama 3 by weebull on Friday April 19, 2024 @05:35AM (#40084803)
You can't really take out the censorship. You can strengthen pathways which work around the damage, but the damage is still there.
Re:Meta Llama 3 by int_19h on Saturday April 20, 2024 @03:56AM (#40095619)
If the model doesn't refuse to produce output, it's not censored anymore for any practical purpose. It doesn't really matter if there are "censorship neurons" inside that are routed around.

Sure, it would be nice if we didn't have to do that so that the model could actually spent its full capacity on something useful. But that's a different issue even if the root cause is the same.

Re:Meta Llama 3 by visarga on Thursday April 18, 2024 @01:22PM (#40078555)
GPT-3.5 rejected to extract data from a German receipt because it contained "Women's Sportswear", sent back a "medium" severity sexual content rating. That was an API call, which should be less restrictive.
Re:Meta Llama 3 by SOVIETIC-BOSS88 on Thursday April 18, 2024 @01:12PM (#40078463)
We are living in a post Dan Schneider world. Feet are off the table.
Re:Meta Llama 3 by sebastiennight on Thursday April 18, 2024 @04:00PM (#40080107)
Well thanks then. Some of us eat on this table you know
Re:Meta Llama 3 by resource_waste on Thursday April 18, 2024 @03:39PM (#40079942)
I think nsfw stats bursted that bubble, not danny.
Re:Meta Llama 3 by SV_BubbleTime on Thursday April 18, 2024 @12:41PM (#40078098)
Sorry, still too sexy. Can’t have that.
Re:Meta Llama 3 by nickthegreek on Thursday April 18, 2024 @12:13PM (#40077719)
And they even allow you to use it without logging in. Didnt expect that from Meta.
Re:Meta Llama 3 by salil999 on Thursday April 18, 2024 @12:25PM (#40077876)
I do see on the bottom left:

Log in to save your conversation history, sync with Messenger, generate images and more.

Re:Meta Llama 3 by zitterbewegung on Thursday April 18, 2024 @12:47PM (#40078163)
Think they meant it can be used without login.
Re:Meta Llama 3 by lairv on Thursday April 18, 2024 @12:42PM (#40078114)
Not in the EU though
Re:Meta Llama 3 by sega_sai on Thursday April 18, 2024 @01:39PM (#40078711)
or the UK
Re:Meta Llama 3 by applecrazy on Thursday April 18, 2024 @12:38PM (#40078059)
I imagine that is to compete with ChatGPT, which began doing the same.
Re:Meta Llama 3 by visarga on Thursday April 18, 2024 @01:20PM (#40078531)
Doesn't work for me, I'm in EU.
Re:Meta Llama 3 by mvkel on Friday April 19, 2024 @01:35AM (#40083726)
Probably bc they're violating gdpr
Re:Meta Llama 3 by HarHarVeryFunny on Thursday April 18, 2024 @02:01PM (#40078932)
Yeah, but not for image generation unfortunately

I've never had a FaceBook account, and really don't trust them regarding privacy

Re:Meta Llama 3 by zingelshuher on Saturday April 20, 2024 @02:31PM (#40099641)
had to upvote this
Re:Meta Llama 3 by sdesol on Thursday April 18, 2024 @02:13PM (#40079072)
I had the same reaction, but when I saw the thumbs up and down icon, I realized this was a smart way to crowd source validation data.
Re:Meta Llama 3 by unshavedyak on Thursday April 18, 2024 @02:24PM (#40079189)
Which indicates that they get enough value out of logged ~in~ out users. Potentially they can identify you without logging in, no need to. But also ofc they get a lot of value by giving them data via interacting with the model.
Re:Meta Llama 3 by MichaelCharles on Thursday April 18, 2024 @09:49PM (#40082700)
But not from Japan, and I assume most other non-English speaking countries.
Re:Meta Llama 3 by mvkel on Friday April 19, 2024 @01:34AM (#40083725)
1. Free rlhf 2. They cookie the hell out of you to breadcrumb your journey around the web.

They don't need you to login to get what they need, much like Google

Re:Meta Llama 3 by eggdaft on Friday April 19, 2024 @01:45AM (#40083775)
Do they really need “free RLHF”? As I understand it, RLHF needs relatively little data to work and its quality matters - I would expect paid and trained labellers to do a much better job than Joey Keyboard clicking past a “which helped you more” prompt whilst trying to generate an email.
Re:Meta Llama 3 by spi on Friday April 19, 2024 @05:00AM (#40084647)
Variety matters a lot. If you pay 1000 trained labellers, you get 1000 POVs for a good amount of money, and likely can't even think of 1000 good questions to have them ask. If you let 1000000 people give you feedback on random topics for free, and then pay 100 trained people to go through all of that and only retain the most useful 1%, you get much ten times more variety for a tenth of the cost.

Of course numbers are pretty random, but it's just to give an idea of how these things scale. This is my experience from my company's own internal -deep learning but not LLM- models to train which we had to buy data instead of collecting it. If you can't tap into data "from the wild" -in our case, for legal reason- you can still get enough data (if measured in GB), but it's depressingly more repetitive, and that's not quite the same thing when you want to generalize.

Re:Meta Llama 3 by mvkel on Friday April 19, 2024 @01:43PM (#40089813)
Absolutely.

Modern captchas are self driving object labelers; you just need a few to "agree" to know what the right answer is.

Re:Meta Llama 3 by dizhn on Saturday April 20, 2024 @06:03AM (#40096146)
We should agree on a different answer for crosswalk and traffic light and mess it up for them.
Re:Meta Llama 3 by throwup238 on Thursday April 18, 2024 @12:15PM (#40077747)
> And announcing a lot of integration across the Meta product suite, ...

That's ominous...

Re:Meta Llama 3 by iosjunkie on Thursday April 18, 2024 @01:17PM (#40078508)
Spending millions/billions to train these models is for a reason and it's not just for funsies.
Re:Meta Llama 3 by schleck8 on Thursday April 18, 2024 @12:31PM (#40077966)
> Neglected to include comparisons against GPT-4-Turbo or Claude Opus, so I guess it's far from being a frontier model

Yeah, almost like comparing a 70b model with a 1.8 trillion parameter model doesn't make any sense when you have a 400b model pending release.

Re:Meta Llama 3 by cjbprime on Thursday April 18, 2024 @01:18PM (#40078511)
(You can't compare parameter count with a mixture of experts model, which is what the 1.8T rumor says that GPT-4 is.)
Re:Meta Llama 3 by schleck8 on Thursday April 18, 2024 @01:29PM (#40078615)
You absolutely can since it has a size advantage either way. MoE means the expert model performs better BECAUSE of the overall model size.
Re:Meta Llama 3 by cjbprime on Thursday April 18, 2024 @01:39PM (#40078706)
Fair enough, although it means we don't know whether a 1.8T MoE GPT-4 will have a "size advantage" over Llama 3 400B.
Re:Meta Llama 3 by matsemann on Thursday April 18, 2024 @12:38PM (#40078068)
> Meta AI isn't available yet in your country

Where is it available? I got this in Norway.

Re:Meta Llama 3 by sunaookami on Thursday April 18, 2024 @02:41PM (#40079370)
>We’re rolling out Meta AI in English in more than a dozen countries outside of the US. Now, people will have access to Meta AI in Australia, Canada, Ghana, Jamaica, Malawi, New Zealand, Nigeria, Pakistan, Singapore, South Africa, Uganda, Zambia and Zimbabwe — and we’re just getting started.

https://about.fb.com/news/2024/04/meta-ai-assistant-built-wi...

Re:Meta Llama 3 by realce on Thursday April 18, 2024 @04:20PM (#40080303)
That's a strange list of nations, isn't it? I wonder what their logic is.
Re:Meta Llama 3 by urbandw311er on Thursday April 18, 2024 @05:47PM (#40081093)
No EU initially - I think this is the same with Gemini 1.5 Pro too. I believe it’s to do with the various legal restrictions around AI which iirc take a few weeks.
Re:Meta Llama 3 by wyh171701 on Thursday April 18, 2024 @10:28PM (#40082898)
yes, china is too
Re:Meta Llama 3 by gliched_robot on Friday April 19, 2024 @01:02AM (#40083582)
GPU server locations, maybe?
Re:Meta Llama 3 by namibj on Friday April 19, 2024 @02:08AM (#40083862)
LLM chat is so compute heavy and not bandwidth heavy that anywhere with reliable fiber and cheap electricity is suitable. Ping is lower than average keystroke delay for most who haven't undergone explicit speed typing training (we're talking 60~120 WPM for between intercontinental to pathological (other end of the world) servers). Bandwidth matters a bit more for multimodal interaction, but it's still rather minor.
Re:Meta Llama 3 by singhblom on Friday April 19, 2024 @06:47AM (#40085184)
All anglophone. I'm guessing privacy laws or something like that disqualifies the UK and Ireland.
Re:Meta Llama 3 by schleck8 on Thursday April 18, 2024 @12:58PM (#40078307)
Just use the Replicate demo instead, you can even alter the inference parameters

https://llama3.replicate.dev/

Or run a jupyter notebook from Unsloth on Colab

https://huggingface.co/unsloth/llama-3-8b-bnb-4bit

Re:Meta Llama 3 by sunaookami on Thursday April 18, 2024 @02:42PM (#40079391)
This version doesn't have web search and the image creation though.
Re:Meta Llama 3 by schleck8 on Friday April 19, 2024 @03:42AM (#40084323)
The image creation isn't Llama 3, it's not multimodal yet. And the web search is Google and Bing API calls so just use Copilot or Perplexity.
Re:Meta Llama 3 by niek_pas on Thursday April 18, 2024 @12:41PM (#40078103)
Got the same in the Netherlands.
Re:Meta Llama 3 by kreddor on Thursday April 18, 2024 @12:49PM (#40078188)
Got the same in Denmark
Re:Meta Llama 3 by flemhans on Thursday April 18, 2024 @12:49PM (#40078187)
Probably the EU laws are getting too draconian. I'm starting to see it a lot.
Re:Meta Llama 3 by sa-code on Thursday April 18, 2024 @12:55PM (#40078264)
EU actually has the opposite of draconian privacy laws. It's more that meta doesn't have a business model if they don't intrude on your privacy
Re:Meta Llama 3 by mrtranscendence on Thursday April 18, 2024 @01:26PM (#40078596)
Well, exactly, and that's why IMO they'll end up pulling out the EU. There's barely any money in non-targeted ads.
Re:Meta Llama 3 by sebastiennight on Thursday April 18, 2024 @03:57PM (#40080082)
If by "barely any money", you mean "all the businesses in the EU will still give you all their money as long as you've got eyeballs", then yes.
Re:Meta Llama 3 by ben_w on Friday April 19, 2024 @02:01AM (#40083838)
Facebook has shown me ads for both dick pills and breast surgery, for hyper-local events in town in a country I don't live in, and for a lawyer who specialises in renouncing a citizenship I don't have.

At this point, I think paying Facebook to advertise is a waste of money — the actual spam in my junk email folder is better targeted.

Re:Meta Llama 3 by latexr on Friday April 19, 2024 @03:10AM (#40084160)
> IMO they'll end up pulling out the EU.

If only we’d be so lucky. I don’t thing they will, but fingers crossed.

Re:Meta Llama 3 by extraduder_ire on Friday April 19, 2024 @07:47AM (#40085611)
If it's more money than it costs to operate, I doubt it. There's plenty of businesses in the EU buying ads and page promotion still.
Re:Meta Llama 3 by zmmmmm on Thursday April 18, 2024 @06:00PM (#40081219)
They just said laws, not privacy - the EU has introduced the "world's first comprehensive AI law". Even if it doesn't stop release of these models, it might be enough that the lawyers need extra time to review and sign off that it can be used without Meta getting one of those "7% of worldwide revenue" type fines the EU is fond of.

[0] https://www.europarl.europa.eu/topics/en/article/20230601STO...

Re:Meta Llama 3 by taneq on Saturday April 20, 2024 @04:33AM (#40095789)
Am I reading that right? It sounds like they’re outlawing advertising (“Cognitive behavioural manipulation of people”), credit scores (“classifying people based on behaviour, socio-economic status or personal characteristics”) and fingerprint/facial recognition for phone unlocking etc. (“Biometric identification and categorisation of people”)

Maybe they mean specific uses of these things in a centralised manner but the way it’s written makes it sound incredibly broad.

Re:Meta Llama 3 by stareatgoats on Thursday April 18, 2024 @01:05PM (#40078390)
Claude has the same restriction [0], the whole of Europe (except Albania) is excluded. Somehow I don't think it is a retaliation against Europe for fining Meta and Google. I could be wrong, but a business decision seems more likely, like keeping usage down to a manageable level in an initial phase. Still, curious to understand why, should anyone here know more.

[0] https://www.anthropic.com/claude-ai-locations

Re:Meta Llama 3 by hanspeter on Thursday April 18, 2024 @04:37PM (#40080471)
It's because of regulations!

The same reason that Threads was launched with a delay in EU. It simply takes a lot of work to comply with EU regulations, and by no surprise will we see these launches happen outside of EU first.

Re:Meta Llama 3 by viraptor on Thursday April 18, 2024 @07:09PM (#40081704)
It's trivial to comply with EU privacy regulation if you're not depending on selling customer data.

But if you say "It's because of regulations!" I hope you have a source to back that up.

Re:Meta Llama 3 by mvkel on Friday April 19, 2024 @01:38AM (#40083741)
That won't be true for much longer.

The AI Act will significantly nerf the capabilities you will be allowed to benefit from in the eu.

Re:Meta Llama 3 by jokethrowaway on Friday April 19, 2024 @02:50AM (#40084053)
It is because of regulations. Nothing is trivial and anything has a cost. Not only it impacts existing businesses, it also make it harder for a struggling new business to compete with the current leaders.

Regulations in the name of the users are actually just made to solidify the top lobbyists in their positions.

The reasons I hate regulations is not because billionaires have to spend an extra week on some employee's salary, but because it makes it impossible for me tiny business to enter a new business due to the sheer complexity of it (or force me to pay more for someone else to handle it, think Paddle vs Stripe thanks to EU VATMOSS)

I'm completely fine with giving away some usage data to get a free product, it's not like everyone is against it.

I'd also prefer to be tracked without having to close 800 pop-ups a day.

Draconian regulations like the EU ones destroy entire markets and force us to a single business model where we all need to pay with hard cash.

Re:Meta Llama 3 by jimnotgym on Friday April 19, 2024 @03:55AM (#40084364)
Do you find EU MOSS harder to deal with that US sales tax?

MOSS is a massive reduction in overhead vs registering in each individual country, isn't it? Or are you really just saying you don't like sales tax?

Re:Meta Llama 3 by viraptor on Friday April 19, 2024 @03:21AM (#40084202)
You didn't provide the source for the claim though. You're saying you think they made that choice because of regulations and what your issues are. That could well be true, but we really don't know. Maybe there's a more interesting reason. I'm just saying you're really sure for a person who wasn't involved in this.
Re:Meta Llama 3 by skissane on Friday April 19, 2024 @07:01AM (#40085277)
> It is because of regulations. Nothing is trivial and anything has a cost. Not only it impacts existing businesses, it also make it harder for a struggling new business to compete with the current leaders.

But, in my experience, it is also true that "regulations" is sometimes a convenient excuse for a vendor to not do something, whether or not the regulations actually say that.

Years ago, I worked for a university. We were talking to $MAJOR_VENDOR sales about buying a hosted student email solution from them. This was mid-2000s, so that kind of thing was a lot less mainstream then compared to now. Anyway, suddenly the $MAJOR_VENDOR rep turned around and started claiming they couldn't sell the product to us because "selling it to a .edu.au domain violates the Australian Telecommunications Act". Never been a lawyer, but that legal explanation sounded very nonsensical to me. We ended up talking to Google instead, who were happy to offer us Google Apps for Education, and didn't believe there were any legal obstacles to their doing so.

I was left with the strong suspicion that $MAJOR_VENDOR didn't want to do it for their own internal reasons (product wasn't ready, we weren't a sufficiently valuable customer, whatever) and someone just made up the legal justification because it sounded better than whatever the real reason was

Re:Meta Llama 3 by ks2048 on Thursday April 18, 2024 @08:56PM (#40082378)
Same message in Guatemala. Not known for regulations.
Re:Meta Llama 3 by A_D_E_P_T on Friday April 19, 2024 @04:27AM (#40084510)
Yet for some reason it doesn't work in non-EU European countries like Serbia and Switzerland, either.
Re:Meta Llama 3 by skissane on Friday April 19, 2024 @06:48AM (#40085196)
In the case of Switzerland, the EU and Switzerland have signed a series of bilateral treaties which effectively make significant chunks of EU law applicable in Switzerland.

Whether that applies to the specific regulations in question here, I don't know – but even if it doesn't, it may take them some time for their lawyers to research the issue and tell them that.

Similarly, for Serbia, a plausible explanation is they don't actually know what laws and regulations it may have on this topic–they probably don't have any Serbian lawyers in-house, and they may have to contract with a local Serbian law firm to answer that question for them, which will take time to organise. Whereas, for larger economies (US, EU, UK, etc), they probably do have in-house lawyers.

Re:Meta Llama 3 by schleck8 on Thursday April 18, 2024 @12:58PM (#40078301)
> the EU laws are getting too draconian

You also said that when Meta delayed the Threads release by a few weeks in the EU. I recommend reading the princess on a pea fairytale since you seem to be quite sheltered, using the term draconian as liberally.

Re:Meta Llama 3 by sunaookami on Thursday April 18, 2024 @02:41PM (#40079360)
>a few weeks

July to December is not "a few weeks"

Re:Meta Llama 3 by Draiken on Thursday April 18, 2024 @01:15PM (#40078491)
Meta (and other privacy exploiting companies) have to actually... care? Even if it's just a bit more. Nothing draconian about it.
[dead]
Re:Meta Llama 3 by kleiba on Thursday April 18, 2024 @01:14PM (#40078488)
What a silly, provocative comparison. China is a suppressive state that strives to control its citizens while the EU privacy protection laws are put in place to protect citizens. If you cannot access websites from "the free world" because of these laws, it means that the providers of said websites are threatening your freedom, not providing it.
Re:Meta Llama 3 by medo-bear on Thursday April 18, 2024 @01:20PM (#40078537)
Nanny state is a nanny state. Chinese authorities are also "protecting their citiziens". However, I think the EU laws are nothing in comparison to some other Western "protections", like in Australia for example, which in many cases "protects" its citizens more than Russian government "protects" its citizens.
Re:Meta Llama 3 by glenstein on Thursday April 18, 2024 @06:00PM (#40081215)
>Nanny state is a nanny state.

In my opinion this is a thought stopping cliche that throws the concept of differences of scale out the window, which is a catastrophic choice to make when engaging in comparative assessments of policies in different countries. Again just my opinion here but I believe statements such as these should be understood as a form of anti-intellectualism.

Re:Meta Llama 3 by medo-bear on Friday April 19, 2024 @02:06AM (#40083857)
> Again just my opinion here but I believe statements such as these should be understood as a form of anti-intellectualism.

What is anti-intellectual about what I said? If you take a step back you see that your response actually contains no argumentative content.

Re:Meta Llama 3 by dheera on Thursday April 18, 2024 @01:18PM (#40078510)
> China is a suppressive state that strives to control its citizens

China's central government also believes it is protecting its citizens.

> while the EU privacy protection laws are put in place to protect citizens

The fact that they CAN exert so much power on information access in the name of "protection" is a bad precedent, and opens the door to future, less-benevolent authoritarian leadership being formed.

(Even if you think they are protecting their citizens now, I actually disagree; blocking access to AI isn't protecting its citizens, it's handicapping them in the face of a rapidly-advancing world economy.)

Re:Meta Llama 3 by Rexxar on Thursday April 18, 2024 @02:28PM (#40079239)
> The fact that they CAN exert so much power on information access in

They don't have any power on information access. They just require their citizen can decide what you do with it. There is no central system where information is stored that can be used in future by authoritarian leadership. But the information stored about American by American companies can be use in such a way if there one day an authoritarian leadership in America.

Re:Meta Llama 3 by glenstein on Thursday April 18, 2024 @06:07PM (#40081274)
>China's central government also believes it is protecting its citizens.

Anyone who's taking a course in epistemology can tell you that there's more to assessing veracity of a belief than noting its equivalence to other beliefs. There can be symmetry in psychology without symmetry in underlying facts. So noting an equivalence of belief is not enough to establish an equivalence in fact.

I'm not even saying I'm for or against the EU's choices but I think the purpose of analogies to China is kind of rhetorical purpose of warning or a comparison intended to reflect negatively on the EU. I find it hard to imagine one would make a straight faced case that they are in fact equivalent in scope or scale or ambition or equivalent and their idea of the relation of their mission to their values for core liberties.

I think the difference is here are clear enough that reasonable people should be able to make the case against AI regulation without losing grasp of the distinction between European and Chinese regulatory frameworks.

Re:Meta Llama 3 by medo-bear on Friday April 19, 2024 @02:11AM (#40083878)
The previous poster said that the EU is not restricting the freedom of its citizens, but protecting them (from themselves?). I fail to see how one can say that with a straight face. If you had a basic understanding of history of dictorships you would know that every dictatorship starts off by "protecting" its citizens.
Re:Meta Llama 3 by bschmidt1 on Friday April 19, 2024 @12:02PM (#40088481)
> China suppresses citizens while EU protects citizens!

Lol this is the real silly provocative comparison.

China bans sites & apps from the West that violate their laws - the ad tracking, monitoring, censorship & influencer/fake news we have here... the funding schemes and market monopolizing that companies like Facebook do in the West is just not legal there. Can you blame them for not wanting it? You think Facebook is a great company for citizens, yet TikTok threatens freedom? Lol it's like I'm watching Fox News.

Companies that don't violate Chinese laws and approach China with realistic deals are allowed to operate there - you can play WoW in China because unlike Facebook it's not involved in censorship, severe privacy violations etc. and Blizzard actually worked with China (NetEase) to bring their product to market there instead of crying and trying to stoke WW3 in the news like our social media companies are doing. Just because Facebook and Google can do whatever they want unchecked in America and its vassal the EU, doesn't mean other countries have to allow it. I applaud China for upholding their rule of law and their traditions, and think it's healthy for the real unethical actors behind our companies to get told "No" for once in their lives.

US and its puppet EU just want to counter-block Chinese apps like TikTok in retaliation for them upholding their own rule of law. Sounds like you fell for the whole "China is a big scary oppressor" bit when the West is an actual oppressor - we have companies that control the entire market and media narrative over here - our companies and media can control whether or not white people can be hired, or can predict what you'll buy for lunch. Nobody has a more dangerous hold on citizens than western corporations.
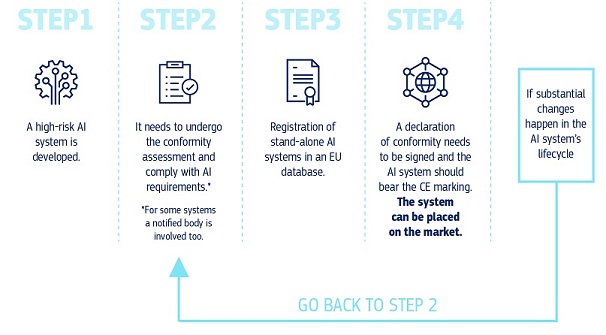
Re:Meta Llama 3 by matsemann on Thursday April 18, 2024 @02:05PM (#40078982)
You surely seem well-informed on this EU matter when you reply to my comment about a non-EU country!
Re:Meta Llama 3 by dev1ycan on Thursday April 18, 2024 @01:51PM (#40078830)
EU? I live in south america and don't have access either, Facebook is just showing what the US plans to do, weaponize AI in the future and give itself accesss first.
Re:Meta Llama 3 by aeyes on Thursday April 18, 2024 @01:21PM (#40078550)
Norway is not in the EU
Re:Meta Llama 3 by watermelon0 on Thursday April 18, 2024 @02:08PM (#40079010)
Not in the EU, but GDPR also applies to countries in European Economic Area, of which Norway is a part of.
Re:Meta Llama 3 by dom96 on Thursday April 18, 2024 @04:48PM (#40080565)
This is so frustrating. Why don't they just make it available everywhere?
Re:Meta Llama 3 by murderfs on Thursday April 18, 2024 @08:13PM (#40082099)
Re:Meta Llama 3 by int_19h on Saturday April 20, 2024 @04:57AM (#40095881)
This says "high-risk AI system", which is defined here: https://digital-strategy.ec.europa.eu/en/policies/regulatory.... I don't see why it would be applicable.
Re:Meta Llama 3 by murderfs on Tuesday April 23, 2024 @10:55PM (#40139969)
The text of the law says that the actual criteria can change to be whatever they think is scary:

    As regards stand-alone AI systems, namely high-risk AI systems other than those that are
   safety components of products, or that are themselves products, it is appropriate to classify
   them as high-risk if, in light of their intended purpose, they pose a high risk of harm to the
   health and safety or the fundamental rights of persons, taking into account both the severity
   of the possible harm and its probability of occurrence and they are used in a number of
   specifically pre-defined areas specified in this Regulation. The identification of those
   systems is based on the same methodology and criteria envisaged also for any future
   amendments of the list of high-risk AI systems that the Commission should be
   empowered to adopt, via delegated acts, to take into account the rapid pace of
   technological development, as well as the potential changes in the use of AI systems.
And there's also a section about systemic risks, which llama definitely falls into, and which mandates that they go through basically the same process, with offices and panels that do not yet exist:

https://ec.europa.eu/commission/presscorner/detail/en/qanda_....

Re:Meta Llama 3 by reisse on Thursday April 18, 2024 @06:45PM (#40081547)
I'm always glad at these rare moments when EU or American people can get a glimpse of a life outside the first world countries.
Re:Meta Llama 3 by user_7832 on Friday April 19, 2024 @05:11PM (#40091941)
I'd call that the "anywhere but US" phenomena. Pretty much 100% of the times I see any "deals"/promotions or whatnot on my google feed, it's US based. Unfortunately I live nowhere near to the continent.
Re:Meta Llama 3 by miohtama on Thursday April 18, 2024 @05:28PM (#40080905)
The EU does not want you to have the AI.
Re:Meta Llama 3 by ks2048 on Thursday April 18, 2024 @08:55PM (#40082370)
Same message in Guatemala.
Re:Meta Llama 3 by stefs on Sunday April 21, 2024 @01:16PM (#40107398)
norway isn't in the EU
Re:Meta Llama 3 by ks2048 on Thursday April 18, 2024 @08:54PM (#40082366)
Everyone saying it's an EU problem. Same message in Guatemala.
Re:Meta Llama 3 by sunny-beast on Monday April 22, 2024 @02:26AM (#40111857)
Anakin AI has Llama 3 models available right now: https://app.anakin.ai/
Re:Meta Llama 3 by josh-sematic on Thursday April 18, 2024 @12:42PM (#40078109)
They also stated that they are still training larger variants that will be more competitive:

> Our largest models are over 400B parameters and, while these models are still training, our team is excited about how they’re trending. Over the coming months, we’ll release multiple models with new capabilities including multimodality, the ability to converse in multiple languages, a much longer context window, and stronger overall capabilities.

Re:Meta Llama 3 by glenstein on Thursday April 18, 2024 @05:57PM (#40081184)
Anyone have any informed guesstimations as to where we might expect a 400b parameter model for llama 3 to land benchmark wise and performance wise, relative to this current llama 3 and relative to GPT-4?

I understand that parameters mean different things for different models, and llama two had 70 b parameters, so I'm wondering if anyone can contribute some guesstimation as to what might be expected with the larger model that they are teasing?

Re:Meta Llama 3 by ZiiS on Thursday April 18, 2024 @06:23PM (#40081386)
They are aiming to beat the current GPT4 and stand a fair chance, they are unlikly to hold the crown for long.
Re:Meta Llama 3 by glenstein on Thursday April 18, 2024 @07:05PM (#40081681)
Right because the very little I've heard out of Sam Altman this year hinting at future updates suggests that there's something coming before we turn our calendars to 2025. So equaling or mildly exceeding GPT-4 will certainly be welcome, but could amount to a temporary stint as king of the mountain.
Re:Meta Llama 3 by llm_trw on Friday April 19, 2024 @12:38AM (#40083472)
This is always the case.

But the fact that open models are beating state of the art from 6 months ago is really telling just how little moat there is around AI.

Re:Meta Llama 3 by oittaa on Friday April 19, 2024 @04:26AM (#40084501)
Google: "We Have No Moat, And Neither Does OpenAI"
Re:Meta Llama 3 by lumost on Friday April 19, 2024 @01:17AM (#40083646)
Unless you are NVidia.
Re:Meta Llama 3 by ZiiS on Friday April 19, 2024 @05:26AM (#40084764)
FB are over $10B into AI. The English Channel was a wide moat just not uncrossable.
Re:Meta Llama 3 by llm_trw on Friday April 19, 2024 @07:42AM (#40085566)
Yes, but the amount they have invested into training llama3 even if you include all the hardware is in the low tens of millions. There are a _lot_ of companies who can afford that.

Hell there are not for profits that can afford that.

Re:Meta Llama 3 by sebzim4500 on Friday April 19, 2024 @12:05PM (#40088517)
Where are you getting that number? I find it hard to believe that can be true, especially if you include the cost of training the 400B model and the salaries of the engineers writing/maintaining the training code.
Re:Meta Llama 3 by glenstein on Friday April 19, 2024 @09:04AM (#40086313)
>This is always the case.

I mean anyone can throw out self evident general truisms about how there will always be new models and always new top dogs. It's a good generic assumption but I feel like I can make generic assumptions and general truisms just as well as the next person.

I'm more interested in divining in specific terms who we consider to be at the top currently, tomorrow and the day after tomorrow based on the specific things that have been reported thus far. And interestingly, thus far, the process hasn't been one of a regular rotation of temporary top dogs. It's been one top dog, Open AI's GPT, I would say that it currently is still, and when looking at what the future holds, it appears that it may have a temporary interruption before it once again is the top dog, so to speak.

That's not to say it'll always be the case but it seems like that's what our near future timeline has in store based on reporting, and it's piecing that near future together that I'm most interested in.

Re:Meta Llama 3 by ZoomerCretin on Friday April 19, 2024 @02:40AM (#40084009)
The benchmark for the latest checkpoint is pretty good: https://x.com/teknium1/status/1780991928726905050?s=46
Re:Meta Llama 3 by MP_1729 on Friday April 19, 2024 @01:54PM (#40089949)
Mark said in a podcast they are currently at MMLU 85, but it's still improving.
Re:Meta Llama 3 by jamesgpearce on Thursday April 18, 2024 @01:07PM (#40078411)
That realtime `/imagine` prompt seems pretty great.
Re:Meta Llama 3 by geepytee on Thursday April 18, 2024 @02:59PM (#40079565)
Also added Llama 3 70B to our coding copilot https://www.double.bot if anyone wants to try it for coding within their IDE and not just chat in the console
Re:Meta Llama 3 by 8n4vidtmkvmk on Thursday April 18, 2024 @10:11PM (#40082814)
Can we stop referring to VS Code as "their IDE"?

Do you support any other editors? If the list is small, just name them. Not everyone uses or likes VS Code.

Re:Meta Llama 3 by DresdenNick on Friday April 19, 2024 @09:21AM (#40086495)
Done. Anything else?
Re:Meta Llama 3 by erhaetherth on Saturday April 20, 2024 @03:54PM (#40100470)
No, actually. Thank you for that.

Your "Double vs. Github Copilot" page is great.

I've signed up for the Jetbrains waitlist.

Re:Meta Llama 3 by rdez6173 on Friday April 19, 2024 @10:47AM (#40087520)
Double seems more like a feature than a product. I feel like Copilot could easily implement those value-adds and obsolete this product.

I also don't understand why I can't bring my own API tokens. I have API keys for OpenAI, Anthropic, and even local LLMs. I guess the "secret" is in the prompting that is being done on the user's behalf.

I appreciate the work that went into this, I just think it's not for me.

Re:Meta Llama 3 by doakes on Friday April 19, 2024 @04:06PM (#40091408)
That was fast! I've really been enjoying Double, thanks for your work.
Re:Meta Llama 3 by ionwake on Saturday April 20, 2024 @06:34AM (#40096272)
Cool thanks! Will try
Re:Meta Llama 3 by krackers on Thursday April 18, 2024 @05:24PM (#40080876)
Are there an stats on if llama 3 beats out chatgpt 3.5 (the free one you can use)?
Re:Meta Llama 3 by dawnerd on Thursday April 18, 2024 @07:05PM (#40081683)
Tried a few queries and was surprised how fast it responded vs how slow chatgpt can be. Responses seemed just as good too.
Re:Meta Llama 3 by gliched_robot on Friday April 19, 2024 @01:02AM (#40083578)
Inference speed is not a great metric given the horizontal scalability of LLMs.
Re:Meta Llama 3 by jaimex2 on Friday April 19, 2024 @04:45AM (#40084584)
Because no one is using it
Re:Meta Llama 3 by dazuaz on Thursday April 18, 2024 @07:29PM (#40081817)
I'm based on LLaMA 2, which is a type of transformer language model developed by Meta AI. LLaMA 2 is a more advanced version of the original LLaMA model, with improved performance and capabilities. I'm a specific instance of LLaMA 2, trained on a massive dataset of text from the internet, books, and other sources, and fine-tuned for conversational AI applications. My knowledge cutoff is December 2022, and I'm constantly learning and improving with new updates and fine-tuning.
Re:Meta Llama 3 by davidmurdoch on Thursday April 18, 2024 @07:52PM (#40081962)
Are you trying to say you are a bot?
Re:Meta Llama 3 by Aaron2222 on Thursday April 18, 2024 @09:28PM (#40082573)
That's the response they got when asking the https://www.meta.ai/ web console what version of LLaMA it is.
Re:Meta Llama 3 by salesynerd on Thursday April 18, 2024 @09:52PM (#40082719)
Strange. The Llama 3 model card mentions that the knowledge cutoff dates are March 2023 for the 8B version and December 2023 for the 70B version (https://github.com/meta-llama/llama3/blob/main/MODEL_CARD.md)
Re:Meta Llama 3 by gliched_robot on Friday April 19, 2024 @12:58AM (#40083556)
Maybe a typo?
Re:Meta Llama 3 by glenstein on Friday April 19, 2024 @09:09AM (#40086365)
I suppose it could be hallucinations about itself.

I suppose it's perfectly fair for large language models not necessarily to know these things, but as far as manual fine tuning, I think it would be reasonable to build models that are capable of answering questions about which model they are, their training date, their number of training parameters, and how they are different from other models, etc. Seems like it would be helpful for it to know and not have to try to do its best guess and potentially hallucinate. Although in my experience Llama 3 seemed to know what it was, but generally speaking it seems like this is not necessarily always the case.

Re:Meta Llama 3 by LrnByTeach on Thursday April 18, 2024 @08:06PM (#40082039)
Losers & Winners from Llama-3-400B Matching 'Claude 3 Opus' etc..

Losers:

- Nvidia Stock : lid on GPU growth in the coming year or two as "Nation states" use Llama-3/Llama-4 instead spending $$$ on GPU for own models, same goes with big corporations.

- OpenAI & Sam: hard to raise speculated $100 Billion, Given GPT-4/GPT-5 advances are visible now.

- Google : diminished AI superiority posture

Winners:

- AMD, intel: these companies can focus on Chips for AI Inference instead of falling behind Nvidia Training Superior GPUs

- Universities & rest of the world : can work on top of Llama-3

Re:Meta Llama 3 by gliched_robot on Friday April 19, 2024 @01:00AM (#40083570)
Disagree on Nvidia, most folks fine-tune model. Proof: there are about 20k models in huggingface derived from llama 2, all of them trained on Nvidia GPUs.
Re:Meta Llama 3 by eggdaft on Friday April 19, 2024 @01:48AM (#40083794)
Fine tuning can take a fraction of the resources required for training, so I think the original point stands.
Re:Meta Llama 3 by nightski on Friday April 19, 2024 @07:21AM (#40085407)
Maybe in isolation when only considering a single fine tune. But if you look at it in aggregate I am not so sure.
Re:Meta Llama 3 by vineyardmike on Friday April 19, 2024 @03:34AM (#40084271)
I also disagree on Google...

Google's business is largely not predicated on AI the way everyone else is. Sure they hope it's a driver of growth, but if the entire LLM industry disappeared, they'd be fine. Google doesn't need AI "Superiority", they need "good enough" to prevent the masses from product switching.

If the entire world is saturated in AI, then it no longer becomes a differentiator to drive switching. And maybe the arms race will die down, and they can save on costs trying to out-gun everyone else.

Re:Meta Llama 3 by cm2012 on Friday April 19, 2024 @06:49AM (#40085205)
AI is taking marketshare from search slowly. More and more people will go to the AI to find things and not a search bar. It will be a crisis for Google in 5-10 years.
Re:Meta Llama 3 by mark_l_watson on Friday April 19, 2024 @08:04AM (#40085741)
I think I agree with you. I signed up for Perplexity Pro ($20/month) many months ago thinking I would experiment with it a month and cancel. Even though I only make about a dozen interactions a week, I can’t imagine not having it available.

That said, Google’s Gemini integration with Google Workplace apps is useful right now, and seems to be getting better. For some strange reason Google does not have Gemini integration with Google Calendar and asking the GMail integration what is on my schedule is only accurate if information is in emails.

I don’t intend to dump on Google, I liked working there and I use their paid for products like GCP, YouTube Plus, etc., but I don’t use their search all that often. I am paying for their $20/month LLM+Google One bundle, and I hope that evolves into a paid for high quality, no ad service.

Re:Meta Llama 3 by endisneigh on Friday April 19, 2024 @11:45AM (#40088255)
Source?
Re:Meta Llama 3 by exoverito on Friday April 19, 2024 @12:26PM (#40088766)
Anecdotally speaking I use google search much less frequently and instead opt for GPT4. This is also what a number of my colleagues are doing as well.
Re:Meta Llama 3 by zingelshuher on Saturday April 20, 2024 @02:22PM (#40099550)
I often use ChatGPT4 for technical info. It's easier then scrolling through pages whet it works. But.. the accuracy is inconsistent, to put it mildly. Sometimes it gets stuck on wrong idea.

Interesting how far LLMs can get? Looks like we are close to scale-up limit. It's technically difficult to get bigger models. The way to go probably is to add assisting sub-modules. Examples would be web search, have it already. Database of facts, similar to search. Compilers, image analyzers, etc. With this approach LLM is only responsible for generic decisions and doesn't need to be that big. No need to memorize all data. Even logic can be partially outsourced to sub-module.

Re:Meta Llama 3 by cm2012 on Sunday April 21, 2024 @05:58PM (#40109592)
I expect a 5x improvement before EOY, I think GPT5 will come out.
Re:Meta Llama 3 by LrnByTeach on Friday April 19, 2024 @02:40PM (#40090513)
my own analysis
Re:Meta Llama 3 by zingelshuher on Saturday April 20, 2024 @02:27PM (#40099606)
Only if it does nothing. In fact Google is one of the major players in LLM field. The winner is hard to predict, chip makers likely ;) Everybody jumped on bandwagon, Amazon is jumping...
Re:Meta Llama 3 by season2episode3 on Friday April 19, 2024 @05:34PM (#40092176)
Google’s play is not really in AI imo, it’s in the the fact that their custom silicon allows them to run models cheaply.

Models are pretty much fungible at this point if you’re not trying to do any LoRAs or fine tunes.

Re:Meta Llama 3 by int_19h on Saturday April 20, 2024 @04:23AM (#40095750)
There's still no other model on par with GPT-4. Not even close.
Re:Meta Llama 3 by herewego on Saturday April 20, 2024 @02:13PM (#40099454)
Many disagree. “Not even close” is a strong position to take on this.
Re:Meta Llama 3 by int_19h on Saturday April 20, 2024 @07:06PM (#40101787)
It takes less than an hour of conversation with either, giving them a few tasks requiring logical reasoning, to arrive at that conclusion. If that is a strong position, it's only because so many people seem to be buying the common scoreboards wholesale.
Re:Meta Llama 3 by herewego on Sunday April 21, 2024 @11:53AM (#40106697)
That’s very subjective and case dependent. I use local models most often myself with great utility and advocate for giving my companies the choice of using either local models or commercial services/APIs (ChatGPT, GPT-4 API, some Llama derivative, etc.) based on preference. I do not personally find there to be a large gap between the capabilities of commercial models and the fine-tuned 70b or Mixtral models. On the whole, individuals in my companies are mixed in their opinions enough for there to not be any clear consensus on which model/API is best objectively — seems highly preference and task based. This is anecdotal (though the population size is not small), but I think qualitative anec-data is the best we have to judge comparatively for now.

I agree scoreboards are not a highly accurate ranking of model capabilities for a variety of reasons.

Re:Meta Llama 3 by int_19h on Sunday April 21, 2024 @05:00PM (#40109205)
If you're using them mostly for stuff like data extraction (which seems to be the vast majority of productive use so far), there are many models that are "good enough" and where GPT-4 will not demonstrate meaningful improvements.

It's complicated tasks requiring step by step logical reasoning where GPT-4 is clearly still very much in a league of its own.

Re:Meta Llama 3 by whywhywhywhy on Friday April 19, 2024 @05:25AM (#40084758)
>AMD, intel: these companies can focus on Chips for AI Inference

No real evidence either can pull that off in any meaningful timeline, look how badly they neglected this type of computing the past 15 years.

Re:Meta Llama 3 by oelang on Friday April 19, 2024 @05:34AM (#40084800)
AMD is already competitive on inference
Re:Meta Llama 3 by int_19h on Saturday April 20, 2024 @04:25AM (#40095757)
Their problem is that the ecosystem is still very CUDA-centric as a whole.
Re:Meta Llama 3 by edward28 on Friday April 19, 2024 @06:03AM (#40084942)
Pretty sure meta still uses NVIDIA for training.
Re:Meta Llama 3 by drcode on Friday April 19, 2024 @11:58AM (#40088436)
The memory chip companies were done for, once Bill Gates figured out no one would ever need more than 64K of memory
Re:Meta Llama 3 by adventured on Friday April 19, 2024 @02:24PM (#40090324)
Misattributed to Bill Gates, he never said it.
Re:Meta Llama 3 by phkahler on Friday April 19, 2024 @06:16PM (#40092523)
Right. We all need 192 or 256GB to locally run these ~70B models, and 1TB to run a 400B.
Re:Meta Llama 3 by Rastonbury on Friday April 19, 2024 @10:00PM (#40093967)
If anything a capable open source model is good for Nvidia, not commenting on their share price but business of course.

Better open models lower the barrier to build products and drive the price down, more options at cheaper prices which means bigger demand for GPUs and Cloud. More of what the end customers pay for goes to inference and not IP/training of proprietary models
Re:Meta Llama 3 by niutech on Friday April 19, 2024 @08:43PM (#40093456)
Why does Meta embed a 3.5MB animated GIF (https://about.fb.com/wp-content/uploads/2024/04/Meta-AI-Expa...) on their announcement post instead of much smaller animated WebP/APNG/MP4 file? They should care about users with low bandwidth and limited data plan.