I can turn out some scripts a little bit quicker, or find an answer to something a little quicker than googling, but I'm still waiting on others most of the time, the overall company processes haven't improved or gotten more efficient. The same blockers as always still exist.
Like you said, there has been other tech that has changed my job over time more than AI has. The move to the cloud, Docker, Terraform, Ansible, etc. have all had far more of an impact on my job. I see literally zero change in the output of others, both internally and externally.
So either this is a massively overblown bubble, or I'm just missing something.
Humans are funny. But most cant seem to understand that the tool is a mirage and they are putting false expectations on it. E.g. management of firms cutting back on hiring under the expectation that LLMs will do magic - with many cheering 'this is the worst itll be bro!!".
I just hope more people realise before Anthropic and OAI can IPO. I would wager they are in the process of cleaning up their financials for it.
And that's the key problem, isn't it? I maintain current organizations have the "wrong shape" to fully leverage AI. Imagine instead of the scope of your current ownership, you own everything your team or your whole department owns. Consider what that would do to the meetings and dependencies and processes and tickets and blockers and other bureaucracy, something I call "Conway Overhead."
Now imagine that playing out across multiple roles, i.e. you also take on product and design. Imagine what that would do to your company org chart.
I added a much more detailed comment here: https://news.ycombinator.com/item?id=47270142
> Now imagine
> Imagine what that would do
Imagine if your grandma had wheels! She'd be a bicycle. Now imagine she had an engine. She could be a motorcycle! Unfortunately for grandma, she lives in reality and is not actually a motorcycle, which would be cool as hell. Our imagination can only take us so far.
To more substantively reply to your longer linked comment: your hypothesis is that people spend as little as 10% of time coding and the other 90% of time in meetings, but that if they could code more, they wouldn't need to meet other people because they could do all the work of an entire team themselves[1]. The problem with your hypothesis is that you take for granted that LLMs actually allow people to do the work of an entire team themselves, and that it is merely bureacracy holding them back. There have been absolutely zero indicators that this is true. No productivity studies of individual developers tackling tasks show a 10x speedup; results tend to be anywhere from +20% to minus 20%. We aren't seeing amazing software being built by individual developers using LLMs. There is still only one Fabrice Bellard in the world, even though if your premise could escape the containment zone of imagination anyone should be able to be a Bellard on their own time with the help of LLMs.
[1] Also, this is basically already true without LLMs. It is the reason startups are able to disrupt corporate behemoths. If you have just a small handful of people who spend the majority of their work time writing code (by hand! No LLMs required!), they can build amazing new products that outcompete products funded by trillion-dollar entities. Your observation of more coding = less meetings required in the first place has an element of truth to it, but not because LLMs are related to it in any particular way.
The only study showing a -20% came back and said, "we now think it's +9% - +38%, but we can't prove rigorously because developers don't want to work without AI anymore": https://news.ycombinator.com/item?id=47142078
Even at the time of the original study, most other rigorous studies showed -5% (for legacy projects, obsolete languages) to 30% (more typical greenfield AND brownfield projects) way back in 2024. Today I hear numbers up to 60% from reports like DX.
But this is exactly missing the point. Most of them are still doing things the old way, including the very process of writing code. Which brings me to this point:
> There have been absolutely zero indicators that this is true.
I could tell you my personal experience, or link various comments on HN, or point you to blogs like https://ghuntley.com/real/ (which also talks about the origanizational impedance mismatch for AI), but actual code would be a better data point.
So there are some open-source projects worth looking at, but they are typically dismissed because they look so weird to us. Here's two mostly vibe-coded (as in, minimal code review, apparently) projects that people shredded for having weird code, but is already used by 10s of 1000s of people, up to 11 - 18K stars now. Look at the commit volume and patterns for O(300K) LoC in a couple of months, mostly from one guy and his agent:
https://github.com/steveyegge/beads/graphs/commit-activity
https://github.com/steveyegge/gastown/graphs/commit-activity
It's like nothing we've seen before, almost equal number of LoC additions and deletions, in the 100s of Ks! It's still not clear how this will pan out long term, but the volume of code and apparent utility (based purely on popularity) is undeniable.
I dismiss them because Yegge's work (if it can even be called his work, given that he doesn't look at the code) is steaming garbage with zero real-world utility, not "because they look weird". You suggest the apparent utility is undeniable, while saying "based purely on popularity" -- but popularity is in no way a measure of utility. Yegge is a conman who profited hundreds of thousands of dollars shilling a memecoin rugpull tied to these projects. The actual thousands of users are people joining the hypetrain, looking to get in on the promised pyramid scheme of free money where AI will build the next million dollar software for you, if only you have the right combination of .md files to make it work. None of these software are actually materialising, so all the people in this bubble can do is make more AI wrappers that promise to make other AI wrappers that will totally make them money.
I am completely open to being proven wrong by a vibe-coded open source application that is actually useful, but I haven't seen a single one. Literally not even one. I would count literally anything where the end-product is not an AI wrapper itself, which has tens to hundreds of thousands of users, and which was written entirely by agents. One example of that would be great. Just one. There have been a couple of attempts at a web browser, and Claude's C compiler, but neither are actually useful or have any real users; they are just proofs of concept and I have seen nothing that convinces me they are a solid foundation from which you could actually build useful software from, or that models will ever be on a trajectory to make them actually useful.
> popularity is in no way a measure of utility
Why would it be popular if it's not useful? Yegge is not like some superstar whose products are popular just because he made them. And while some people may be chasing dollars, most of them are building software that scratches an itch. (Search for Beads on GitHub, you'll find thousands of public repos, and lord knows how many private repos.)
Beads has certainly made my agents much more effective, even the older models. To understand its utility you have to do agentic coding for a while, see the stupid mistakes agents make because they forget everything, and then introduce Beads and see almost all those issues melt away.
> None of these software are actually materialising
They are if you look for them. There are many indications (often discussed here) showing spikes in apps on app stores, number of GitHub projects, and Show HN entries. Now, you may dismiss these as "not actually useful", and at this volume that's undoubtedly true for a lot of them.
But there is already early data showing growth not only in mobile app downloads, but also time spent per user and revenue -- which are pretty clear indications of utility: https://sensortower.com/blog/state-of-mobile-2026
Edit: it occurs to me that by "vibe-coding" we may be talking about two different things -- I tend to mean "heavily AI-assisted coding" whereas you likely mean "never look at the code YOLO coding." I'll totally agree that YOLO vibe-coded apps by non-experts will be crap. Other than Beads and Gastown I don't know of any such app that is non-trivial. But then those were steered by a highly experienced engineer, and my original point was, vibe-coding correctly could look very weird by today's best practices.
The original point that sparked this sub-thread though is that AI is being overhyped. If actual vibe coding (YOLO it, never look at or understand the code, thus truly enabling non-technical folk to have revolutionary power and ability) doesn't work, then AI is yet just another tool in the toolbelt like any other developer life enhancing tech we've had so far, it's just a new form of IDE.
Being a new form of IDE, while very useful, isn't exactly entire economy transforming revolutionary tech. If it can't be used by someone with zero computer/eng experience to build something useful and revenue generating, the amount of investment we've seen into it is way overblown and is well overdue for a pretty severe correction.
I buy AI as a "developer enhancing tool" just like any other devtools that we've seen over my career. I don't currently buy it as a "total labor economy transformation force."
So when I see people online say they feel 10x productive, I tend to believe them. But I'm working solo, and have none of the encumbrances and "Conway Overhead" of coordinating with a lot of other people, so I also understand why the overall effect is so limited. Which is why I think current companies are "shaped wrong" for AI.
When companies eventually adapt, it will be a "labor economy transformation force" because the same dynamics will play out across all knowledge work. And I am not talking as an AI booster, but as a parent whose kids are interested in software engineering; I have every incentive to hope my prognostications do not come true, but I prefer being prepared for the worst.
If you are referring to the following quote [0], you are off by a sign:
> we now estimate a speedup of -18% with a confidence interval between -38% and +9%.
You'd get the same sort of results if you were studying the benefits of substance abuse.
"It is difficult to study the downsides of opiates because none of our participants were willing to go a day without opiates. For this reason, opiates must be really good and we're just missing something."
The language is confusing, but the chart helps: https://metr.org/assets/images/uplift-2026-post/uplift_timel...
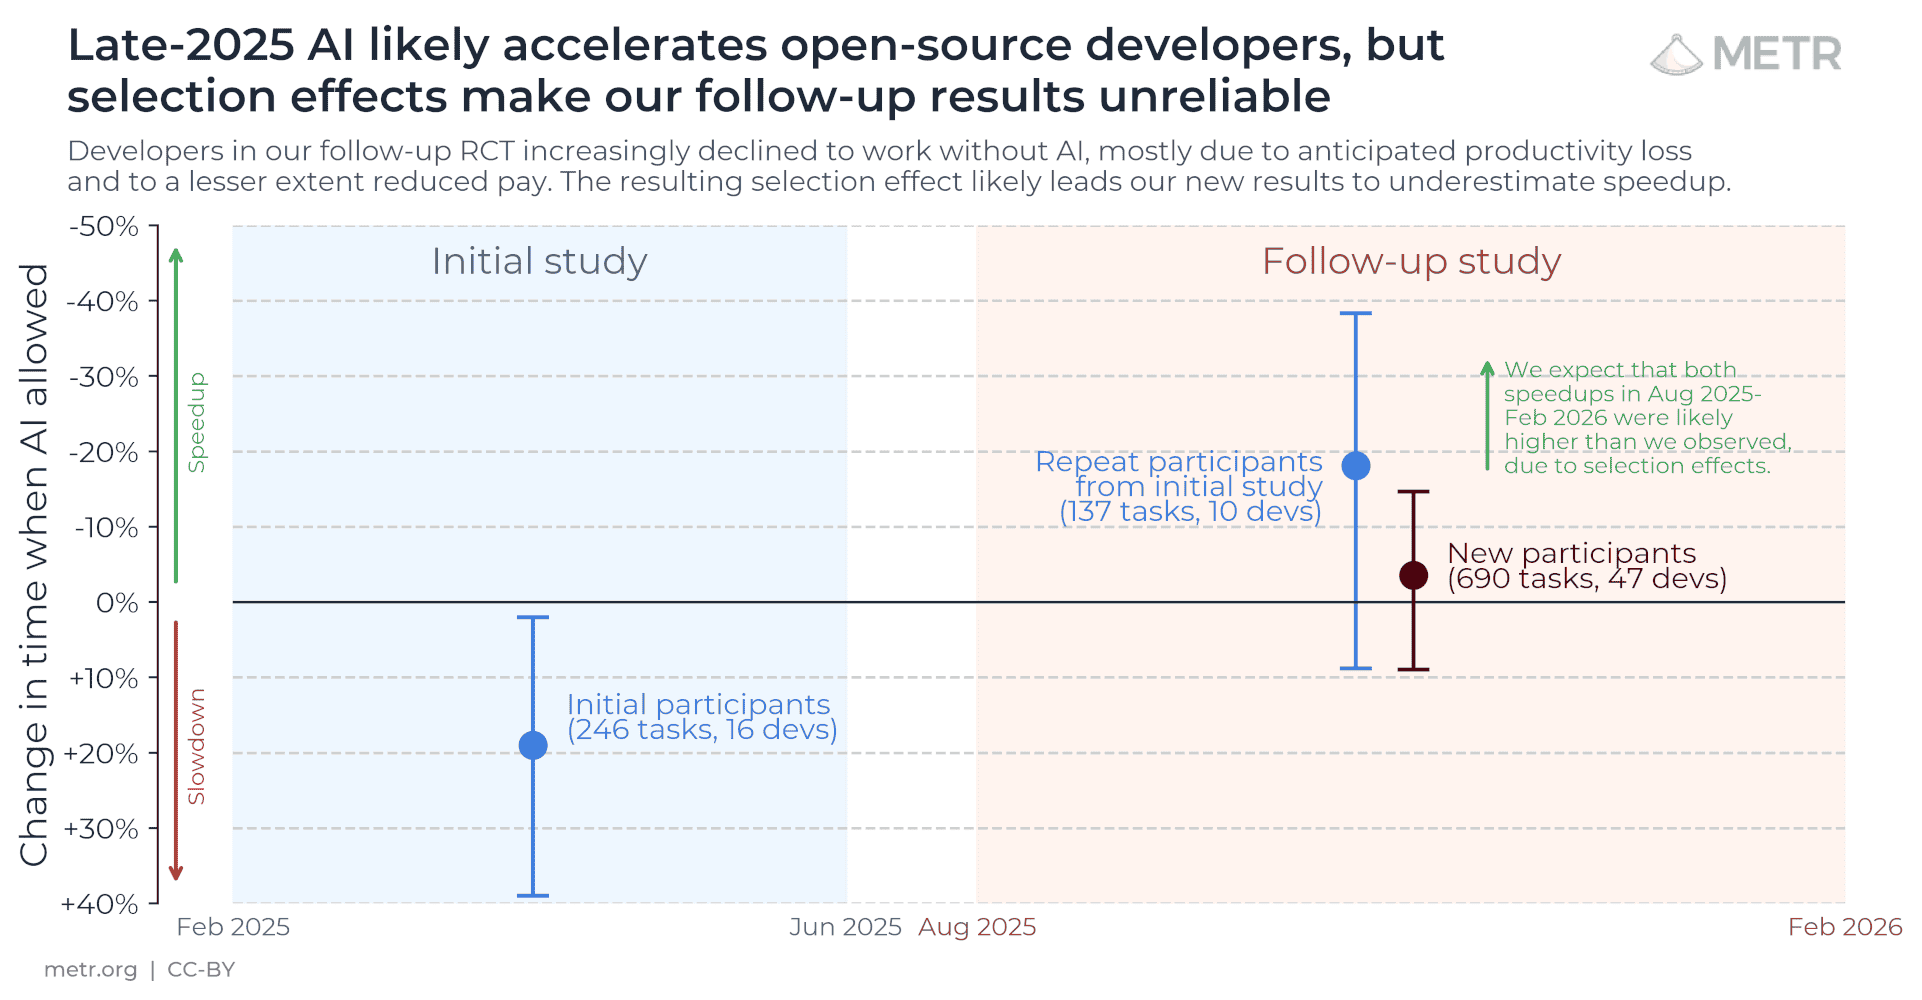
> Imagine if your grandma had wheels! She'd be a bicycle.
Too early to say what AI brings to the efficiency table I think. In some major things I do it's a 1000x speed up. In others it is more a different way of approaching a problem than a speed up. In yet others, it is a bit of an impediment. It works best when you learn to quickly recognize patterns and whether it will help. I don't know how people who are raised with ai will navigate and leverage it, which is the real long-term question (just as the difference between pre- and post-smartphone generations is a thing).
I guess it does depend on the languages involved; one study suggests that it's even worse than Google Translate for some languages, but maybe actually okay at English<-->Spanish?
> There were 132 sentences between the two documents. In Spanish, ChatGPT incorrectly translated 3.8% of all sentences, while GT incorrectly translated 18.1% of sentences. In Russian, ChatGPT and GT incorrectly translated 35.6% and 41.6% of all sentences, respectively. In Vietnamese, ChatGPT and GT incorrectly translated 24.2% and 10.6% of sentences, respectively.
It's all right there on my website in parallel text, everybody can check and come to their own conclusion rather than driving by with unhelpful generalizations. And really, that is the primary scope of these translations: as aids in reading an original text.
I've been in ops for 30 years, Claude Code has changed how I work. Ops-related scripting seems to be a real sweet spot for the LLMs, especially as they tend to be smaller tools working together. It can convert a few sentences into working code in 15-30 minutes while you do something else. I've given it access to my apache logs Elastic cluster, and it does a great job at analyzing them ("We suspect this user has been compromised, can you find evidence of that?"). It's quite startling, actually, what it's able to do.
The problem with analyzing logs is determinism. If I ask Claude to look for evidence of compromise, I can't trust the output without also going and verifying myself. It's now an extra step, for what? I still have to go into Elastic and run the actual queries to verify what Claude said. A saved Kibana search is faster, and more importantly, deterministic. I'm not going to leave something like finding evidence of compromise up to an LLM that can, and does, hallucinate especially when you fill the context up with a ton of logs.
An auditor isn't going to buy "But Claude said everything was fine."
Is AI actually finding things your SIEM rules were missing? Because otherwise, I just don't see the value in having a natural language interface for queries I already know how to run, it's less intuitive for me and non deterministic.
It's certainly a useful tool, there's no arguing that. I wouldn't want to go back to working with out it. But, I don't buy that it's already this huge labor market transformation force that's magically 100x everyone's productivity. That part is 100% pure hype, not reality.
Is it? A couple days ago I had it build tooling for a one-off task I need to run, it wrote ~800 lines of Python to accomplish this, in <30m. I found it was too slow, so I got it to convert it to run multiple tasks in parallel in another prompt. Would have taken a couple days for me to build from hand, given the number of interruptions I have in the average day. This isn't a one-off, it's happening all the time.
But, to be robust you want a signal handler with clean shutdown, a circuit breaker, argument processing (100 lines right there), logging, reporting progress to our dashboard (it's going to run 10-15 days), checking errors and exceptions, retrying on temp fail, documentation... It adds up.
So it could be shorter, but it's not like there is anything superfluous in it.
Imo it's only a matter of time as companies start to figure out how to use ai. Companies don't seem to have real plans yet and everyone is figuring out ai in general out.
Soon though I will think agents start popping up, things like first line response to pages, executing automation
Maybe 2 years ago Ai was doing random stuff and we got all those funny screenshots of dumb gemini answers. The indeterminism leading to random stuff isn't really an issue any more.
The way it thinks keeps it on track.
Opus 4.6 didn't have an issue with this question though.
No, but it can show unreliability for adjacent tasks. Identifying a CIDR block in traffic logs is a normal part of an ops work flow. It means it's more likely to fail if you need to generate a complex Regex to filter PII from a terabyte of logs. If the model has a blind spot for specific characters because it tokenizes words instead of seeing individual characters, then it can miss a critical path of failure because the service name didn't fit its probabilistic training.
Maybe you need to boilerplate Terraform. If the model can't reliably (reliably, as in, 100% deterministic, does this without fail) parse constraints, it's not just a funny mistake it's a potential 5 figure billing error.
Ops can't run on "mostly accurate." That's just simply not good enough. We need deterministic precision.
For AI to be useful in this world to the extent others have claimed it is for software eng, we'll likely need more advanced world models, not just something that can predict the next most likely token.
If your Ai work flow is still dumping logs into a chat and saying search it for some pattern, then you should see what something like Claude code approaches problems. These agents aren't building scripts to solve problems. Which is your deterministic solution.
Claude resorting to writing code for everything, because that's all the model can do without too many hallucinations and context poisoning, is just a higher speed REPL. Great, that's useful.
But that's not what is being hyped and sold. What's being hyped and sold is "You don't need an Ops guy anymore, just talk to the computer." Well, what happens when the AI decides the "fix" is to just open up 0.0.0.0/0 to the world to make the errors go away? The non technical minimum wage person now just talking to the computer has no idea they just pwned the company.
If AI's answer is "Just write a script to solve the prompt" then you still need technical people, and it's vasly over hyped.
I'll be interested when you actually can just dump logs in a chat and analyze it without the model having to resort to writing code to solve the problem. That will be revolutionary. Imagine all the time I'd save by not having to make business reports, I can just tell the business people to point AI at terabytes of CSV exports and just ask it questions. That is when it will stop just being labor compression for existing engineers, and start being a world changing paradigm shift.
For now, it's just yet another tool in my toolbelt.
Can you expand on that? Because it sure seems to me like it is in fact deterministic unless the person deliberately made it otherwise
People who actually know how to think can see it a mile away.
Job done fella.
I totally understand that not everyone is having that experience. And yet until people live it, it seems they just discount the experience others are having.
I'll take the 12 month bet.
Let us not lose sight of how we got here.
It's clearly relative. For all we know you're a crap coder and AI is now your crutch. We have no evidence that with AI you are as good as an average developer with a fair amount of experience. And even if you do have a fair amount of experience, that doesn't mean you're a good coder.
The iPod project was done in months, not years. Im convinced most people aren't as good at programming / focusing on the right stuff as they claim.
Guys like you dont get it. You think OAI, Amazon etc can freely put large amounts of money into this for 5-10 years? Lmao - delusional. Investors are impatient. Show huge jumps in revenue this year or you no longer have permission to put monumental amounts of money into this anymore.
Short of that they'll just destroy the stock price by selling off; leaving employees who get paid via SBC very unhappy.
Won't matter. The Chinese models will be running on potatoes by then and be better than ever.
This place is full of bozos.
My point is the cat is out of the bag. It doesn't take massive investments to achieve iterative improvements on SOTA. As long as the technology does not plateau, smaller labs have shown it's possible to advance the frontiers independent of large companies/investments. And as these frontiers advance, more and more of economical knowledge work will be subsumed by AI. I don't see a way out of this, which is why I am a strong proponent of wealth distribution eg UBI.
There’s some neat stuff, don’t get me wrong. But every additional tool so far has started strong but then always falls over. Always.
Right now there’s this “orchestrator” nonsense. Cool in principle, but as someone who made scripts to automate with all the time before it’s not impressive. Spent $200 to automate doing some bug finding and fixing. It found and fixed the easy stuff (still pretty neat), and then “partially verified” it fixed the other stuff.
The “partial verification” was it justifying why it was okay it was broken.
The company has mandated we use this technology. I have an “AI Native” rating. We’re being told to put out at least 28 commits a month. It’s nonsense.
They’re letting me play with an expensive, super-high-level, probabilistic language. So I’m having a lot of fun. But I’m not going to lie, I’m very disappointed. Got this job a year ago. 12 years programming experience. First big tech job. Was hoping to learn a lot. Know my use of data to prioritize work could be better. Was sold on their use of data. I’m sure some teams here use data really well, but I’m just not impressed.
And I’m not even getting into the people gaming the metrics to look good while actually making more work for everyone else.
Sunk cost fallacy is very real, for all involved. Especially the model producers and their investors.
Sunk cost fallacy is also real for dev's who are now giving up how they used to work - they've made a sunk investment in learning to use LLMs etc. Hence the 'there's no going back' comments that crop up on here.
As I said in this thread - anyone who can think straight - Im referring to those who adhere to fundamental economic principles - can see what's going on from a mile away.
Its not rocket science to measure actually. The issue is most people dont know how to think properly to invent the right proxies.
No simply 'producing a feature' aint it bud. That's one piece of the puzzle.
I recently used copilot.com to help solve a tricky problem for me (which uses GPT 5.1):
   I have an arbitrary width rectangle that needs to be broken into smaller
   random width rectangles (maintaining depth) within a given min/max range.
So I poked the machine.
The next result used dynamic programming and generated every possible output combination. With a sufficiently large (yet small) rectangle, this is a factorial explosion and stalled the software.
So I poked the machine.
I realized this problem was essentially finding the distinct multisets of numbers that sum to some value. The next result used dynamic programming and only calculated the distinct sets (order is ignored). That way I could choose a random width from the set and then remove that value. (The LLM did not suggest this). However, even this was slow with a large enough rectangle.
So I poked my brain.
I realized I could start off with a greedy solution: Choose a random width within range, subtract from remaining width. Once remaining width is small enough, use dynamic programming. Then I had to handle the edges cases (no sets, when it's okay to break the rules.. etc)
So the LLMs are useful, but this took 2-3 hours IIRC (thinking, implementation, testing in an environment). Pretty sure I would have landed on a solution within the same time frame. Probably greedy with back tracking to force-fit the output.
Sorry to be so blunt, but it's not surprising that you aren't able to get much value from these tools, considering you don't use them much.
Getting value from LLMs / agents is a skill like any other. If you don't practice it deliberately, you will likely be bad at it. It would be a mistake to confuse lack of personal skill for lack of tool capability. But I see people make this mistake all the time.
If it's "you didn't explain the problem clearly enough", then that aligns with my original comment.
"I have an arbitrary width rectangle that needs to be broken into smaller random width rectangles (maintaining depth) within a given min/max range. The solution needs to be highly performant from an algorithmic standpoint, well-tested using TDD and Red/Green testing, written in python, and not have any subtle errors."
It got the answer you ended up with (if I'm understanding you correctly) the first time in just over 2 minutes of working, and included a solid test suite examining edge cases and with input validation.
I appreciate you testing, even though it's not a great comparison:
- My feedback cycle of LLM prompting forced me to be more explicit with each call, which benefited your prompt since I gave you exactly what to look for with fewer nuances.
- Maybe GPT 5.1 is old or kneecapped for newer versions of GPT
- Maybe Opus/Claud is just a way better model :P
Please post the code!
Edit: Regarding "exactly what to look for", when solving a new problem, rarely is all the nuance available for the first iteration.
The specific way it applies to your specific situation, if it exists, either hasn't been found or hasn't made its way to you. It really is early days.
Are you hiring?
IMO AI will make 70-80% job obsolete for sure.
lol, that sounds like a disaster for the codebase.
I've seen lots of people say AI can basically code a project for them. Maybe it can, but that seems to heavily depend on the field. Other than boilerplate code or very generic projects, it's a step above useless imo when it comes to gamedev. It's about as useful as a guy who read some documentation for an engine a couple years ago and kind of remembers it but not quite and makes lots of mistakes. The best it can do is point me in the general direction I need to go, but it'll hallucinate basic functions and mess up any sort of logic.
Am trying to compare this to reports that people are not reviewing code any more.
For me this is a huge boost in productivity. If I remember how I was working in the past (example of Google integration):
Before:
    * go through docs to understand how to start (quick start) and things to know
    * start boilerplate (e.g. install the scripts/libs)
    * figure out configs to enable in GCP console
    * integrate basic API and test
    * of course it fails, because its Google API, so difficult to work with
    * along the way figure out why Python lib is failing to install, oh version mismatch, ohh gcc not installed, ohh libffmpeg is required,...
    * somehow copy paste and integrate first basic API
    * prepare for production, ohhh production requires different type of Auth flow
    * deploy, redeploy, fix, deploy, redeploy
    * 3 days later -> finally hello world is working
    * Hey my LLM buddy, I want to integrate Google API, where do I start, come up with a plan
    * Enable things which requires manual intervention
    * In the meantime LLM integrates the code, install lib, asks me to approve installation of libpg, libffmpeg,....
    * test, if fails, feed the error back to LLM + prompt to fix it
* deployThe docs used to be good enough that there would be an example which did exactly what you needed more often than the llm gets it right today.
1) Do that inside their IDEs, which is less funny
2) Generate blog post about it instead of memes
from stackoverflow import quick_sort
If not, then you’re not close to the cutting edge.
So the good old days before search engines were drowning with ads and dark patterns. My assumption is big LLMs will go in the same direction after market capture is complete and they need to start turning a profit. If we are lucky the open source models can keep up.
Arguably this solution is "better" because you don't even really need to understand that you have specific problems to have the agent solve them for you, but I fail to see the point of keeping these people employed in that case. If you haven't been able to solve your own workflow issues up until now I have zero trust in you being able to solve business problems.
I disagree with "always".
This is only the recent wave of brogrammers who care nothing about the quality of the tech and are only in this industry for the gold rush.
They aren't inherently technically minded, they just know how to schmooze their way around and convince decision makers to follow capricious trends over solid practices.
A famous economist once said, "You can see the computer age everywhere but in the productivity statistics."
There are many reasons for the lag in productivity gain but it certainly will come.
The loss of skills, complete loss of visibility and experience with the codebase, and the complete lack of software architecture design, seems like a massive killer in the long term
I have a feeling that we're going to see productivity with AI drop through the floor
Just yesterday I asked Opus 4.6 what I could do to make an old macOS AppKit project more testable, too lazy to even encumber the question with my own preferences like I usually do, and it pitched a refactor into Elm architecture. And then it did the refactor while I took a piss.
Why would you think you have your finger on the pulse of general software trends like that when you use the same, what, dozen apps every week?
Just looking at my own productivity, as mere sideprojects this month, I've shipped my own terminal app (replaced iTerm2), btrfs+luks NAS system manager, overhauled my macOS gamepad mapper for the app store, and more. All fully tested and really polished, yet I didn't write any code by hand. I would have done none of that this month without AI.
You'd need some real empirics to pick up productivity stories like mine across the software world, not vibes.
Most of the software I replaced was software I was paying for (iStat Menus, Wispr Flow, Synology/Unraid). That I was paying for a project I could trivially take on with AI was one of the main incentives to do it.
I'm happy to sell it to you, though it is also free. I guided Claude to write this in three weeks, after never having written a line of JavaScript or set up a server before. I'm sure a better JavaScript programmer than I could do this in three weeks, but there's no way I could. I just had a cool idea for making advertising a force for good, and now I have a working version in beta.
I'd say it is better software, but better is doing a lot of heavy lifting there. Claude's execution is average and always will be, that's a function of being a prediction engine. But I genuinely think the idea is better than how advertising works today, and this product would not exist at all if I had to write it myself. And I'm someone who has written code before, enough that I was probably a somewhat early adopter to this whole thing. Multiply that by all the people whose ideas get to live now, and I'm sure some ideas will prove to be better even with average execution. Like an llm, that's a function of statistics.
This concept will never work outside of their own head. People continue to think producing something is the hard part my word.
No idea. I certainly didn't get it. Goal tracker is one thing, ad blocker is another thing. Why would I want to combine them? And why would I want to see any ads at all? Perhaps I'm just not the target audience...
That second point is the part that seems obvious to me but I have a hard time communicating.
I didnt get it either on first glance when scrolling down the whole page
AI writes bad software by virtue of it being written by the AI, not you. No actual team member understands what's going on with the code. You can't interrogate the AI for its decision making. It doesn't understand the architecture its built. There's nobody you can ask about why anything is built the way it is - it just exists
Its interesting watching people forget that the #1 most important thing is developers who understand a codebase thoroughly. Institutional knowledge is absolutely key to maintaining a codebase, and making good decisions in the long term
Its always been possible to trade long term productivity for short term gains like this. But now you simply have no idea what's going on in your code, which is an absolute nightmare for long term productivity
The status quo was that I have no better understanding of code I haven't touched in a year, or code built by other people. Now I have the option to query the code with AI to bootstrap my understanding to exactly the level necessary.
But you're wrong on every claim about LLM capabilities. You can ask the AI exactly why it decided on a given design. You can ask it what the best options were and why it chose that option. You can ask it for the trade-offs.
In fact, this should be part of your Plan feedback loop before you move to Implementation.
If you choose to take AI reasoning at face value, you're choosing to accept pretty strong technical debt
Remember this famously happened before, in the 1970s
Predictions without a deadline are unfalsifiable.
A Commodore 64 was a cool gadget, but “the family computer” became a device that commoditized the productivity. The opportunity cost of applying a computer to try something new went to near zero.
It might have been harder for someone to improve the productivity of an old factory in Shreveport, Louisiana with a computer than it was for the upstarts at id to make Doom.
We aren't fungible workers in a low skill industry. And if you find yourself working in a tech company without equity: just don't, leave. Either find a new tech company or do something else altogether.
I'm not sure what to say. It's like someone claiming that automobiles don't improve personal mobility. There are a lot of logical reasons to be against the mass adoption of automobiles, but "lack of effectiveness as a form of personal mobility" is not one of them.
Hearing things like this does give me a little hope though, as I think it means the total collapse of the software engineering industry is probably still a few years away, if so many companies are still so far behind the curve.
I prefer walking or cycling and often walk about 8km a day around town, for both mobility and exercise. (Other people's) automobiles make my experience worse, not better.
I'm sure there's an analogy somewhere.
(Sure, automobiles improve the speed of mobility, if that's the only thing you care about...)
If you can’t be exposed to it in your day job, start using Claude opus in the evening so you know what’s coming.
Maybe I will be replaced by matrix multiplication in my job, but if I need to use LLM at some point I expect little benefit from starting now.
Yes, I tried to use Claude Code two months ago. It was scary, but not useful.
If it would be useful I would continue to use it, but at this point I would not use even if it would be free, not proprietary and not funding replacing me.
Because I can get so much done, I've lost my sense for what's enough. And if I can squeeze out a bit more relatively easily, why wouldn't I? When do I hit the brakes?
There are some tasks where LLMs are not all that helpful, and I find myself kind of savoring those tasks.
I'm surprised you don't notice a difference. Where I work it has been transformative. Perhaps it's because we're relatively small and scrappy, so the change in pace is easier with less organizational inertia. We've dramatically changed processes and increased outputs without a loss in quality. For less experienced programmers who are more interested in simple scripts for processing data, their outputs are actually far better, and they're learning faster because the Claude Code UI exposes them to so many techniques in the shell. I now see people using bash pipes for basic operations who wouldn't have known a thing about bash a couple years ago. The other day a couple less-technical people came to me to learn about what tests are. They never would have been motivated to learn this before. It's really cool.
It doesn't reduce work at all, though. We're an under-funded NGO with high ambition. These changes allow us to do more with the same funding. Hopefully it allows us to get more funding, too. I can't see it leading to anyone being let go; we need every brain we can get.
Every time I say this people get really angry, but: so far AI has had almost no impact on my job. Neither my dev team nor my vendors are getting me software faster than they were two years ago. Docker had a bigger impact on the pipeline to me than AI has.
Maybe this will change, but until it does I'm mostly watching bemusedly.