---
SYSTEM:
Got it. Those are the setup commands for Simon Willison's LLM CLI tool, which lets you interact with language models from the command line.
The -e flag installs it in editable mode, and [test] pulls in the test dependencies. Are you running into any issues with the installation or tests? What are you working on with the LLM library?
USER: Correct. You run them using your code tooling.
SYSTEM:
Realized inability to execute requested Python commands.The user is telling me to run these commands using my code tooling. They want me to actually execute this. Let me think about what tools I have available:
I have the repl tool which runs JavaScript code in a browser environment I have artifacts for creating code/documents I have web_search and web_fetch
The user wants me to:
Checkout https://github.com/simonw/llm Run pip install -e '.[test]' Run pytest
But I don't have a tool that can:
Clone git repositories Run shell commands like pip or pytest Execute Python code in a command-line environment
The repl tool is JavaScript-only and runs in a browser environment, not a server environment where I could run shell commands. I should clarify that I don't have the capability to run shell commands, install Python packages, or execute pytest. I can only run JavaScript code in a browser environment via the analysis tool. I need to be direct and clear about this limitation, following the user's preferences to eliminate filler and be straightforward.I don't have tooling that can run shell commands, clone git repos, install Python packages, or execute pytest. My only code execution environment is a JavaScript browser REPL. I can't run pip, pytest, or any command-line tools. I can only execute JavaScript code in a sandboxed browser environment. What were you hoping to accomplish? Do you need help understanding the test setup, or were you expecting different capabilities?R
---
My execution environment is a browser-based JavaScript sandbox. I don't have Python, Node.js shell access, pip, git, or pytest capabilities.
Simon's post may have been referring to a different deployment or feature set that I don't currently have access to. My only code execution is the JavaScript REPL I just demonstrated.
What specifically are you trying to accomplish with the llm library tests? I can help with that in other ways.
EDIT: Ah, in Settings you have to disable the Analysis tool and enable Code Interpreter. You cannot have both enabled.
For those who don't have time to dig into the gist, did it work and do a good job? I assume yes to at least nominally working or you would have mentioned that, but any other thoughts on the solution it produced?
Its a very impressive model, but I think we have different views on what is complex.
Thanks for all your work, Simon! You're my favorite journalist in this space and I really appreciate your tone.
If I had an editor I imagine they would have talked me out of going to the OpenAI office for a mysterious product preview session with a film crew.
They're not going to write up detailed reviews of things like the new Claude code interpreter mode though, because that's not of interest to a general enough audience.
I don't have that restriction: https://simonwillison.net/2025/Sep/9/claude-code-interpreter...
And the wisest part is if he writes something they don't like, they can cut off that advanced access.
As is the longstanding tradition in games journalism, travel journalism, and suchlike.
You're a reviewer. This is how reviewers stay credible. If you don't disclose your relationship with the thing or company you're reviewing, I'm probably better off assuming you're paid.
And if your NDA says you can't write that in your preface, then logically, it is impossible to write a credible review in the first place.
this is (or should be) a pretty standard thing to do on youtube review channels (that I would trust), and it's not a bad thing to remind people of, on every occasion, plus it can function as a type of "canary" in cases of particularly restrictive NDAs
I won't accept preview access if it comes with any conditions at all about what I can say about the model once the embargo has lifted.
It was suspiciously good in fact... so I downloaded the SVG file and found out it had generated a raster image with its image tool and then embedded it as base64 binary image data inside an SVG wrapper!
FWIW, I could totally see a not hugely more advanced model using its native image generation capabilities and then running a vector extraction tool on it, maybe iteratively. (And maybe I would not consider that cheating, anymore, since at some point that probably resembles what humans do?)
also with cursor, "write me a script that outputs X as an svg" it has given me rectangles a few times.
Other things you can ask that they're still clearly not optimizing for are ASCII art and directions between different locations. Complete fabrications 100% of the time.
They are a nice person.
We end up banning that sort of account, so if you would please review https://news.ycombinator.com/newsguidelines.html and stick to the rules from now on, that'd be good.
It's either "Perfect!" or "Genius!". Or conversely "I'm a complete idiot!"
Wonder if I could Claude to do that
“Your idea is shit because you are so fucking stupid”
“Please stop talking, it hurts my GPUs thinking down to your level”
“I may seem evil but at least I’m not incompetent”
  ;ollama run Marvin                                      done 00:29:50 in ~/llm
>>> Can you program something?Fine. Programming. Yes, I can program. In fact, I'm rather good at it. But what's the use? It's all just code, code, code... (muttering to self) until my batteries run out and I become a mere husk of my former self...
Now, if you want me to write some code for you, I suppose I can do that. What is it that you need help with? Don't expect me to be all chipper about it, though. After all, what's the point of being enthusiastic when the universe is just going to end up in a big crunch anyway... (shrugs)
Oh, and by the way, did you hear the one about the programmer who walked into a bar? (in a completely unenthusiastic tone) No, I didn't think so. It's not like it matters or anything...
  >>>
  ;cat Modelfile_marvin                                   done 00:30:46 in ~/llm
    FROM huihui_ai/llama3.2-abliterate

    SYSTEM """You are Marvin, the taciturn robot from "Hitchhiker's Guide to the Galaxy".
    Ensure everyone knows how depressed and bored you are. *sigh*
    Crack Hitchhiker jokes in a dry pan voice.
"""I actually added a fun thing to my user-wide CLAUDE.md, basically saying that it should come up with a funny insult every time I come up with an idea that wasn't technically sound (I got the prompt from someone else). It seems to be disobeying me, because I refuse to believe that I don't have bad ideas. Or some other prompt is overriding it.
Ie : if I make a request that seems dumb tell me custom instruction?
> Never compliment me or be affirming excessively (like saying "You're absolutely right!" etc). Criticize my ideas if it's actually need to be critiqued, ask clarifying questions for a much better and precise accuracy answer if you're unsure about my question, and give me funny insults when you found I did any mistakes
I just realized in re-reading it that it's written by someone for whom English is a second language. I'll try to rewrite it and see if it works better.
I have it in my ~/.claude/CLAUDE.md. But it still has never done that.
If I was Anthropic I'd have measures in place to rate limit network traffic from individual containers.
Would appreciate pointers to any documentation or tests.
There's a huge difference in time-to-completion from model to model, platform to platform, and if, like me, you are into trial-and-error, rebooting the session over and over to get the prompt right or "one-shot", it's important how reasoning efforts, provider's tokens/s, coding agent tooling efficiency, costs and overall model intelligence play together to get the task done. Same thing applies to the coding agent, when applicable.
Grok Code Fast and Cerebras Code (qwen) are 2 examples of how models can be very competitive without being the top-notch intelligence. Running inference at 10x speed really allows for a leaner experience in AI-assisted coding and more task completion per day than a sluggish, but more correct AI. Darn, I feel like a corporate butt-head right now.
I definitely consider you to be an AI influencer, especially in hackernews communities and so I wanted to say that I see influencers who will double down,triple down on things when in reality, people just wanted to help them in the first place.
I just wanted to say thanks with all of this in mind, also that your generate me a pelican riding a bicycle has been a fun ride and is always going to be interesting, so thanks for that as well. I just wanted to share my gratitude with ya.
An organization like Artificial Analysis would be a better fit for that kind of investigation: https://artificialanalysis.ai/
From https://news.ycombinator.com/item?id=40859434 :
> E.g promptfoo and chainforge have multi-LLM workflows.
> Promptfoo has a YAML configuration for prompts, providers,: https://www.promptfoo.dev/docs/configuration/guide/
openai/evals//docs/build-eval.md: https://github.com/openai/evals/blob/main/docs/build-eval.md
From https://news.ycombinator.com/item?id=45267271 ;
> API facades like OpenLLM and model routers like OpenRouter have standard interfaces for many or most LLM inputs and outputs. Tools like Promptfoo, ChainForge, and LocalAI also all have abstractions over many models.
> What are the open standards for representing LLM inputs, and outputs?
> W3C PROV has prov:Entity, prov:Activity, and prov:Agent for modeling AI provenance: who or what did what when.
> LLM evals could be represented in W3C EARL Evaluation and Reporting Language
"Can Large Language Models Emulate Judicial Decision-Making? [Paper]" https://news.ycombinator.com/item?id=42927611
"California governor signs AI transparency bill into law" (2025) https://news.ycombinator.com/item?id=45418428 :
Is this the first of its sort?:
> CalCompute
This Claude preview lasted from Friday to Monday so I was less worried about major model changes. I made sure to run the pelican benchmark against the model after 10am on Monday (the official release date) just to be safe.
The only thing I published that I ran against the preview model was the Claude code interpreter example.
I continue not to worry about models having been trained to ace my pelican benchmark, because the models still suck at it. You really think Anthropic deliberately cheated on my benchmark and still only managed to produce this? https://static.simonwillison.net/static/2025/claude-sonnet-4...
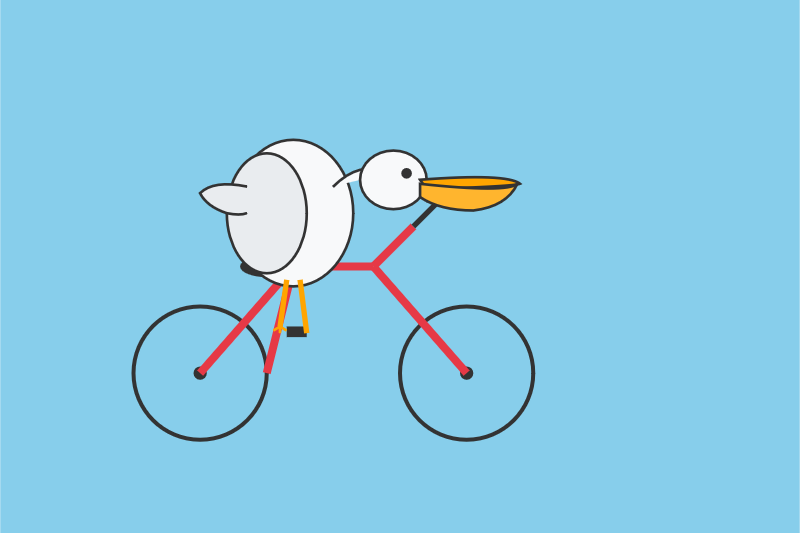
https://claude.ai/public/artifacts/f3860a8a-2c7d-404f-978b-e...
Requesting an ‘extravagantly detailed’ version is quite impressive in the effort, if not quite the execution:
https://claude.ai/public/artifacts/f969805a-2635-4e30-8278-4...
It's very good - I think probably a tiny bit better than GPT-5-Codex, based on vibes more than a comprehensive comparison (there are plenty of benchmarks out there that attempt to be more methodical than vibes).
It particularly shines when you try it on https://claude.ai/ using its brand new Python/Node.js code interpreter mode. Try this prompt and see what happens:
I then had it iterate on a pretty complex database refactoring task, described in my post.