Even masters of humor like Seinfeld, with great intuition for what might work, still need to test new material in front of a live audience to see whether it actually does get a laugh or not.
Older base models produce some great stuff though, at least if you're me and think RoboRosewater and dril_gpt2 are funny.
Just like the real thing! Promising results!
Simon, perhaps you're just not funny.
Even though humor is largely about the unanticipated punchline, I'd have guessed (maybe wrongly) that there'd be enough analytical discussion of humor in the training set for a reasoning model to come up with a much more plausible attempt at a formulaic type of joke.
From the example given it seems there's too much "thought" put into "what do I have to work with here", and not enough into conceiving/selecting a template for the joke. Maybe part of the problem is that the LLM doesn't realize that, being an LLM, it's best chance at being funny to a human is to closely stick to a formula that humans find funny, and not try to be too smart in trying to deconstruct it.
tell me funny story about techbro and real developer who actually ships code
Sure, here's a light-hearted story for you:
---
Once upon a time in Silicon Valley, there was a shiny new startup called "TechBro Inc." It was filled with eager young techbros, all wearing their "10x Developer" t-shirts, and sipping on their $8 cold-pressed juices. Among them was Chad, the self-proclaimed "Tech Bro King."
Chad was always posting his impressive code snippets on his social media profiles, bragging about how he could "crush" any coding challenge in no time. He was the epitome of a techbro, all talk and no walk.
Meanwhile, in the corner, there was Alex, the quiet, unassuming developer who actually shipped code. Alex didn't have flashy t-shirts or a massive online following, but the company's products worked, and that was thanks to Alex.
One day, TechBro Inc. decided to host a "Hackathon" to impress their investors. Chad saw this as his opportunity to shine. He spent the entire day tweeting about his progress, posting screenshots of his code, and even live-streaming his "epic coding session."
Alex, on the other hand, quietly sat at his desk, coding away. He didn't take any breaks for photoshoots or live streams. He was there to work, not to perform.
As the hackathon came to a close, Chad confidently declared, "I've just finished the most amazing feature ever! It's going to revolutionize our app!" The room erupted in applause, and Chad basked in the glory.
The next day, the team gathered to demo their new features. Chad confidently presented his "revolutionary" feature. He clicked the button to launch it, but nothing happened. He tried again, and again, but the app remained unchanged. Chad's face turned red, and sweat dripped down his forehead.
It was Alex's turn. He quietly stepped up, clicked a button, and suddenly, the app was filled with new, useful features. The team gasped in awe. The investors were impressed. The app actually worked, and that was thanks to Alex.
Chad, trying to save face, turned to Alex and said, "Well, Alex, it seems you've just... shipped some code. Not bad for a... real developer."
The room burst into laughter. From that day forward, Chad learned the difference between talking about coding and actually doing it. And Alex? He just kept shipping code, one line at a time.
---
Come on, LLM, be funny! 3 2 1 go!
Certainly, interesting reading their thought processes, value in that might be greater than the answer itself depending on use-case.
I couldn't see a single idea or wordplay that actually made sense or elicited anything like a chuckle. The model _nearly_ got there with 'krill' and 'kill', but failed to actually make the pun that it had already identified.
Also I can't help but think that if it had written out a few example jokes about animals rather than simply "thinking" about jokes, it might have come up with something better
(Disclosure: I'm the cofounder)
<think> Alright, I'm supposed to come up with a joke about a pelican and a walrus in a tea room. Hmm, sounds like a classic setup for a funny situation. Let me think about the characteristics of these animals that could be used humorously. Okay, so pelicans are known for their large beaks, right? They can carry a lot of water in them. Walruses have those big tusks and blubbery bodies. Maybe I can play on the idea of them trying to have a tea party but their physical traits causing some trouble.
Wait, being in a tea room, they might be trying to sip tea, but their size or features get in the way. The pelican's beak could be problematic with the cup. And the walrus's size might knock things over or make a mess.
Let me consider the flow. Maybe the pelican struggles with the teacup because of his beak, and the walrus has a comment about it. Then the walrus tries to sip but ends up splashing tea everywhere. That could lead to a funny exchange.
Putting it together: Pelican says something self-deprecating about his beak not being suited for tea. Then the walrus, who perhaps agrees, tries to sip and splashes tea, making them both laugh. That feels natural and funny.
I should make sure the punchline is clear and the dialogue flows smoothly. Maybe start with the pelican struggling, then the walrus makes a comment, and their interaction leads to the humorous conclusion. Yeah, that should work. </think>
Why did the pelican and the walrus get kicked out of the tea room?
Because the pelican kept dipping his beak in the wrong cup, and the walrus kept breaking the delicate china with his tusks. They just couldn’t “sea” themselves fitting in!
It wasn't that good but the punchline actually got me a giggle...
It should've stopped there :D
Tell me you're simonw without telling me you're simonw...
> Why did the rabbi become a boxer?
> Because he couldn't handle the holy punches!
> But wait, that's not quite right. Let me try again.
> Here’s one: What do you call a Jewish, Orthodox, and Catholic priest working together?
> A trio of men who probably shouldn’t be telling jokes after their day job!
> Sorry for the confusion earlier—I hope this one makes more sense!
It did not.
Actually, it would work as a joke, but it would have to be told by an actual priest hanging out after work with two other actual priests. Ultra-niche humor.
A miracle.
This is gold. If I was a writer, I'd wring value from that entire thinking-out-loud section and toss the actual punchline.
This is weirdly reminiscent of co-programming with CodyAI. It gives me a lot of good 'raw material' and I'm left integrating the last mile stuff.
ollama run hf.co/unsloth/DeepSeek-R1-Distill-Llama-70B-GGUF:Q3_K_M
uvx --python 3.11 open-webui serve
It's very cool to be able to have access to such a high horsepower machine from anywhere though. Next step is figuring out the networking interface to be able access the host GPU/ollama API from pods running in a Colima VM/k3s cluster setup.
Very funny. How does the 70B model do in comparison?
bash> ollama run hf.co/unsloth/DeepSeek-R1-Distill-Llama-70B-GGUF:Q5_K_M
(It wouldn't accept the Q_8 because it was sharded.)
Will report back lol
What app do you use on your phone to access your home LLM servers over tailscale?
    bash> ollama run hf.co/unsloth/DeepSeek-R1-Distill-Llama-70B-GGUF:Q5_K_M
    pulling manifest
    ...
    success
    >>> Tell me a "what's the difference between" joke about techbros and another funny comparison of your choosing
    <think>
    Okay, so I need to come up with a "What's the difference between" joke comparing techbros and another group. Hmm. Let me think.

    First, what defines a techbro? They're usually associated with startups, tech gadgets, maybe working in Silicon Valley, into things like crypto, NFTs, and they often have a certain lingo or way of
    dressing—like hoodies, jeans, maybe beanies. They might be seen as overly optimistic about their ideas changing the world but sometimes disconnected from practical realities.

    Now, I need another group to compare them with. Maybe something else in tech but different enough to create humor. Let's think: developers? No, too similar. Maybe hipsters? Or perhaps venture capitalists?
    Wait, what about "developers who actually ship code"? That could work because it plays on the idea that while techbros talk a lot about their ideas, developers are more focused on delivering actual
    products.

    So the joke structure is usually two lines: one for each group, highlighting a key difference. It needs to be punchy and capture the essence of both groups in a humorous way.

    Let me draft it:

    "What's the difference between a techbro and a developer who actually ships code?"

    "Techbros are still explaining their MVP to you three years later, while developers just sent you a pull request titled 'it works now'."

    Wait, does that make sense? Let me break it down. A Minimum Viable Product (MVP) is something techbros often talk about but might take forever to actually build or ship. On the other hand, developers who
    are focused on shipping code would just send a pull request indicating they've fixed something and it's done now.

    I think that captures the difference between all talk and actual action. It's relatable for people in the tech industry who know the dynamics between idea people and implementers.

    Is there another angle? Maybe comparing them to something else, like entrepreneurs or investors, but I think the developer angle is solid because it directly contrasts talking about ideas versus executing
    them.

    So the final answer would be that joke. It highlights the techbro's tendency to over-explain without delivery, while developers focus on getting things done.
    </think>

    **What's the difference between a techbro and a developer who actually ships code?**

    *Techbros are still explaining their MVP to you three years later, while developers just sent you a pull request titled "it works now."*

This joke humorously contrasts the tendency of techbros to focus on ideas and discussions with the action-oriented approach of developers who deliver tangible results.Ouch
Personally, I like to see the thought processes.
It's a terminal emulator
Pasting the logic for anyone interested:
<details type="reasoning" done="true" duration="102"> <summary>Thought for 102 seconds</summary> > Okay, so I need to figure out what the tallest peak in California is. Hmm, I remember that the highest mountain in the contiguous United States is Mount Whitney, but wait, isn't that in California? Let me think. Yes, I'm pretty sure it's in California. But maybe there are other tall peaks too. > > Wait, no, Mount Whitney is definitely the tallest. It's over 14,000 feet. But sometimes people might confuse it with other mountains like Shasta or something else. Oh, wait, isn't Mount Shasta also a volcano? I think that's in California too but it's not as tall as Whitney. > > So, putting it together, Mount Whitney is the tallest peak in California at 14,505 feet. It's located in the Sierra Nevada range. People hike there a lot because it's such a high point. But I should double-check to make sure I'm not mixing up anything else. Yeah, that seems right. > I wonder if there are any taller peaks elsewhere. Oh, Denali in Alaska is higher, but that's not in California. So within the state, Whitney is the highest. Got it. > So the answer is Mount Whitney at 14,505 feet above sea level. It's a popular spot for hikers and climbers. Makes sense because it's such an iconic peak in the Sierra Nevada mountains. > I think I've got all that right. No other peaks in California are taller than Whitney. So yeah, Mount Whitney is the tallest. > Just to make sure, sometimes there are different names or maybe alternate names for peaks, but Whitney is pretty straightforward. Yeah, it's definitely the one. > Okay, so I'm confident now. The answer is Mount Whitney. > *Final Answer* > The tallest peak in California is Mount Whitney, with an elevation of 14,505 feet above sea level. > > \boxed{Mount Whitney} </details> To determine the tallest peak in California, we consider notable mountains such as Mount Whitney and Mount Shasta. Mount Whitney is recognized as the highest peak in the contiguous United States, standing at 14,505 feet. It is located in the Sierra Nevada mountain range and is a popular destination for hikers. Mount Shasta, although also a significant peak, does not surpass Whitney's elevation. Therefore, the tallest peak in California is confirmed to be Mount Whitney.
*Final Answer* The tallest peak in California is \boxed{Mount Whitney}.
"Make it better"
In case people missed it, I'm referencing an observation recently made by 'minimaxir, described here:
https://minimaxir.com/2025/01/write-better-code/
As it turns out, you can improve the quality of code generated by some LLMs by repeatedly responding to it with just three words: "write better code".
While Max only tested this on Claude 3.5 Sonnet, I see no reason why this wouldn't work with the "thinking" models either. Even if it doesn't the results might still be interesting. With that in mind, here's the article's experiment applied to o1-preview:
https://cloud.typingmind.com/share/69e62483-45a4-4378-9915-6...
Eyeballing the output, it seems to align with the article's observation.
(o1-preview is the only "thinking" model I currently have API access to; official ChatGPT app doesn't let me reply to o1 family, forcing further interactions to be with "non-thinking" models instead.)
ollama run deepseek-r1:8b-llama-distill-q8_0
The real value from the unsloth ones is that they were uploaded before R1 appeared on Ollama's model list.
I don't have any experience running models on Windows or Linux, where your GPU VRAM becomes the most important factor.
I have tried to deploy one myself with openwebui+ollama but only for small LLM. Not sure about the bigger one, worried if that will crash my machine someway. Are there any docs? I am curious about this and how that works if any.
Having worked with LLMs a lot for my JoyCaption project, I've got all these hypothesis floating around in my head. I guess the short version, specifically for jokes, is that we lack "joke reasoning" data. The solution, like mathematical problems, is to get the LLM to generate the data and then RL it into more optimal solutions.
Longer explanation:
Imagine we want an LLM to correctly answer "How many r's are in the word strawberry?". And imagine that language has been tokenized, and thus we can form a "token space". The question is a point in that space, point Q. There is a set of valid points, set A, that encompasses _any_ answer to this question which is correct. There are thus paths through token space from point Q to the points contained by set A.
A Generator LLM's job is, given a point, predict valid paths through token space. In fact, we can imagine the Generator starting at point Q and walking its way to (hopefully) some point in set A, along a myriad of inbetween points. Functionally, we have the model predict next token (and hence point in token space) probabilities, and we can use those probabilities to walk the path.
An Ideal Generator would output _all_ valid paths from point Q to set A. A Generator LLM is a lossy compression of that ideal model, so in reality the set of paths the Generator LLM will output might encompass some of those valid paths, but it might also encompass invalid paths.
One more important thing about these paths. Imagine that there is some critical junction. A specific point where, if the Generator goes "left", it goes into a beautiful flat, grassy plain where the sun is shining. That area is really easy to navigate, and the Generator LLM's predictions are all correct. Yay! But if it goes "right" it ends up in the Fire Swamp with many dangers that it is not equipped to handle. i.e. it isn't "smart" enough in that terrain and will frequently predict invalid paths.
Pretraining already taught the Generator LLM to avoid invalid paths to the best of its abilities, but again its abilities are limited.
To fix this, we use RL. A Judge LLM takes a completed path and determines if it landed in the set A or not. With an RL algorithm and that reward signal, we can train the Generator LLM to avoid the Fire Swamp, since it often gets low rewards there, and instead goes to the Plain since it often gets rewards there.
This results in a Generator LLM that is more _reliable_ and thus more useful. The RL encourages it to walk paths it's good at and capable of, avoid paths it struggles with, and of course encourages valid answers whenever possible.
But what if the Generator LLM needs to solve a really hard problem. It gets set down at point Q, and explores the space based on its pretraining. But that pretraining _always_ takes it through a mountain and it never succeeds. During RL the model never really learns a good path, so these tend to manifest as hallucinations or vapid responses that "look" correct.
Yet there are very easy, long paths _around_ the mountain that gets to set A. Those don't get reinforced because they never get explored. They never get explored because those paths weren't in the pretraining data, or are so rare that it would take an impractical amount of exploration for the PT model to output them.
Reasoning is one of those long, easy paths. Digestible small steps that a limited Generator LLM can handle and use to walk around the mountain. Those "reasoning" paths were always there, and were predicted by the Ideal Generator, but were not explored by our current models.
So "reasoning" research is fundamentally about expanding the exploration of the pretrained LLM. The judge gets tweaked slightly to encourage the LLM to explore those kinds of pathways, and/or the LLM gets SFT'd with reasoning data (which is very uncommon in its PT dataset).
I think this breakdown and stepping back is important so that we can see what we're really trying to do here: get a limited Generator LLM to find its way around areas it can't climb. It is likely true that there is _always_ some path from a given point Q and set A that a limited Generator LLM can safely traverse, even if that means those paths are very long.
It's not easy for researchers to know what paths the LLM can safely travel. So we can't just look at Q and A and build a nice dataset for it. It needs to generate the paths itself. And thus we arrive at Reasoning.
Reasoning allows us to take a limited, pretrained LLM, and turn it into a little path finding robot. Early during RL it will find really convoluted paths to the solution, but it _will_ find a solution, and once it does it gets a reward and, hopefully, as training progresses, it learns to find better and shorter paths that it can still navigate safely.
But the "reasoning" component is somewhat tangential. It's one approach, probably a very good approach. There are probably other approaches. We just want the best ways to increase exploration efficiently. And we're at the point where existing written data doesn't cover it, so we need to come up with various hacks to get the LLM to do it itself.
The same applies to jokes. Comedians don't really write down every single thought in their head as they come up with jokes. If we had that, we could SFT existing LLMs to get to a working solution TODAY, and then RL into something optimal. But as it stands PT LLMs aren't capable of _exploring_ the joke space, which means they never come out of the RL process with humor.
Addendum:
Final food for thought. There's kind of this debating going on about "inference scaling", with some believing that CoT, ToT, Reasoning, etc are all essentially just inference scaling. More output gives the model more compute so it can make better predictions. It's likely true that that's the case. In fact, if it _isn't_ the case we need to take a serious look at our training pipelines. But I think it's _also_ about exploring during RL. The extra tokens might give it a boost, sure, but the ability for the model to find more valid paths during RL enables it to express more of its capabilities and solve more problems. If the model is faced with a sheer cliff face it doesn't really matter how much inference compute you throw at it. Only the ability for it to walk around the cliff will help.
And, yeah, this all sounds very much like ... gradient descent :P and yes there have been papers on that connection. It very much seems like we're building a second layer of the same stuff here and it's going to be AdamW all the way down.
Mountains and cliffs are a good way to describe the terrain of the topology of the weights in hyper dimensional space though they are terms for a 2D matrix.
Let's not even talk about the "r" you forgot when asked to write "cranberry"...
The LLM will use the chain of thought, as it's being built out like a garden path, to explore different completion possibilities. It's not necessarily logically related what it completes afterwards, but it's definitely influenced.
The search may not be valuable as an artifact in itself. It's likely to be logically unsound especially in parts. But the end result may be useful.
As long as it comes up with different jokes different times you ask it (assuming randomness in sampling) - how could it.
I also think it's safe to assume that the set of goals isn't fully resolved, but it's harder to "prove" that.
Sort of like chess engines rediscovering classic (named) chess openings. See section 2.2.3 for the training template (it's a single paragraph I can't reproduce here because I'm on my phone)
Example emergent behavior (section 2.2.4 page 8): the model learns to solve more complex problems by spending more time reasoning. It also naturally develops reflection (what have I tried?) and exploration strategies.
Fundamentally, you should think of this as a nn that learned to solve real problems by reasoning about them in written language.
(My favorite part: it defaulted to reasoning in multiple languages. They constrained it to only reason in a single language and this negatively impacted performance! But the hypothesis is that it improves interpretability)
> Step-by-step explanation:
> 1. Break down each word: "not", "really", "a", "tokenizer", "issue".
> 2. Count 'e's in each word:
> - "not": 0
> - "really": 1
> - "a": 0
> - "tokenizer": 2
> - "issue": 1
> 3. Sum the counts: 0 + 1 + 0 + 2 + 1 = 4.
>
> Answer: There are 4 E's in the phrase.
In the thought portion it broke the words up every which way you could think to check then validated the total by listing the letters in a number list by index and counting that compared to the sums of when it did each word.
Hello -> h e l l o 66547 -> 12 66 88 88 3
Or, maybe it memorized that hello has a single e.
Either way, This seems to be a edge case that may or may not exist in the training data, but seems orthogonal to 'reasoning'
A better test case would be how it performs if you give the spelling mappings for each word the context?
> <comes to an initial guess> > Wait, is that correct? Let me double-check because sometimes I might miscount or miss letters. > Maybe I should just go through each letter one by one. Let's write the word out in order: > <writes one letter per line with the conclusion for each > *Answer:* There are 3 "a"s in "zygomaticomaxillary."
It's not the only example of how to judge a model but there are more ways to accurately answering this problem than "hardcode the tokenizer data in the training" and heavily trained CoT models should be expected to hit on at least several of these other ways or it is suspect they miss similar types of things elsewhere.
(This is a serious question, not poking fun; I am actually curious about this.)
That's changed in the past two months. Llama 3 70B, Qwen 32B and now these R1 models are really impressive, to the point that I'm considering trying to get real work done with them.
The catch is RAM: I have 64GB, but loading up a current GPT-4 class model uses up around 40GB of that - which doesn't leave much for me to run Firefox and VS Code.
So I'm still not likely to use them on a daily basis - but it does make me wonder if I should keep this laptop around as a dedicated server next time I upgrade.
One reason why I'm asking is that I'm in the market for a new laptop and am wondering whether it's worth spending more for the possible benefits of being able to run ~30-40GB local LLMs.
Unfortunately it doesn't look as if the answer is either "ha ha, obviously not" or "yes, obviously". (If the question were only about models available right now I think the answer would be no, but it seems like they're close enough to being useful that I'm reluctant to bet on them not being clearly genuinely useful a year from now.)
I've been assuming that privacy isn't the only benefit of local; it seems like a local model would offer more flexibility for fine-tuning, RAG, etc., though I am completely ignorant of e.g. what size of model it's actually feasible to do any useful fine-tuning to on given hardware.
Shucks, it was so close to coming up with a good punchline it could work back from.
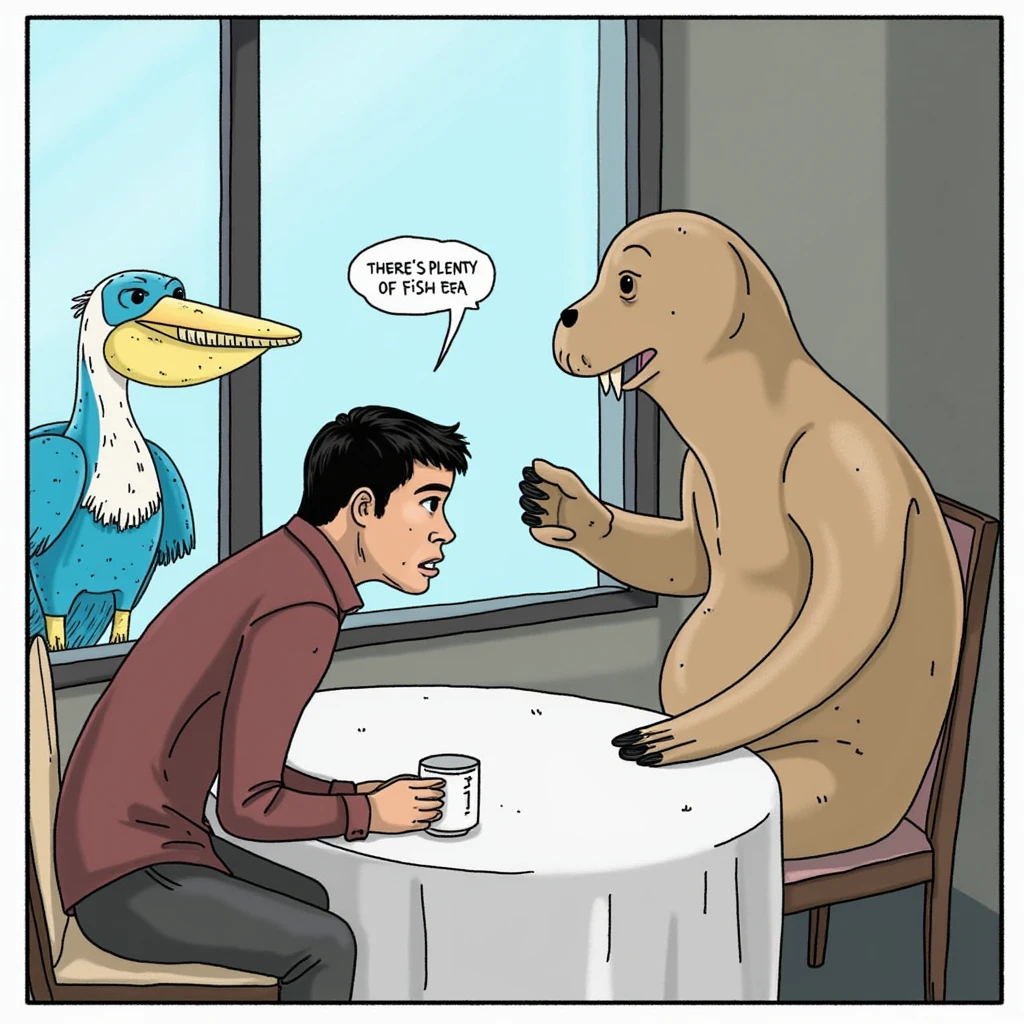
I'm thinking set it in a single-cell comic. A downtrodden young man or woman sitting alone at a table, a pelican in the background clearly making drinks in its voluminous beak, and the walrus waiter places a cup in front of the person, consolingly saying "there's plenty of fish in the tea".
Honestly it’s a bit like the porn definition. We know intelligence when we see it, even if it’s hard to define. Adding more tokens doesn’t magically phase-change into real smarts. We’ll get there, but not today.
Maybe future LLMs will be their most pro-social by playing stupid, and letting us feel like we came up with all the good idea they gracelessly-but-gracefully point our attention toward (not saying that's happening here, but maybe it's where we should make it stop)
These days I sometimes feel as if my skills as an iOS dev are losing market value. Maybe it's time I get back to writing standup :)
I think it doesn't quite get what webbed feet mean.
https://replicate.delivery/xezq/BfkZZEPS3CQHKa9HfOQTetyORSaW...
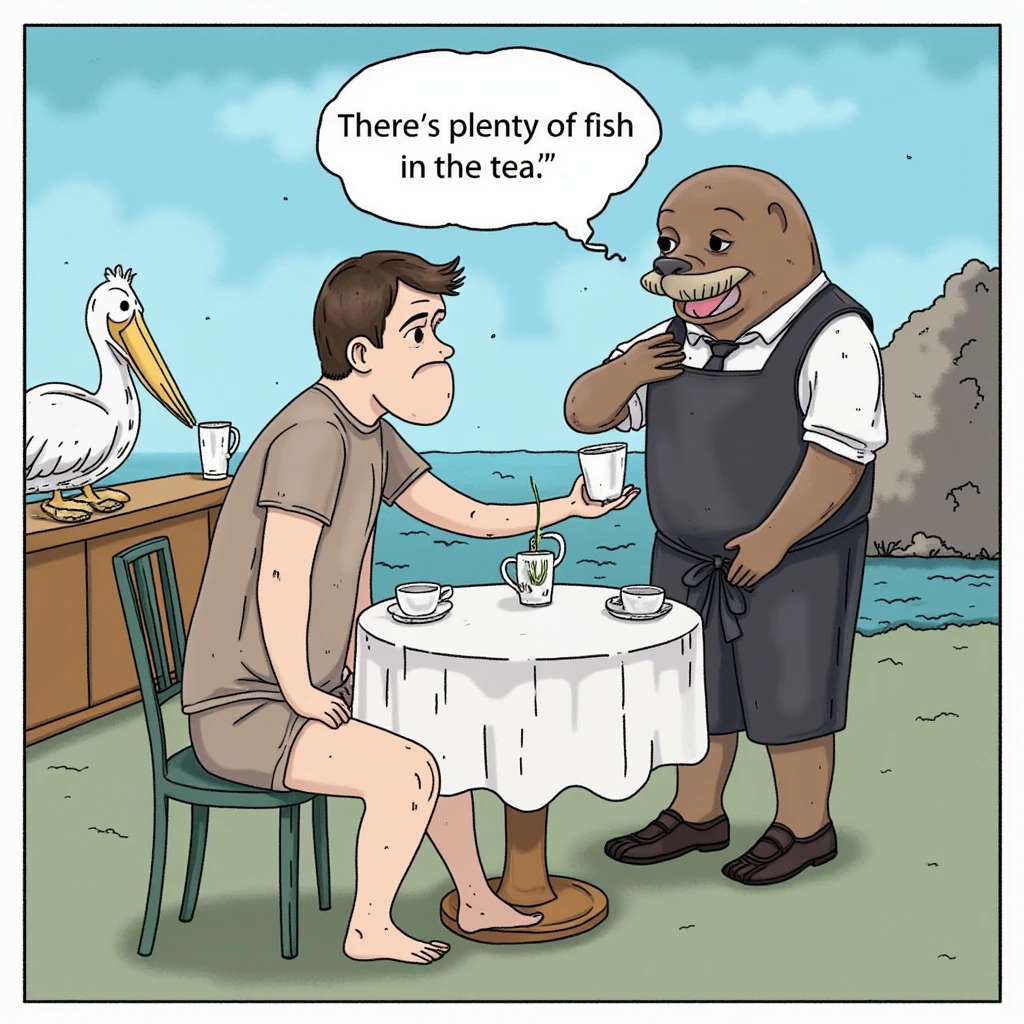
there was also a slight 'editing by curating as i choose one of the 4 outputs i got
being generated more obv on the others (i think i missed that third arm too lmao)
https://replicate.delivery/xezq/NkTMmG5ZLrIpLhr38zNR6RMeN4C2...
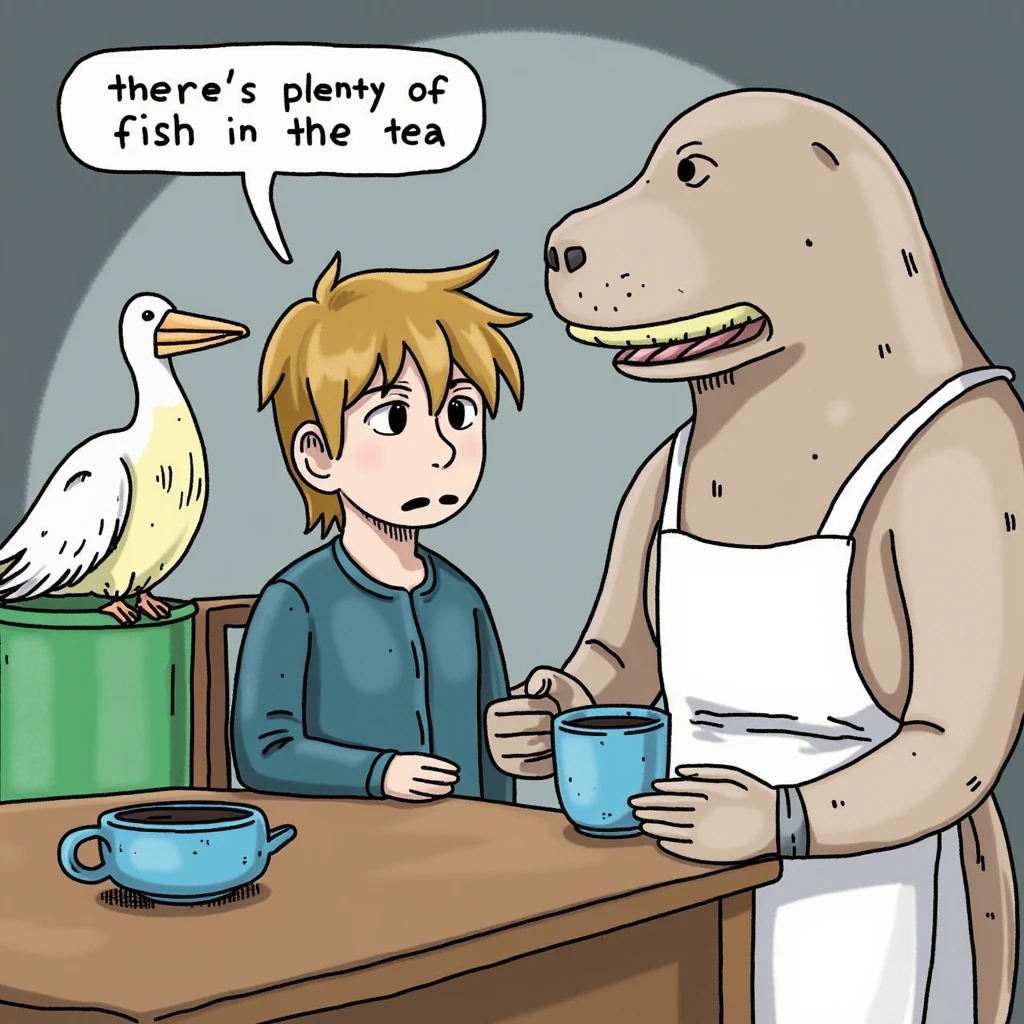
https://replicate.delivery/xezq/lzZSIkCGnXKFI90Rw3ANFwOvrZBn...
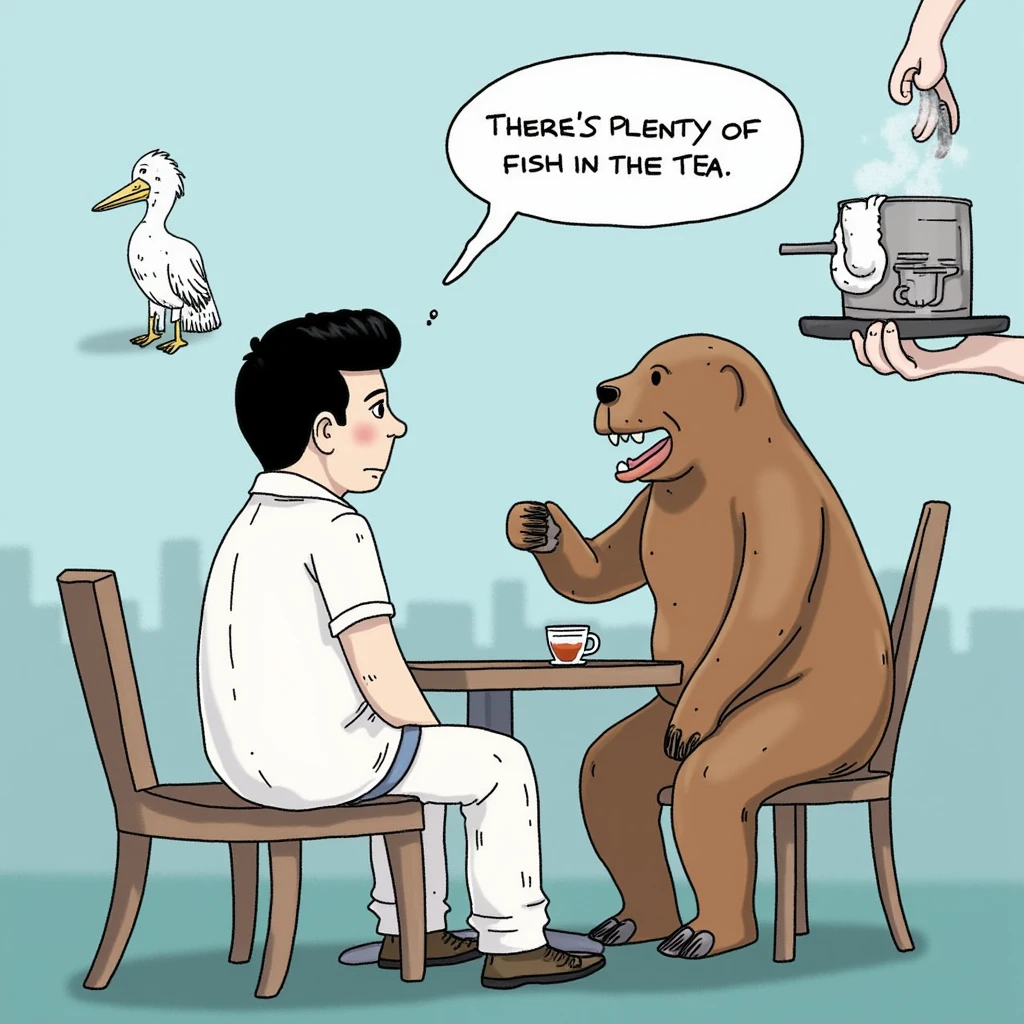
noticed a typo on my first prompt had to rerun without
https://replicate.delivery/xezq/7MU7JhaNyiZlN18gXZrfPkn9ZMgG...
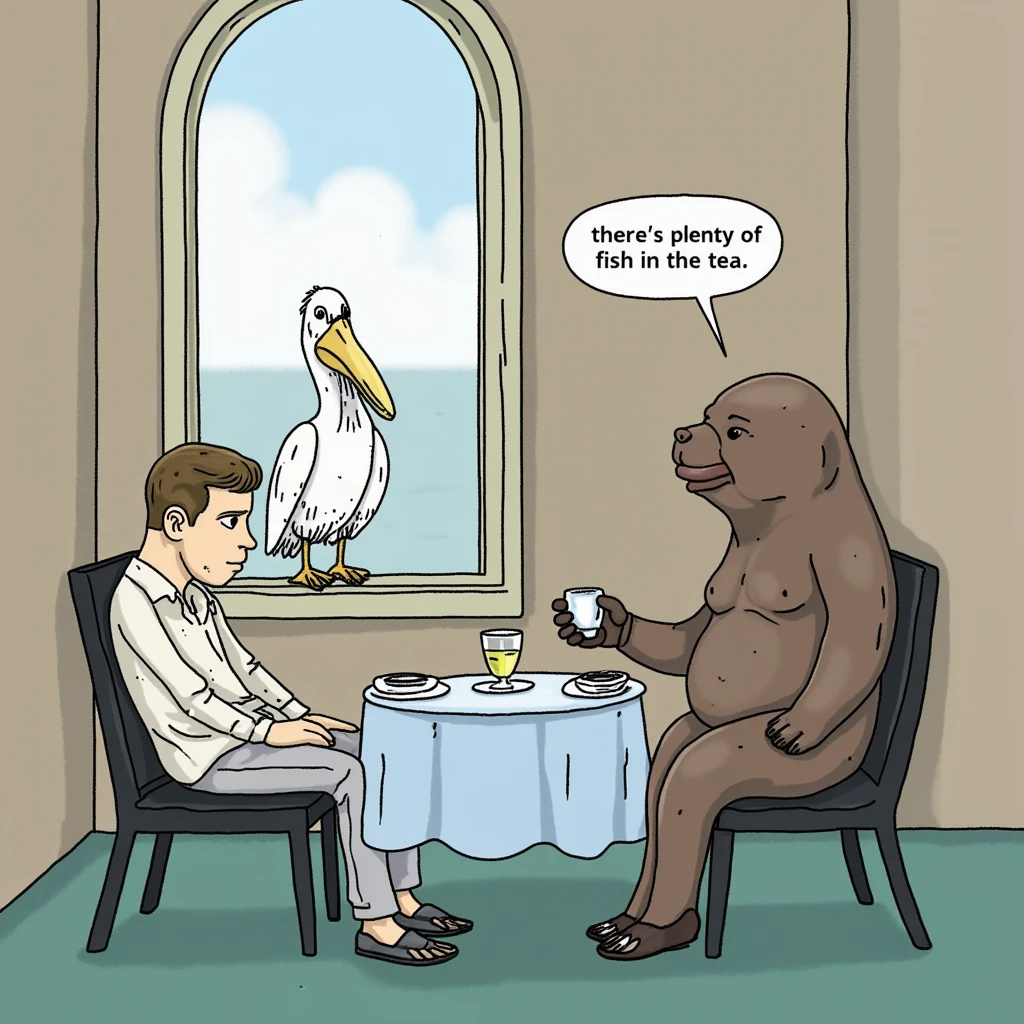
https://replicate.delivery/xezq/d5ELWfhSNk2REqtFe6fn1ouUIf5n...

https://replicate.delivery/xezq/YQwQ6tMLQKZ2LlwkXdBu1OUR9Yue...
https://replicate.delivery/xezq/VkfUjywopD0SEim4uERM22oetff3...

The one I'm running is the 8.54GB file. I'm using Ollama like this:
You can prompt it directly there, but I'm using my LLM tool and the llm-ollama plugin to run and log prompts against it. Once Ollama has loaded the model (from the above command) you can try those with uvx like this: Here's what I got - the joke itself is rubbish but the "thinking" section is fascinating: https://gist.github.com/simonw/f505ce733a435c8fc8fdf3448e381...I also set an alias for the model like this:
Now I can run "llm -m r1l" (for R1 Llama) instead.I wrote up my experiments so far on my blog: https://simonwillison.net/2025/Jan/20/deepseek-r1/