News for hackers. Stuff that matters.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by pseudosavant on Thursday January 08, 2026 @02:18PM (#46545198)
I don't know how many others here have a CoPilot+ PC but the NPU on it is basically useless. There isn't any meaningful feature I get by having that NPU. They are far too limited to ever do any meaningful local LLM inference, image processing or generation. It handles stuff like video chat background blurring, but users' PC's have been doing that for years now without an NPU.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by kenjackson on Thursday January 08, 2026 @02:34PM (#46545388)
I'd love to see a thorough breakdown of what these local NPUs can really do. I've had friends ask me about this (as the resident computer expert) and I really have no idea. Everything I see advertised for (blurring, speech to text, etc...) are all things that I never felt like my non-NPU machine struggled with. Is there a single remotely killer application for local client NPUs?
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by martinald on Thursday January 08, 2026 @02:50PM (#46545570)
The problem is essentially memory bandiwdth afiak. Simplifying a lot in my reply, but most NPUs (all?) do not have faster memory bandwidth than the GPU. They were originally designed when ML models were megabytes not gigabytes. They have a small amount of very fast SRAM (4MB I want to say?). LLM models _do not_ fit into 4MB of SRAM :).

And LLM inference is heavily memory bandwidth bound (reading input tokens isn't though - so it _could_ be useful for this in theory, but usually on device prompts are very short).

So if you are memory bandwidth bound anyway and the NPU doesn't provide any speedup on that front, it's going to be no faster. But has loads of other gotchas so no real "SDK" format for them.

Note the idea isn't bad per se, it has real efficiencies when you do start getting compute bound (eg doing multiple parallel batches of inference at once), this is basically what TPUs do (but with far higher memory bandwidth).

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by zozbot234 on Thursday January 08, 2026 @03:01PM (#46545695)
NPUs are still useful for LLM pre-processing and other compute-bound tasks. They will waste memory bandwidth during LLM generation phase (even in the best-case scenario where they aren't physically bottlenecked on bandwidth to begin with, compared to the iGPU) since they generally have to read padded/dequantized data from main memory as they compute directly on that, as opposed to being able to unpack it in local registers like iGPUs can.

> usually on device prompts are very short

Sure, but that might change with better NPU support, making time-to-first-token quicker with larger prompts.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by observationist on Thursday January 08, 2026 @04:30PM (#46546764)
The idea that tokenization is what they're for is absurd - you're talking a tenth of a thousandth of a millionth of a percent of efficiency gain in real world usage, if that, and only if someone bothers to implement it in software that actually gets used.

NPUs are racing stripes, nothing more. No killer features or utility, they probably just had stock and a good deal they could market and tap into the AI wave with.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by microtonal on Thursday January 08, 2026 @04:39PM (#46546870)
I think they were talking about prefill, which is typically compute-bound.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by adastra22 on Thursday January 08, 2026 @08:45PM (#46549147)
NPUs aren't meant for LLMs. There are a lot more neural net tech out there than LLMs.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by aleph_minus_one on Thursday January 08, 2026 @09:04PM (#46549274)
> NPUs aren't meant for LLMs. There are a lot more neural net tech out there than LLMs.

OK, but where can I find demo applications of these that will blow my mind (and make me want to buy a PC with an NPU)?

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by adastra22 on Thursday January 08, 2026 @09:49PM (#46549543)
Apple demonstrates this far better. I use their Photos app to manage my family pictures. I can search my images by visible text, by facial recognition, or by description (vector search). It automatically composes "memories" which are little thematic video slideshows. The FaceTime camera automatically keeps my head in frame, and does software panning and zooming as necessary. Automatic caption generation.

This is normal, standard, expected behavior, not blow your midn stuff. Everyone is used to having it. But where do you think the computation is happening? There's a reason that a few years back Apple pushed to deprecate older systems that didn't have the NPU.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by adgjlsfhk1 on Thursday January 08, 2026 @10:05PM (#46549633)
I've yet to see any convincing benchmarks showing that NPUs are more efficient than normal GPUs (that don't ignore the possibility of downclocking the GPU to make it run slower but more efficient)
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by adastra22 on Thursday January 08, 2026 @10:11PM (#46549664)
NPUs are more energy efficient. There is no doubt that a systolic array uses less watts per computation than a tensor operation on a GPU, for these kinds of natural fit applications.

Are they more performant? Hell no. But if you're going to do the calculation, and if you don't care about latency or throughput (e.g. batched processing of vector encodings), why not use the NPU?

Especially on mobile/edge consumer devices -- laptops or phones.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by hulitu on Sunday January 11, 2026 @01:50PM (#46578502)
> NPUs are more energy efficient. There is no doubt

Maybe because they sleep all the time. To be able to use an NPU you need at least a compiler which generates code for this particular NPU and a CPU scheduler which can dispatch instructions to this NPU.
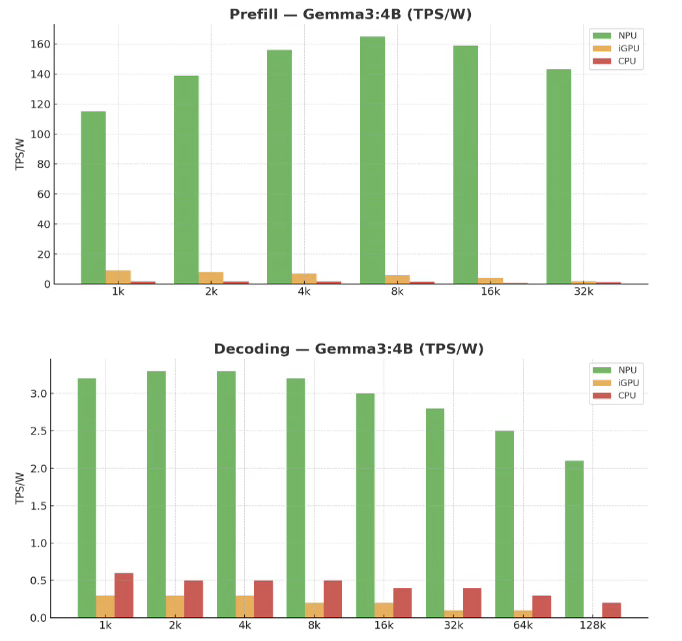
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by imtringued on Friday January 09, 2026 @06:06AM (#46552565)
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by jychang on Thursday January 08, 2026 @11:07PM (#46549936)
Best NPU app so far is Trex for Mac.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by martinald on Thursday January 08, 2026 @05:14PM (#46547236)
Yes I said that in my comment. Yes they might be useful for that - but when you start getting to prompts that are long enough to have any significant compute time you are going to need far more RAM than these devices have.

Obviously in the future this might change. But as we stand now dedicated silicon for _just_ LLM prefill doesn't make a lot of sense imo.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by zozbot234 on Thursday January 08, 2026 @05:20PM (#46547304)
You don't need much on-device RAM for compute-bound tasks, though. You just shuffle the data in and out, trading a bit of latency for an overall gain on power efficiency which will help whenever your computation is ultimately limited by power and/or thermals.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by Someone on Thursday January 08, 2026 @03:02PM (#46545709)
> Everything I see advertised for (blurring, speech to text, etc...) are all things that I never felt like my non-NPU machine struggled with.

I don’t know how good these neural engines are, but transistors are dead-cheap nowadays. That makes adding specialized hardware a valuable option, even if it doesn’t speed up things but ‘only’ decreases latency or power usage.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by bitwize on Thursday January 08, 2026 @03:33PM (#46546057)
"WHAT IS MY PURPOSE?"

"You multiply matrices of INT8s."

"OH... MY... GOD"

NPUs really just accelerate low-precision matmuls. A lot of them are based on systolic arrays, which are like a configurable pipeline through which data is "pumped" rather than a general purpose CPU or GPU with random memory access. So they're a bit like the "synergistic" processors in the Cell, in the respect that they accelerate some operations really quickly, provided you feed them the right way with the CPU and even then they don't have the oomph that a good GPU will get you.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by fragmede on Thursday January 08, 2026 @04:45PM (#46546944)
Do compilers know how to take advantage of that, or do programs need code that specifically takes advantage of that?
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by bfrog on Thursday January 08, 2026 @09:40PM (#46549497)
It’s more like you need to program a dataflow rather than a program with instructions or vliw type processors. They still have operations but for example I don’t think ethos has any branch operations.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by blep-arsh on Thursday January 08, 2026 @10:54PM (#46549874)
There are specialized computation kernels compiled for NPUs. A high-level program (that uses ONNX or CoreML, for example) can decide whether to run the computation using CPU code, a GPU kernel, or an NPU kernel or maybe use multiple devices in parallel for different parts of the task, but the low-level code is compiled separately for each kind of hardware. So it's somewhat abstracted and automated by wrapper libraries but still up to the program ultimately.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by indubioprorubik on Thursday January 08, 2026 @05:03PM (#46547117)
YaWelco

metothe

clubpal

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by mjevans on Friday January 09, 2026 @12:29AM (#46550385)
So it's a higher power DSP style device. Small transformers for flows. Sounds good for audio and maybe tailored video flow processing.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by cookiengineer on Friday January 09, 2026 @01:23AM (#46550687)
My question is: Isn't this exactly what SIMD has done before? Well, or SSE2 instructions?

To me, an NPU and how it's described just looks like a pretty shitty and useless FPGA that any alternative FPGA from Xilinx could easily replace.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by recursivecaveat on Friday January 09, 2026 @01:39AM (#46550757)
You definitely would use SIMD if you were doing this sort of thing on the CPU directly. The NPU is just a large dedicated construct for linear algebra. You wouldn't really want to deploy FPGAs to user devices for this purpose because that would mean paying the reconfigurability tax in terms of both power-draw and throughput.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by imtringued on Friday January 09, 2026 @06:15AM (#46552648)
Yes but your CPUs have energy inefficient things like caches and out of order execution that do not help with fixed workloads like matrix multiplication. AMD gives you 32 AI Engines in the space of 3 regular Ryzen cores with full cache, where each AI Engine is more powerful than a Ryzen core for matrix multiplication.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by cookiengineer on Saturday January 10, 2026 @04:21AM (#46564155)
I thought SSE2 and everything that came after like AVX 512 or SSE4 were made for streaming, leveraging the cache only for direct access to speed things up?

Haven't used SSE instructions for anything other than fiddling around with it yet, so I don't know if I'm wrong in this assumption. I understand the lock state argument about cores due to always max 2 cores being able to access the same cache/memory... but doesn't this have to be identical for FPUs if we compare this with SIMD + AVX?

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by rcxdude on Thursday January 08, 2026 @04:24PM (#46546703)
I think a lot of it is just power savings on those features, since the dedicated silicon can be a lot more energy efficient even if it's not much more powerful.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by sosodev on Thursday January 08, 2026 @04:48PM (#46546972)
In theory NPUs are a cheap, efficient alternative to the GPU for getting good speeds out of larger neural nets. In practice they're rarely used because for simple tasks like blurring, speech to text, noise cancellation, etc you can get usually do it on the CPU just fine. For power users doing really hefty stuff they usually have a GPU anyway so that gets used because it's typically much faster. That's exactly what happens with my AMD AI Max 395+ board. I thought maybe the GPU and NPU could work in parallel but memory limitations mean that's often slower than just using the GPU alone. I think I read that their intended use case for the NPU is background tasks when the GPU is already loaded but that seems like a very niche use case.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by zozbot234 on Thursday January 08, 2026 @05:29PM (#46547406)
If the NPU happens to use less power for any given amount of TOPS it's still a win since compute-heavy workloads are ultimately limited by power and thermals most often, especially on mobile hardware. That frees up headroom for the iGPU. You're right about memory limitations, but these are generally relevant for e.g. token generation not prefill.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by throwaway293892 on Thursday January 08, 2026 @06:54PM (#46548233)
I used to work at Intel until recently. Pat Gelsinger (the prior CEO) had made one of the top goals for 2024 the marketing of the "AI PC".

Every quarter he would have an all company meeting, and people would get to post questions on a site, and they would pick the top voted questions to answer.

I posted mine: "We're well into the year, and I still don't know what an AI PC is and why anyone would want it instead of a CPU+GPU combo. What is an AI PC and why should I want it?" I then pointed out that if a tech guy like me, along with all the other Intel employees I spoke to, cannot answer the basic questions, why would anyone out there want one?

It was one of the top voted questions and got asked. He answered factually, but it still wasn't clear why anyone would want one.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by skrebbel on Thursday January 08, 2026 @07:16PM (#46548429)
So... what was the answer?
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by throwaway293892 on Thursday January 08, 2026 @07:41PM (#46548647)
Pretty much the same as what you see in the comments here. For certain workloads, NPU is faster than CPU by quite a bit, and I think he gave some detailed examples at the low level (what types of computations are faster, etc).

But nothing that translated to real world end user experience (other than things like live transcription). I recall I specifically asked "Will Stable Diffusion be much faster than a CPU?" in my question.

He did say that the vendors and Microsoft were trying to come up with "killer applications". In other words, "We'll build it, and others will figure out great ways to use it." On the one hand, this makes sense - end user applications are far from Intel's expertise, and it makes sense to delegate to others. But I got the sense Microsoft + OEMs were not good at this either.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by hulitu on Friday January 09, 2026 @01:37PM (#46557337)
> For certain workloads, NPU is faster than CPU by quite a bit

WTF is an NPU ? What kind of instructions does it support ? Can it add 3 and 5 ? Can it compute matrices ?

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by cyanydeez on Saturday January 10, 2026 @09:29AM (#46565980)
Neural Processing Unit.

A retarded GPU that does matrix multiplication.

https://en.wikipedia.org/wiki/Neural_processing_unit

In theory, its your math coprocessor for your 386.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by hulitu on Sunday January 11, 2026 @01:29PM (#46578228)
> In theory, its your math coprocessor for your 386.

A math coprocessor, AFAIK, can do much more than matrix multiplications. From my POV, having a separate chip doing a single math operation is (so 1970) lame.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by Mistletoe on Thursday January 08, 2026 @07:32PM (#46548565)
Probably a lot of jargon AI word salad that boiled down to “I’m leaving in Dec. 2024, you guys have fun.”
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by TitaRusell on Friday January 09, 2026 @07:41AM (#46553254)
The only people who are actually paying good money for a PC nowadays are gamers- and they sure as hell aren't paying 3k so that they can use copilot.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by nextaccountic on Friday January 09, 2026 @03:18PM (#46558758)
Also professionals that need powerful computers ("workstations") in their jobs, like video editing

A lot of them are incorporating AI in their workflow, so making local AI better would be a plus. Unfortunately I don't see this happening unless GPUs come with more VRAM (and AI companies don't want that, and are willing to spend top dollar to hoard RAM)

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by scrame on Saturday January 10, 2026 @02:45AM (#46563690)
Assuming you can buy GPU's at a reasonable price.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by bigfatkitten on Saturday January 10, 2026 @06:59AM (#46564987)
Or at least they were. I don't know a huge number of gamers, but all of those I know are suddenly making do with what they have due to RAM prices.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by MonkeyClub on Saturday January 10, 2026 @09:21AM (#46565940)
> I used to work at Intel until recently.

Do you feel your question was the reason this is no longer the case? (Honestly curious, not /s.)

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by hacker_homie on Thursday January 08, 2026 @04:16PM (#46546606)
Yeah, that's because the original npus were a rush job, the amd AI Max is the only one that's worth anything in my opinion.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by mrinterweb on Thursday January 08, 2026 @04:26PM (#46546715)
The Apple M series chips are solid for inference.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by hamdingers on Thursday January 08, 2026 @05:52PM (#46547672)
Correct me if I'm wrong, but I thought everyone was still doing inference on the GPU for Apple silicon.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by mrinterweb on Thursday January 08, 2026 @07:51PM (#46548735)
The Apple M series is SoC. The CPU, GPU, NPU, RAM are all part of the chip.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by wtallis on Thursday January 08, 2026 @10:03PM (#46549621)
The RAM is not part of the SoC. It's a bunch of separate commodity RAM dies packaged alongside the SoC.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by Dylan16807 on Thursday January 08, 2026 @08:21PM (#46548981)
Is that because of the actual processing unit or because they doubled the width of the memory bus?
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by zamadatix on Thursday January 08, 2026 @08:33PM (#46549061)
It's because it comes with a decent iGPU, not because of the NPU inside of that. The NPU portion is still the standard tiny 50 TOPS and could be filled with normal RAM bandwidth like on a much cheaper machine.

On the RAM bandwidth side it depends if you want to look at it as "glass is half full" or "glass is half empty". For "glass is half full" the GPU has access to a ton of RAM at ~2x-4x the bandwidth of normal system memory an iGPU would have and so you can load really big models. For "glass is half empty" that GPU memory bandwidth is still nearly 2x less than a even a 5060 dGPU (which doesn't have to share any of that bandwidth with the rest of the system), but you won't fit as large of a model on a dGPU and it won't be as power efficient.

Speaking of power efficiency - it is decently power efficient... but I wouldn't run AI on battery on mine unless I was plugged in anyways as it still eats through the battery pretty quick when doing so. Great general workstation laptop for the size and wattage though.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by SomeHacker44 on Friday January 09, 2026 @04:25AM (#46551781)
I have a Strix Halo 395 128GB laptop running Ubuntu from HP. I have not been able to do anything with the NPU. I was hoping it could be used for OpenCL, but does not seem so.

What examples do you have of making the NPU in this processor useful please?

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by pseudosavant on Friday January 09, 2026 @12:46PM (#46556617)
All the videos I've seen of AI workloads with an AMD Strix Halo with 128GB setup have used the GPU for the processing. It has a powerful iGPU and unified memory more like Apple's M chips.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by skrebbel on Thursday January 08, 2026 @02:40PM (#46545462)
I have one as well and I simply don’t get it. I lucked into being able to do somewhat acceptable local LLM’ing by virtue of the Intel integrated “GPU” sharing VRAM and RAM, which I’m pretty sure wasn’t meant to be the awesome feature it turned out to be. Sure, it’s dead slow, but I can run mid size models and that’s pretty cool for an office-marketed HP convertible.

(it’s still amazing to me that I can download a 15GB blob of bytes and then that blob of bytes can be made to answer questions and write prose)

But the NPU, the thing actually marketed for doing local AI just sits there doing nothing.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by janalsncm on Thursday January 08, 2026 @03:53PM (#46546299)
If I had to steelman Dell, they probably made a bet a while ago that the software side would have something for the NPU, and if so they wanted to have a device to cash in on it. The turnaround time for new hardware was probably on the order of years (I could be wrong about this).

It turned out to be an incorrect gamble but maybe it wasn’t a crazy one to make at the time.

There is also a chicken and egg problem of software being dependent on hardware, and hardware only being useful if there is software to take advantage of its features.

That said I haven’t used Windows in 10 years so I don’t have a horse in this race.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by aleph_minus_one on Thursday January 08, 2026 @08:31PM (#46549045)
> There is also a chicken and egg problem of software being dependent on hardware, and hardware only being useful if there is software to take advantage of its features.

In the 90s, as a developer you couldn't depend on that a user's computer had a 3D accelerator (or 3D graphics) card. So 3D video games used multiple renderers (software rendering, hardware-accelerated rendering (sometimes with different backends like Glide, OpenGL, Direct3D)).

Couldn't you simply write some "killer application" for local AI that everybody "wants", but which might be slow (even using a highly optimized CPU or GPU backend) if you don't have an NPU. Since it is a "killer application", very many people will still want to run it, even if the experience is slow.

Then as a hardware vendor, you can make the big "show-off" how much better the experience is with an NPU (AI PC) - and people will immediately want one.

Exactly the same story as for 3D accelerators and 3D graphics card where Quake and Quake II were such killer applications.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by Gigachad on Thursday January 08, 2026 @09:26PM (#46549426)
They are still including the NPU though, they just realised that consumers aren't making laptop purchases based on having "AI" or being branded with Copilot.

The NPU will just become a mundane internal component that isn't marketed.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by GrantMoyer on Thursday January 08, 2026 @02:53PM (#46545613)
The idea is that NPUs are more power efficient for convolutional neural network operations. I don't know whether they actually are more power efficent, but it'd be wrong to dismiss them just because they don't unlock new capabilties or perform well for very large models. For smaller ML applications like blurring backgrounds, object detection, or OCR, they could be beneficial for battery life.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by heavyset_go on Thursday January 08, 2026 @03:48PM (#46546238)
Yes, the idea before the whole shove LLMs into everything era was that small, dedicated models for different tasks would be integrated into both the OS and applications.

If you're using a recent phone with a camera, it's likely using ML models that may or may not be using AI accelerators/NPUs on the device itself. The small models are there, though.

Same thing with translation, subtitles, etc. All small local models doing specialized tasks well.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by fragmede on Thursday January 08, 2026 @05:50PM (#46547649)
OCR on smartphones is a clear winner in this area. Stepping back, it's just mind blowing how easy it is to take a picture of text and then select it and copy and paste it into whatever. And I totally just take it for granted.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by margalabargala on Thursday January 08, 2026 @02:56PM (#46545649)
Not sure about all NPUs, but TPUs like Google's Coral accelerator are absolutely, massively more efficient per watt than a GPU, at least for things like image processing.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by heavyset_go on Thursday January 08, 2026 @03:44PM (#46546194)
The stacks for consumer NPUs are absolutely cursed, this does not surprise me.

They (Dell) promised a lot in their marketing, but we're like several years into the whole Copilot PC thing and you still can barely, if at all, use sane stacks with laptop NPUs.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by zozbot234 on Thursday January 08, 2026 @02:58PM (#46545674)
NPUs overall need better support from local AI frameworks. They're not "useless" for what they can do (low-precision bulk compute, which is potentially relevant for many of the newer models) and they could help address thermal limits due to their higher power efficiency compared to CPU/iGPU. but that all requires specialized support that hasn't been coming.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by krooj on Thursday January 08, 2026 @04:51PM (#46547002)
Question - from the perspective of the actual silicon, are these NPUs just another form of SIMD? If so, that's laughable sleight of hand and the circuits will be relegated to some mothball footnote in the same manner as AVX512, etc.

To be fair, SIMD made a massive difference for early multimedia PCs for things like music playback, gaming, and composited UIs.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by zozbot234 on Thursday January 08, 2026 @05:33PM (#46547449)
NPUs are a separate accelerator block, not in-CPU SIMD. The latter exists for matrix compute, but only in the latest version of AVX which has yet to reach consumer CPUs.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by aleph_minus_one on Thursday January 08, 2026 @08:43PM (#46549136)
> The latter exists for matrix compute, but only in the latest version of AVX which has yet to reach consumer CPUs.

As far as I am aware, AMD implemented has implemented many parts of AVX-512 in their consumer CPUs since Zen 4:

https://en.wikipedia.org/w/index.php?title=AVX-512&oldid=133...

On the other hand, Intel still does not support AVX-512 in Raptor Lake, Meteor Lake and Arrow Lake:

> https://en.wikipedia.org/wiki/Raptor_Lake

> https://en.wikipedia.org/wiki/Meteor_Lake

> https://en.wikipedia.org/wiki/Arrow_Lake_(microprocessor)

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by adastra22 on Thursday January 08, 2026 @08:49PM (#46549178)
> circuits will be relegated to some mothball footnote in the same manner as AVX512

AVX512 is widely used...

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by kristianp on Saturday January 10, 2026 @05:45AM (#46564560)
Not on Intel consumer CPUs.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by greenchair on Thursday January 08, 2026 @05:07PM (#46547170)
I've got one anecdote: friend needed Live Captions for a translating job and had to get copilot+ PC just for that.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by physicles on Friday January 09, 2026 @04:23AM (#46551760)
What software are they using for that, and how did they know ahead of time that the software would use their NPU?
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by generalizations on Thursday January 08, 2026 @06:04PM (#46547779)
NPUs were pushed by Microsoft, who saw the writing on the wall: AI like chatgpt will dominate the user's experience, edge computing is a huge advantage in that regard, and Apple's hardware can do it. NPUs are basically Microsoft trying to fudge their way to a llamacpp-on-Apple-Silicon experience. Obviously it failed, but they couldn't not try.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by alfiedotwtf on Thursday January 08, 2026 @07:51PM (#46548732)
> AI like chatgpt will dominate the user's experience

I hope not. Sure they’re helpful, but I’d rather they sit idle behind the scenes, and then only get used when a specific need arises rather than something like a Holodeck audio interface

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by aleph_minus_one on Thursday January 08, 2026 @08:33PM (#46549060)
> NPUs were pushed by Microsoft, who saw the writing on the wall: AI like chatgpt will dominate the user's experience, edge computing is a huge advantage in that regard

Then where is a demo application from Microsoft of a model that I can run locally where my user experience is so much better (faster?) if my computer has an NPU?

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by generalizations on Thursday January 08, 2026 @10:28PM (#46549730)
I didn't say they succeeded, I said they had no option but to try.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by imtringued on Friday January 09, 2026 @06:23AM (#46552703)
I think the reason why NPUs failed is that Microsoft's preferred standard ONNX and the runtime they developed is a dud. Exporting models to work on ONNX is a pain in the ass.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by dworks on Thursday January 08, 2026 @08:23PM (#46549000)
What we want as developers: To be able to implement functionality that utilizes a model for tasks like OCR, visual input and analysis, search or re-ranking etc, without having to implement an LLM API and pay for it. Instead we'd like to offer the functionality to users, possibly at no cost, and use their edge computing capacity to achieve it, by calling local protocols and models.

What we want as users: To have advanced functionality without having to pay for a model or API and having to auth it with every app we're using. We also want to keep data on our devices.

What trainers of small models want: A way for users to get their models on their devices, and potentially pay for advanced, specialized and highly performant on-device models, instead of APIs.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by zamadatix on Thursday January 08, 2026 @10:21PM (#46549700)
What seems to be delivered by NPUs at this point: filtering background noise from our microphone and blurring our camera using a watt or two less than before.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by pxc on Thursday January 08, 2026 @10:57PM (#46549887)
If it really is a watt or two less, that's a lot on a laptop.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by zamadatix on Friday January 09, 2026 @11:03AM (#46555265)
If you do video calls for 7 hours a day and then ran out it means you could have maybe ~7.5 hours. Not nothing, but differences in things like screen backlight and other component efficiency still dominate battery interests over whether there is an NPU or not. If you don't spend your day on video calls it's more like a 0% increase (mic noise processing is much lower load).

Regardless if it does zilch or some minor good for you in the battery respect, the point was more NPUs don't deliver on the above reasons everyone was supposed to want AI for. Most likely, IMO, because they are far too weak to do so and making them powerful takes too much power+cost.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by cromka on Sunday January 11, 2026 @04:52AM (#46574105)
I believe iOS and macOS make good use for NPUs, actually, with automatic OCRing on any photo displayed, be it in browser or Photos app. You can select any text easily and quickly.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by simulator5g on Thursday January 08, 2026 @08:33PM (#46549062)
If you do use video chat background blurring, the NPU is more efficient at it vs using your cpu or gpu. So the feature it supports is longer battery life and less resource usage on your main chips.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by Gigachad on Thursday January 08, 2026 @09:27PM (#46549434)
I'm not too familiar with the NPU, but this sounds a lot like GPU acceleration where a lot of the time you still end up having everything run on the CPU since it just works everywhere all the time rather than having to have both a CPU and an NPU version.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by simulator5g on Thursday January 08, 2026 @08:36PM (#46549079)
If you do use video chat background blurring, the NPU is more efficient at it vs using your cpu or gpu. So the feature it supports is longer battery life, and less resource usage on your main chips, and better performance for the things that NPUs can do. E.g higher video quality on your blurred background.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by lpribis on Thursday January 08, 2026 @08:40PM (#46549108)
Really, the best we can do with the NPU is a less battery intensive blurred background? R&D money well spent I guess...
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by shrubble on Thursday January 08, 2026 @09:49PM (#46549544)
The NPU is essentially the Sony Cell "SPE" coprocessor writ large.

The Cell SPE was extremely fast but had a weird memory architecture and a small amount of local memory, just like the NPU, which makes it more difficult for application programmers to work with.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by withinrafael on Thursday January 08, 2026 @11:27PM (#46550033)
The Copilot Runtime APIs to utilize the NPU are still experimental and mostly unavailable. I can't believe an entire generation of the Snapdragon X chip came and went without working APIs. Truly incredible.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by SomeHacker44 on Friday January 09, 2026 @04:22AM (#46551752)
Also the Copilot button/key is useless. It cannot be remapped to anything in Ubuntu because it sends a sequence of multiple keycodes instead if a single keycode for down and then up. You cannot remap it to a useful modifier or anything! What a waste of keyboard real estate.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by amluto on Friday January 09, 2026 @12:04PM (#46556013)
If you want a small adventure, you could see which HID device those keystrokes show up on, and they might be remappable courtesy of showing up on a HID device for that specific button. Failing that, they most likely come from either ACPI AML code or from the embedded controller (EC). If the former, it’s not that hard to patch the AML code, and maybe Copilot could do it for you (you use standard open source tooling to disassemble the AML blob, which the kernel will happily give you, and then you make a patched version and load it). If the latter, you could see if anyone has made progress toward finding a less silly way to configure the EC.

(The EC is a little microcontroller programmed by the OEM that does things like handling weird button presses.)

There are also reports of people having decent results using keyd to remap the synthetic keystrokes from the copilot button.

(The sheer number of times Microsoft has created totally different specs for how OEMs should implement different weird buttons is absurd.)

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by pseudosavant on Friday January 09, 2026 @12:51PM (#46556686)
I did some research on if the transistor budget for the NPU was spent on something else in the SoC/CPU, what could you get?

You could have 4-10 additional CPU cores, or 30-100MB more L3 cache. I would definitely rather have more cores or cache, than a slightly more efficient background blurring engine.