News for hackers. Stuff that matters.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by zozbot234 on Thursday January 08, 2026 @03:01PM (#46545695)
NPUs are still useful for LLM pre-processing and other compute-bound tasks. They will waste memory bandwidth during LLM generation phase (even in the best-case scenario where they aren't physically bottlenecked on bandwidth to begin with, compared to the iGPU) since they generally have to read padded/dequantized data from main memory as they compute directly on that, as opposed to being able to unpack it in local registers like iGPUs can.

> usually on device prompts are very short

Sure, but that might change with better NPU support, making time-to-first-token quicker with larger prompts.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by observationist on Thursday January 08, 2026 @04:30PM (#46546764)
The idea that tokenization is what they're for is absurd - you're talking a tenth of a thousandth of a millionth of a percent of efficiency gain in real world usage, if that, and only if someone bothers to implement it in software that actually gets used.

NPUs are racing stripes, nothing more. No killer features or utility, they probably just had stock and a good deal they could market and tap into the AI wave with.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by microtonal on Thursday January 08, 2026 @04:39PM (#46546870)
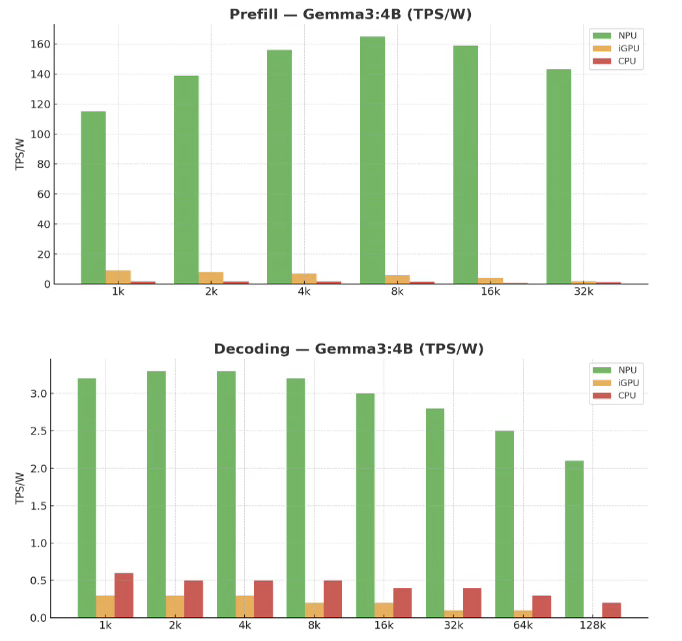
I think they were talking about prefill, which is typically compute-bound.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by adastra22 on Thursday January 08, 2026 @08:45PM (#46549147)
NPUs aren't meant for LLMs. There are a lot more neural net tech out there than LLMs.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by aleph_minus_one on Thursday January 08, 2026 @09:04PM (#46549274)
> NPUs aren't meant for LLMs. There are a lot more neural net tech out there than LLMs.

OK, but where can I find demo applications of these that will blow my mind (and make me want to buy a PC with an NPU)?

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by adastra22 on Thursday January 08, 2026 @09:49PM (#46549543)
Apple demonstrates this far better. I use their Photos app to manage my family pictures. I can search my images by visible text, by facial recognition, or by description (vector search). It automatically composes "memories" which are little thematic video slideshows. The FaceTime camera automatically keeps my head in frame, and does software panning and zooming as necessary. Automatic caption generation.

This is normal, standard, expected behavior, not blow your midn stuff. Everyone is used to having it. But where do you think the computation is happening? There's a reason that a few years back Apple pushed to deprecate older systems that didn't have the NPU.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by adgjlsfhk1 on Thursday January 08, 2026 @10:05PM (#46549633)
I've yet to see any convincing benchmarks showing that NPUs are more efficient than normal GPUs (that don't ignore the possibility of downclocking the GPU to make it run slower but more efficient)
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by adastra22 on Thursday January 08, 2026 @10:11PM (#46549664)
NPUs are more energy efficient. There is no doubt that a systolic array uses less watts per computation than a tensor operation on a GPU, for these kinds of natural fit applications.

Are they more performant? Hell no. But if you're going to do the calculation, and if you don't care about latency or throughput (e.g. batched processing of vector encodings), why not use the NPU?

Especially on mobile/edge consumer devices -- laptops or phones.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by hulitu on Sunday January 11, 2026 @01:50PM (#46578502)
> NPUs are more energy efficient. There is no doubt

Maybe because they sleep all the time. To be able to use an NPU you need at least a compiler which generates code for this particular NPU and a CPU scheduler which can dispatch instructions to this NPU.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by imtringued on Friday January 09, 2026 @06:06AM (#46552565)
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by jychang on Thursday January 08, 2026 @11:07PM (#46549936)
Best NPU app so far is Trex for Mac.
Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by martinald on Thursday January 08, 2026 @05:14PM (#46547236)
Yes I said that in my comment. Yes they might be useful for that - but when you start getting to prompts that are long enough to have any significant compute time you are going to need far more RAM than these devices have.

Obviously in the future this might change. But as we stand now dedicated silicon for _just_ LLM prefill doesn't make a lot of sense imo.

Re:Dell's CES 2026 chat was the most pleasingly un-AI briefi... by zozbot234 on Thursday January 08, 2026 @05:20PM (#46547304)
You don't need much on-device RAM for compute-bound tasks, though. You just shuffle the data in and out, trading a bit of latency for an overall gain on power efficiency which will help whenever your computation is ultimately limited by power and/or thermals.