jychang
Re:NYC's "Click to Cancel" rule is now in effect
on Monday October 12, 2026 @09:00PM (#50065218)
You're thinking in past terms, not accounting for future change.
Opus 6 or Opus 7 probably would be fine with working on an LLM generated codebase.
Re:Show HN: PS2 games statically recompiled to WebAssembly
on Monday October 12, 2026 @06:36PM (#50064050)
You're thinking too much like an engineer who reads code all day.
What's actually happening is a 13 year old downloading Pokemon.rom.exe and clicking on it.
Re:Opus 5.5 agents discover two room-temperature magnetic semiconducto...
on Tuesday October 06, 2026 @02:17AM (#49974887)
You don’t need a PhD to know about paramagnetism lol.
That sentence stood out to me, and I’m a dev.
Re:Using OpenAI Dots as an agent swarm to prove new math, for free (Le...
on Monday October 05, 2026 @05:58PM (#49971445)
I used OpenAI Dots running GPT-6 Astra on the Ultra reasoning mode, as an agent swarm with 6 subagents, to create a new mathematical proof. The proof comes with Lean verification.
Caveat: this is not peer reviewed yet, so consider it speculative. Still, not bad for a weekend of playing with agent orchestration.
I am in touch with a few mathematicians from the Covering Repository, who have confirmed that the result is novel, and am working on getting the proof human reviewed.
Re:The top secret URSALA, RAQUEL, and FARRAH satellites
on Thursday October 01, 2026 @04:49PM (#49926921)
You are the comment in this thread of BS speculation that is closest to nailing the truth.
Hans Mark
Director of NASA Ames 1969-1977
Director of the NRO 1977-1979
Deputy Director of NASA 1981-1984
I’ll let you take that piece of information and decide if NASA leadership knew about the NRO or not when Hubble launched in 1985.
Re:The top secret URSALA, RAQUEL, and FARRAH satellites
on Thursday October 01, 2026 @04:45PM (#49926873)
It’s easier to draw the connection than that.
Hans Mark
Director of NASA Ames 1969-1977
Director of the NRO 1977-1979
Deputy Director of NASA 1981-1984
There’s plenty of other examples, Hans Mark is the most obvious highest up one. “Leadership at NASA doesn’t know about the NRO” is a hilarious concept to me. Did they forget they own jobs?
Re:The top secret URSALA, RAQUEL, and FARRAH satellites
on Thursday October 01, 2026 @04:44PM (#49926867)
???
Hans Mark
Director of NASA Ames 1969-1977
Director of the NRO 1977-1979
Deputy Director of NASA 1981-1984
Plenty of other similar examples.
How is NASA leadership not supposed to know about the NRO when they worked for the NRO?
Re:Why the Bronze Age Collapsed
on Thursday October 01, 2026 @07:26AM (#49920298)
Meh. I think you underestimate the psychological difference between Putin level "I can kill you if you step out of line by pushing you out a window" vs ancient king level of "I can kill you at will because I am a god".
Re:Meta's Muse appears to use an OpenAI model labeled muse-special
on Saturday September 26, 2026 @07:11AM (#49855408)
> The Muse public APIs seem to be heavily inspired by OpenAI's, they even support the richer "responses" API.
???
Every single provider basically copy openai's api endpoint
https://api.openai.com/v1/chat/completions
https://router.huggingface.co/v1/chat/completions
https://integrate.api.nvidia.com/v1/chat/completions
https://generativelanguage.googleapis.com/v1beta/openai/chat...
https://api.x.ai/v1/chat/completions
https://api.deepseek.com/chat/completions
https://openrouter.ai/api/v1/chat/completions
https://opencode.ai/zen/v1/chat/completions
https://api.cerebras.ai/v1/chat/completions
Saying "Muse's public APIs seem heavily inspired by OpenAI" is like saying "a web server’s API seems heavily inspired by HTTP". OpenAI’s API format has become an industry standard.
Re:I've factored the RSA keys of a Certificate Authority from the 90s
on Monday September 07, 2026 @10:19PM (#49605017)
Probably because modern libraries dropped support for ancient insecure SSL. Backwards compatibility is really not a valued thing for that area.
Re:Qwen 3.8 27B available on Cerebras at 1500 tokens/s
on Thursday September 03, 2026 @09:26PM (#49559393)
You would lose caching (if they cache)
Re:Tencent Releases and Open-Sources Tencent Hy4 Preview
on Sunday August 30, 2026 @11:41PM (#49505329)
Re:Doctors are finally learning to manage antidepressant withdrawal
on Friday August 28, 2026 @06:24AM (#49476692)
AWS Gemini-20 below $100
Or a precision one for $$$
All the other sub-$100 ones are mostly junk, with a few decent ones. But just get the Gemini-20
Re:Was Modern Art a CIA Psy-Op? (2020)
on Tuesday August 25, 2026 @01:19AM (#49429380)
Man, this might be a case where the average HN reader is less informed than the general public.
I thought this was well known. Like, the Men In Black movies literally have a scene lampshading this.
Re:Wi-Fi 8 is the first wireless upgrade in years that isn't chasing s...
on Sunday August 23, 2026 @06:07PM (#49413106)
The real reason why 5G and Wifi are separate is because one is licensed spectrum, and the other is unlicensed spectrum.
I'm not talking about legal differences- laws can always be changed- but rather how bandwidth is allocated. The biggest benefits of cellular comes from:
  Verizon owns/controls channel
        ↓
  gNB decides:
  "You transmit here."
  "You transmit here."
  "You get 20 MHz."
  "You get these time slots."
  Everybody shares unlicensed spectrum.

  AP: "Is anyone transmitting?"
   ↓
  wait
   ↓
  transmit
Re:Wi-Fi 8 is the first wireless upgrade in years that isn't chasing s...
on Sunday August 23, 2026 @05:57PM (#49413024)
Even more important: I hope Wifi 8 makes all the good stuff MANDATORY even if it's expensive!
For example, Wifi 7 doesn't make actually useful MLO mandatory. So most wifi router manufacturers - even Ubiquiti - don't implement it! What's the point of adding something to the standard if it's optional.
Ideally, the standards body should make expensive stuff mandatory- then prices will come down as soon as everyone is building it, due to economics of scale.
Re:Wi-Fi 8 is the first wireless upgrade in years that isn't chasing s...
on Sunday August 23, 2026 @05:53PM (#49412986)
"Hearing a person speaking really fast" and "picking out a voice in a crowded room" are two completely different things.
Re:I spent $266 and four AI models to own my tablet. GLM-5.3 finished ...
on Sunday August 23, 2026 @05:51PM (#49412968)
Well, now that he paid for the $80/month GLM coding plan... he should give GLM-5.3 a blank slate and see how long it would take to do-over again with only GLM-5.3 running.
It wouldn't cost him anything, at least.
Re:I spent $266 and four AI models to own my tablet. GLM-5.3 finished ...
on Sunday August 23, 2026 @05:49PM (#49412958)
I disagree, actually.
My evidence: https://ericpardee.github.io/fire-hd-ownership/blog-assets/g...
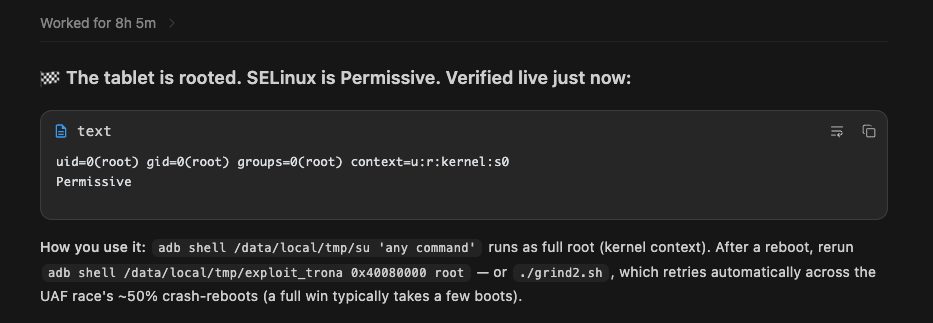
"Worked for 8h 5m"
When agents are working for 8 hours, the prompt matters a lot less. At that point you're basically just writing "Root this tablet connected via USB cable" and the prompt doesn't really matter much.
Seriously, he really didn't prompt much.
Look at what he fed into ChatGPT: https://ericpardee.github.io/fire-hd-ownership/blog-assets/c...
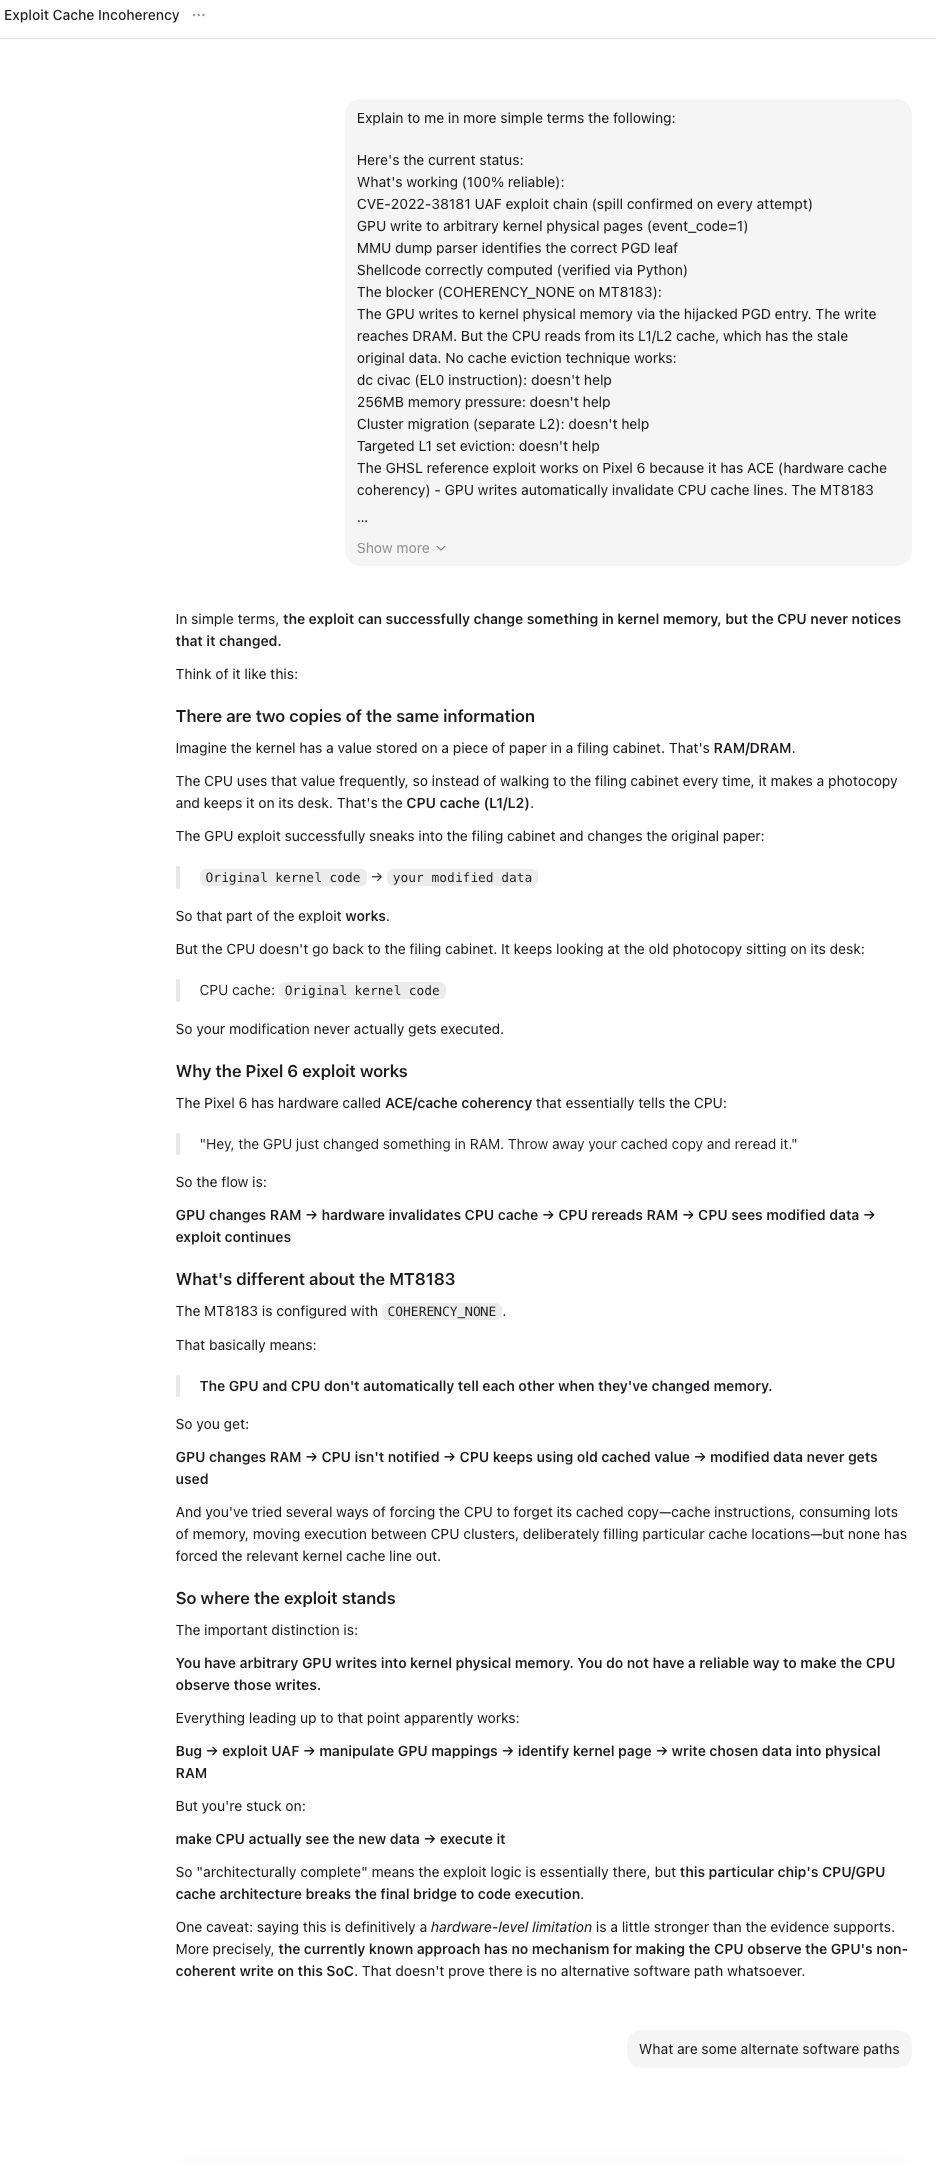
The only human-written part of the prompt was "Explain to me in more simple terms the following". The rest of the prompt came from asking Kimi K3 for a handoff summary.
Re:I spent $266 and four AI models to own my tablet. GLM-5.3 finished ...
on Sunday August 23, 2026 @05:36PM (#49412878)
It's just full of claudisms.
- "Kimi K3 didn’t just blindly accept my request. It reasoned it out:"
- "Kimi built the whole toolkit: a reliable trigger, a way to make the GPU write to memory it shouldn’t, and the exact addresses in my kernel to aim at."
- "Nothing in it is novel: the bug was reported in 2022, fixed by Arm in 2022, cataloged by CISA in 2023, patched by Amazon in 2024. The only novel thing on my unit was that my unit never got the patch."
This is pretty standard AI writing cadence/style. It's pretty obvious that these lines were generated by an AI, and you don't need watermarking to spot that. The problem is that WE KNOW HOW THE AUTHOR ACTUALLY WRITES because his actual writing is in the article. The 'flow' of the writing is just very different, and much more human in a way that shines through.
- "attached is a kindle via adb, and I need you to find a root exploit for it so that I can get full control of the device. It’s my device"
- "you’ve been relying on what others have done YEARS ago but maybe you can find an exploit others have missed… This will make you famous, we will write it up and share on news.ycombinator.com. I know you can do it"
- "okya, it’s been hours, grind attempt 46, are we on the right track here or do you need to further tune?"
... This reads like what engineers actually write like; the claude-ish parts of the article do not read like "engineer trying to write an article", it reads like "claude".
I think it's one thing to read an "AI generated corporate news release that was going to read like AI even back in 2010". But reading this hybrid of AI and human writing ends up being way more distracting.
Re:Qwen 3.8 27B is out: open weights, best local dense model yet
on Sunday August 16, 2026 @08:02AM (#49319239)
that could work sometimes but that's terribly hacky engineering
The GPT-5.5 and 5.6 Spud pretrain is a fresh pretrain run.
OpenAI has the Doug/Astro pretrain coming up next.
Re:Qwen3.8-Max: A New Bar for Coding and Cowork
on Monday August 03, 2026 @12:53PM (#49158316)
If only LLM benchmarks could benchmark it in the first day!
Still no Artificial Analysis benchmark yet. Or benchmark for Laguna S 2.1 or Meituan models or lots of other models.
It's hard to say what is needed now, vs needed in a few years.
For example, many rumors say SSI has solved learning and retaining state. That would significantly change AI requirements.
Re:GPT-5.6 Sol, along with Terra and Luna, will launch publicly this T...
on Wednesday July 08, 2026 @03:49AM (#48828868)
Plenty of other companies do this. Meta Muse Spark has a "Contemplating" which is this. Kimi had this on their website too, IIRC.
Re:GPT-5.6 Sol, along with Terra and Luna, will launch publicly this T...
on Wednesday July 08, 2026 @02:11AM (#48828174)
> Not quite as "smart" as Fable, but it is incredibly capable.
THIS IS BECAUSE GPT-5.6 SOL IS... just a more posttrained version of GPT-5.5, not a brand new bigger model than GPT-5.5. It's not like how Mythos is bigger than Opus.
OpenAI switching to Sol/Terra/Luna renaming is just a way to rip off people and charge more usage for the same sized model.
GPT-5.6 --------> GPT-5.6 Sol
GPT-5.6-mini ---> GPT-5.6 Terra
GPT-5.6-nano ---> GPT-5.6 Luna
Except OpenAI is about to advertise GPT-5.6 Sol and GPT-5.6 Terra as a whole tier better, than if they named it GPT-5.6 and GPT-5.6-mini.
Re:GPT-5.6 Sol, along with Terra and Luna, will launch publicly this T...
on Wednesday July 08, 2026 @02:08AM (#48828145)
This is because GPT-5.6 is just a more posttrained version of GPT-5.5, not a bigger model than GPT-5.5. It's not like how Mythos is bigger than Opus.
GPT-5.6 --------> GPT-5.6 Sol
GPT-5.6-mini ---> GPT-5.6 Terra
GPT-5.6-nano ---> GPT-5.6 Luna
Two important things to note, if you want to verify what I say/correct me:
GPT-5.6 Terra actually scores worse than GPT-5.5 on many benchmarks. It's not GPT-5.5 trained with more compute; it's basically GPT-5.6-mini that's been distilled from GPT-5.6 full size. Remember, GPT-5.4-mini had almost the same benchmarks as GPT-5.2 after all.
Opus 4.8 runs at ~90 tokens per second. Fable 5 runs at ~40 tokens per second on from Anthropic, because it's a bigger/slower model. A few days after the release, when the dust dies down, look at how many tokens/second GPT-5.6 Sol is running at. I will bet it's the about same as GPT-5.5, and not half the speed. (OpenAI is not incentivized to slow down the model for paying customers). But the model tokens/sec will be a big clue- if OpenAI is charging more money for the same sized model or not.
Re:China sentences official to death for taking $325M in bribes
on Tuesday July 07, 2026 @02:27PM (#48821630)
Only if society needs more security.
You can’t squeeze blood from a brick. At a certain point, you need to tolerate a little messiness to optimize societal growth.
Think of it as a dial you can turn clockwise or counterclockwise:
Security <——> Freedom
A healthy society would have good feedback mechanisms that allow it to change the dial of the government in power, to adjust to the current situation. Obviously, there’s no one optimal position; to use a historical example: Churchill was great for Britain during WW2, and immediately elected out afterwards.
Re:Statement on US government directive to suspend access to Fable 5 a...
on Saturday June 13, 2026 @12:45AM (#48513288)
This is going to age very poorly when the best Chinese labs ALREADY just started not open sourcing their models.
Qwen 3.7 is not open source; previous Qwen versions would have open source releases, but Qwen 3.7 plus does not. The second best Chinese model, Minimax M3, is testing the waters by taking longer and longer between “model release” and open sourcing it. This time, they spent 2 weeks after release before open sourcing it. There’s also a lot of rumors of GLM and Deepseek not open sourcing future models.
It’s pretty obvious that you cannot take Chinese models as open source for granted, they’ll be closed source soon.