NYT should be a relatively simple website. Sure, they have some very nice interactive stories and we'll give those a pass, but even just plain text articles load an amazing amount of cruft. It's text, just send the damn text.
Everyone else being bloated isn't an excuse.
> Everyone else being bloated isn't an excuse.
It's not, but I'd rather focus on the worst offenders instead of the half-decent ones. I didn't compare it to Slack because I thought Slack was a good example—I did it for the exact opposite reason.
And, as long as there are sites that are so much heavier and yet seem to be doing fine (I don't like it, but it is what it is), I doubt NY Times is removing 3rd-party ads due to performance issues. It could be a nice side effect, though.
Render time for my (aging) macbook pro is within the acceptable threshold (< 1500ms), memory snapshot in firefox is ~90Mb, and it feels like it loads quickly and responsively. It could be better - but it's infinitely more usable than NYT for me.
Does this resource need to be generated dynamically?
Related: can this resource be cached?
More important: can this resource be resized?
Often overlooked: do I need to process this javascript to provide the equivalent UX?
The modern Web is terrible, and the modern state of app dev is terrible due to a substantial subset of the reasons that the modern Web is terrible.
It was a contender?
> NYT should be a relatively simple website.
There's editors from the NYT lurking here who will strongly disagree.
And sure, obviously NYT is more complex than throwing textfiles at users.. but do you really need to be running A/B tests for acquisition and have such a complicated pipeline to buying a subscription? Do you need dozens of analytics suites? Data is useful, but only to an upper bound of what you can meaningfully analyze.
So, I have some empathy for the NYT staff as individual contributors, but as an org, it's time to evolve.
They only send what the user requests.
Using a software program that makes automatic requests that you are not easily in control of, e.g., a popular web browser, might give the impression that they control what is sent.
They do not control what is sent. The user does.^1
The user makes a request and they send a response.
One of the requests a fully-automatic web browser makes to NYT is to static01.nyt.com
Personally, as a user who prefers text-only, this is the only request I need to make. As such I don't really need a heavily marketed, fully-automatic, graphical, ad-blocking web browser to make a single request for some text.^2
    #! /bin/sh

    case $1 in
    world        |w*)  x=world       # shortcut: w
    ;;us         |u*)  x=us          # shortcut: u
    ;;politics   |p*)  x=politics    # shortcut: p
    ;;nyregion   |n*)  x=nyregion    # shortcut: n
    ;;business   |bu*) x=business    # shortcut: bu
    ;;opinion    |o*)  x=opinion     # shortcut: o
    ;;technology |te*) x=technology  # shortcut: te
    ;;science    |sc*) x=science     # shortcut: sc
    ;;health     |h*)  x=health      # shortcut: h
    ;;sports     |sp*) x=sports      # shortcut: sp
    ;;arts       |a*)  x=arts        # shortcut: a
    ;;books      |bo*) x=books       # shortcut: bo
    ;;style      |st*) x=style       # shortcut: st
    ;;food       |f*)  x=food        # shortcut: f
    ;;travel     |tr*) x=travel      # shortcut: tr
    ;;magazine   |m*)  x=magazine    # shortcut: m
    ;;t-magazine |t-*) x=t-magazine  # shortcut: t-
    ;;realestate |r*)  x=realestate  # shortcut: r
    ;;*)
    echo usage: $0 section
    exec sed -n '/x=/!d;s/.*x=//;/sed/!p' $0
    esac

    curl -s https://static01.nyt.com/services/json/sectionfronts/$x/index.jsonp

   Example: Make simple page of titles, article urls and captions, where above script is named "nyt".

    nyt tr |  sed '/\"headline\": \"/{s//<p>/;s/\".*/<\/p>/;p};/\"full\": \"/{s//<p>/;s/..$/<\/p>/;p};/\"link\": \"/{s///;s/ *//;s/\".*//;s|.*|<a href=&>&</a>|;p}' > travel.html

    firefox ./travel.html
The truth is that they are just sending the damn text. However you are voluntarily choosing to use a software program that is automatically making requests for things other than the text of the article, i.e., "cruft".
1. The Google-sponsored HTTP/[23] protocol is seeking to change this dynamic, so if websites sending stuff to you without you requesting it first bothers you, you might want to think about how online advertisers and the companies that enable them might use these new protocols.
2. However I might use one for for viewing images, watching video, reading PDFs, etc., offline. Web browsers are useful programs for consuming media. It is in the simple task of making HTTP requests that their utility has diminished over time. The user is not really in control.
I go to a restaurant and I can't just walk into the kitchen and grab a plate of food. Nor can I walk into the refrigerator, grab some supplied, and then walk over to the stations and start cooking. Instead I have wait to be seated, order indirectly via a waiter, wait for the chef and staff to prepare more order, etc...
It seems to me visiting a website is similar. The user choose to visit the site. That includes the 3rd parties and less controls. Just like I don't get to pick what sources the restaurant used for their food, nor do I have any say in their hiring or management practices. Nor do I have any choice in the music they play or the TVs they have on (bar like restaurants often have TVs). If I don't like their choices my choice is to be or not be a customer. I don't get to hack around that, walking in the back door and taking the food.
I know the analogy isn't perfect. It's my computer and I have no obligation to let them use it as they please vs as I please. But still, there's some middle ground IMO between the 2 extremes.
IMO the reason is quite easy to put the finger on:
It's because it is framing the problem squarely as one of the user, culminating in the phrase that one is "voluntarily choosing".
If you don't want to do research and customize scripts for every friggin' domain/website (and having to do it again when the site structure changes), there is no "voluntary choice".
If you don't want to accept that this "solution" has to forgo a lot of essential characteristics of hypermedia, there is no "voluntary choice".
If you're not technically versed in these things, there never was a "voluntary choice" to begin with.
In general, if you want to use the World Wide Web remotely as it is intended, there is no "voluntary choice".
I think you're unclear in your mind about the relationship between you and the website you visit.
To use your restaurant analogy, browsing the web is more like ordering delivery. You send a request for food from the menu and money to cover it, and a while later, a driver with a bag arrives at your doorstep. That bag contains the food you order, some packaging, often plastic cutlery, and some advertising. The transaction between you and the restaurant involved exchanging money for food, and the restaurant doesn't get to have any further say about what you do with that food. You're free to throw away the box, the cultery and the advertising leaflets into the bin, and give half of the food to your cat. They cannot, technically or ethically, make you eat the food out of the box it came from, while reading the advertising leaflets.
It's like that with web browsers. You ask for content (via HTTP), you get a response that includes links to other things you're invited to request. You're free to cut the response up and render it the way you like, you're free to request or not request the other linked resources. That was how the web was designed to work, that's how HTTP protocol is meant to be used. Now plenty of websites will try to insist they're more like dining in than delivery, but that's just them trying to guilt-trip you into making them more money. It's not something they're entitled to.
https://developers.google.com/web/tools/chrome-devtools/netw...
https://developer.mozilla.org/en-US/docs/Tools/Network_Monit...
https://developer.apple.com/documentation/safariservices/cre...
https://docs.microsoft.com/en-us/microsoft-edge/devtools-gui...
The web's first browser, working in line mode, could probably request the text, and only the text, of an article from nytimes.com. It has no capability to automatically follow links to ads and trackers.
nyt tr |sed 's/ *//;/</!d'|uniq > travel.html
An interesting point of discussion might be the amount of third party cruft on the template article page versus the more dynamic front page. When Javascript is disabled, on each article page all images display and there are no ads. Downloading any video in the page is as simple as
curl -O `grep -o https://[^\"]*mp4 article.html`I don't think you're aware of how much time as passed since 200 MB of RAM was the norm. Even in 2005, lower end Dell laptops ($639) had 256 MB of RAM as the minimum [0]. The 2002 PowerBook G4's base model had 256 MB [1].
[0]: http://web.archive.org/web/20050309050556/http://www1.us.del...
> And, you could read on those computers just fine.
The problem is not that the New York Times website is using too much memory for the average system. The problem is that it is using several orders of magnitude more memory to run ad-related JS in the background than it needs for the user-desired functionalitty.
It isn't the user's responsibility to provide a better solution. Not having a solution doesn't make the problem disappear.
At first, I couldn't get it to boot—it kept kernel panicking, and I couldn't figure out why. After a bit of Googling, I found the problem—I'd given the VM too much memory. Rhapsody DP2 will not boot if it has access to more than 192 MB of RAM. I assume Apple figured that no one would ever need that much.
Rhapsody came out in 1998. Not really that long ago.
The Apple II came out in 1977, 43 years ago.
1998 therefore roughly marks the halfway point between the dawn of mainstream personal computers and the present day. I dare say 1998 was a very long time ago, in PC years.
"There was a time—recent enough that it was within most of our lifetimes—when most computers had less than 200 MB of RAM total. You could read on those computers just fine."
Most ofthe gnu utils still work perfectly fine many of them were written in late 70’s and 80’s , apple itself ships , in the latest OSX , posix utilities from late 80’s versions for GPL reasons.
Perhaps it is not fair comparison , utilities are not the same as an OS . unix or Linux from the same era may not work anymore as well.
In addition to being an entire OS as you mentioned, Rhapsody was a "developer preview". The final version was called "Mac OS X Server 1.0". https://en.wikipedia.org/wiki/Mac_OS_X_Server_1.0
Rhapsody was more of a quick and dirty port of NeXTSTEP to Mac hardware than a version of OS X.
https://en.wikipedia.org/wiki/NeXTSTEP
>Rhapsody came out in 1998.
NeXTSTEP is from the late 80's.
The version he tested was from 1998. Similar to how Windows NT came out in 1993, but the current version (Windows 10) has a few added capabilities since.
MacOS addressed up to 96 Gigs of RAM initially, now up to 128 Gigs of RAM.
Because '10% of a core and 200 MB of ram' just to read a few headlines is obscene, and slack being even worse doesn't make the NYT's bloat less obscene.
With my uBO/uMatrix settings, about:performance in firefox reports that the nytimes.com homepage takes 7.9 MB of ram (and immeasurably little CPU time, because I disabled javascript.) https://lite.cnn.com/en/ is better insofar as it takes 2.6 MB of ram.
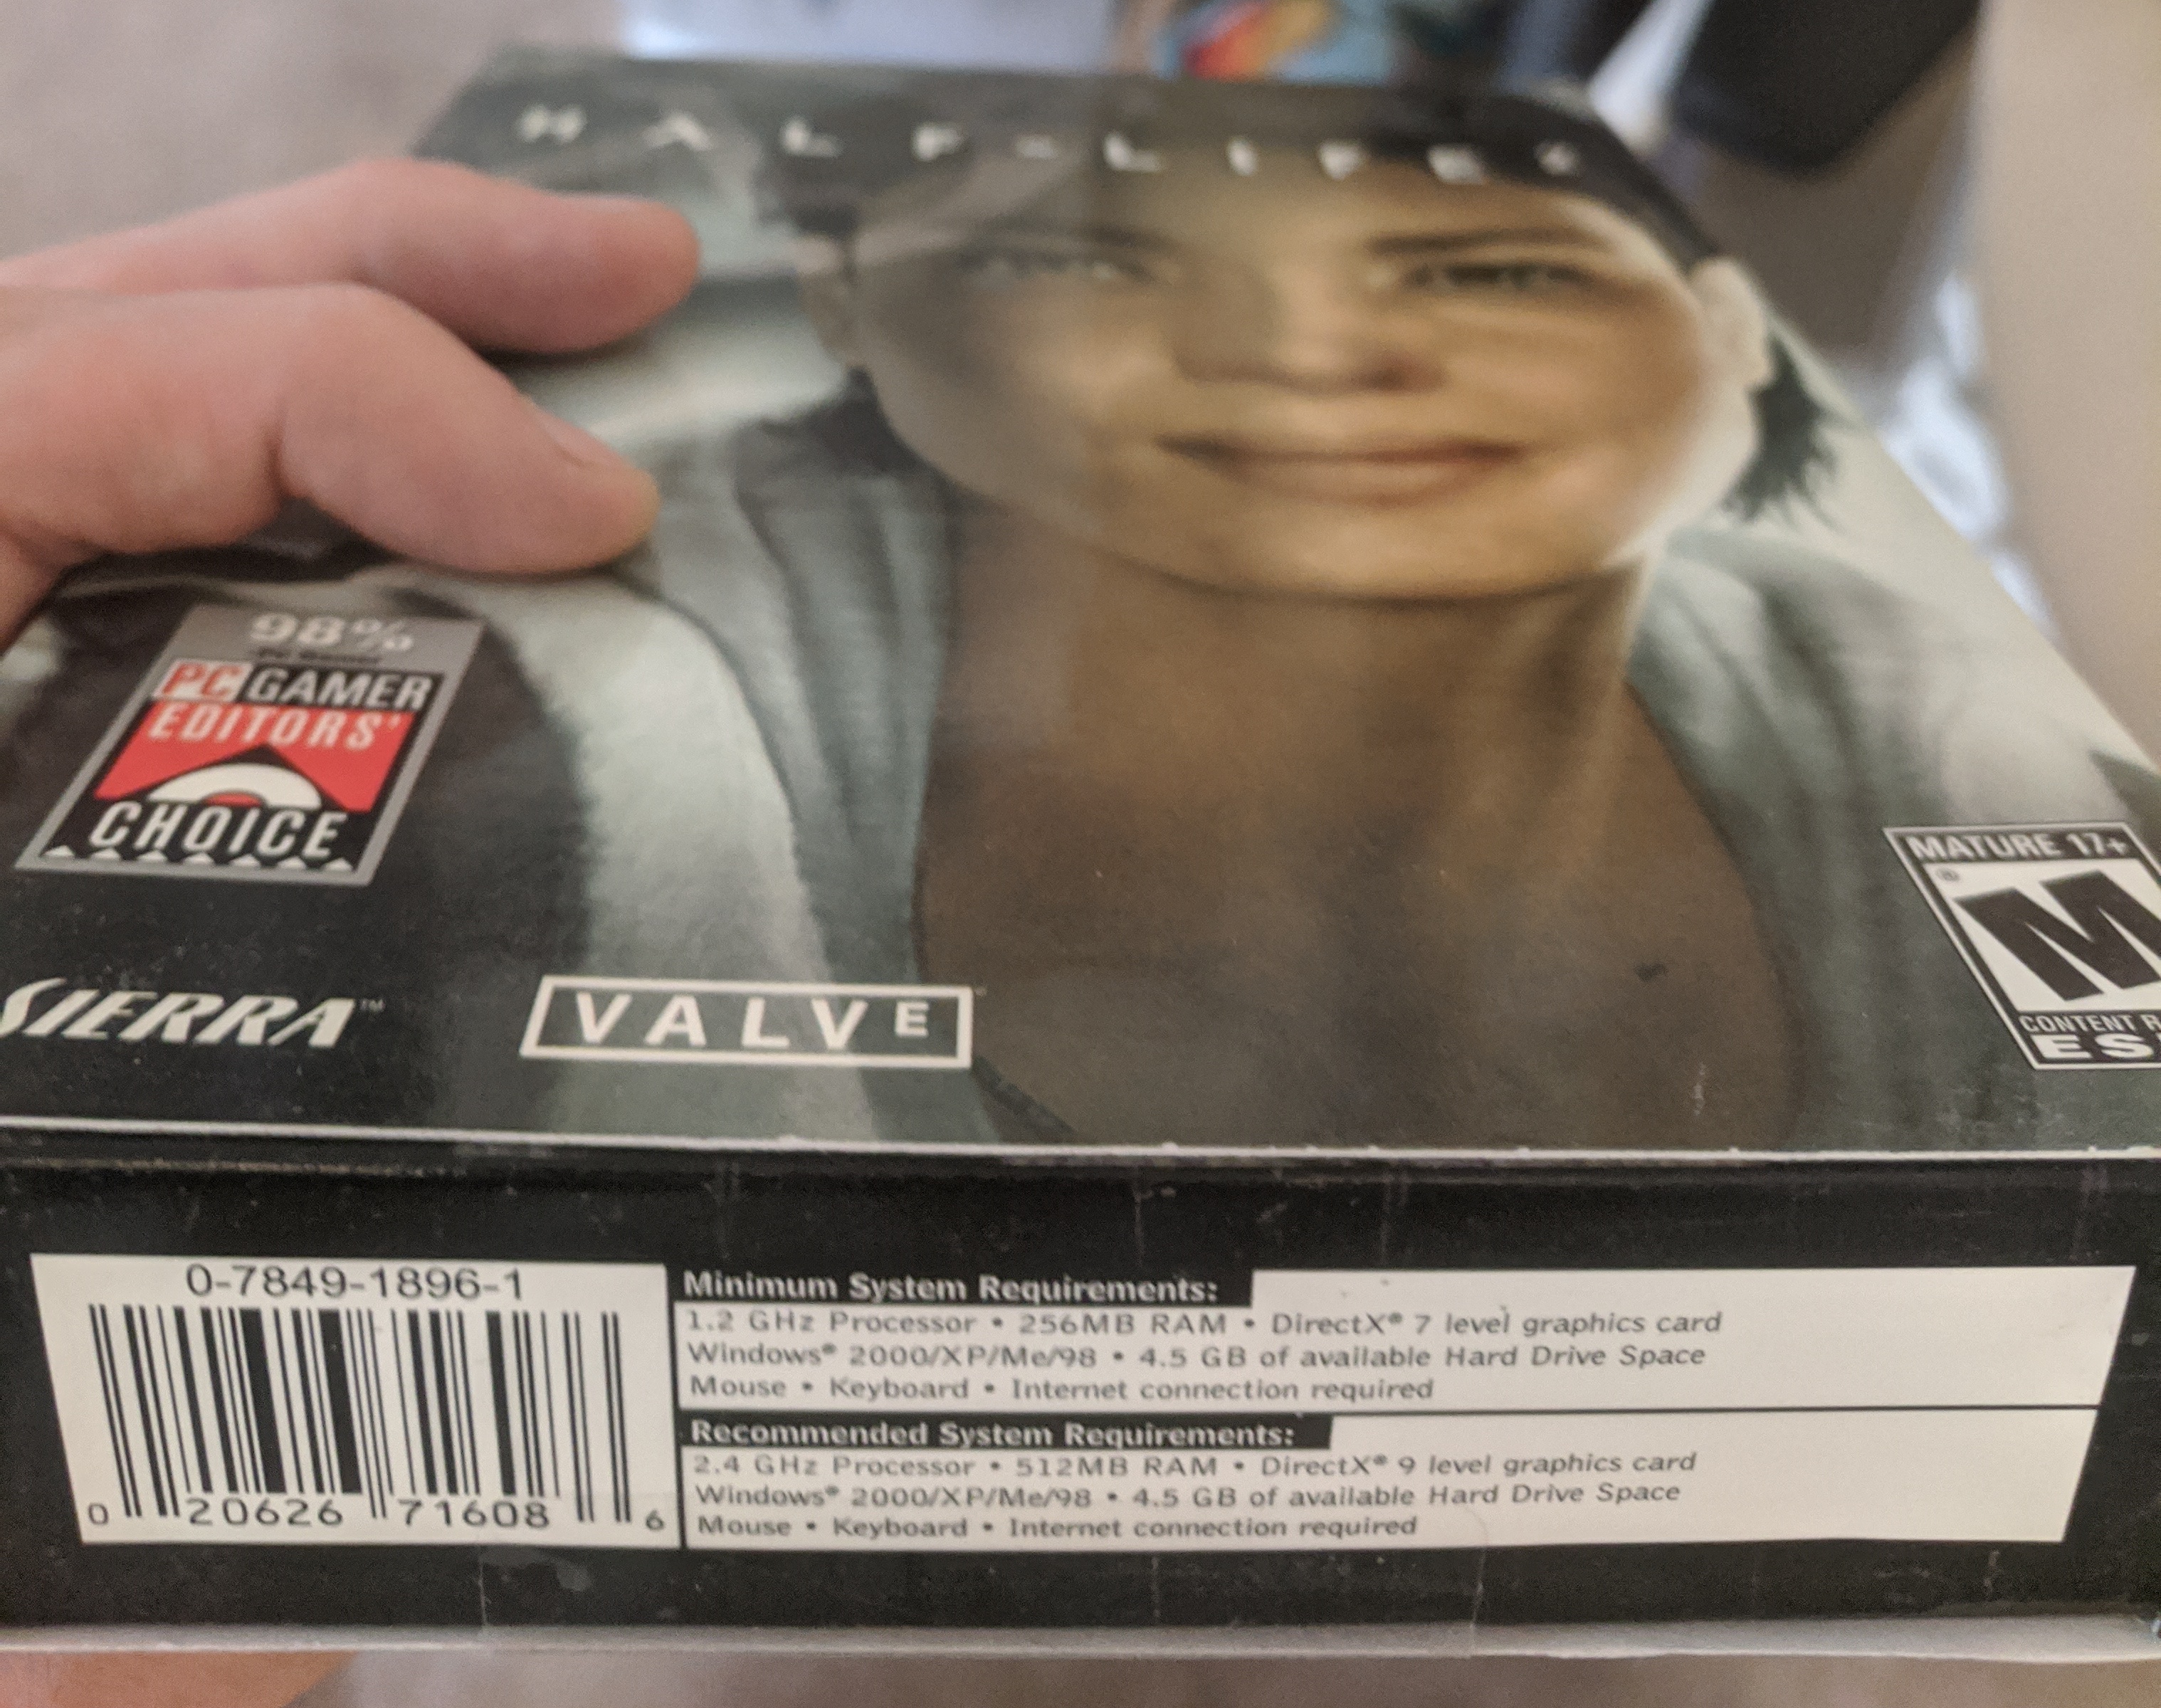
Half-Life 2 lists 512mb ram as required. It came out in 2004.
Also, Half Life 2 was a state-of-the-art video game for an audience that largely had fancy gaming PCs.
They likely couldn't run Slack or the NYT tho. Just think about how slow the PS4 store loads (it's html5) or the whole xbone ui.
Games are actually optimized for speed. NYT is optimized on a different key performance indicator.
I just built a 12 core system I would describe as "pretty fast." A high end consumer desktop these days is 16 cores. A couple years from now, that will be considered "pretty fast."
Make no mistake, he knew he worked on the production of CPUs and memories, it was just not his focus. Also, he certainly cared about switching time, but his observation was about transistor count, not switching time.
Also, my over 6 year old DAW (Digital Audio Workstation) CPU[0] is still plenty fast. It’s almost everything around it I have since upgraded (NVMe SSD, RAM, audio interface, video card) to keep overall system performance high.
[0] https://ark.intel.com/content/www/us/en/ark/products/77780/i...
The last decade of stagnation in the consumer CPU market was less the end of Moores law and more Intel not needing to do any better because they had no real competition.
I wont argue there wasn't lots of R&D going on behind the scenes, but their current improvements are still on the same architecture they've been using for years - this wasn't something they couldn't have done earlier (especially the prices - surely being able to lower them so much and still make a profit means that consumers were getting screwed earlier?).
CPUs continue to get more powerful, but the minimum hardware requirements for newer editions of operating systems tends to not follow the same curve that new game releases do. (I can't play Rainbow 6 Siege on my Ryzen 5 3550H + GTX 1050 laptop, but CSGO runs fine on it and my i7-2670QM laptop mobo with a GTX 1060 strapped to it.)
This has not been my experience with Windows 7 ==> 10.
I've never played R6 Siege and have no idea how it performs, but I would just like to say that this is effectively meaningless and I hate how games put it in their system requirements. Writing "moderately fast CPU" would carry more useful information. A Westmere Core i3-530 from 2010 is not going to perform anything like a Coffee Lake Core i3-8100B from 2018.
(I'm not that smart, I looked up the model numbers on Wikipedia: https://en.wikipedia.org/wiki/List_of_Intel_Core_i3_micropro...)
> Intel Core i3 560 @ 3.3 GHz or AMD Phenom II X4 945 @ 3.0 GHz
Many users have flipped to prioritize power efficiency and quiet operation over speed. And even despite those optimizations, most of their tasks are still bottlenecked as often by their available memory and the quality of their network connection as as their processor.
We just haven’t figured out what to do with all that power in the hands of a user who isn’t super technical, so we’re just spending it on inefficient cruft instead.
And yeah, Moore's Law isn't a law recently. :)
I don't know why they are different.
But it has been a couple hours since your comment and the other replies :)
I get a 58kB HTML document, plus 2kB each CSS & JS, 3 * ~400B images, and a 7kB favicon.
Edit: Oh sorry, RAM. Leaving comment just to compare page size to RAM use for interest.
There's now ~388 comments. Source is 529kb and content 114kb (simple cut and paste of page, no markup).
Those are some impressive ratios.
When I go to NYTimes without an ad blocker, it takes a long tie to show up, it sometimes freezes my scrolling while it loads things, things jump around on the page so when I'm trying to click something I get the wrong target as some ad loads and moves things around, it can be 10 seconds until the page stabilizes after load. I do not experience that with Slack.
How does Slack use so much RAM and CPU and still perform better than a mostly static page of text and graphics? I dunno. But it does. In the end the RAM and CPU usage matter to me theoretically, but all that really matters is the actually experienced interface. The NYT may not be the worst, but it's definitely worse than many, and the comparison to Slack is odd to me, cause my experience with Slack is that is quickly responsive with no lag.
You have a different experience, for you nytimes loads faster and has interactivity with less lag/freezing up than Slack, which for you has a lot of lag/freezing/slow load problems?
They increased core count for every gen starting 8th gen and made a significant leap in perf.
Your processor would give the same perf as the lowest end ryzen.
Not for single core performance though, right? Which is what I'm looking at here.
But the 2700x was a good buy, in retrospect.
Yes it was. 1997 was a long time ago. Kids born that year can legally drink.
Bit of an absurd claim to make, since IM clients 20 years ago had a fraction of the features that Slack has today. To pretend otherwise is disingenuous.
Now, I have a pretty fast CPU—a 4790K—and it wasn't that long ago that most computers had less than 200 MB of RAM total. And, you could read on those computers just fine.
On the other hand, if I repeat the same test with my Slack tab, I get 30% of CPU and 400 MB of RAM. Slack doesn't have ads, and IM clients are another thing that worked just fine 20 years ago.
I guess my point is, the web is bloated, and I'm not sure why we're harping on The Times.