Maybe back in the 90s, it was okay to wait 2-3 seconds for a button click, but today we just assume the thing is dead and reboot.
In the age of microservices and cattle servers, reboot/reinstall might be cheap, but in the long run it is not. A long running server, albeit being cattle, is always a better solution because esp. with some excess RAM, the server "warms up" with all hot data cached and will be a low latency unit in your fleet, given you pay the required attention to your software development and service configuration.
Secondly, Kernel swaps out unused pages to SWAP, relieving pressure from RAM. So, SWAP is often used even if you fill 1% of your RAM. This allows for more hot data to be cached, allowing better resource utilization and performance in the long run.
So, eff it, we ball is never a good system administration strategy. Even if everything is ephemeral and can be rebooted in three seconds.
Sure, some things like Kubernetes forces "no SWAP, period" policies because it kills pods when pressure exceeds some value, but for more traditional setups, it's still valuable.
> Secondly, Kernel swaps out unused pages to SWAP, relieving pressure from RAM. So, SWAP is often used even if you fill 1% of your RAM. This allows for more hot data to be cached, allowing better resource utilization and performance in the long run.
Yes, and you can observe that even in your desktop at home (if you are running something like Linux).
> So, eff it, we ball is never a good system administration strategy. Even if everything is ephemeral and can be rebooted in three seconds.
I wouldn't be so quick. Google ran their servers without swap for ages. (I don't know if they still do it.) They decided that taking the slight inefficiency in memory usage, because they have to keep the 'leaked' pages around in actual RAM, is worth it to get predictability in performance.
For what it's worth, I add generous swap to all my personal machines, mostly so that the kernel can offload cold / leaked pages and keep more disk content cached in RAM. (As a secondary reason: I also like to have a generous amount of /tmp space that's backed by swap, if necessary.)
With swap files, instead of swap partitions, it's fairly easy to shrink and grow your swap space, depending on what your needs for free space on your disk are.
Yup, that part of my comment was culmination of using Linux desktops for the last two decades. :)
> I wouldn't be so quick. Google ran their servers without swap for ages.
If you're designing this from get go and planning accordingly, it doesn't fit into my definition of eff it, we ball, but let's try this and see whether we can make it work.
> With swap files, instead of swap partitions,...
I'm a graybeard. I eyeball a swap partition size while installing the OS, and just let it be. Being mindful and having good amount of RAM means that SWAP acts as a eviction area for OS first, and as an escape ramp second, in very rare cases.
--
Sent from my desktop.
So no, my experience with swap isn't that it's invisible with SSD.
I've had good experience with linux's multi-generation LRU feature, specifically the /sys/kernel/mm/lru_gen/min_ttl_ms feature that triggers OOM-killer when the "working set of the last N ms doesn't fit in memory".
    Enables Multi-Gen LRU (improved page reclaim and caching policy).
    Prevents thrashing, improves loading speeds under low ram conditions.
    Requires kernel 6.1+.
    Has dramatic effect especially on slower HDDs.
    For slower HDDs, consider 1000 instead of 300 for min_ttl_ms.

    sudo tee /etc/tmpfiles.d/mglru.conf <<EOF
    w-      /sys/kernel/mm/lru_gen/enabled          -       -       -       -       y
    w-      /sys/kernel/mm/lru_gen/min_ttl_ms       -       -       -       -       300
EOFOn my 8gb M1 Mac, I can have a ton of tabs open and it'll swap with minimal slowdown. On the other hand, running a 4k external display and a small (4gb) llm is at best horrible and will sometimes require a hard reset.
I've seen similar with different combinations of software/hardware.
Dirty buffer should also be tuned (limited), absolutely. Default is 20% of RAM, (with 5 second writeback and 30 second expire intervals), which is COMPLETELY insane. I limit it to 64 MB max usually, with 1 second writeback and 3 second expire intervals.
It doesn't. SSDs came a long way but so did memory dies and buses, and with that the way programs work also changed as more and more they are able to fit their stacks and heaps on memory more often than not.
I have had a problem with shellcheck that for some reason eats up all my ram when I open I believe .zshrc and trust me, it's not invisible. The system crawls to a halt.
If we're talking about SATA SSDs which top at 600MBps, then yes, an aggressive application can make itself known. However, if you have a modern NVMe, esp. a 4x4 one like Samsung 9x0 series or if you're using a Mac, I bet you'll notice the problem much later, if ever. Remember the SSD trashing problem on M1 Macs? People never noticed that system used SWAP that heavily and trashed the SSD on board.
Then, if you're using a server with a couple of SAS or NVMe SSDs, you'll not notice the problem again, esp. if these are backed by RAID (even md counts).
( ) a 1% chance the system would crawl to a halt but would work
( ) a 1% change the kernel would die and nothing would work
Eg Google used to (and perhaps still does?) run their servers without swap, because they had built fault tolerance in their fleet anyway, so were happier to deal with the occasional crash than with the occasional slowdown.
For your desktop at home, you'd probably rather deal with a slowdown that gives you a chance to close a few programs, then just crashing your system. After all, if you are standing physically in front of your computer, you can always just manually hit the reset button, if the slowdown is too agonising.
If your problem doesn't keep growing, and you just have more data that programs want to keep in memory than you have RAM, but the actual working set of what's accessed frequently still fits in RAM, then swap perfectly solves this.
Think lots of programs open in the background, or lots of open tabs in your browser, but you only ever rapidly switch between at most a handful at a time. Or you are starting a memory hungry game and you don't want to be bothered with closing all the existing memory hungry programs that idle in the background while you play.
> Doesn't swap just delay the fundamental issue?
The fundamental issue here is what the linux fanboys literally think what killing a working process and most of the time the process[0] is a good solution for not solving the fundamental problem of memory allocation in the Linux kernel.
Availability of swap allows you to avoid malloc failure in a rare case your processes request more memory than physically (or 'physically', heh) present in the system. But in the mind of so called linux administrators even if a one byte of the swap would be used then the system would immediately crawl to a stop and never would recover itself. Why it always should be the worst and the most idiotic scenario instead of a sane 'needed 100MB more, got it - while some shit in the memory which wasn't accessed since the boot was swapped out - did the things it needed to do and freed that 100MB' is never explained by them.
[0] imagine a dedicated machine for *SQL server - which process would have the most memory usage on that system?
Also: When those processes that haven't been active since boot (and which may never be active again) are swapped out, more system RAM can become available for disk caching to help performance of things that are actively being used.
And that's... that's actually putting RAM to good use, instead of letting it sit idle. That's good.
(As many are always quick to point out: Swap can't fix a perpetual memory leak. But I don't think I've ever seen anyone claim that it could.)
And maybe plan on getting more RAM.
(It's your system. You're allowed to tune it to fit your usage.)
What if I've got 64G of ram and 64G of swap and need the same amount of memory?
And no, if you need 100MB more then it's literally not important how much RAM do you have. You just needed 100MB more this time.
Adding a couple of gb of swap means the image resizing is _slow_, but completes without causing issues.
Detecting things are down is far easier than detecting things are slow.
I'd rather that oom started killing things though than a kernel panic or a slow system. Ideally the thing that is leaking, but if not the process using the most memory (and yes I know that "using" is tricky)
So most of the time I'd prefer option 3: the OOM killer to reap a few offending programs and let me handle restarting them.
I’m gonna guess you’re not old enough to remember computers with memory measured in MB and IDE hard disks? Swapping was absolutely brutal back then. I agree with the other poster, swap hitting an SSD is a barely noticeable in comparison.
If the slowest drive on the machine is the SSD, how does caching to swap help?
This cache is evictable, but it'll be there eventually.
Linux used to don't touch unused pages in the RAM in the older days if your RAM was not under pressure, but now it swaps out pages unused for a long time. This allows more cache space in RAM.
> how does caching to swap help?
I think I failed to convey what I tried to say. Let me retry:
Kernel doesn't cache to SSD. It swaps out unused (not accessed) but unevictable pages to SWAP, assuming that these pages will stay stale for a very long time, allowing more RAM to be used as cache.
When I look to my desktop system, in 12 days, Kernel moved 2592MB of my RAM to SWAP despite having ~20GB of free space. ~15GB of this free space is used as disk cache.
So, to have 2.5GB more disk cache, Kernel moved 2592 MB of non-accessed pages to SWAP.
I DON’T WANT THE KERNEL PRIORITIZING CACHE OVER NRU PAGES. The easiest way to do this is to disable swap.
Then tell the Kernel about it. Don't remove a feature which might benefit other things running on your system.
> Lock all pages which are currently mapped into the address space of the process.
> Lock all pages which will become mapped into the address space of the process in the future.
wallstop@fridge:~$ swapon --show NAME TYPE SIZE USED PRIO /swap.img file 4G 0B -2
wallstop@fridge:~$ uptime 22:59:29 up 37 days, 21:39, 1 user, load average: 0.00, 0.00, 0.00
This is from another system I have close:
                   total        used        free      shared  buff/cache   available
    Mem:           31881        1423        1042          10       29884       30457
    Swap:            976           2         974
ls -lrt, ls -lSh and ls -lShr are also very common in my daily use, depending on what I'm doing.
               total        used        free      shared  buff/cache   available
    Mem:           31989       11350        4474        2459       16164       19708
    Swap:           6047          20        6027
    Mem:            1919         333          75           0        1511        1403
    Swap:           2047         803        1244
If I were to increase this to 8G of ram instead of 2G, but for arguments sake had to have no swap as the tradeoff, would that be better or worse. Swap fans say worse.
As I noted somewhere, my other system has 2,5GB of SWAP allocated over 13 days. That system is a desktop system and juggles tons of things everyday.
I have another server with tons of RAM, and the Kernel decided not to evict anything to SWAP (yet).
> If I were to increase this to 8G of ram instead of 2G, but for arguments sake had to have no swap as the tradeoff, would that be better or worse. Swap fans say worse.
I'm not a SWAP fan, but I support its use. On the other hand I won't say it'd be worse, but it'd be overkill for that server. Maybe I can try 4, but that doesn't seem to be necessary if these numbers are stable over time.
How about this server:
             total       used       free     shared    buffers     cached
  Mem:          8106       7646        459          0        149       6815
  -/+ buffers/cache:        681       7424
  Swap:         6228         25       6202
How long does the server have to run to reach 100% of ram?
25MB swap use seems normal for a server which doesn't juggle much tasks, but works on one.
The easiest way affecting everything running on the system might not be the best or even the correct way to do things.
There's always more than one way to solve a problem.
Reading the Full Manual (TM) is important.
I'm not an AWS guy. I can see and touch the servers I manage, and in my experience, SWAP works, and works well.
However, from my experience, normal (eviction based) usage of SWAP doesn't impact the life of an SSD in a measurable manner. My 256GB system SSD (of my desktop system) shows 78% life remaining after 4 years of power on hours, which also served as /home for at least half of its life.
This is not about belief, but lived experience. Setting up swap to me is a choice between a unresponsive system (with swap) or a responsive system with a few oom kills or downed system.
I mean, I manage some servers, and this is my experience.
> Setting up swap to me is a choice between a unresponsive system (with swap) or a responsive system with a few oom kills or downed system.
Sorry, but are you sure that you budgeted your system requirements correctly? A Linux system shall neither fill SWAP nor trigger OOM regularly.
With a good amount of swap, you don't have to worry about closing programs. As long as your 'working set' stays smaller than your RAM, your computer stays fast and responsive, regardless of what's open and idling in the background.
Old habits die hard, but I'm not complaining about this one. :)
Without swap oom killer runs and things become responsive.
I still don’t use it though.
I once used an Intel Optane drive as swap for a job that needed hundreds of gigabytes of ram (in a computer that maxed out at 64 gigs). The latency was so low that even while the task was running the machine was almost perfectly usable; in fact I could almost watch videos without dropping frames at the same time.
The free memory won't go below a configurable percentage and the contiguous io algorithms of the swap code and i/o stack can still do their work.
Here’s a screenshot from atop while the task was running: <https://db48x.net/temp/Screenshot%20from%202019-11-19%2023-4...>. Note the number of page faults, the swin and swout (swap in and swap out) numbers, and the disk activity on nvme0n1. Swap in is 150k, and the number of disk reads was 116k with an average size of 6KB. Swap out was 150k with 150k disk writes of 4KB. It’s also reading from sdh at a fair clip (though not as fast as I wanted!)

<https://db48x.net/temp/Screenshot%20from%202019-12-09%2011-4...> is interesting because it actually shows 24KB average write size. But notice that swout is 47k but there were actually 57k writes. That’s because the program I was testing had to write data out to disk to be useful, and I had it going to a different partition on the same nvme disk. Notice the high queue depth; this was a very large serial write. The swap activity was still all 4KB random IO.
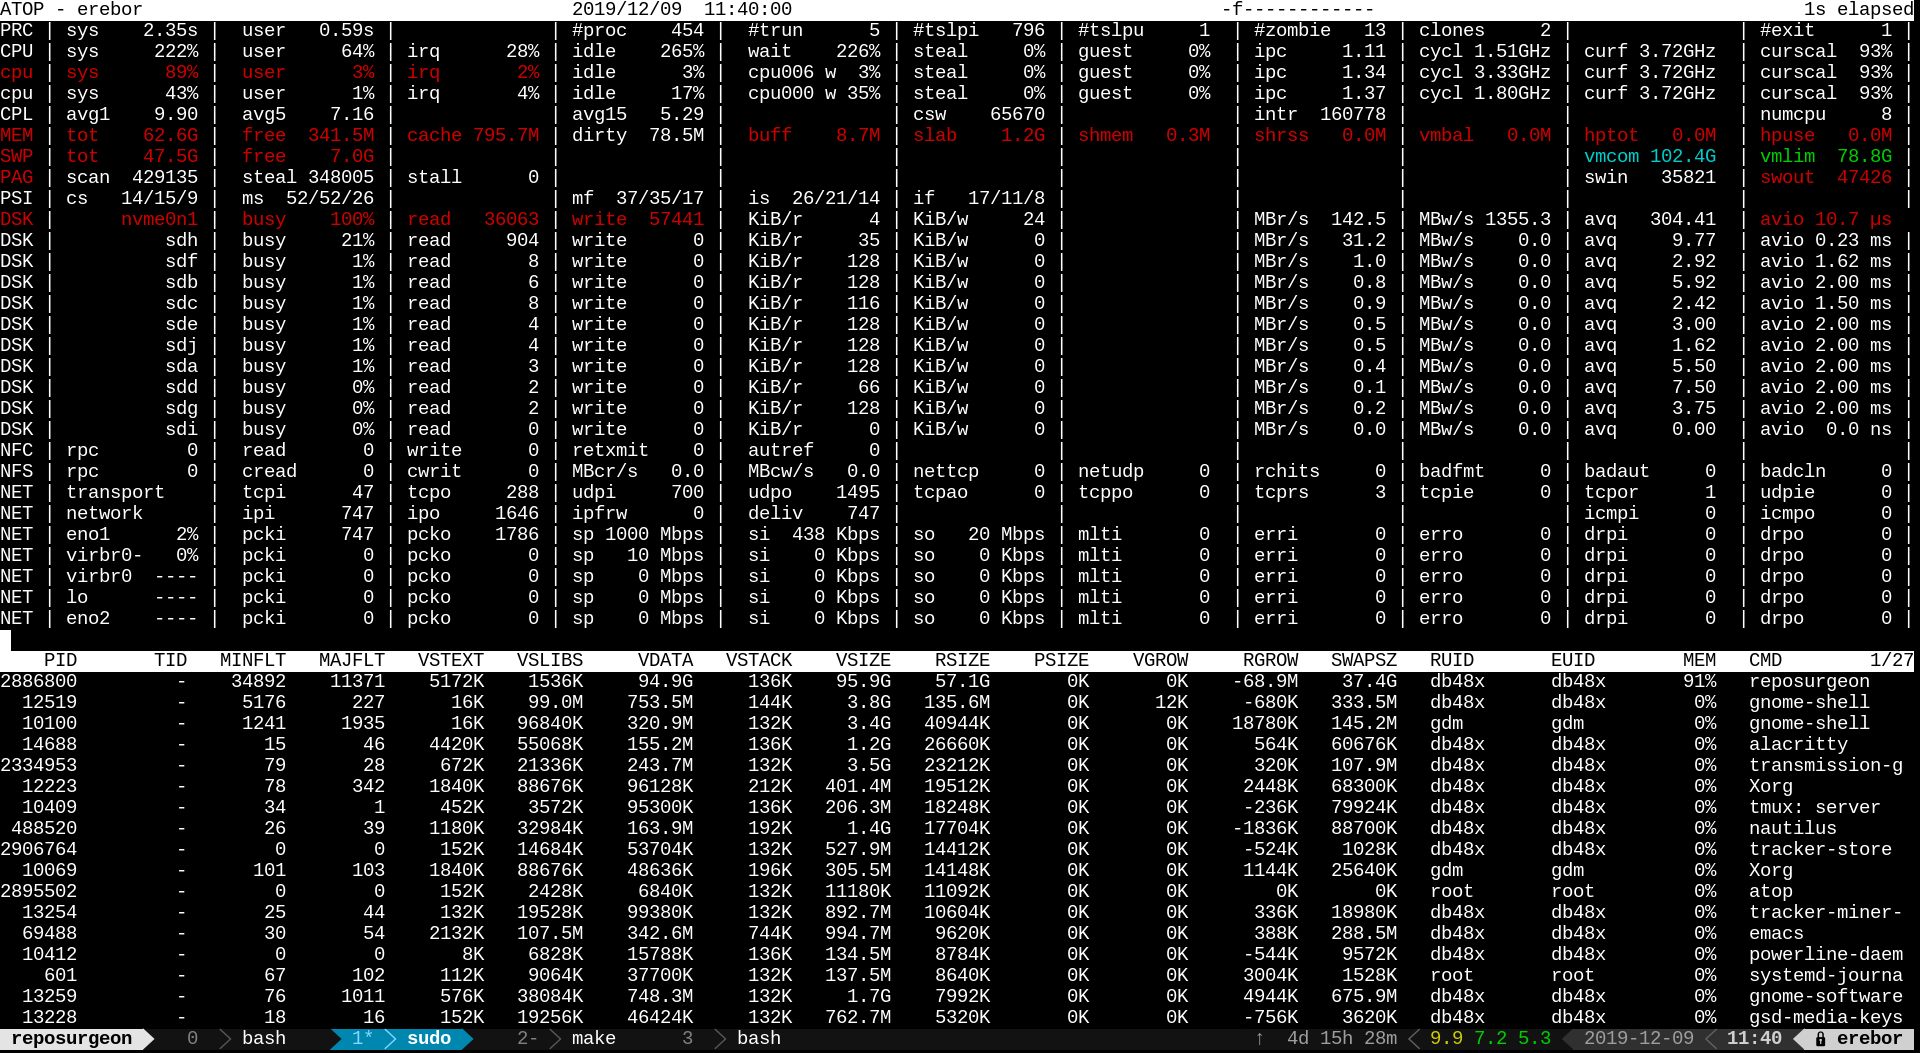
I rewrote a slice of the program in Rust with quite promising results, but by that time there wasn’t really any demand left. You see, one of the many uses of Reposurgeon <http://www.catb.org/esr/reposurgeon/> is to convert SVN repositories into Git repositories. These performance results were taken while reposurgeon was running on a dump of the GCC source code repository. At the time this was the single largest open source SVN repository left in the world with 287k commits. Now that it’s been converted to a Git repository it’s unlikely that future Reposurgeon users will have the same problem.
Also, someone pointed out that MG-LRU <https://docs.kernel.org/admin-guide/mm/multigen_lru.html> might help by increasing the block size of the reads and writes. It was introduced a year or more after I took these screenshots, so I can’t easily verify that.
MGLRU is basically a smarter version of already existing eviction algorithm, with evicts (or keeps) both page cache and anon pages, and combined with min_ttl_ms it tries to keep current active page cache for a specified amount of time. It still takes into account swappiness and does not operate on a fixed amount of page cache, unlike le9.
Both are effective in trashing prevention, both are different. MGLRU, especially with higher min_ttl_ms, could cause OOM killer more frequently than you'd like it to be called. I find le9 more effective for desktop use on old low-end machines, but that's only because it just keeps the (large/er amounts of) page cache. It's not very preferable for embedded systems for example.
Swap helps you use ram more efficiently, as you put the hot stuff in swap and let the rest fester on disk.
Sure if you overwhelm it, then you're gonna have a bad day, but thats the same without swap.
Seriously, swap is good, don't believe the noise.
That is my interpretation of what people are saying upthread, at least. To which posters such as yourself are saying “you still need swap.” Why?
It's a bit wasteful to provision your computers so that all the cold data lives in expensive RAM.
But that's a job applications are already doing. They put data that's being actively worked on in RAM they leave all the rest in storage. Why would you need swap once you can already fit the entire working set in RAM?
In that case, and if you are only running these applications, the need for swap is much less.
Almost by definition, that leaked memory is never accessed again, so it's very cold. But the applications don't put this on disk by themselves. (If the app's developers knew about which specific bit is leaking, they'd rather fix the leak then write it to disk.)
Swap ram by itself would be stupid but no one doing this isn’t also turning on compression.
I'm not sure what you mean here? Swapping out infrequently accesses pages to disk to make space for more disk cache makes sense with our without compression.
Uhh... A VMM that swaps out to disk an allocated page to make room for more disk cache would be braindead. The process has allocated that memory to use it. The kernel doesn't have enough information to deem disk cache a higher priority. The only thing that should cause it to be swapped out is either another process or the kernel requesting memory.
Claiming any decision is “brain dead” in something as heuristic heavy and impossible to compute optimally as resident memory pages is quite the statement to make; this is a form of the knapsack problem (NP-complete at least) with the added benefit of time where the items are needed in some specific indeterminate order in the future and there’s a whole bunch of different workloads and workload permutations that alter this.
To drive this point home in case you disagree, what’s dumber? Swapping out to disk an allocated page (from the kernel’s perspective) that’s just sitting in the free list of the userspace allocator for that process or a page of some frequently accessed page of data?
Now, I agree that VMMs may not do this because it’s difficult to come up with these kinds of scenarios that don’t penalize the general case, more importantly than performance this has to be a mechanism that is explainable to others and understandable for them. But claiming it’s a braindead option to even consider is IMHO a bridge too far.
If you size your RAM and swap right, you get no service degradation, but still get away with using less RAM.
But when I was at Google (about a decade ago), they followed exactly the philosophy you were outlining and disabled swap.
Right, you seem to be not understanding what I'm getting at.
Memory exhaustion is bad, regardless of swap or not.
Swap gets you a better performing machine because you can swap out shit to disk and use that ram for vfs cache.
the whole "low latency" and "I want my VM to die quicker" is tacitly saying that you haven't right sized your instances, your programme is shit, and you don't have decent monitoring.
Like if you're hovering on 90% ram used, then your machine is too small, unless you have decent bounds/cgroups to enforce memory limits.
Many won't enable swap. For some swap wouldn't help anyways, but others it could help soak up spikes. The latter in some cases will upgrade to a larger instance without even evaluating if swap could help, generating AWS more money.
Either way it's far-fetched to derive intention from the fact.
Nowadays when a program hits swap it's not going to fallback to a different memory usage profile that prioritises disk access. It's going to use swap as if it were actual ram, so you get to see the program choking the entire system.
If your GC is a moving collector, then absolutely this is something to watch out for.
There are, however, a number of runtimes that will leave memory in place. They are effectively just calling `malloc` for the objects and `free` when the GC algorithm detects an object is dead.
Go, the CLR, Ruby, Python, Swift, and I think node(?) all fit in this category. The JVM has a moving collector.
It's that "touching" of all the pages controlled by the GC that ultimately wrecks swap performance. But also the fact that moving collector like to hold onto memory as downsizing is pretty hard to do efficiently.
Non-moving collectors are generally ultimately using C allocators which are fairly good at avoiding fragmentation. Not perfect and not as fast as a moving collector, but also fast enough for most use cases.
Java's G1 collector would be the worst example of this. It's constantly moving blocks of memory all over the place.
The memory that's now not in use, but still held onto, can be swapped out.
Tracing garbage collectors solve a single problem really really well - managing a complex, possibly cyclical reference graph, which is in fact inherent to some problems where GC is thus irreplaceable - and are just about terrible wrt. any other system-level or performance-related factor of evaluation.
Even not so modern ones: have you heard of generational garbage collection?
But even in eg Python they introduced 'immortal objects' which the GC knows not to bother with.
There's a lot of "it depends" here.
For example, an RC garbage collector (Like swift and python?) doesn't ever trace through the graph.
The reason I brought up moving collectors is by their nature, they take up a lot more heap space, at least 2x what they need. The advantage of the non-moving collectors is they are much more prompt at returning memory to the OS. The JVM in particular has issues here because it has pretty chunky objects.
If the implementer cares about memory use it won't. There are ways to compact objects that are a lot less memory-intensive than copying the whole graph from A to B and then deleting A.
Also since the refcounts are inline, adding a reference to a cold object will update that object. IIRC Swift has the latter issue as well (unless the heap object’s RC was moved to the side table).
I regularly use it on my Snapdragon 870 tablet (not exactly a top of the line CPU) to prevent OOM crashes (it's running an ancient kernel and the Android OOM killer basically crashes the whole thing) when running a load of tabs in Brave and a Linux environment (through Tmux) at the same time.
ZRAM won't save you if you do actually need to store and actively use more than the physical memory but if 60% of your physical memory is not actively used (think background tabs or servers that are running but not taking requests) it absolutely does wonders!
On most (web) app servers I happily leave it enabled to handle temporary spikes, memory leaks or applications that load a whole bunch of resources that they never ever use.
I'm also running it on my Kubernetes cluster. It allows me to set reasonable strict memory limits while still having the certainty that Pods can handle (short) spikes above my limit.
Would love to be corrected if I'm wrong
If swapping to SSD is 'extremely slow', what's your term for swapping to HDD?
Yup, this is a thing. It happens because file-backed program text and read-only data eventually get evicted from RAM (to make room for process memory) so every access to code and/or data beyond the current 4K page can potentially involve a swap-in from disk. It would be nice if we had ways of setting up the system so that pages of code or data that are truly critical for real-time responsiveness (including parts of the UI) could not get evicted from RAM at all (except perhaps to make room for the OOM reaper itself to do its job) - but this is quite hard to do in practice.
Example on my personal VPS
   $ free -m
                  total        used        free      shared  buff/cache   available
   Mem:            3923        1225         328         217        2369        2185
Swap: 1535 1335 200Swap is good to have. The value is limited but real.
Also not having swap doesn't prevent thrashing, it just means that as memory gets completely full you start dropping and re-reading executable code over and over. The solution is the same in both cases, kill programs before performance falls off a cliff. But swap gives you more room before you reach the cliff.
But also false. Swap is there so anonymous pages can be evicted. Not as a “slow overflow for RAM”, as a lot of people still believe.
By disabling swap you can actually *increase* thrashing, because the kernel is more limited in what it can do with the virtual memory.
My experience is the exact opposite. If anything 2-3 second button clicks are more common than ever today since everything has to make a roundtrip to a server somewhere whereas in the 90s 2-3s button click meant your computer was about to BSOD.
Edit: Apple recently brought "2-3s to open tab" technology to Safari[1].
[1] https://old.reddit.com/r/MacOS/comments/1nm534e/sluggish_saf...
NSDJUST=$(pgrep -x nsd); echo -en '-378' > /proc/"${NSDJUST}"/oom_score_adj
    vm.overcommit_memory = 0
    vm.overcommit_ratio = 0
    vm.admin_reserve_kbytes = 262144
    vm.user_reserve_kbytes = 262144
    vm.min_free_kbytes = 1024000
Another option is to limit memory per application in cgroups but that requires more explaining than I am putting in an HN comment.
Another useful thing is to never OOM kill in the first place on servers that are only doing things in memory and need not commit anything to disk. So don't do this on a disked database. This is for ephemeral nodes that should self heal. Wait 60 seconds so drac/ilo can capture crash message and then earth shattering kaboom...
    # cattle vs kittens, mooooo...
    kernel.panic = 60
    vm.panic_on_oom = 2
Companies that use k3/k8's they may still have bare metal nodes that are dedicated to a role such as databases, ceph storage nodes, DMZ SFTP servers, PCI hosts that were deemed out of scope for kube clusters and of course any "kittens" such as Linux nodes turned into proprietary appliances after installing some proprietary application that will blow chunks if shimmed into k8's or any other type of abstraction layer.
Is earlyoom a better solution than that to prevent an erratic process from making an instance unresposnsive?
Gives you some time to upgrade, or tune services before it goes ka-boom.
If your memory usage spikes suddenly, a nominal amount of swap isn't stopping anything from getting killed; you're at best buying yourself a few seconds, so unless you spend your time just staring at the server, it'll be dead anyways.
As a small example from a default Ubuntu installation, "unattended-upgrades" is holding 22MB of RSS, and will not impact system performance at all if it spends next week swapped out. Bigger examples can be found in monolithic services where you don't use some of the features but still have to wire them into RAM. You can page those inactive sections of the individual process into swap, and never notice.
And of course the overhead is zero when you don't page-out to swap.
For an algorithm using the whole memory, that’s a terrible idea.
I understand all of those words, but none of the meaning. Why would I reserve RAM in order to put fast swap on it?
This has a number of benefits: in practice more “active” space is freed up as unused pages are compressed and often compressible. Often times that can be freed application memory that is reserved within application space but in the free space of the allocator, especially if that allocator zeroes it those pages in the background, but even active application memory (eg if you have a browser a lot of the memory is probably duplicated many times across processes). So for a usually invisible cost you free up more system RAM. Additionally, the overhead of the swap is typically not much more than a memcpy even compressed which means that you get dedup and if you compressed erroneously (data still needed) paging it back in is relatively cheap.
It also plays really well with disk swap since the least frequently used pages of that compressed swap can be flushed to disk leaving more space in the compressed RAM region for additional pages. And since you’re flushing retrieving compressed pages from disk you’re reducing writes on an SSD (longevity) and reducing read/write volume (less overhead than naiive direct swap to disk).
Basically if you think of it as tiered memory, you’ve got registers, l1 cache, l2 cache, l3 cache, normal RAM, compressed swap RAM, disk swap - it’s an extra interim tier that makes the system more efficient.
I do: https://postimg.cc/G8Gcp3zb (casualmeasurement.png)
To clarify OP's represention of the tool, it compresses swap space not resident ram. Outside of niche use-cases, compressing swap has overall little utility.
It has the benefit of absorbing memory leaks (which for whatever reason compress really well) and compressing stale memory pages.
Under actual memory pressure performance will degrade. But in many circumstances where your powerful CPU is not fully utilized you can 2x or even 3x your effective RAM (you can opt for zstd compression). zram also enables you to make the trade-off of picking a more powerful CPU for the express purpose of multiplying your RAM if the workload is compatible with the idea.
PS: On laptops/workstations, zram will not interfere with an SSD swap partition if you need it for hibernation. Though it will almost never be used for anything else if you configure your zram to be 2x your system memory.
That reads like what they said? You reserve part of the RAM as a swap device, and memory is swapped from resident RAM to the swap ramdisk, as long as there’s space on there. And AFAIK linux will not move pages between swap devices because it doesn’t understand them beyond priority.
Zswap actually seems strictly better in many cases (especially interactive computers / dev machines) as it can more flexibly grow / shrink, and can move pages between the compressed RAM cache and the disk swap.
To enable a swap file in Linux, first create the swap file using a command like sudo dd if=/dev/zero of=/swapfile bs=1G count=1 for a 1GB file. Then, set it up with sudo mkswap /swapfile and activate it using sudo swapon /swapfile. To make it permanent, add /swapfile swap swap defaults 0 0 to your /etc/fstab file. fallocate -l 1G /swapfile
chmod 600 /swapfile
mkswap /swapfile
swapon /swapfile
Partly it's a money thing (they want to sell you RAM), partly it's so that the shared disk isn't getting thrashed by multiple VPS
/swapfile swap swap sw 0 0
or via ansible:
    mount:
      src: "/swapfile"
      name: "swap"
      fstype: "swap"
      opts: "sw"
      passno: "0"
      dump: "0"
state: presentI don't think using swap as "emergency RAM" makes a lot of sense in 2025. The arguments in favor of swap which I find convincing are about allowing the system to evict low use pages which otherwise would not be evictable.
And that was like... two years ago? 1GB of RAM and actually ~700MB usable before I found the proper magik incantations to really disable kdump.
Also have used 1GB machines for literally years.
Strongly suggest you shouldn't strongly suggest.
You do understand what's being discussed... right?
Or you have a very peculiar understanding what 'VPS' means.
So no, VPS is a proper virtualization for a 15 years. And with a proper virtualization you have the full control.
systemd-oomd and oomd use the kernel's PSI[2] information which makes them more efficient and responsive, while earlyoom is just polling.
earlyoom keeps getting suggested, even though we have PSI now, just because people are used to using it and recommending it from back before the kernel had cgroups v2.
[0]: https://www.freedesktop.org/software/systemd/man/latest/syst...
> systemd-oomd periodically polls PSI statistics for the system and those cgroups to decide when to take action.
It's unclear if the docs for systemd-oomd are incorrect or misleading; I do see from the kernel.org link that the recommended usage pattern is to use the `poll` system call, which in this context would mean "not polling", if I understand correctly.
What I was trying to say is that the actual information on when there's memory pressure is more accurate for systemd-oomd / oomd because they use PSI, which the kernel itself is updating over time, and they just poll that, while earlyoom is also internally making its own estimates at a lower granularity than the kernel does.
I think it's off on the server variants.
The case of swap thrashing sounds like a misbehaving program, which can maybe be tamed by oomd.
System responsiveness though needs a complete resource control regime in place, that preserves minimum resources for certain critical processes. This is done with cgroupsv2. By establishing minimum resources, the kernel will limit resources for other processes. Sure, they will suffer. That’s the idea.
- hardware, networks, monitoring, provisioning, server room locations in existing buildings, how to prepare server rooms
- and so on up to hiring and firing sysadmins, salary negotiations[2], vendor negotiations and the first book even had a whole chapter dedicated to "Being happy"
[1] There is a third author as well now, but those two were the ones that are on the cover of my book from 2005 and that I can remember
[2] Has mostly worked well after I more or less left sysadmin behind as well
Therefore it is better to always tune "vm.swappiness" to 1 in /etc/sysctl.conf
You can also configure your web server / TCP stack buffers / file limits so they never allocate memory over the physical ram available. (eg. in nginx you can setup worker/connection limits and buffer sizes.)
As someone with zero ansible experience, can you elaborate on why a yaml list is better than a simple shell script with comments before each command?
Another option is to run BSD to avoid the Linux oom issue
For example, I'm not using Hetzner but I run NetBSD entirely from memory (no disk, no swap) and it never "went down" when out of memory
Looks like some people install FreeBSD and OpenBSD on Hetzner
https://gist.github.com/c0m4r/142a0480de4258d5da94ce3a2380e8...
https://computingforgeeks.com/how-to-install-freebsd-on-hetz...
https://web.archive.org/web/20231211052837if_/https://www.ar...
https://community.hetzner.com/tutorials/freebsd-openzfs-via-...
https://www.souji-thenria.net/posts/openbsd_hetzner/
https://web.archive.org/web/20220814124443if_/https://blog.v...
https://www.blunix.com/blog/how-to-install-openbsd-on-hetzne...
https://gist.github.com/ctsrc/9a72bc9a0229496aab5e4d3745af0b...
If it is possible to boot Hetzner from a BSD install image using "Linux rescue mode"^1 then it should also possible to run NetBSD entirely from memory using custom kernel
Every user is different but this is how I prefer to run UNIX-like OS for personal, recreational use; I find it more resilient
1.
https://docs.hetzner.com/robot/dedicated-server/troubleshoot...
https://blog.tericcabrel.com/hetzner-rescue-mode-unlock-serv...
https://github.com/td512/rescue
https://gainanov.pro/eng-blog/linux/hetzner-rescue-mode/
https://docs.hetzner.com/cloud/servers/getting-started/rescu...
ChromeOS has an interesting approach to Linux oom issues. Not sure it has ever been discussed on HN
https://github.com/dct2012/chromeos-3.14/raw/chromeos-3.14/m...
You can also enable zram to compress ram, so you can over-provision like the pros'. A lot of long-running software leaks memory that compresses pretty well.
Here is how I do it on my Hetzner bare-metal servers using Ansible: https://gist.github.com/fungiboletus/794a265cc186e79cd5eb2fe... It also works on VMs.