Sorry but there is no justification for this. With the same thermal constraints there is every expectation that an Apple / Arm CPU would be more performant and efficient than a comparable x86. Why? Because aarch64 doesn't have the historical legacy that x86 has and Apple has already shown what they can do in the iPad etc. Sure they won't be triple digits but it will enough to be noticeable.
And, as you say, they will have the advantage of Apple's custom silicon for specific use cases. So best of both worlds.
And the CISC vs RISC arguments are questionable, seeing that Apple has done the migration in both directions by now.
- Emphasise the breadth of their silicon expertise across CPU / GPU / Neural Engines etc. - Because Arm has little or no brand recognition (Apple > Intel > Arm in branding terms). - Distinguish from any me-too moves to Arm by competitors.
The absence of any ARM mention is marketing, nothing more.
Heck, I'm happy with 1 hour. I leave my laptop plugged in nearly 100% of the time. The point of the laptop is that it's easy to move, not that I want to use it while I'm in transit.
Intel tried to compete in mobile for a long time and failed even with a better manufacturing process.
Modern x86_64 processors don't actually natively execute x86 instructions, they translate them into the instructions the hardware actually uses. The percentage of the die required to do that translation is small and immaterial.
> Intel tried to compete in mobile for a long time and failed even with a better manufacturing process.
Intel didn't understand the market.
I recently bought a new phone. On paper it's twice as fast as my old phone. I imagine that's true but I can't tell any difference. Everything was sufficiently fast before and it still is. I never use my phone to do anything that needs an actually-fast CPU. I have no reason to pay additional money for a faster phone CPU. But I do notice how often I have to charge the battery.
These are not atypical purchasing criteria for mobile devices, but that's not the market Intel was chasing with their designs and pricing, so they failed. It's not because they couldn't make an x86 CPU for that market, it's because they didn't want to, because it's a lower margin commodity market.
They didn't fail because of performance, though, they failed because of app support & lack of a quality radio. The CPU performance & efficiency itself was otherwise fine. It wasn't always chart-topping good, but it wasn't bad either.
General point is that I think that Arm has a small architectural advantage due to lack of cruft but that other factors are usually more important - e.g. the resources and quality of team behind implementation.
Agreed that CISC vs RISC is very questionable by now.
It seems most people feel that the DEC Alpha went too far in weakening the memory model to improve performance, but A64 seems to at least be near the sweet spot.
It's also not a huge amount of work that gets thrown away decoding x86 instructions in parallel, but there's non-zero overhead introduced by having the start location of the next instruction depend on what the current instruction is.
iDevices weren't really made with games in mind, but they can push out performance that beats handheld gaming devices. Artists (including myself) use iPads extensively and the response time with the Apple Pencil beats out just about anything else on the market. The only limiting factor is the tiny memory that limits the file size and layer limit on some programs. They're just fine for watching video, and even multitasking with a video playing while working on something else. This is on tiny device with no active cooling and long battery life, beating out most laptops in the same price range.
I don't believe there is any curated use case. They're already more than capable of being general purpose computers. I mean, Apple is already openly advertising that they're making iPad OS more desktop-like and operable with mice and keyboards. Literally the only things holding them back are the OS and Apple's refusal to put some decent memory inside.
[1]https://www.top500.org/news/japan-captures-top500-crown-arm-... [2]https://news.ycombinator.com/item?id=23601098
I’d be interested in estimates of how much hand-written AVX/SSE your computer actually runs. The apps I’ve seen usually have a fairly small core of AVX/SSE code.
In an even more niche area (high-end VFX apps, like compositors, renderers) SSE/AVX intrinsics are used quite a bit in performance-critical parts of the code, and auto-vectorisers can't yet do as good a job (they're pretty useless at conditionals and masking).
The memory model differences are going to be painful to debug, I think ("all-the-world's-a-VAX syndrome" is now "all the world's a Pentium/x86-64").
https://www.macrumors.com/2020/05/12/ipad-pro-vs-macbook-air...
https://www.anandtech.com/show/15578/cloud-clash-amazon-grav...
>> "As fast" on specific curated use cases. Show me an Apple chip that beats any laptop on 7zip.
> Is this a joke, what kind of usage benchmark is 7zipping large numbers of files?
A benchmark that Apple is unlikely to have implemented specific optimizations for, which therefore is a better test of the general purpose performance of the chip.
The situation being claimed here is sort of like if someone cited a DES benchmark to claim that Deep Crack's DES cracking chips (https://en.wikipedia.org/wiki/EFF_DES_cracker) were faster than a contemporary 1998 Pentium II.
edit: Just tried compressing a large file, ultra setting on my desktop i5 CPU, it's running at 3 MB/s on 1 core.
If true, that's just a nitpick that doesn't affect the overall point of the GGGP, though.
(Semi-seriously, I don't know anyone who uses a Unix(-like) system who uses 7zip, although I'm sure they're out there. For the record, I just unzipped a 120M archive on both my 2020 Core i7 MacBook Air and my 2018 (last-gen) iPad Pro and as near as I can tell the iPad was faster actually extracting the files, but had an extra second or so of overhead from the UI.)
7zip is an implementation of LZMA, like xz. So, different names and file format details, but essentially the same algorithm.
Linux distributions have been using xz compression for all packages (replacing gzip). So to the question of how relevant is xz/lzma/7zip performance to day to day task, is it's a lot relevant.
The successor will probably be zstd in the coming years. https://www.phoronix.com/scan.php?page=news_item&px=Fedora-3...
I read about a chip that had that feature yesterday but I can’t find the link unfortunately.
I guess AMD is fine for me (as is my old Intel-notebook) and I'll just wait for POVray, GROMACS and Co.
EDIT: And well, I noticed, supposedly Anandtech ran SPECint2006 on the A13 (and numerous other chips) - they ran it with WSL for x86 (because running on a dozen Android things is easier than running a standard benchmark on Linux/Windows ofc). You find the results here: https://images.anandtech.com/doci/14892/spec2006-global-over... - I guess (not sure, because it's for some reason not cleary marked and mentioned...) these are SPECint2006-results. So, let's check them for validity (because WSL is no problem and it matches Linux ofc); just looking at an i7-6700K (which is a little bit behind the i9-9900K they supposedly ran on): https://www.spec.org/cpu2006/results/res2016q1/cpu2006-20160... - marginal worse performance than @anandtech in some benchmarks, but that's with an older CPU and an older arch! And then there are the 3 or 4 benchmarks which are just way off. Makes one wonder, what they really did (because of course, installing CentOS and running SPEC on native Linux is too much of a hassle, when running and compiling on 8 ARM-platforms!?)
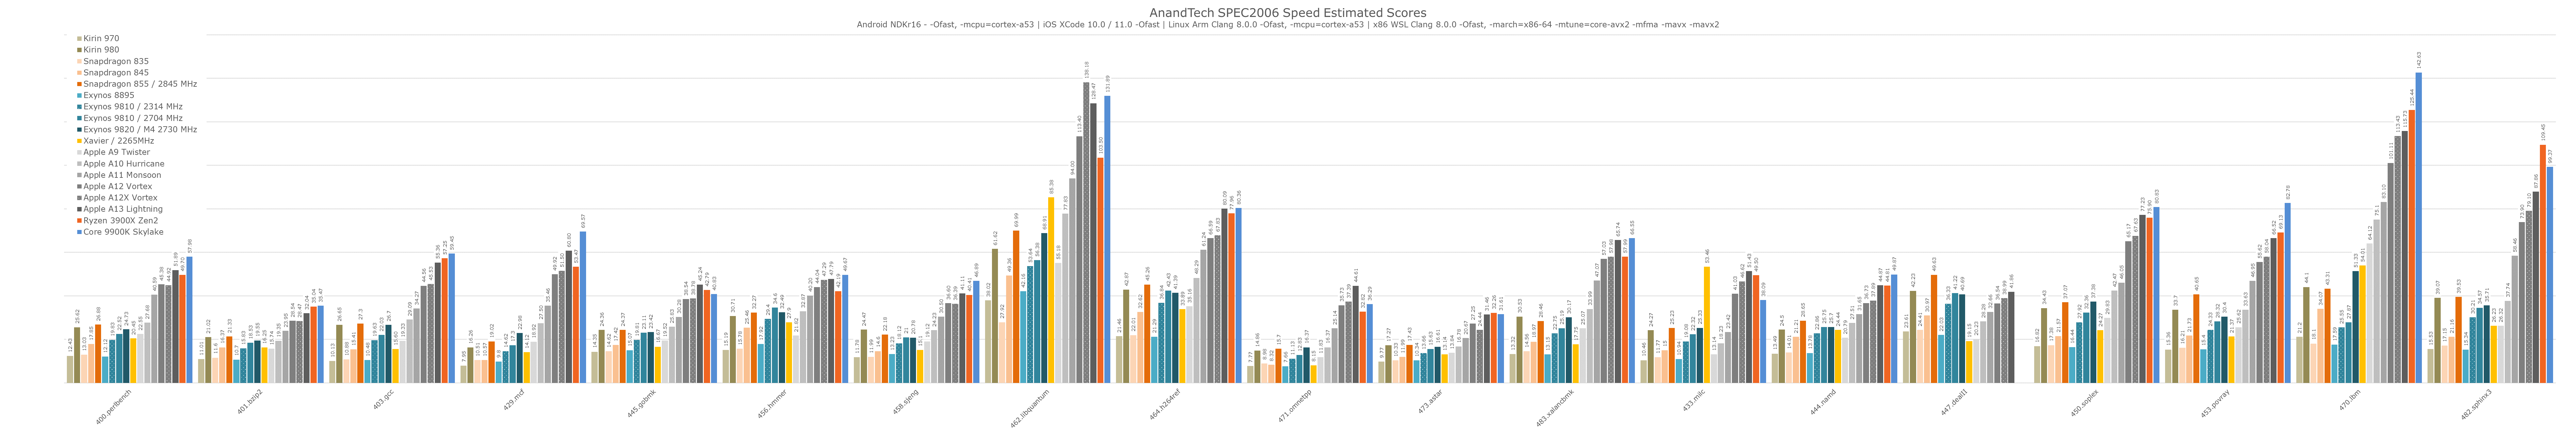
EDITEDIT: it's even worse for SPECfp2006: https://www.spec.org/cpu2006/results/res2016q1/cpu2006-20160... [well, here the old 6700K suddenly sometimes is twice as fast as the 9900K and 3x as fast as the A13 (and yeah the story of the 2.8GHz-low-power-chip drawing circles around a 4.5GHz-HF-part just didn't sound convincing in the first place...)]
Andrei mentions this here: https://www.realworldtech.com/forum/?threadid=187314&curpost...
And some other things which are bugging me:
- can you only optimize for A53 on Android with the big.LITTLE-configurations (they do!)?
- so they cross-compiled an AMD64-producing gcc 3.2 with Xcode 10 on MacOS-X for ARM? impressive.
E.g., a nice article from 2010: https://nofilmschool.com/2010/07/apple-snubs-adobe-again-wit...
There is no guarantee that a phone-scale CPU can just become 4x faster by 4x'ing the power/TDP/die area. If it were that easy, Intel would already have done it (and no, the x86 architecture isn't so terribly inefficient that they are leaving triple-digit percentage improvements on the table).
What I expect we'll see are ARM chips that are power and performance competitive with x86 chips only for specific curated use cases. Apple will extract an advantage by putting custom hardware acceleration into them, to cater for those specific tasks. They will not be able to achieve general purpose performance improvements wildly beyond what Intel can already do.
This is how the current iDevices achieve their excellent performance and battery life. Not through raw general-purpose CPU horsepower, but by a finely tuned synergy between hardware and software. Apple are taking their desktop down the same route. This will be the ultimate competitive advantage for their own software - they will be able to move key software components into hardware, and make it look like magic. But as a developer, you won't be able to participate in this unless you target Apple-blessed hardware instructions/APIs. Your Python script isn't going to start running 4x faster unless you can convince Apple to implement its inner loop in custom silicon.
I have no doubt that Apple will be leaning hard into ASIC territory as they build out their new CPUs. The endgame? Every software function you need, baked into perfectly optimised silicon by the monovendor.