News for hackers. Stuff that matters.
Re:Apple announces it will switch to its own processors for ... by eanzenberg on Monday June 22, 2020 @04:36PM (#23606238)
They already have a mobile chip that is as fast as an active-thermally cooled notebook chip.
Re:Apple announces it will switch to its own processors for ... by alkonaut on Monday June 22, 2020 @04:46PM (#23606386)
Isn't that for specific benchmarks though such as some geekbench/specint or web browsing benchmarks? I worry about non-gpu floating point for example. There is so much hand-optimized AVX/SSE code out there in big apps.
Re:Apple announces it will switch to its own processors for ... by klodolph on Monday June 22, 2020 @05:00PM (#23606586)
There’s a fair bit of AVX/SSE code out there, but these days the vast bulk of AVX/SSE code is generated by the autovectorizer and that’s mostly going to work on NEON without a hitch. Clang enables the autovectorizer at -O2 by default.

I’d be interested in estimates of how much hand-written AVX/SSE your computer actually runs. The apps I’ve seen usually have a fairly small core of AVX/SSE code.

Re:Apple announces it will switch to its own processors for ... by berkut on Monday June 22, 2020 @09:22PM (#23609007)
They're admittedly not applications most users run every day, but many multimedia applications (audio processing, encoding, decoding) is mostly done with hand-crafted instrinsics, the same goes for video stuff.

In an even more niche area (high-end VFX apps, like compositors, renderers) SSE/AVX intrinsics are used quite a bit in performance-critical parts of the code, and auto-vectorisers can't yet do as good a job (they're pretty useless at conditionals and masking).

Re:Apple announces it will switch to its own processors for ... by saagarjha on Tuesday June 23, 2020 @07:24AM (#23612482)
Even less esoteric: your libc likely has at least a half dozen vectorized functions for the mem* and str* functions.
Re:Apple announces it will switch to its own processors for ... by wolf550e on Monday June 22, 2020 @07:10PM (#23608026)
But is the bulk of AVX code by time spent running, code that was generated by autovectorizer? The SIMD in openssl and ffmpeg is written by hand. I bet the code that spends a lot of time on the CPU, especially the code that runs a lot while humans are waiting, is written by hand.
Re:Apple announces it will switch to its own processors for ... by throwaway5792 on Tuesday June 23, 2020 @02:33AM (#23610531)
Those should have AArch64 versions written. AArch64 is old now, it's not some niche architecture.
Re:Apple announces it will switch to its own processors for ... by wolf550e on Tuesday June 23, 2020 @08:41AM (#23613076)
Desktop productivity content creation apps have never before needed ARM versions, so many probably don't have ARM specific optimizations, and some probably have x86 specific code that is just enabled by default.

The memory model differences are going to be painful to debug, I think ("all-the-world's-a-VAX syndrome" is now "all the world's a Pentium/x86-64").

Re:Apple announces it will switch to its own processors for ... by jl6 on Monday June 22, 2020 @04:46PM (#23606391)
"As fast" on specific curated use cases. Show me an Apple chip that beats any laptop on 7zip.
Re:Apple announces it will switch to its own processors for ... by tshaddox on Monday June 22, 2020 @05:19PM (#23606829)
I don’t know about 7zip specifically, but the iPad Pro seems to beat even some MacBook Pros on some benchmarks.

https://www.macrumors.com/2020/05/12/ipad-pro-vs-macbook-air...

Re:Apple announces it will switch to its own processors for ... by tw04 on Monday June 22, 2020 @05:16PM (#23606801)
Given that Amazon was able to get there, what makes you think Apple can't? I would struggle to believe that Annapurna Labs has any significant advantage over PA Semi given the track record PA has had since joining Apple, and the fact they had nearly a decade head-start.

https://www.anandtech.com/show/15578/cloud-clash-amazon-grav...

Re:Apple announces it will switch to its own processors for ... by fock on Monday June 22, 2020 @06:00PM (#23607373)
not sure, what they are measuring though - random Xeon from spec.org: https://www.spec.org/cpu2006/results/res2017q3/cpu2006-20170... ; at most 30% higher frequency, yet twice as fast. Well...
Re:Apple announces it will switch to its own processors for ... by r00fus on Monday June 22, 2020 @04:59PM (#23606565)
Is this a joke, what kind of usage benchmark is 7zipping large numbers of files?
Re:Apple announces it will switch to its own processors for ... by ardy42 on Monday June 22, 2020 @05:31PM (#23606991)
>>> They already have a mobile chip that is as fast as an active-thermally cooled notebook chip.

>> "As fast" on specific curated use cases. Show me an Apple chip that beats any laptop on 7zip.

> Is this a joke, what kind of usage benchmark is 7zipping large numbers of files?

A benchmark that Apple is unlikely to have implemented specific optimizations for, which therefore is a better test of the general purpose performance of the chip.

The situation being claimed here is sort of like if someone cited a DES benchmark to claim that Deep Crack's DES cracking chips (https://en.wikipedia.org/wiki/EFF_DES_cracker) were faster than a contemporary 1998 Pentium II.

Re:Apple announces it will switch to its own processors for ... by r00fus on Monday June 22, 2020 @05:35PM (#23607033)
A benchmark that probably relies as much on disk access speeds as CPU?
Re:Apple announces it will switch to its own processors for ... by user5994461 on Monday June 22, 2020 @05:49PM (#23607229)
Nope, 7zip is using LZMA algorithm for compression, which is around a few MB/s on the fastest CPU. It's heavily CPU bound.

edit: Just tried compressing a large file, ultra setting on my desktop i5 CPU, it's running at 3 MB/s on 1 core.

Re:Apple announces it will switch to its own processors for ... by dwaite on Tuesday June 23, 2020 @02:09AM (#23610423)
Apple ships a framework for doing lzma and other compression algorithms. I doubt they will be taken by surprise
Re:Apple announces it will switch to its own processors for ... by r00fus on Monday June 22, 2020 @07:08PM (#23608001)
One large file could be CPU bound, many small files (which is partly why you zip/jar things up) is disk bound.
Re:Apple announces it will switch to its own processors for ... by stjohnswarts on Monday June 22, 2020 @05:59PM (#23607354)
Not true. the bottleneck is going to be compression not disk access.
Re:Apple announces it will switch to its own processors for ... by ardy42 on Monday June 22, 2020 @05:44PM (#23607164)
> A benchmark that probably relies as much on disk access speeds as CPU?

If true, that's just a nitpick that doesn't affect the overall point of the GGGP, though.

Re:Apple announces it will switch to its own processors for ... by AlexandrB on Monday June 22, 2020 @05:17PM (#23606806)
I think the point is that it won’t be as fast in applications that Apple didn’t anticipate.
Re:Apple announces it will switch to its own processors for ... by chipotle_coyote on Monday June 22, 2020 @05:17PM (#23606812)
I believe it is what the poster you are replying to would call "a specific curated use case."

(Semi-seriously, I don't know anyone who uses a Unix(-like) system who uses 7zip, although I'm sure they're out there. For the record, I just unzipped a 120M archive on both my 2020 Core i7 MacBook Air and my 2018 (last-gen) iPad Pro and as near as I can tell the iPad was faster actually extracting the files, but had an extra second or so of overhead from the UI.)

Re:Apple announces it will switch to its own processors for ... by ac29 on Monday June 22, 2020 @05:44PM (#23607154)
> I don't know anyone who uses a Unix(-like) system who uses 7zip

7zip is an implementation of LZMA, like xz. So, different names and file format details, but essentially the same algorithm.

Re:Apple announces it will switch to its own processors for ... by user5994461 on Monday June 22, 2020 @06:01PM (#23607375)
Correct. 7zip is a LZMA compressor. The common equivalent command line tool on Linux is xz.

Linux distributions have been using xz compression for all packages (replacing gzip). So to the question of how relevant is xz/lzma/7zip performance to day to day task, is it's a lot relevant.

The successor will probably be zstd in the coming years. https://www.phoronix.com/scan.php?page=news_item&px=Fedora-3...

Re:Apple announces it will switch to its own processors for ... by rjsw on Monday June 22, 2020 @08:47PM (#23608789)
You can find a 7zip for UNIX here [1].

[1] http://p7zip.sourceforge.net/

Re:Apple announces it will switch to its own processors for ... by robocat on Monday June 22, 2020 @06:16PM (#23607527)
Actually the zip algorithm is a perfect candidate for dedicated silicon of a dedicated instruction.

I read about a chip that had that feature yesterday but I can’t find the link unfortunately.

Re:Apple announces it will switch to its own processors for ... by Sleaker on Monday June 22, 2020 @06:35PM (#23607733)
this is something that's looking at getting moved to storage controllers on motherboards, ex: PS5/Xbox consoles so that compressed data can be streamed directly to the GPU. Hopefully we'll start to get this type of tech after it's been proven in the console space.
Re:Apple announces it will switch to its own processors for ... by fomine3 on Monday June 22, 2020 @09:08PM (#23608897)
Intel QAT supports gzip compression.
Re:Apple announces it will switch to its own processors for ... by 43920 on Monday June 22, 2020 @05:24PM (#23606900)
Re:Apple announces it will switch to its own processors for ... by fock on Monday June 22, 2020 @04:44PM (#23606364)
so could you provide some actual, open-source basic benchmarks. And not strange, opaque geekbench results...

I guess AMD is fine for me (as is my old Intel-notebook) and I'll just wait for POVray, GROMACS and Co.

EDIT: And well, I noticed, supposedly Anandtech ran SPECint2006 on the A13 (and numerous other chips) - they ran it with WSL for x86 (because running on a dozen Android things is easier than running a standard benchmark on Linux/Windows ofc). You find the results here: https://images.anandtech.com/doci/14892/spec2006-global-over... - I guess (not sure, because it's for some reason not cleary marked and mentioned...) these are SPECint2006-results. So, let's check them for validity (because WSL is no problem and it matches Linux ofc); just looking at an i7-6700K (which is a little bit behind the i9-9900K they supposedly ran on): https://www.spec.org/cpu2006/results/res2016q1/cpu2006-20160... - marginal worse performance than @anandtech in some benchmarks, but that's with an older CPU and an older arch! And then there are the 3 or 4 benchmarks which are just way off. Makes one wonder, what they really did (because of course, installing CentOS and running SPEC on native Linux is too much of a hassle, when running and compiling on 8 ARM-platforms!?)
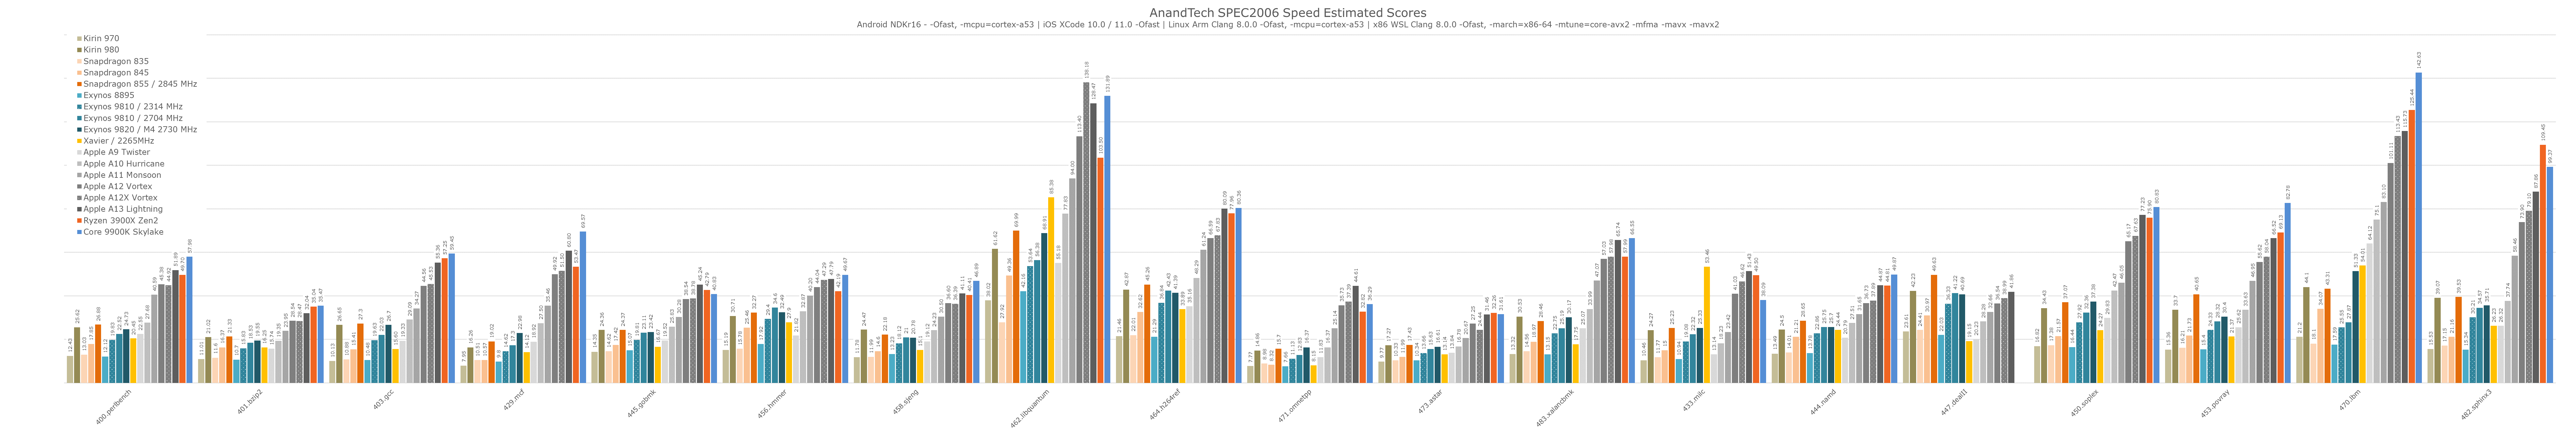
EDITEDIT: it's even worse for SPECfp2006: https://www.spec.org/cpu2006/results/res2016q1/cpu2006-20160... [well, here the old 6700K suddenly sometimes is twice as fast as the 9900K and 3x as fast as the A13 (and yeah the story of the 2.8GHz-low-power-chip drawing circles around a 4.5GHz-HF-part just didn't sound convincing in the first place...)]

Re:Apple announces it will switch to its own processors for ... by Veedrac on Monday June 22, 2020 @09:08PM (#23608899)
The official results from spec.org have a bunch of cheating, eg. exploiting undefined behaviour to run a benchmark improperly. AnandTech uses a consistent compiler (Clang, not ICC) without settings to exploit this, hence the divergence.

Andrei mentions this here: https://www.realworldtech.com/forum/?threadid=187314&curpost...

Re:Apple announces it will switch to its own processors for ... by KMag on Tuesday June 23, 2020 @02:30AM (#23610516)
When I started at Google, I sat next to a guy who used to write compilers for DEC and Intel. I asked him, given the huge amount Google spends on hardware and electricity, if he thought that switching to ICC was worth while. His answer was basically that ICC is tuned to maximally exploit undefined behavior for marketing purposes and he wouldn't want to use it in production, at least without heavily tweaking flags to disable some optimizations. ICC gets most of its speed advantages by enabling optimizations that are present in GCC/Clang, but deemed too dangerous to turn on by default.
Re:Apple announces it will switch to its own processors for ... by fock on Tuesday June 23, 2020 @03:17AM (#23610789)
clang with "-Ofast"; I really wonder, which other options are there?! And imho this just doesn't explain the 200% difference?

And some other things which are bugging me:

- can you only optimize for A53 on Android with the big.LITTLE-configurations (they do!)?

- so they cross-compiled an AMD64-producing gcc 3.2 with Xcode 10 on MacOS-X for ARM? impressive.