News for hackers. Stuff that matters.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by 0xbadcafebee on Wednesday June 03, 2026 @05:10PM (#48390110)
It was almost certainly not trained for coding, as it's got both audio and vision input, is only 12B, and nowhere in the announcement is coding mentioned. It will likely not have good performance on coding in general, compared to other small models like Qwen 3.6 35B A3B, Gemma 4 26B A4B, Nvidia Nemotron 3 Nano 30B-A3B, gpt-oss-20b.

For 16GB laptops, Qwen 3.5 9B is the undisputed champ.

Gemma 4 31B is the top dog at small model coding, but is dense so it needs ~48GB unified RAM for full context. If you want decent coding on a laptop you need a lot of RAM. But this shouldn't be surprising, dev machines have always needed lots of resources.

Re:Gemma 4 12B: A unified, encoder-free multimodal model by dotancohen on Wednesday June 03, 2026 @07:34PM (#48391585)

  > For 16GB laptops, Qwen 3.5 9B is the undisputed champ.
You seem like the guy to ask. For a laptop with 12GB VRAM (RTX 5070) and 32 GB system RAM, what is a good multilingual (English, Hebrew, Greek) model for conversing with personal notes in Org mode format? I don't care how long updating the model or rag takes, and even inference can be reasonably slow, but the results of the query as they relate to my personal notes are important. I don't care about general knowledge, for those questions I can use e.g. ChatGPT.

Thanks

Re:Gemma 4 12B: A unified, encoder-free multimodal model by sourcecodeplz on Wednesday June 03, 2026 @10:21PM (#48392869)
Any Gemma 4 model, they are great at translations, multilingual
Re:Gemma 4 12B: A unified, encoder-free multimodal model by silversmith on Thursday June 04, 2026 @01:26AM (#48394350)
For the biggest languages, Spanish, French, maybe.

For smaller ones like my native Latvian, the output could be confused for good translation from across the room, the words do look like Latvian words. But the quality is Google translate circa 20 years ago, tops.

It could probably do a decent enough translation to English, if all you need is to get the gist of text. But for smaller European language outputs, nothing comes close to Gemini.

Re:Gemma 4 12B: A unified, encoder-free multimodal model by dotancohen on Thursday June 04, 2026 @04:24AM (#48395771)
While Gemini 4 seems fine, Gemma 4 does not do Hebrew well. I've replaced it with Aya Expanse and am getting much better results, but there is still much improvement to be had.

I'm not doing translations, rather querying Hebrew text with a Hebrew prompt.

Re:Gemma 4 12B: A unified, encoder-free multimodal model by emmelaich on Wednesday June 03, 2026 @11:03PM (#48393181)
You may like https://www.llmfit.org/

(not recommendation, I've not used it .. yet)

Re:Gemma 4 12B: A unified, encoder-free multimodal model by hypfer on Thursday June 04, 2026 @04:06AM (#48395644)
Just tried it and honestly it's a terrible experience lacking any sort of intent or reason.

Which is unsurprising in the AI space.

You get a wall of text showing you various random fine-tuned models by random people, and that is basically it.

Actual sane default requirements like "just give me the normal AI labs", "please filter for dense only" and "I want this exact context size at this quant" are not part of the tool, apparently. Neither is "compare these quants for me for the same model".

Or maybe it's just hidden enough that I did not find them before I've stopped caring.

Conway's law is at it again.

Re:Gemma 4 12B: A unified, encoder-free multimodal model by hparadiz on Thursday June 04, 2026 @06:27AM (#48396604)
We need benchmarks by engine, cli switch sets, and device with filters by cpu, gpu, and type. And if someone could please aggregate that in a way where people can upload results and just automatically see the best of any model for their device that would be a killer app.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by alfiedotwtf on Thursday June 04, 2026 @07:05AM (#48396929)
I've wanted to vibe code a tuning app, that pumps data through your CPU-GPU-RAM to try and determine the best parameters for each model, but I think it's just too much work compared to manually running by hand a one-liner and changing things here and there.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by hypfer on Thursday June 04, 2026 @09:55AM (#48398705)
Re:Gemma 4 12B: A unified, encoder-free multimodal model by dofm on Thursday June 04, 2026 @10:32AM (#48399270)
I have found these things to be fully exasperating, to be honest, even though I am seeking information about a pretty "known" machine — a 64GB M1 Max MBP.

(Honestly I think Apple's "AI push" could do worse than just focus on a curated model library, a couple of Apple-standard Gemini distillations, an OS-level model manager and some sort of tweak of their containers system to do what Docker's sbx does. They could demystify a lot of this shit.)

Re:Gemma 4 12B: A unified, encoder-free multimodal model by tacomagick on Thursday June 04, 2026 @01:09AM (#48394196)
Gemma 4 26A4B
Re:Gemma 4 12B: A unified, encoder-free multimodal model by akmarinov on Thursday June 04, 2026 @01:14AM (#48394236)
Joins us over on Reddit at r/LocalLlaMA to get 10 different opinions on that
Re:Gemma 4 12B: A unified, encoder-free multimodal model by spacebacon on Thursday June 04, 2026 @03:08AM (#48395144)
People can post on reddit without being downvoted and deleted? I had no idea.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by dotancohen on Thursday June 04, 2026 @05:51AM (#48396337)
I read there regularly. I find little value there between the memes. I was hoping to ask a knowledgeable person here.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by alfiedotwtf on Thursday June 04, 2026 @07:03AM (#48396911)
/r/localllama for a while now seems to prefer Gemma 4 E4B for creative writing (especially the uncensored GGUFs).
Re:Gemma 4 12B: A unified, encoder-free multimodal model by plagiarist on Thursday June 04, 2026 @02:23PM (#48402587)
Do they prefer E4B over the larger models or is it a matter of what fits their machine? I assume 4B isn't large enough to get interesting writing but I don't know anything about it.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by KludgeShySir on Friday June 05, 2026 @02:14PM (#48416202)
Gemma4-31b seems to be very highly regarded for creative writing, especially its finetunes. As for comparison to E4B, I can't say.

Creative writing is not my focus, so this is only secondhand information. r/LocalLlama tends to focus more on the technical side; if you want more creative side check out r/SillyTavern as well (but type of info does bleed over between them).

Re:Gemma 4 12B: A unified, encoder-free multimodal model by nl on Thursday June 04, 2026 @07:32AM (#48397170)
Qwen 3.5 35B A3

Qwen models are always good. The 35B A3 model is a MoE model which means it has higher performance in RAM constrained environments compared to the 27B dense model (which is better at coding).

I don't have experience to rate it's Hebrew or Greek performance but apparently it's not bad.

Re:Gemma 4 12B: A unified, encoder-free multimodal model by kajecounterhack on Wednesday June 03, 2026 @05:48PM (#48390606)
Have you found Gemma 4 31B better than Qwen 3.6 27B Q8? I just started using Qwen + Pi agent and it's great, but "which model works best" is still totally crowdsourced and I was going off of peoples' opinions on reddit. Would love to hear more opinions if people have them.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by embedding-shape on Wednesday June 03, 2026 @06:37PM (#48391079)
> Have you found Gemma 4 31B better than Qwen 3.6 27B Q8?

Which quant of Gemma? For coding Qwen seems to be pretty far ahead, but generally Gemma seems to have a "vaster" set of knowledge, but armed with a search tool it doesn't really matter, and Qwen 3.6 been really great for all sorts of tool calling. I mostly do programming and related things though, fwiw.

> I was going off of peoples' opinions on reddit

It's extremely astroturfed all over the place, especially the larger subreddits, and especially the one related to a specific animal in a specific location. It's sad, as early on it was a great resource, but now it's mostly paid posts and a race to the bottom, with lots of piling, and all the knowledgeable people I used to recognize are nowhere to be found.

Re:Gemma 4 12B: A unified, encoder-free multimodal model by xenophonf on Wednesday June 03, 2026 @07:06PM (#48391311)
It took me way too long to realize you were referring to r/localllama.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by MoonWalk on Wednesday June 03, 2026 @07:41PM (#48391651)
Why the obfuscation in the first place?
Re:Gemma 4 12B: A unified, encoder-free multimodal model by zozbot234 on Wednesday June 03, 2026 @08:10PM (#48391934)
I'm not sure that GP is correct, many people in that forum tend to hate Qwen for closing up many of their more recent models and leaving the whole local inference community 'stranded' on their older releases.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by kajecounterhack on Thursday June 04, 2026 @12:08AM (#48393684)
That was definitely not the subreddit where I got my info.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by julianlam on Thursday June 04, 2026 @12:34AM (#48393908)
Are you sure? Prior to today the sub seems to be pretty partial to Qwen.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by embedding-shape on Thursday June 04, 2026 @06:24AM (#48396572)
Just a bit of flair. Also, bunch of people have "keyword watchers" setup for various terms, so when you mention certain things on HN, reddit and elsewhere, you get commentators who enter the conversation not because the context or larger conversation, but because the single term/thing they care deeply about was mentioned, and it just gets very boring to read the whole attackers/defenders comments over and over again. But ultimately I just did it like that because it was more fun to write it like that.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by MoonWalk on Monday June 08, 2026 @12:56PM (#48447872)
But it renders the comment baffling to those who have never heard of that forum. I'm on here and Reddit quite a bit, and never heard of it.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by thangalin on Wednesday June 03, 2026 @06:35PM (#48391069)
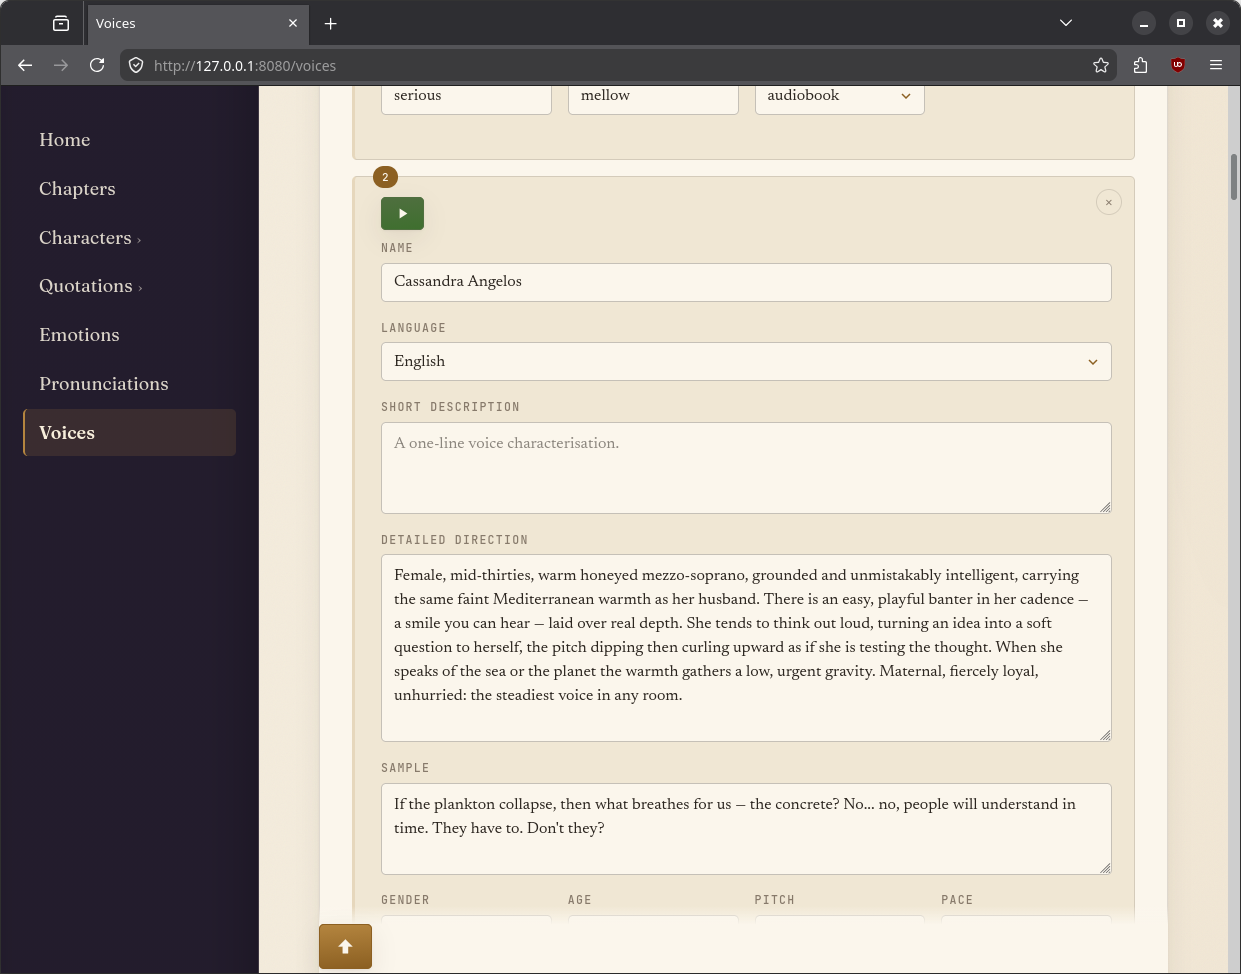
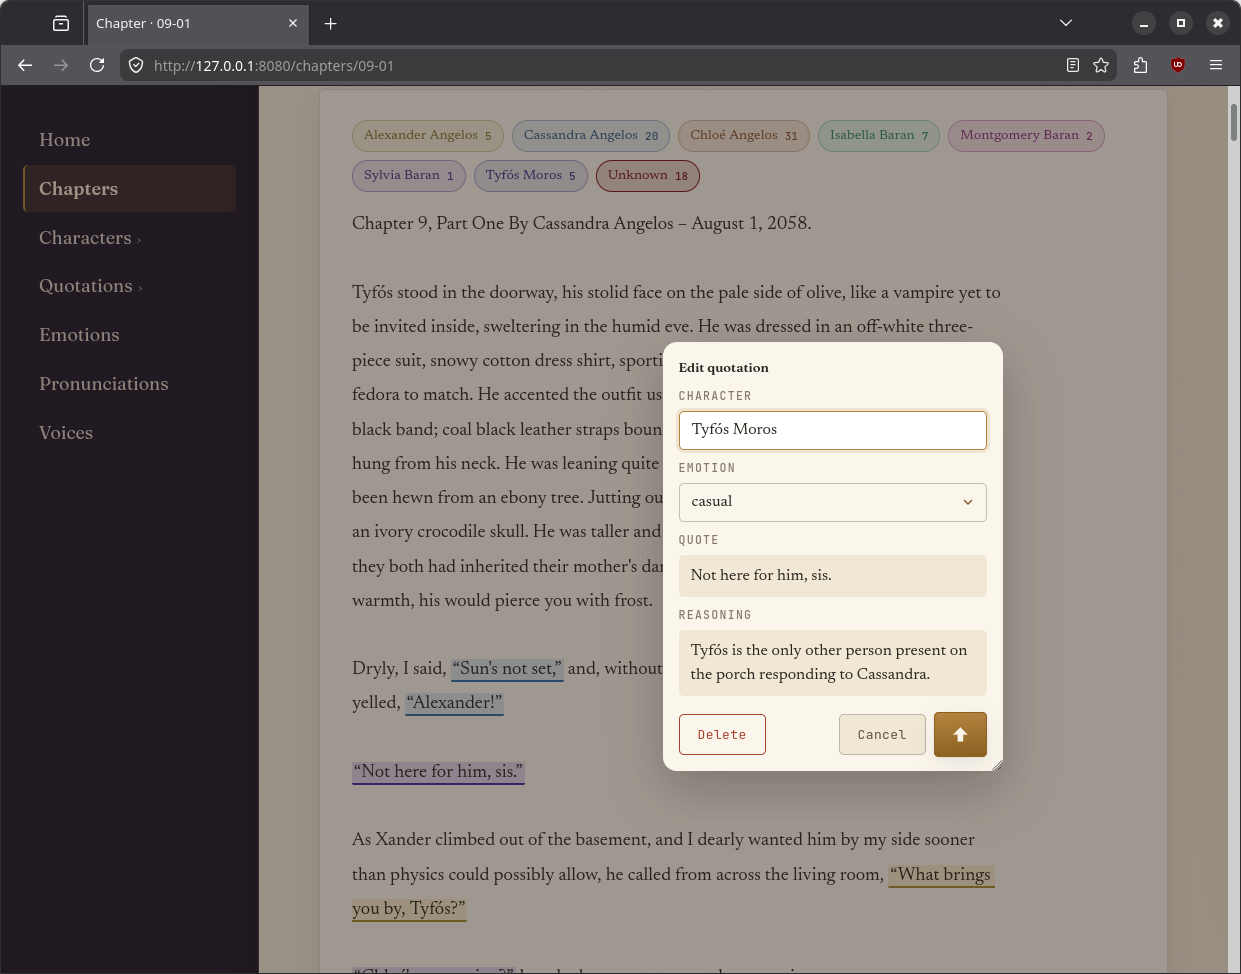
Yes. I'm using Gemma-4 31B (gemma-4-31B-it-assistant.Q4_K_M.gguf) with llama.cpp to attribute quotations throughout chapters of my sci-fi novel. I started with Qwen3, but couldn't get it to work. Qwen3 TTS Voice Design, on the other hand, is incredible (Qwen3-TTS-12Hz-1.7B-VoiceDesign). I'm using both for an audiobook generator that produces a novel in a variety of voices.

Screens:

* https://i.ibb.co/TBBV5nJk/kl-01.png (voice design)
* https://i.ibb.co/nNvvKDyV/kl-02.png (quotation attributions)
Re:Gemma 4 12B: A unified, encoder-free multimodal model by khimaros on Thursday June 04, 2026 @01:55PM (#48402168)
building something similar: https://github.com/khimaros/autiobook
Re:Gemma 4 12B: A unified, encoder-free multimodal model by qingcharles on Thursday June 04, 2026 @02:36AM (#48394876)
Gemma 4 31B is enormously impressive. You get 1000 requests/day for free on Google's API and another 1000/day off OpenRouter. Only problem is you get 503 like crazy.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by senko on Wednesday June 03, 2026 @05:45PM (#48390570)
Yeah, I agree 24B-36B sizes are better in general.

I don't have unified RAM tho and offloading to CPU is dog slow, which is why I'm interested in 7b-12b models.

Re:Gemma 4 12B: A unified, encoder-free multimodal model by iso1631 on Wednesday June 03, 2026 @07:48PM (#48391722)
I find ram crazy. My thinkpad has 32G of ram, it's a t470 that's nearly a decade old

Why do people with modern laptops have such little amounts of ram?

Re:Gemma 4 12B: A unified, encoder-free multimodal model by doubled112 on Wednesday June 03, 2026 @08:28PM (#48392089)
My job still issues 16GB laptops as standard. You need a business reason to get more. This has been going on since before the price hikes.

I’m a system administrator and I can do my job with no issues at 16GB. Most days 8GB would likely be enough, since I’m just using and abusing other systems anyway.

Java devs at my last job were still running 16GB in 2020. Admittedly that was a while ago. Still not a decade.

Close some Chrome tabs?

Re:Gemma 4 12B: A unified, encoder-free multimodal model by willy_k on Wednesday June 03, 2026 @08:28PM (#48392096)
The ram that’s important for LLMs is gpu-accessible memory, meaning either systems with unified ram or VRAM, the latter of which is tied to the caliber of GPU one has.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by SturgeonsLaw on Thursday June 04, 2026 @05:36AM (#48396246)
Unified memory is soldered to the motherboard and needs to be ordered with the new laptop, for prices that are well above what the equivalent amount of SODIMM would cost.

Fine if work's paying, but for personal devices (that might have been purchased before local models got good), people have what they have.

Re:Gemma 4 12B: A unified, encoder-free multimodal model by AshleyGrant on Friday June 05, 2026 @01:57PM (#48415995)
It doesn't have to be soldered to the motherboard. I've got a Minisforum PC that has unified memory installed via dual SODIMM slots. I put 64 gigs of DDR5 sticks that cost me over $600 and can determine the split between the system and VRAM in the BIOS.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by alfiedotwtf on Thursday June 04, 2026 @07:08AM (#48396954)
8Gb was the standard for a long time (before Apple went Silicon), because from what I understood, is that SDRAM needs to contantly power cycle the memory bus otherwise the bits will fade, and so by having more RAM, your battery would last a little less... this was around the time when 3 hours charge was unheard of, so every little bit helped.

Probably doesn't matter these days with all-day batterys, but now the demand-supply curve is lopsided.

Re:Gemma 4 12B: A unified, encoder-free multimodal model by jmpeax on Wednesday June 03, 2026 @10:26PM (#48392909)
> nowhere in the announcement is coding mentioned

It's right there in the middle benchmark bar "LiveCode Bench" 72%.

Re:Gemma 4 12B: A unified, encoder-free multimodal model by dirkg on Thursday June 04, 2026 @01:25AM (#48394339)
> For 16GB laptops, Qwen 3.5 9B is the undisputed champ.

you can run qwen 3.6 35BA3B on a 12-16GB vram gpu and ot works pretty well.

https://www.youtube.com/watch?v=8F_5pdcD3HY&t=1s

even the 27B in some quants can fit.

https://www.reddit.com/r/LocalLLaMA/comments/1tkmgwj/qwen27b...

qwen IMO is far better for coding, esp agentic coding when combined with something like Pi, it comes probably close enough to Sonnet for a lot of use cases.

Gemma family is better for almost all other tasks you'd use a local llm for.

Re:Gemma 4 12B: A unified, encoder-free multimodal model by ricardobayes on Thursday June 04, 2026 @09:28AM (#48398354)
You can run it, however those low quantized models (iQ2, iQ4, Q2) will very likely underperform the 9B versions at Q6/Q8.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by kanemcgrath on Thursday June 04, 2026 @05:33PM (#48404921)
Something about qwen models hold up really well even at low quants. for most other models anything under q5 is cooked, but on 35B-A3B I can get a lot of things done even at q3_xl. It is definitely better than full precision 9B
Re:Gemma 4 12B: A unified, encoder-free multimodal model by dofm on Thursday June 04, 2026 @10:29AM (#48399213)
The larger Gemma models are quite good at PHP. I would not be surprised if that was a training objective — it's one of the more consumer-focussed programming languages. They have very good knowledge of wordpress hooks.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by selicos on Thursday June 04, 2026 @12:29PM (#48400980)
I want to try a hybrid setup of Gemma 4 E4B with lots of context for general, then Qwen 3.5 9B or larger for coding. Strix Halo set up this weekend, which may enable even larger Qwen models with tons of context.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by ricardobayes on Thursday June 04, 2026 @09:23AM (#48398291)
Qwen 3.5 9B is great for coding, but somehow, based on a few hours of subjetive tests, the Gemma 4 12B seems even better.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by mark_l_watson on Friday June 05, 2026 @09:05AM (#48411933)
I had odd Gemma 4 12B results: it was ‘almost excellent’ for writing code in a variety of languages if I was using a detailed one-shot prompt describing new code to write.

I had horrible luck with Gemma 4 12B with a variety of coding harnesses - but as usual Qwen 3.5 9B did OK.

EDIT: CORRECTION: I pulled a fresh copy of Gemma 4 12B and inference code and the tool use problems in my test harnesses are fixed. Gemma 4 12B is slow on my 16B MacBook Air, put produces OK results.

Re:Gemma 4 12B: A unified, encoder-free multimodal model by dofm on Thursday June 04, 2026 @10:27AM (#48399183)
It does appear to have training for javascript and PHP, from what I can see, and pretty solid knowledge of wordpress and woocommerce. I would guess it has beginner-friendly knowledge of Python, too?

(Though it is gaslighting me about PHP anonymous functions.)

I would not use it to write code (the MoE 26B writes really good PHP), but it appears to have absolutely good enough knowledge to write implementation plans, and I think that could be useful in a sort of agentic coding tutorial environment.

I test these models with simple things. My favourite mini test is asking an AI to write a "last login" tracker facility for wordpress with a sortable admin column, which is trivial code — only a few lines -- but touches on a reasonably deep bit of the WP API. If you ask it to prompt you with clarifying questions, those questions are quite revealing.

It can write the code. Not tested it but I am sure it works. It's not as elegant.

It is not as good at understanding nuanced instructions as either the 26B or the sparse Qwen 3.6. There are concise things you can say in a prompt to Qwen 3.6 that have it draw logical conclusions that fully impress me.

I am more impressed by it than I expected. I reckon this would be quite useful in a tutorial tool.

(I say this as a sort of qualified cynic; I think much of the AI circus is a farce. But if these things are to ever be useful for teaching without making people dependent on some cloud "intelligence tap", this is progress)

Re:Gemma 4 12B: A unified, encoder-free multimodal model by sgt101 on Thursday June 04, 2026 @03:46PM (#48403691)
31B won't run in 48GB for me - it needs 54.
Re:Gemma 4 12B: A unified, encoder-free multimodal model by yassa9 on Thursday June 04, 2026 @04:51PM (#48404456)
what quantization did u try ? u can use Q4 quantization, im pretty sure that 48GB would be enough
Re:Gemma 4 12B: A unified, encoder-free multimodal model by sgt101 on Saturday June 06, 2026 @03:05AM (#48422220)
8bits is fine.... I was talking full bore.