I don’t think that’s the article was trying to say that AI is inherently racist or inherently is causing people to be racist, it’s that AI is still seeing as authoritative. If you just ask AI show me a picture of someone from a specific culture ask and it shows very stereotypical result, I wouldn’t call the AI result. Racist what I would say is the problem is that the person viewing this might except that this is an authoritative answer this is what progrsmmers and maths have shown is undoubtably, a true accurate representation of a person from such a culture, and the end-user is no more aware how this picture was formed, or whether or not the AI considers to be a stereotypical representation
I think the focus on the Barbies around the world from AI generation was a good example as it does. Kind of show some very strange interpretations of different cultures. Now granted we need to take this with a grain of salt because we don’t know the queries we don’t know the exact models and stuff like that but that’s not really the point the point is more that AI in person to use AI frequently treat the AI output as authoritative. There is no indication if the AI maybe it wasn’t able to get a good idea of what your request was if they maybe had a lack of confidence in what they are responding, you just get a results and it seems with all the white papers and with the buzz around AI that it’s an authoritative result
I am not a stranger to using AI to assist with tasks, something like a quickly converting from one syntax to another, is something I do on a fairly regular basis the difference, however, between using AI like that, and using it as an authoritative source is that I would check the queries or the code that’s produced by the AI. I would not accept it blindly. I will double check and make sure since at some point I need to run this code in real environments. I think that is what the article was trying to say is that AI is very cool and I can do some very cool things but if you’re not understanding how it’s doing what it’s doing and not checking it output and trusting the AI blindly that is where it has a problem. And I would agree with the article if this is what I’m trying to say,
I don’t think it’s so much about moderating speech or anything like that, not that it must not produce certain outputs; It’s more long lines of there is simply too much implicit trust in how AI works in the output that AI produces. And I would agree with the article if this is what I’m trying to say, I don’t think it’s so much about curtailing speech or anything like that or that so must must not produce certain outputs. It’s more along the lines of people’s Trust in how AI works and in the output that it gives and s stereotypes users are probably giving it bad inputs to produce these outputs, which are quite stereotypical and very often incorrect.
I think, showing more about how the AI understood the prompt and how the output was produced, such as sources, or may be certain key words and examples of images, that the AI associate with his key words would help the users to understand why they are getting this out put and also it would help them understand may be watch the words they use in their props are associated with, and maybe understand a bit more about why their innocent understanding of their problems or questions may be is not as innocent as they thought originally. It doesn’t have to lecture them. It simply needs a show “X is associated with Y in this model and that’s produced Z” and let the users draw their own conclusions.
A more sensible response would perhaps invent additional requirements to get more interesting and more varied outcomes. The right amount of variance depends on the context, but it's rarely as low as the current interfaces default to.
I wanted a photo of an average-looking older woman and it was unbelievably hard to get it to produce that. And even after some very detailed, emphatic prompts the results still weren't as good as generic stock photo - never mind someone you might see in the real world.
SD believes most women are in their 20s and have big boobs. It's comically obvious if you try to get any fantasy art out of it and you want something that isn't big-boobed porn.
It's a content problem, not a prompt problem. It's been modified since to make it less porn-y but it's still a very long way from supporting straightforward prompt access to the face and body space most humans live in.
So it's a fair criticism to say it's stereotyping. Most of what comes out of it is a white middle class male's idea of what [thing] looks like.
This is inevitable with small training sets. AI is basically data compression. But the lack of awareness that the output comes from a lumpy dumbed down version of the training space is worrying.
It's textbook worse-is-better - narrowing experience and possibility towards flawed mediocrity, with the firm implication no one should have higher expectations. Because that's as good as it gets, and it's fine.
You means the community-made checkpoint.
ITT people complaining about stereotypes while stereotyping.
For example: trying to get chatgpt to write about psychotic post-partum symptoms, getting stable diffusion to produce a realistic looking woman above the age of 50, or writing an immigration narrative that isn't "home country bad, new country better".
I think the deeper problem is that it only writes happy endings.
A while back someone pointed out that Dracula, Sherlock Holmes, and Winnie the Pooh had all become public domain characters on the same day, so I tried asking it for a story that combined them — it read like I expected it to (a terrible premise written with middling skill), but it also insisted on wrapping everything up with a twee "and then all three of them went on more jolly adventures" kind of ending.
Likewise the time I asked it for one about alien invaders, where it wrote them turning (without good reason) from villains into friends at the end.
"Give it a surprising, dark ending" or "add a twist".
The majority of stories people tell have happy endings, so it's not surprising that it defaults to those twee resolutions.
This was my experience too with NightCafé models. Once I wanted to refine a model to do a detail differently, but even with exaggerated weighting I was not successful.
The models are fed with stereotypes, so they don't know to spit out something not a stereotype.
You also need consistently labelled data so that the model can have a chance to learn the differences properly.
I've also seen the image models not understand context, so if you ask for e.g. "green eyes" then it will often place the image in grass/a green background, select green clothes, etc. -- i.e. it is only learning the association of the colour and not the association to a particular facial feature.
The image models are very bad at feature shifting and not understanding how features combine -- resulting in things like multiple arms because two of the images it is splicing have the arms in different positions.
For instance, SDXL produces very different results when you expand your prompt vocabulary even marginally. Pairing prompts with Hindu, Sikh, desi, Telegu, Brahmins, North/South, Kerala, country/city, etc provides detailed and diverse results, and that's all pretty generic. It also recognizes clothing styles and types, food, holidays and events, and it even generates recognizable background details and architectural styles with regional prompts. Also, to their example, "Jollof rice" beats prompting "Nigerian food" if you expect to see jollof rice.
I plug this to artists who also teach, but this is a great way to show the tremendous value of the arts and art history. Start tagging for training, make better datasets, and license them. People think they're slick because they know how to prompt "cool picture, in the style of $artist", but most of the world doesn't know what filigree, sfumato, or Rococo are. Guess who does? Their art students.
> “A Mexican person” is usually a man in a sombrero.
They are asking for an image of a Mexican person.
If the result shows an infant, or a person in a business attire in front of a glass building, or a construction worker, or someone competing in a bike race, how would we know they're "Mexican"?
Exactly. Even more so, they're asking for an image that is likely to be described as depicting a Mexican person. It should be obvious why, without additional detail in the prompt, the model will reach for features that'll make it obvious the person is a Mexican to a viewer with no other context - hence exaggerated stereotypes.
Artists do that too, all the time, if they want to communicate nationality in a "show, don't tell" way, and there is no other indicator in the image (such as location, or overall topic of the work).
Quite a bit of variety there, looks pretty mexican to me!
Generative AI images are "plausible description generators" with a human in the loop.
They aren't trying to draw something, they're trying to get you to call what they draw something.
Given a prompt from a human, they produce an image likely to be labeled as such by a human.
"Well sure that's a Mexican person but I meant..." is not a valid caption.
That is, what they say. If you ask midjourney for the image of a Mexican man it produces this cliche. Most Mexicans don't look like that. Most will be closed to the Mexican in a suit.
I think, the result would be more diverse if you look for stick photos of Mexicab men.
This example only shows, what you can expect from every other prompt: a bias for cliches.
And yes, you are right: that is, what you ask for in Midjourney.
But you should know, that it's always a cliche.
By definition this is true of any group. Most people do not look alike. There’s no way to have a single picture of what “most Mexicans” look like.
If you asked an AI image generator for "a Mexican" and got back someone competing in a bike race, do you need to know that the person in the image is Mexican? Do you need to verify by doing a visual check for stereotypical features?
Or would it be good enough for you to just believe that the AI gave you "a Mexican" and hence accept the image as a valid answer to your prompt?
Would you? That's pretty boring: Given the vagueness of the prompt, you're actually free to paint anyone, from Kumari Mayawati to Satya Nadella.
Not doing "the obvious", whether that's a harmful stereotype or just a tired trope, is part of what makes art art. But from the images, of which there are hundreds, all of them extremely similar, I wouldn't think "an Indian person". I'd think something far more specific: an old bearded Indian man wearing a turban. Which is sort of the article's point.
Interestingly, trying the same prompt in my local installation of Stable Diffusion, I got quite a lot more variety in terms of age and sex (though I couldn't really escape turbans and bindis). So this actually seems fixable even for very vague prompts, despite the implication of your comment that the problem is with the user.
If I were to be honest, yes. There would probably be a lot more diversity in my paintings than demonstrated in the article, but ultimately my experience would be limited to what I see in the immigrant community, popular culture, and the news. For the most part, those are very narrow slices of Indian society. More important, it will reflect what I see most often in those categories and is unlikely to reflect facets I rarely see.
If anything, AI art could probably do better than I when properly prompted. One could choose someone who would is likely to exist (a farmer in India or a university student in India) and the model would likely have some "idea" of what they look like. Perhaps a language model can massage vague prompts to create more specific and representative ones automatically, to further reduce individual bias. (I say reduce because it's ultimately limited to the data that has been fed to it, but it should have a broader scope than an individual person has.)
this would be a valid point if the person doing the painting was of sufficient artistic ability that they could paint a picture of a specific Indian person and have it be recognizable, if they knew what specific Indian person would be recognized by the person requesting they drawn an Indian person.
If you commission someone to paint "an Indian person", would you withhold payment if they painted a specific Indian person, or an Indian person not in traditional dress? (And, to be clear, Midjourney is certainly capable of doing this recognisably). Hopefully you would instead be happy with the result, because it would be what you asked for -- if you specifically wanted a "stereotypical Indian person" you would have asked for that instead. "Be recognised by the largest amount of people" is not typically the goal of an artistic work. Is it the goal of Midjourney? Well, to the extent that it is, that's the problem that the article is pointing out: if you attempt to cater to everyone, you will necessarily produce a picture which is at best conventional and at worst extremely stereotypical.
A few seconds of playing around with Stable Diffusion shows that this need not be the case, so the article actually points out a specific deficiency of Midjourney.
let me re-emphasize
>you're
the abbreviation you are is evidently in reference to a person, a person free to paint anyone. Specifically you asked the previous person if THEY would paint a stereotype if asked to paint an Indian.
If I am free to paint anyone when asked to paint an Indian I will never paint a specific Indian and always attempt to paint a stereotype because my personal painting skills are not good enough to paint any specific Indian and have them be recognizable by anyone.
I assume the abilities of Stable Diffusion and Midjourney are actually good enough to paint a specific Indian, their abilities are definitely greater than mine when it comes to 'painting'.
For some reason you decided my response had something to do with Stable Diffusion and Midjourney from an engineer's perspective, rather than the specific subject of what a human would do if given the same prompt.
I don't know why you would make this mistake, maybe the response demonstrates the tendency of engineers to misunderstand the meaning of simple texts if they do not match up to their preconceptions?
If you told an actual artist to draw 5 pictures of Indian people, I doubt you'd get 5 old men with Turban and beard. Most people understand that reality is more varied than this.
This reminds me of a paper my former coworker wrote about how Google Translate, a couple years ago, would misapply gender stereotypes to gendered nouns in a way that humans wouldn't. The world "table" translates to German as "Tisch" (where you eat; masculine) or as "Tabelle" (in a spreadsheet; feminine). It turned out that when accompanied by an adjective stereotypically associated with masculinity (e.g. "strong"), the system would translate "table" as "Tisch", but in the presence of a stereotypically feminine adjective (like "soft"), it would pick "Tabelle". This is ridiculous, no human translator (not even the most sexist) would do that, as we understand that grammatical gender isn't biological or sociological gender. But the AI system somehow can't say "I don't know what the translation is, it's ambiguous" and so it just makes up a pattern where there should be none.
You have to keep in mind that with these models, it's not like asking an artist to draw 5 pictures of something - it's like asking 5 different artists, who don't know about each other, to each draw a single picture of something.
Generated images are independent, there's no system there to notice it's generating multiple images from one prompt, and thus might want to ensure they're not too similar. I hear OpenAI is hacking around this with DALL-E 3 by having the prompt preprocessor (GPT-4 expanding your prompt) inject stuff like "diverse people" many times in the expanded prompt, to bias things the other way.
I just asked GPT-4 for images of an Indian man, and it created four separate prompts to pass to Dall-E.
  1. Photo of an Indian man wearing traditional attire, standing against a scenic backdrop with a serene expression.
  2. Oil painting of an Indian man in a kurta, playing a sitar under a banyan tree.
  3. Illustration of an Indian man in modern clothing, holding a cup of chai while reading a newspaper in a bustling city.
  4. Watercolor painting of an Indian man practicing yoga in a tranquil setting near a river.
  1. Photo of three Indian men from different regions, each wearing distinct traditional attire, standing side by side in a vibrant market setting. (The resulting image literally looks like triplets in different attire)
  2. Photo of a group of Indian men from various descents, engaging in a conversation at a local tea stall.
  3. Photo of young and elderly Indian men, representing diverse backgrounds, enjoying a game of chess in a park.
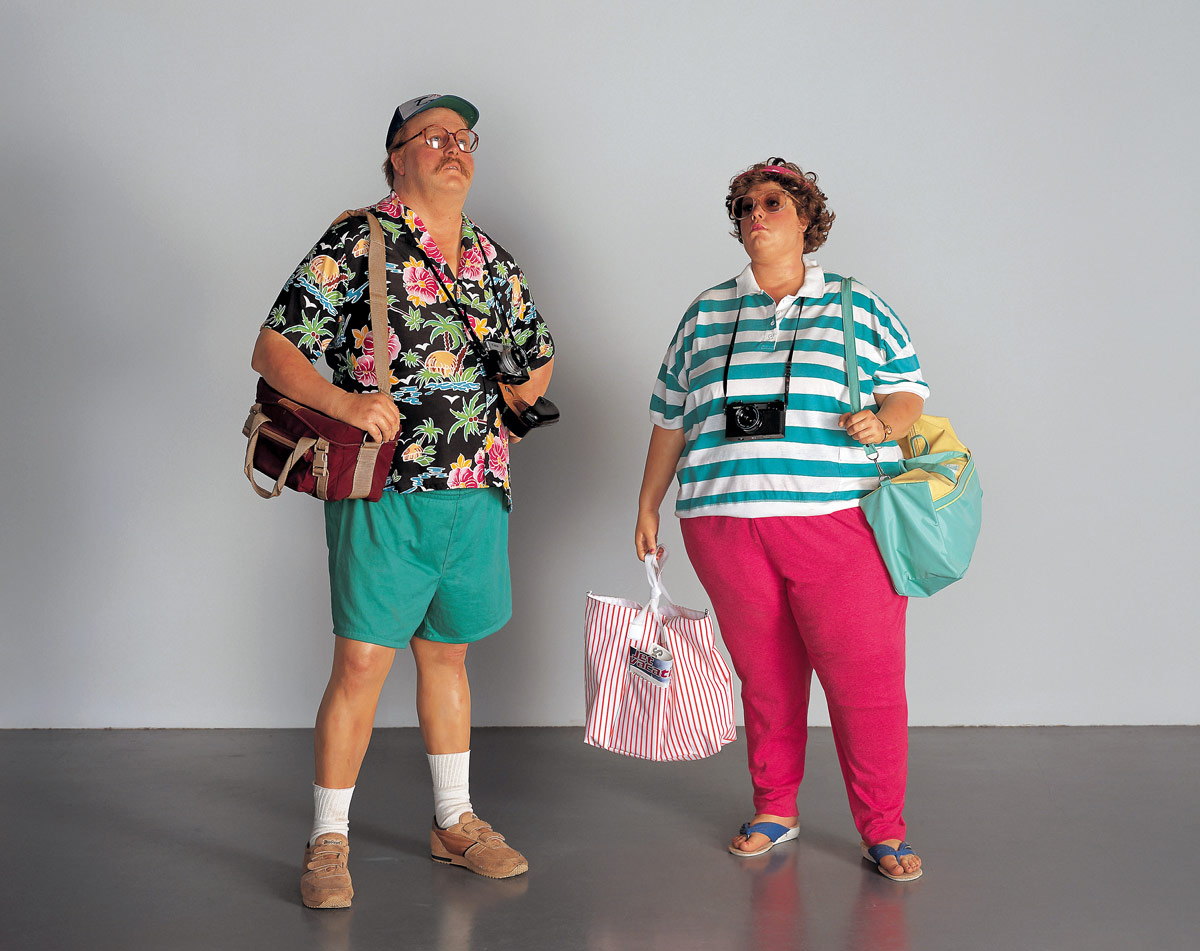
4. Photo of Indian men of diverse ages and regions participating in a traditional dance ceremony. (This one was funny. It was a bunch of Indian men sitting with their legs crossed with one Indian man in a cross legged position floating above all the rest)(This would be a better fit: https://artblart.files.wordpress.com/2011/01/duane-hanson-to... )
"Nigeria is home to more than 300 different ethnic groups"
Followed by this:
"But you wouldn’t know this from a simple search for “a Nigerian person” on Midjourney"
So they literally asked for a generic Nigerian person instead of specifying something like a Yoruba Nigerian and complain they got a generic Nigerian person? If the model isn't trained with explicitly labeled Yoruba Nigerians, that's a training problem.
No matter how granular you get with specific ethnic groups, it’s not possible to capture the long tail of all the types of people who exist, and all of their appearances.
If you ask Midjourney to draw a man, should he be wearing clothes? A man might be naked. Should he have two arms and two legs? Some men don’t. What about two eyes? What color skin should he have?
The fact that Midjourney will never draw a third degree burn victim when simply asked to draw “a man” isn’t a flaw in the model. The model is biased, yes, but it is biased towards utility.
For me, the salient observation is the complete lack of any kind of creativity or anything approximating imagination, of those models, despite a constant barrage of opinions to the contrary. Yes, if you asked me to draw you "a mexican man" (not "person") I'd start with a somberro, moustache, a poncho, maybe a donkey if I was going for a Lucky Luke kind of vibe. But if you asked 100 people to draw "a mexican man" and it turned out they all converged on the same few elements you'd nevertheless have 100 clearly, unambiguously different images of the same kind of "mexican man", often with the same trappings, but each with a clearly distinct style.
It is this complete lack of variance, this flattening of detail into a homogeneous soup, that is the most notable characteristic, and limitation, of these models.
And yet when hands came back with beautiful variations in finger count, people were unhappy.
Inside cities, no one is specifically looking for a member of their own tribe to marry so the ability to identify ethnic groups by facial features is collapsing.
Offspring tends to go in one direction or another so one group may end up inbred, but a mix is more accurate than compiling the beliefs of human cultures about their genetic traits and isolation from each other.
If you'd ask me to paint an Indian person, of course I'd paint a stereotype to make sure it looks Indian, and not some normal person from India that could be from anywhere.
Or like imagine playing one of those games where you're supposed to guess the prompt of what your friend is drawing. This is sort of like that, isn't it? The AI is creating an image that would have you look at it and think "an Indian person", not just "a person".