It's a little more nuanced than that. Compression may cause information leaks or it can prevent them depending on the circumstances. If you're encrypting an audio stream, then compressing it first can cause leaks. If you're encrypting a document, then compressing it first may prevent leaks.
Therefore, I feel like compression complicates the discussion unnecessarily. Information that's not encrypted (the time a key was typed or the spacing between phonemes in a word) can be recovered by an attacker without breaking the encryption. Obvious when you say it like that ;)
An interesting paper on using padding to obscure length: http://cihangir.forgottenlance.com/papers/lengthhiding-corre...
As for compress. My understanding is that the inscurity has nothing much to do with timing, and everything to do with giving an attacker some "known" plaintext they can use Bayesian (Turing?) analysis against to shorten the key space.
Problem with compress is the protocol headers give you a known part at the start of every message. Which you can then very quickly test keys against rainbow tables or other statistical means.
The best solution i know for this is to compress, then xor with a stream cipher then run into a decent block cipher.
The "compress after encrypt" is a trick question. If your data doesnt get bigger after that your encryption implementation is royally broken.
But you definately don't want every "plaintext" message starting with "..gzip".
Freudian slip? I like it anyway.
Encrypted content should be indistinguishable from random data. So encrypt than compress shouldn't be able to yield any reasonable compression.
What this short proof shows is that even though random data may have patterns, no compression algorithm can successfully leverage this for every random string.
So while a compression alg applied to a very large amount of random data is unlikely to reduce the size, it is quite possible to achieve some compression on smaller blocks.
http://marknelson.us/2012/10/09/the-random-compression-chall...
I think your main point is correct, just presented too strongly. In many cases compression after encryption will yield poor results. But I wouldn't go so far as to say that it can't be done.
For a reasonable definition of incompressible, properly encrypted data is it.
Consider using basic modular addition of letters, with A=1, B=2 ... Z = 26. If your plaintext is HELLO, and you get AAAAA as ciphertext, then your key has to be SVOOL. If you look, that's just an inversion of each letter. H is the 8th letter of the alphabet, whereas S is the 8th from the end, etc. So, your one-time pad was incidentally a simple translation of your message.
I'm not sure if there's any interesting information being leaked this way. Perhaps by seeing that the encrypted message can be heavily compressed, or knowing that it has been heavily compressed, you can assume that the encryption key has some very improbable patterns, and use that to bound guesses about the encryption key.
Not an expert. Not even an intermediate.
If you compress a document that simply obscures the size of the original document.
That is not generally true - if you compress AAA and ABC then the compressed version also leaks information about the content exactly like in the case of an audio stream and it reveals more information then the lengths of the uncompressed documents which don't differ.
Feed that information into a prebuilt phoneme-in-context model trained on that codec and language, and said eavesdropper could probably reconstruct a pretty good estimated transcript - different phonemes compress differently.
There is no reason this would not work in bulk: I am under the impression GCHQ have done a fair amount of research in this area, for example.
These sorts of attacks don't matter against a compressed and then encrypted file of indeterminate data, correct? Similarly, an amalgamation of many types of data, such as a disk or archive?
For example, you know its type, and it's 150KB. Even if you know it's a text document, or a WAV file, or bitmap, I think you get far less information from the compressed version than from the non-compressed version. The non-compressed version of the text document may give you approximate word count, and the WAV file will give you some probable lengths of the recording at common sampling rates, and the bitmap will give you some probable dimensions. Compressed versions hide this information within the natural variance of the compression.
The problem seems less to do with compression, and more to do with splitting larger data (or streams of data) into smaller chunks to encrypt, which in itself loses some of the benefits of hiding information in the variance of the data presented. Compression seems to exacerbate this situation by amplifying variances in very small data sets in a way that yields additional information, but it seems to me that's just a natural progression of encrypting very small amounts of data being not nearly as effective as large amounts of data.
At least, that's what I can intuit about the situation. It may be partly (or totally) wrong given some more advanced security theory (I am not a security professional).
I would guess that the phones and voip is a perfect target to do this, as those system are often designed to filter out noise. I guess it also would be almost impossible to use this to transcribe a encrypted movie or music, as the unpredictable sounds would break the prediction model.
I might be wrong, but I think the parent had something like this in mind:
Assuming you are encrypting with AES-CFB your each plaintext block P[i] produces a ciphertext block C[i] (with key K and initialization vector IV) according to rule:
    C[0] = AES_encrypt(K, IV) ^ P[0],
    C[i] = AES_encrypt(K, C[i-1]) ^ P[i].
This particular implementation would benefit then from adding a pseudorandom P[0] block (a "salt", if I understood correctly) that the receiver is to discard on arrival. I don't know enough cryptanalysis to tell if the above scenario is valid or not, but it sounds like a legitimate question at least.
I think this is only true if you use a bad encryption algorithm where same plaintext blocks have the same ciphertext.
Stream ciphers.
Other famous AEAD schemes are:
- CCM (Counter with CBC-MAC), packages AES-CTR and CBC-MAC together in an authenticate-then-encrypt regime
- ChaCha20-Poly1305, which packages together the stream cipher ChaCha20 and the MAC Poly1305.
Not that this really matters. The advantages/disadvantages of compression are the same in both cases.
If the attacker can influence the traffic, they can potentially gather information about the secret by examining the effect of differing traffic patterns on the size of the encrypted result.
I may be too close to the problem. I've had to explain this to project managers and customers of course, but this is hacker news.
It feels like a three page article on why you should put your socks on before your shoes and not after.
So? There are too many domains to be familiar with. You just happen to be familiar with this one. I bet there are plenty things I'd consider obvious on many other domains where you'd be clueless.
His big example was a Lego brick labelled "Compression" and another brick labelled "Encryption", and how you could arbitrarily compose them to achieve different protocols.
Meanwhile, I was sitting at the back of the room wearing my "I'm not a security guy, but this is garbage" look.
[1] https://mesosconna2016.sched.org/event/6ljt/keynote-a-real-t... [2] http://go.linuxfoundation.org/mesoscon-north-america-2016-vi...
I am guilty of not waiting around for him to get to his point 3/4 of the way through the article. If you're trying to bring up subtle issues, don't bury the lede.
What he's really trying to say is that you shouldn't compress sensitive data at all. And now we're into the non obvious stuff that some of us are clearly talking past each other about.
Personally, I think he's painting too broad a stroke and some domains don't have this problem, and for some there are other factors at play such as insufficient block size giving away too much information.
You could for instance probably figure out who is speaking just by the pattern of pauses, without even trying to decrypt what is said.
And then there's session cookies, which I despair of ever being secure. Because of the chosen plaintext of CRIME, even a large block size would only make the setup phase take a bit longer (finding a message that is one byte bigger than the block size). Encryption is insufficient to protect shared secrets.
Indeed, I think the conventional wisdom was that compressing first would in fact improve security a little bit. This idea goes back all the way to Shannon in 1949, who noted that compressing before encrypting should improve information-theoretic security, because if the messages contain redundancy, then an adversary with infinite computing power can use that to decode the message. (Just try all possible keys, and see if it decrypts to an actual English sentence.) On the other hand, if you first compress using an ideal compressor, then every compressed plaintext will look the same (just random noise), so every possible encryption key will produce some plausible plaintext.
[1] http://netlab.cs.ucla.edu/wiki/files/shannon1949.pdf ; see sections 16 - 19.
As someone else said, the title is terrible. What we are left with in some scenarios is choosing one or the other, not one before the other.
something something padding oracle
Not to nitpick, but this is incorrect. A encrypted file can very well have something like 100 X's in a row which the compression system could turn from XXXXXXXXXXXXXXXX.... into (100 x's go here) - Lousy example I know but it gets the point across.
Its also easy enough to test- Just encrypt a file then compress it. Sometimes it will be smaller. (Your reply indicated that in 100% of attempts compression is impossible)
That's a text file, which doesn't use the full range of a byte (0-255), so each character takes less than a byte.
Try compressing the output of /dev/urandom on your nearest convenient UNIX-like system. If you figure out a way to reliably and significantly compress that, please report back.
Also, the odds of getting finding even a single encrypted file of that length which can be compressed are lower than the odds of winning the lottery three times in a row. Trust me, you didn't just happen to stumble across a working example. You screwed up the test.
Then compressed it with winrar http://pasted.co/compressed.rar ( 7,743 bytes )
Roughly 20% compression isnt meaningless- so I fail to see why you are just giving a flat 'no' when its obvious what you are saying is untrue.
$ dd if=/dev/urandom of=test bs=1k count=10
$ cat test | gzip -9 > test.gz
$ cat test | bzip2 -9 > test.bz2
$ ls -al test*
-rw-r--r-- 1 r1ch r1ch 10240 Jun 28 16:30 test
-rw-r--r-- 1 r1ch r1ch 10739 Jun 28 16:31 test.bz2
-rw-r--r-- 1 r1ch r1ch 10263 Jun 28 16:31 test.gz
Random data is not compressible.
$ dd if=/dev/zero of=test bs=1k count=10
$ openssl enc -in test -aes-256-ctr -out test.encrypted
$ cat test.encrypted | gzip -9 > test.encrypted.gz
$ cat test.encrypted | bzip2 -9 > test.encrypted.bz2
$ ls -al test*
-rw-r--r-- 1 r1ch r1ch 10240 Jun 28 16:32 test
-rw-r--r-- 1 r1ch r1ch 10256 Jun 28 16:33 test.encrypted
-rw-r--r-- 1 r1ch r1ch 10737 Jun 28 16:34 test.encrypted.bz2
-rw-r--r-- 1 r1ch r1ch 10279 Jun 28 16:33 test.encrypted.gz
Encrypted zeroes are not compressible.
http://pasted.co/wasteoftime.txt 4,732 bytes
http://pasted.co/wasteoftime.rar 3,753 bytes
Also, if there is issues with using the 'wrong' encryption, I feel thats kind of a straw man argument. Please feel free to upload a file over 5MB which cant be reduced in size through any of the various compression tools.
Also, keep in mind that I never said it would be a huge benefit at all- I only said that SOME compression was possible SOME of the time.
Do you understand the difference between base64 and binary data? Base64 only uses six bits per byte. It's designed to allow data to transit cleanly through places which only allow text, such as JSON. Binary data is eight bits per byte. Binary data is what encryption and compression algorithms output. Naturally, if you take data which only uses six bits per byte, and run it through a compression algorithm which is able to use eight bits per byte, you can achieve good compression. But this is illusory, because you expanded the original by 33% when you applied base64 in the first place! All your attempts at compression can be beaten by simply decoding the base64 into the original binary data.
It doesn't matter what magnitude of compression you specified. Random data cannot be compressed at all on average. This is a simple mathematical certainty with a straightforward proof. Encrypted data looks and acts like random data. If you find a way to reliably compress the output of a modern, secure encryption algorithm (not the base64 encoding, but the original binary) then you'll have found a massive security hole in it which will make you famous.
This is a common misconception. The pigeonhole principle here tells us that any scheme that ever achieves some compression also achieves some expansion. The only reason compression algorithms work at all is because they are more likely to compress than they are to expand, because we know something about the probability distribution of the plaintexts.
The pigeonhole argument treats compression as a black box with input and output, and makes no assumption about how the compression works.
Your idea—to only compress some inputs and not others—doesn't change the fact that your algorithm can be treated as if it is a black box with inputs and outputs. So the pigeonhole principle still applies. Many people before you have made this argument before, so we are very familiar with it, and very familiar with the reason why it is wrong.
FURTHERMORE, compression, by its very nature, works very poorly on data which is apparently uniformly distributed, as encrypted data is.
This is why you are wrong.
you are trying to bring empirical evidence to an information theoretic fight :(
So yes, it is random, and 100 X's could appear in a row. But if your model can effectively compress that, then the model has to be wasting space for all the other sequences.
Let's just imagine that you are doing some like basic run length coding (gif! Or jif if you're wrong :) )
So 100 x's turns into (100, x). So you've compressed that part of the stream. Unfortunately everything else is likely (1,a), etc so every other symbol/byte increases in size. If we look at the stream probabilities we get something like P(nX)=(P(X)^n) -- very rough I haven't been at uni for a long time :). You can do a bunch of reasonably simple math do verify it but you eventually end up with something that your average symbol size is sum{x in X}-log(P(x))/|X|. Where X is your set of possible symbols (n,x:X).
For a given stream that is not encrypted you may save some space representing the input bytes, but each symbol (n,X) has at /least/ 1 extra bit of information. Overall you can save space.
But let's look at the encrypted data. Each input symbol is independent so your probability of any sequence in the input is equal. You will typically have a run length of 1 (P=0.5), 2 (P=0.5), ...
So 50% of your output symbols will have at least one extra bit of information /added/. This means your output by necessity is bigger than the input.
I used RLE as an example here, but it's true for all compression schemes. This is a necessary property for compression to work: for any data that compresses by n% under a given model there must be some input that increases in size by n% (or some such, again, long time since uni). I believe Wikipedia has an article on the pigeon hole problem or some such that probably explains this better than I can.
Any decent encryption algorithm has output indistinguishable from random noise; the odds of 100 Xes in a row in random data is 1:2^800; there are only 10^80 particles in the universe (2^266), which is 534 base-2 orders of magnitude smaller than 2^800. Yes, every particle in the universe could be a universe of fundamental particles and you'd still never see 100 Xs in a row in a decently-encrypted message.
If you manage to get that under 5MB by applying any tool which allows recovering the original data, I will be most interested to know how you did it.
./compress.sh https://mikeash.com/tmp/randomfile.bin > randomfile.compressedzomg
:D
/me hides
Everyone here is telling you that you are wrong, and have even clearly demonstrated this through both mathematical reasoning and empirical tests. Quit digging :-)
On that note, sometimes we all get too attached to our own hard-won mistakes. We all need to remember that sometimes we should set aside pride and just say, "Whoops, my reasoning was unclear or I was misinformed, thanks for correcting my misstatent or misunderstanding."
AES-ECB mode will actually compress fairly well for some inputs (the canonical example being a bitmap image). The reason the compression can work? Because the crypto is broken. In the image case you can actually just visually (no maths or anything) see a large amount of the details of the source image.
https://upload.wikimedia.org/wikipedia/commons/f/f0/Tux_ecb....
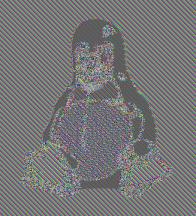
An additional point you need to consider: You can select different models and compression programs (and some programs do do this), but you have to record which one you use in your output. This again increases the size of the output - this means that even a no-op compression algorithm (say cat or cp :D ) results in output that is bigger (you need a initial byte to say you haven't tried to compress).
I think the better approach to what you're claiming is for you to provide an example that is compressed. Just provide the input, the key, the encryption algorithm (AES-GCM for preference, but seriously AES-CBC would work to), and the compression algorithm.
    (in-package :cl-user)
    (use-package :ironclad)
    (let ((data (make-array (* 5 1024 1024)
                            :element-type '(unsigned-byte 8)
                            :initial-element (char-code #\X))))
      (encrypt-in-place
       (make-cipher
        :aes
        :key (sb-ext:string-to-octets "YELLOW SUBMARINE")
        :mode :ctr
        :initialization-vector (make-array 16 :element-type '(unsigned-byte 8)))
       data)
      (with-open-file (tmp "/tmp/data" :direction :output
                           :element-type '(unsigned-byte 8))
        (write-sequence data tmp)))
may be smaller, not all outputs will be smaller, this is true of all lossless compression algorithms:
The real question is, can you reliably compress encrypted messages in general? And, given that the encryption is not broken, the answer is no.
In theory, some random outputs will be compressible by common tools (for example, a file that's all zeroes). However, the probability of encountering a random file that compresses more than the overhead from any common compression tool is vanishingly small.
No they're not. They're saying that as a class, you cannot compress the data. That is a statement about what happens in aggregate. And the aggregate result of trying to compress securely-encrypted data is that you don't save bytes. Even just having the option of compression does not save bytes, because you have to store the choice.
It's just compress or not, before encrypting. If security is important, the answer to that is no, unless you're an expert and familiar with CRIME and related attacks.
Compression after encryption is useless, as there should be NO recognizable patterns to exploit after the encryption.