News for hackers. Stuff that matters.
Re:GPT-5.4 by twtw99 on Thursday March 05, 2026 @01:24PM (#47265254)
If you don't want to click in, easy comparison with other 2 frontier models - https://x.com/OpenAI/status/2029620619743219811?s=20
Re:GPT-5.4 by bicx on Thursday March 05, 2026 @02:47PM (#47266371)
That last benchmark seemed like an impressive leg up against Opus until I saw the sneaky footnote that it was actually a Sonnet result. Why even include it then, other than hoping people don't notice?
Re:GPT-5.4 by osti on Thursday March 05, 2026 @03:00PM (#47266514)
It's only that one number that is for sonnet.
Re:GPT-5.4 by 0123456789ABCDE on Thursday March 05, 2026 @03:46PM (#47267051)
except for the webarena-verified
Re:GPT-5.4 by conradkay on Thursday March 05, 2026 @02:57PM (#47266477)
Sonnet was pretty close to (or better than) Opus in a lot of benchmarks, I don't think it's a big deal
Re:GPT-5.4 by jitl on Thursday March 05, 2026 @03:03PM (#47266561)
wat
Re:GPT-5.4 by 0123456789ABCDE on Thursday March 05, 2026 @03:54PM (#47267142)
maybe gp's use of the word "lots" is unwarranted

https://artificialanalysis.ai indicates that sonnect 4.6 beats opus 4.6 on GDPval-AA, Terminal-Bench Hard, AA Long context Reasoning, IFBench.

see: https://artificialanalysis.ai/?models=claude-sonnet-4-6%2Ccl...

Re:GPT-5.4 by conradkay on Thursday March 05, 2026 @10:47PM (#47270622)
I was basing it off my recollection of this:

https://www.anthropic.com/_next/image?url=https%3A%2F%2Fwww-...
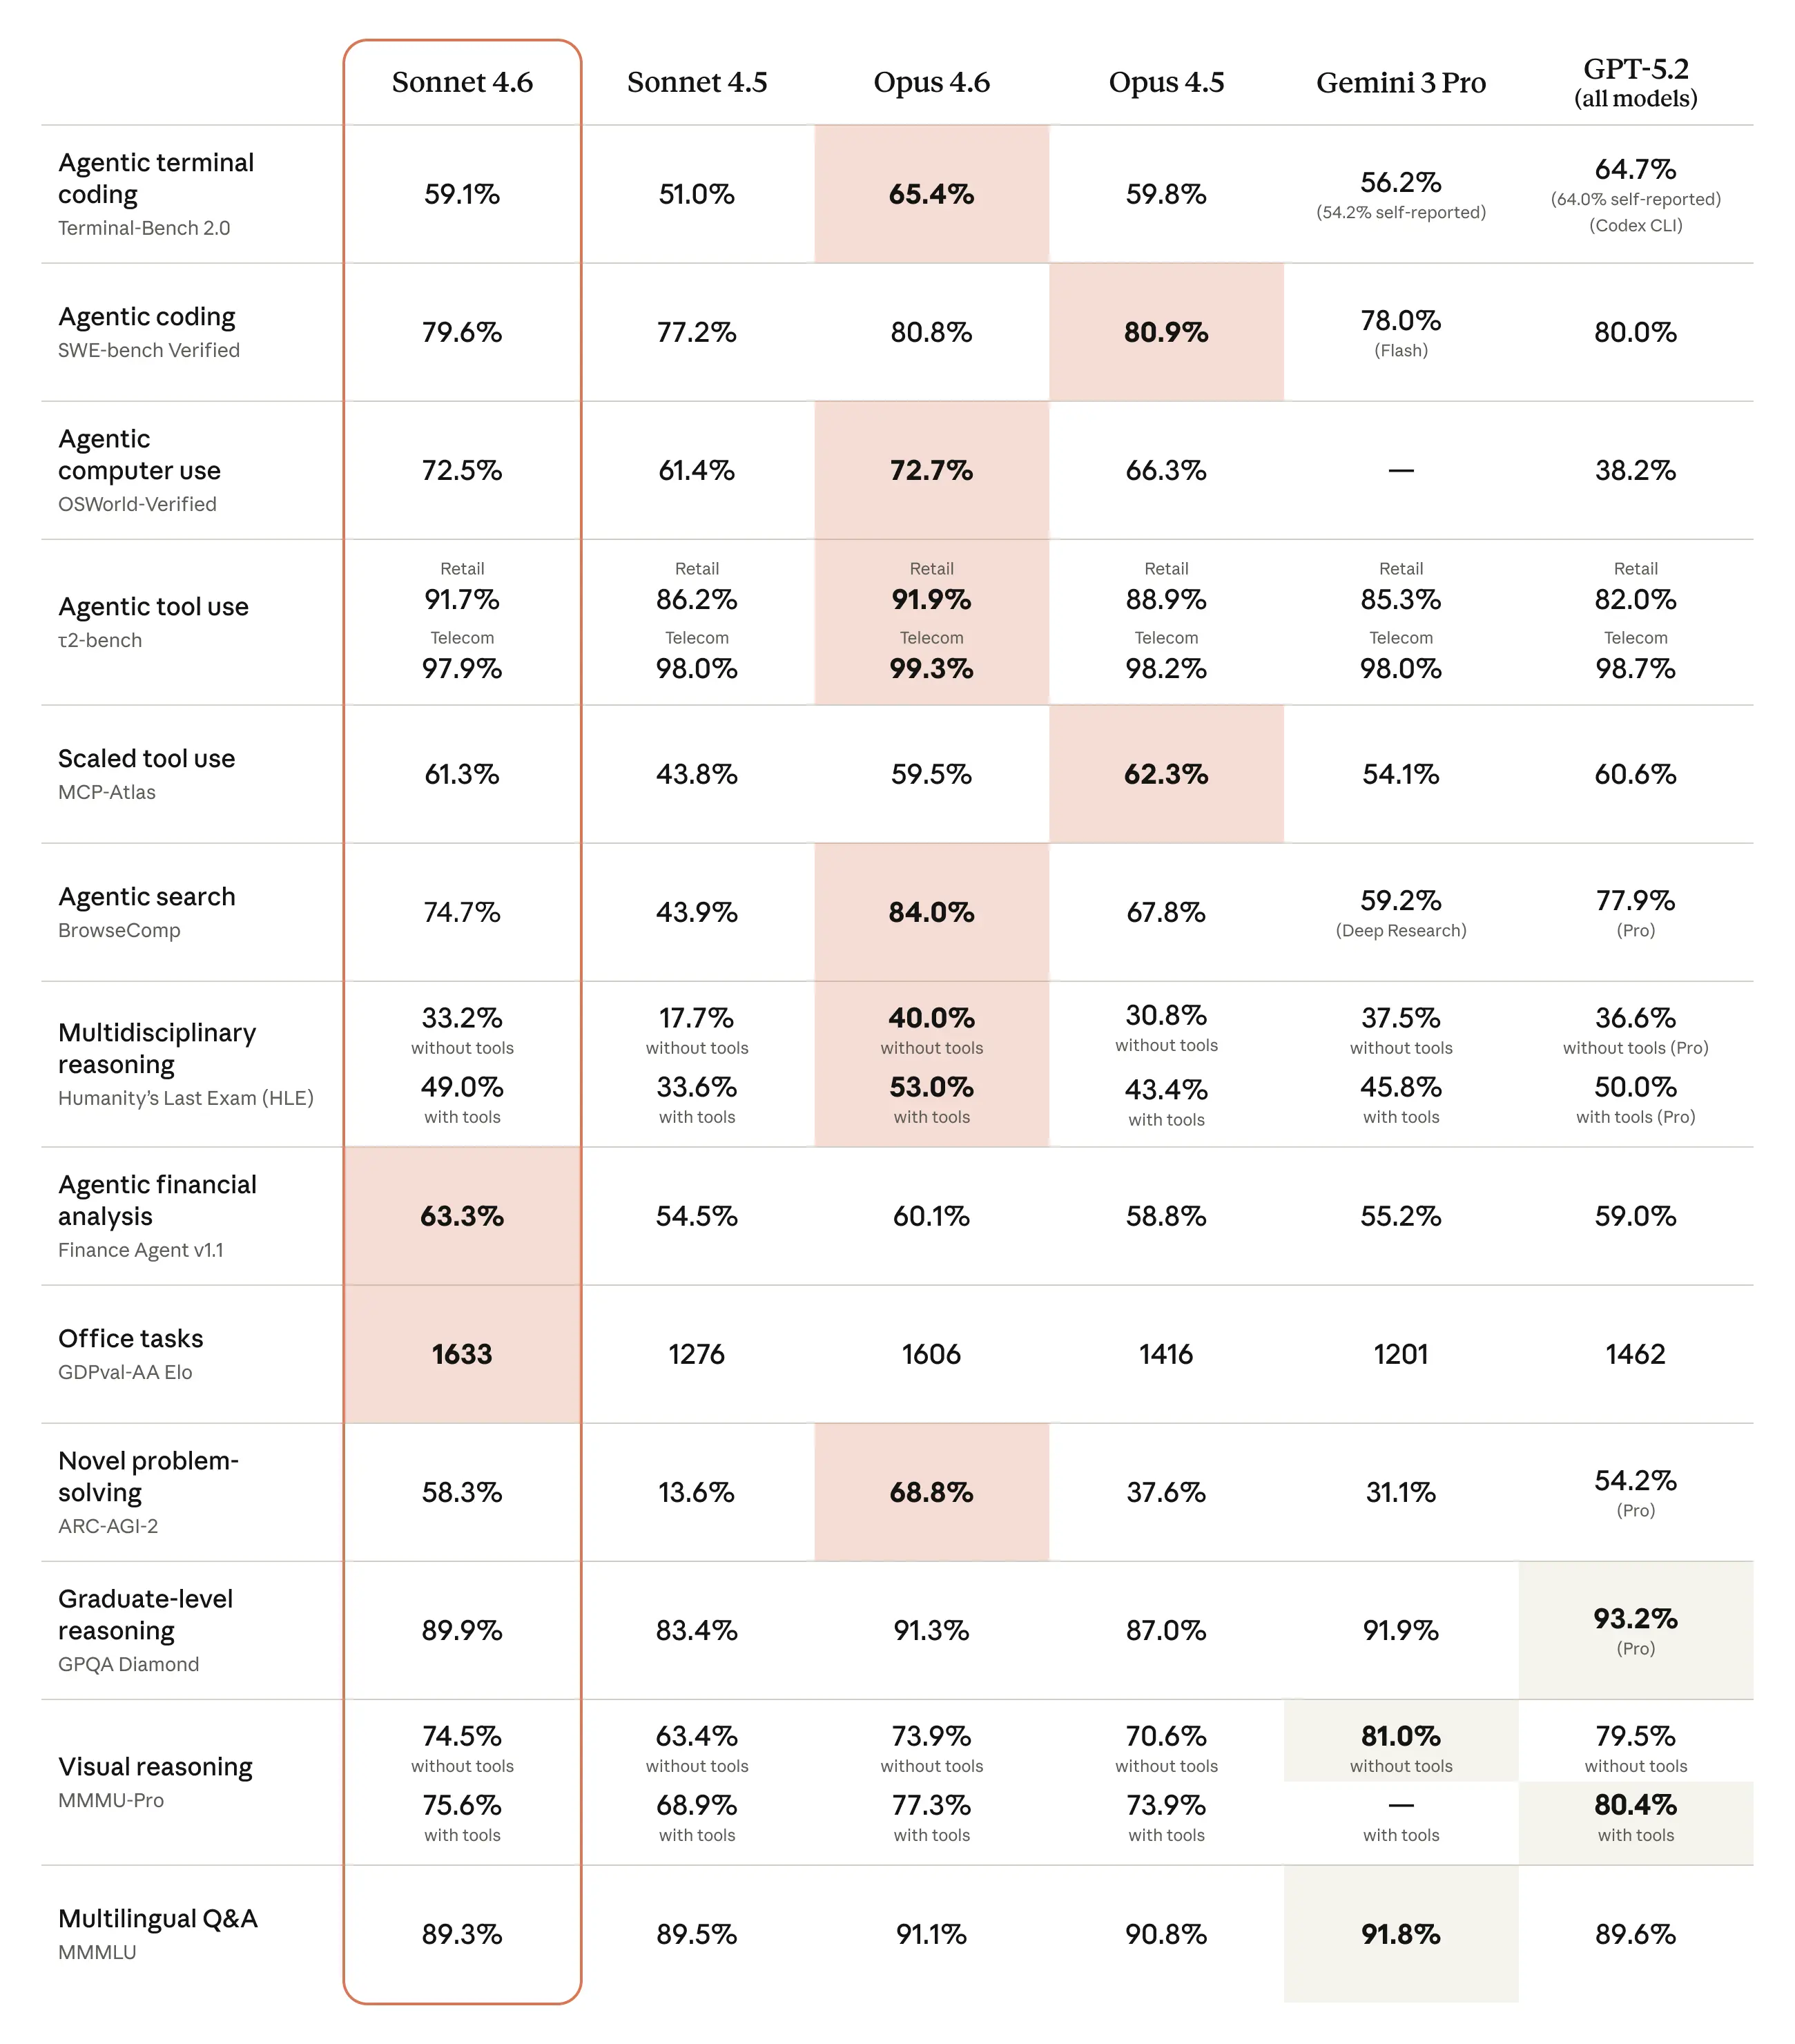
basically 9/13 are very close

Re:GPT-5.4 by Aboutplants on Thursday March 05, 2026 @01:32PM (#47265342)
It seems that all frontier models are basically roughly even at this point. One may be slightly better for certain things but in general I think we are approaching a real level playing field field in terms of ability.
Re:GPT-5.4 by observationist on Thursday March 05, 2026 @01:47PM (#47265575)
Benchmarks don't capture a lot - relative response times, vibes, what unmeasured capabilities are jagged and which are smooth, etc. I find there's a lot of difference between models - there are things which Grok is better than ChatGPT for that the benchmarks get inverted, and vice versa. There's also the UI and tools at hand - ChatGPT image gen is just straight up better, but Grok Imagine does better videos, and is faster.

Gemini and Claude also have their strengths, apparently Claude handles real world software better, but with the extended context and improvements to Codex, ChatGPT might end up taking the lead there as well.

I don't think the linear scoring on some of the things being measured is quite applicable in the ways that they're being used, either - a 1% increase for a given benchmark could mean a 50% capabilities jump relative to a human skill level. If this rate of progress is steady, though, this year is gonna be crazy.

Re:GPT-5.4 by baq on Thursday March 05, 2026 @01:55PM (#47265688)
Gemini 3.1 slaps all other models at subtle concurrency bugs, sql and js security hardening when reviewing. (Obviously haven’t tested gpt 5.4 yet.)

It’s a required step for me at this point to run any and all backend changes through Gemini 3.1 pro.

Re:GPT-5.4 by observationist on Thursday March 05, 2026 @02:18PM (#47265989)
I have a few standard problems I throw at AI to see if they can solve them cleanly, like visualizing a neural network, then sorting each neuron in each layer by synaptic weights, largest to smallest, correctly reordering any previous and subsequent connected neurons such that the network function remains exactly the same. You should end up with the last layer ordered largest to smallest, and prior layers shuffled accordingly, and I still haven't had a model one-shot it. I spent an hour poking and prodding codex a few weeks back and got it done, but it conceptually seems like it should be a one-shot problem.
Re:GPT-5.4 by thejohnconway on Thursday March 05, 2026 @06:29PM (#47268692)
Lol, I’ve had cutting edge models suggest I make an inflexible hole bigger by putting shim in it, and argue their case stubbornly. I don’t know what you’re using to suggest they are anywhere near solving your problem there!
Re:GPT-5.4 by adonese on Thursday March 05, 2026 @02:14PM (#47265932)
Which subscription do you have to use it? Via Google ai pro and gemini cli i always get timeouts due to model being under heavy usage. The chat interface is there and I do have 3.1 pro as well, but wondering if the chat is the only way of accessing it.
Re:GPT-5.4 by baq on Thursday March 05, 2026 @02:55PM (#47266456)
Cursor sub from $DAYJOB.
Re:GPT-5.4 by basch on Thursday March 05, 2026 @03:17PM (#47266726)
>ChatGPT image gen is just straight up better

Yet so much slower than Gemini / Nano Banana to make it almost unusable for anything iterative.

Re:GPT-5.4 by bigyabai on Thursday March 05, 2026 @01:53PM (#47265667)
> If this rate of progress is steady, though, this year is gonna be crazy.

Do you want to make any concrete predictions of what we'll see at this pace? It feels like we're reaching the end of the S-curve, at least to me.

Re:GPT-5.4 by observationist on Thursday March 05, 2026 @02:04PM (#47265800)
If you look at the difference in quality between gpt-2 and 3, it feels like a big step, but the difference between 5.2 and 5.4 is more massive, it's just that they're both similarly capable and competent. I don't think it's an S curve; we're not plateauing. Million token context windows and cached prompts are a huge space for hacking on model behaviors and customization, without finetuning. Research is proceeding at light speed, and we might see the first continual/online learning models in the near future. That could definitively push models past the point of human level generality, but at the very least will help us discover what the next missing piece is for AGI.
Re:GPT-5.4 by ryandrake on Thursday March 05, 2026 @02:59PM (#47266498)
For 2026, I am really interested in seeing whether local models can remain where they are: ~1 year behind the state of the art, to the point where a reasonably quantized November 2026 local model running on a consumer GPU actually performs like Opus 4.5.

I am betting that the days of these AI companies losing money on inference are numbered, and we're going to be much more dependent on local capabilities sooner rather than later. I predict that the equivalent of Claude Max 20x will cost $2000/mo in March of 2027.

Re:GPT-5.4 by mootothemax on Thursday March 05, 2026 @03:54PM (#47267147)
Huh, that’s interesting, I’ve been having very similar thoughts lately about what the near-ish term of this tech looks like.

My biggest worry is that the private jet class of people end up with absurdly powerful AI at their fingertips, while the rest of us are left with our BigMac McAIs.

Re:GPT-5.4 by thewebguyd on Thursday March 05, 2026 @01:46PM (#47265552)
Kind of reinforces that a model is not a moat. Products, not models, are what's going to determine who gets to stay in business or not.
Re:GPT-5.4 by gregpred on Thursday March 05, 2026 @01:47PM (#47265578)
Memory (model usage over time) is the moat.
Re:GPT-5.4 by energy123 on Thursday March 05, 2026 @01:49PM (#47265603)
Narrative violation: revenue run rates are increasing exponentially with about 50% gross margins.
Re:GPT-5.4 by kseniamorph on Thursday March 05, 2026 @02:31PM (#47266175)
makes sense, but i'd separate two things: models converging in ability vs hitting a fundamental ceiling. what we're probably seeing is the current training recipe plateauing — bigger model, more tokens, same optimizer. that would explain the convergence. but that's not necessarily the architecture being maxed out. would be interesting to see what happens when genuinely new approaches get to frontier scale.
Re:GPT-5.4 by druskacik on Thursday March 05, 2026 @01:50PM (#47265612)
That has been true for some time now, definitely since Claude 3 release two years ago.
Re:GPT-5.4 by chabes on Thursday March 05, 2026 @01:26PM (#47265285)
Definitely don’t want to click in at x either.
Re:GPT-5.4 by thejarren on Thursday March 05, 2026 @01:28PM (#47265300)
Re:GPT-5.4 by anonym00se1 on Thursday March 05, 2026 @01:28PM (#47265305)
Ditto, but I did anyways and enjoyed that OpenAI doesn't include the dogwater that is Grok on their scorecard.
Re:GPT-5.4 by Sabinus on Thursday March 05, 2026 @05:06PM (#47267956)
Get a redirect plugin and set it up to send you to xcancel instead of Twitter. I've done it, and it's very convenient.
Re:GPT-5.4 by dom96 on Thursday March 05, 2026 @02:08PM (#47265853)
Why do none of the benchmarks test for hallucinations?
Re:GPT-5.4 by tedsanders on Thursday March 05, 2026 @03:34PM (#47266925)
In the text, we did share one hallucination benchmark: Claim-level errors fell by 33% and responses with an error fell by 18%, on a set of error-prone ChatGPT prompts we collected (though of course the rate will vary a lot across different types of prompts).

Hallucinations are the #1 problem with language models and we are working hard to keep bringing the rate down.

(I work at OpenAI.)

Re:GPT-5.4 by netule on Thursday March 05, 2026 @02:51PM (#47266399)
Optics. It would be inconvenient for marketing, so they leave those stats to third parties to figure out.
Re:GPT-5.4 by swingboy on Thursday March 05, 2026 @01:35PM (#47265381)
Why do so many people in the comments want 4o so bad?
Re:GPT-5.4 by cheema33 on Thursday March 05, 2026 @02:24PM (#47266077)
> Why do so many people in the comments want 4o so bad?

You can ask 4o to tell you "I love you" and it will comply. Some people really really want/need that. Later models don't go along with those requests and ask you to focus on human connections.

Re:GPT-5.4 by astrange on Thursday March 05, 2026 @01:38PM (#47265421)
They have AI psychosis and think it's their boyfriend.

The 5.x series have terrible writing styles, which is one way to cut down on sycophancy.

Re:GPT-5.4 by baq on Thursday March 05, 2026 @01:57PM (#47265702)
Somebody on Twitter used Claude code to connect… toys… as mcps to Claude chat.

We’ve seen nothing yet.

Re:GPT-5.4 by mikkupikku on Thursday March 05, 2026 @02:05PM (#47265813)
My computer ethics teacher was obsessed with 'teledildonics' 30 years ago. There's nothing new under the sun.
Re:GPT-5.4 by Sharlin on Thursday March 05, 2026 @03:13PM (#47266685)
There are many games these days that support controllable sex toys. There's an interface for that, of course: https://github.com/buttplugio/buttplug. Written in Rust, of course.
Re:GPT-5.4 by the_af on Thursday March 05, 2026 @03:51PM (#47267109)
> Written in Rust, of course.

Safety is important.

Re:GPT-5.4 by vntok on Thursday March 05, 2026 @02:59PM (#47266500)
Was your teacher Ted Nelson?
Re:GPT-5.4 by mikkupikku on Thursday March 05, 2026 @03:26PM (#47266816)
I wish, dude is a legend.
Re:GPT-5.4 by manmal on Thursday March 05, 2026 @02:13PM (#47265916)
ding-dong-cli is needed
Re:GPT-5.4 by Herring on Thursday March 05, 2026 @02:21PM (#47266033)
what.. :o
Re:GPT-5.4 by embedding-shape on Thursday March 05, 2026 @01:38PM (#47265413)
Someone correct me if I'm wrong, but seemingly a lot of the people who found a "love interest" in LLMs seems to have preferred 4o for some reason. There was a lot of loud voices about that in the subreddit r/MyBoyfriendIsAI when it initially went away.
Re:GPT-5.4 by drittich on Thursday March 05, 2026 @02:18PM (#47265988)
I think it's time for an https://hotornot.com for AI models.
Re:GPT-5.4 by vntok on Thursday March 05, 2026 @02:59PM (#47266504)
botornot?
Re:GPT-5.4 by MattGaiser on Thursday March 05, 2026 @01:47PM (#47265571)
The writing with the 5 models feels a lot less human. It is a vibe, but a common one.
Re:GPT-5.4 by MarcFrame on Thursday March 05, 2026 @02:20PM (#47266029)
how does 5.4-thinking have a lower FrontierMath score than 5.4-pro?
Re:GPT-5.4 by nico1207 on Thursday March 05, 2026 @02:23PM (#47266065)
Well 5.4-pro is the more expensive and more advanced version of 5.4-thinking so why wouldn't it?
Re:GPT-5.4 by karmasimida on Thursday March 05, 2026 @01:29PM (#47265316)
It is a bigger model, confirmed