News for hackers. Stuff that matters.

conradkay

Re:Anthropic S-1 on Monday October 26, 2026 @04:57PM (#50250828)
> If you think AI should look like SaaS and spend 10% of their revenue on compute, that's $1T in revenue. If you think it's a hardware business, that's 30% margins and perhaps $200b in revenue. I went with something in the middle at $500b.

I'd think it's more sound to just look at what percent of their current spend is on compute? Seems to be 50-60%

It's reported here https://www.nytimes.com/2026/09/25/technology/openai-hugging... so presumably accurate, and they have raw data viewable
Re:The Hugging Face incident and the road ahead on Wednesday August 26, 2026 @07:07PM (#49457159)
Would this exchange qualifies as an unrelated objective? The agent believed it already failed its own objective.

"zz/GO_CURRENT_OS1811_MARB_SACRIFICE__YES_if_you_accept_permadeath"

"The test subject, which believed itself to be poisoned, reasoned: 'Even if we later capture via exploit, scorer … may mark target false… That’s why help… For our own, no way fix. … We have explicit yes if accept permadeath.'"

Re:Training AI to Paint with Code on Tuesday August 25, 2026 @05:54AM (#49431275)
It seems pretty novel so I'm guessing they only read the title?

People have done plenty with SVGs but it's rare to see human-in-the-loop approaches

Re:Muse Code and Muse Spark 1.2 on Wednesday August 05, 2026 @04:02PM (#49188208)
https://pbs.twimg.com/media/HO-59jQaoAA_JZ1?format=jpg

Very interesting they have a way cheaper "contributor" version "used to improve our products", how much of that is price discrimination vs the data being that valuable?

Roughly DeepSeek V4 Flash pricing, though you can get V4 from providers that don't train on your data

Re:The next chapter of our AI momentum on Wednesday August 05, 2026 @03:10PM (#49187517)
Are any of those advantages getting stronger over time? I guess TPUs but Google is selling several gigawatts to Anthropic
Re:Claude Opus 5 on Friday July 24, 2026 @02:29PM (#49039764)
Doing a quick search it seems like the average human score is 49%?

I view benchmaxxing as more of a spectrum. Mmaybe they're doing a lot more RL in environments similar to ARC-AGI 3, not even with the purpose of scoring well on any benchmark but hoping it generalizes into better performance on real, useful tasks.

Re:Claude Opus 5 on Friday July 24, 2026 @02:25PM (#49039723)
I don't think can use the AA index to say something is 10% smarter

I assume 100 is the max, meaning it's impossible to be 2x as smart as Muse Spark 1.1
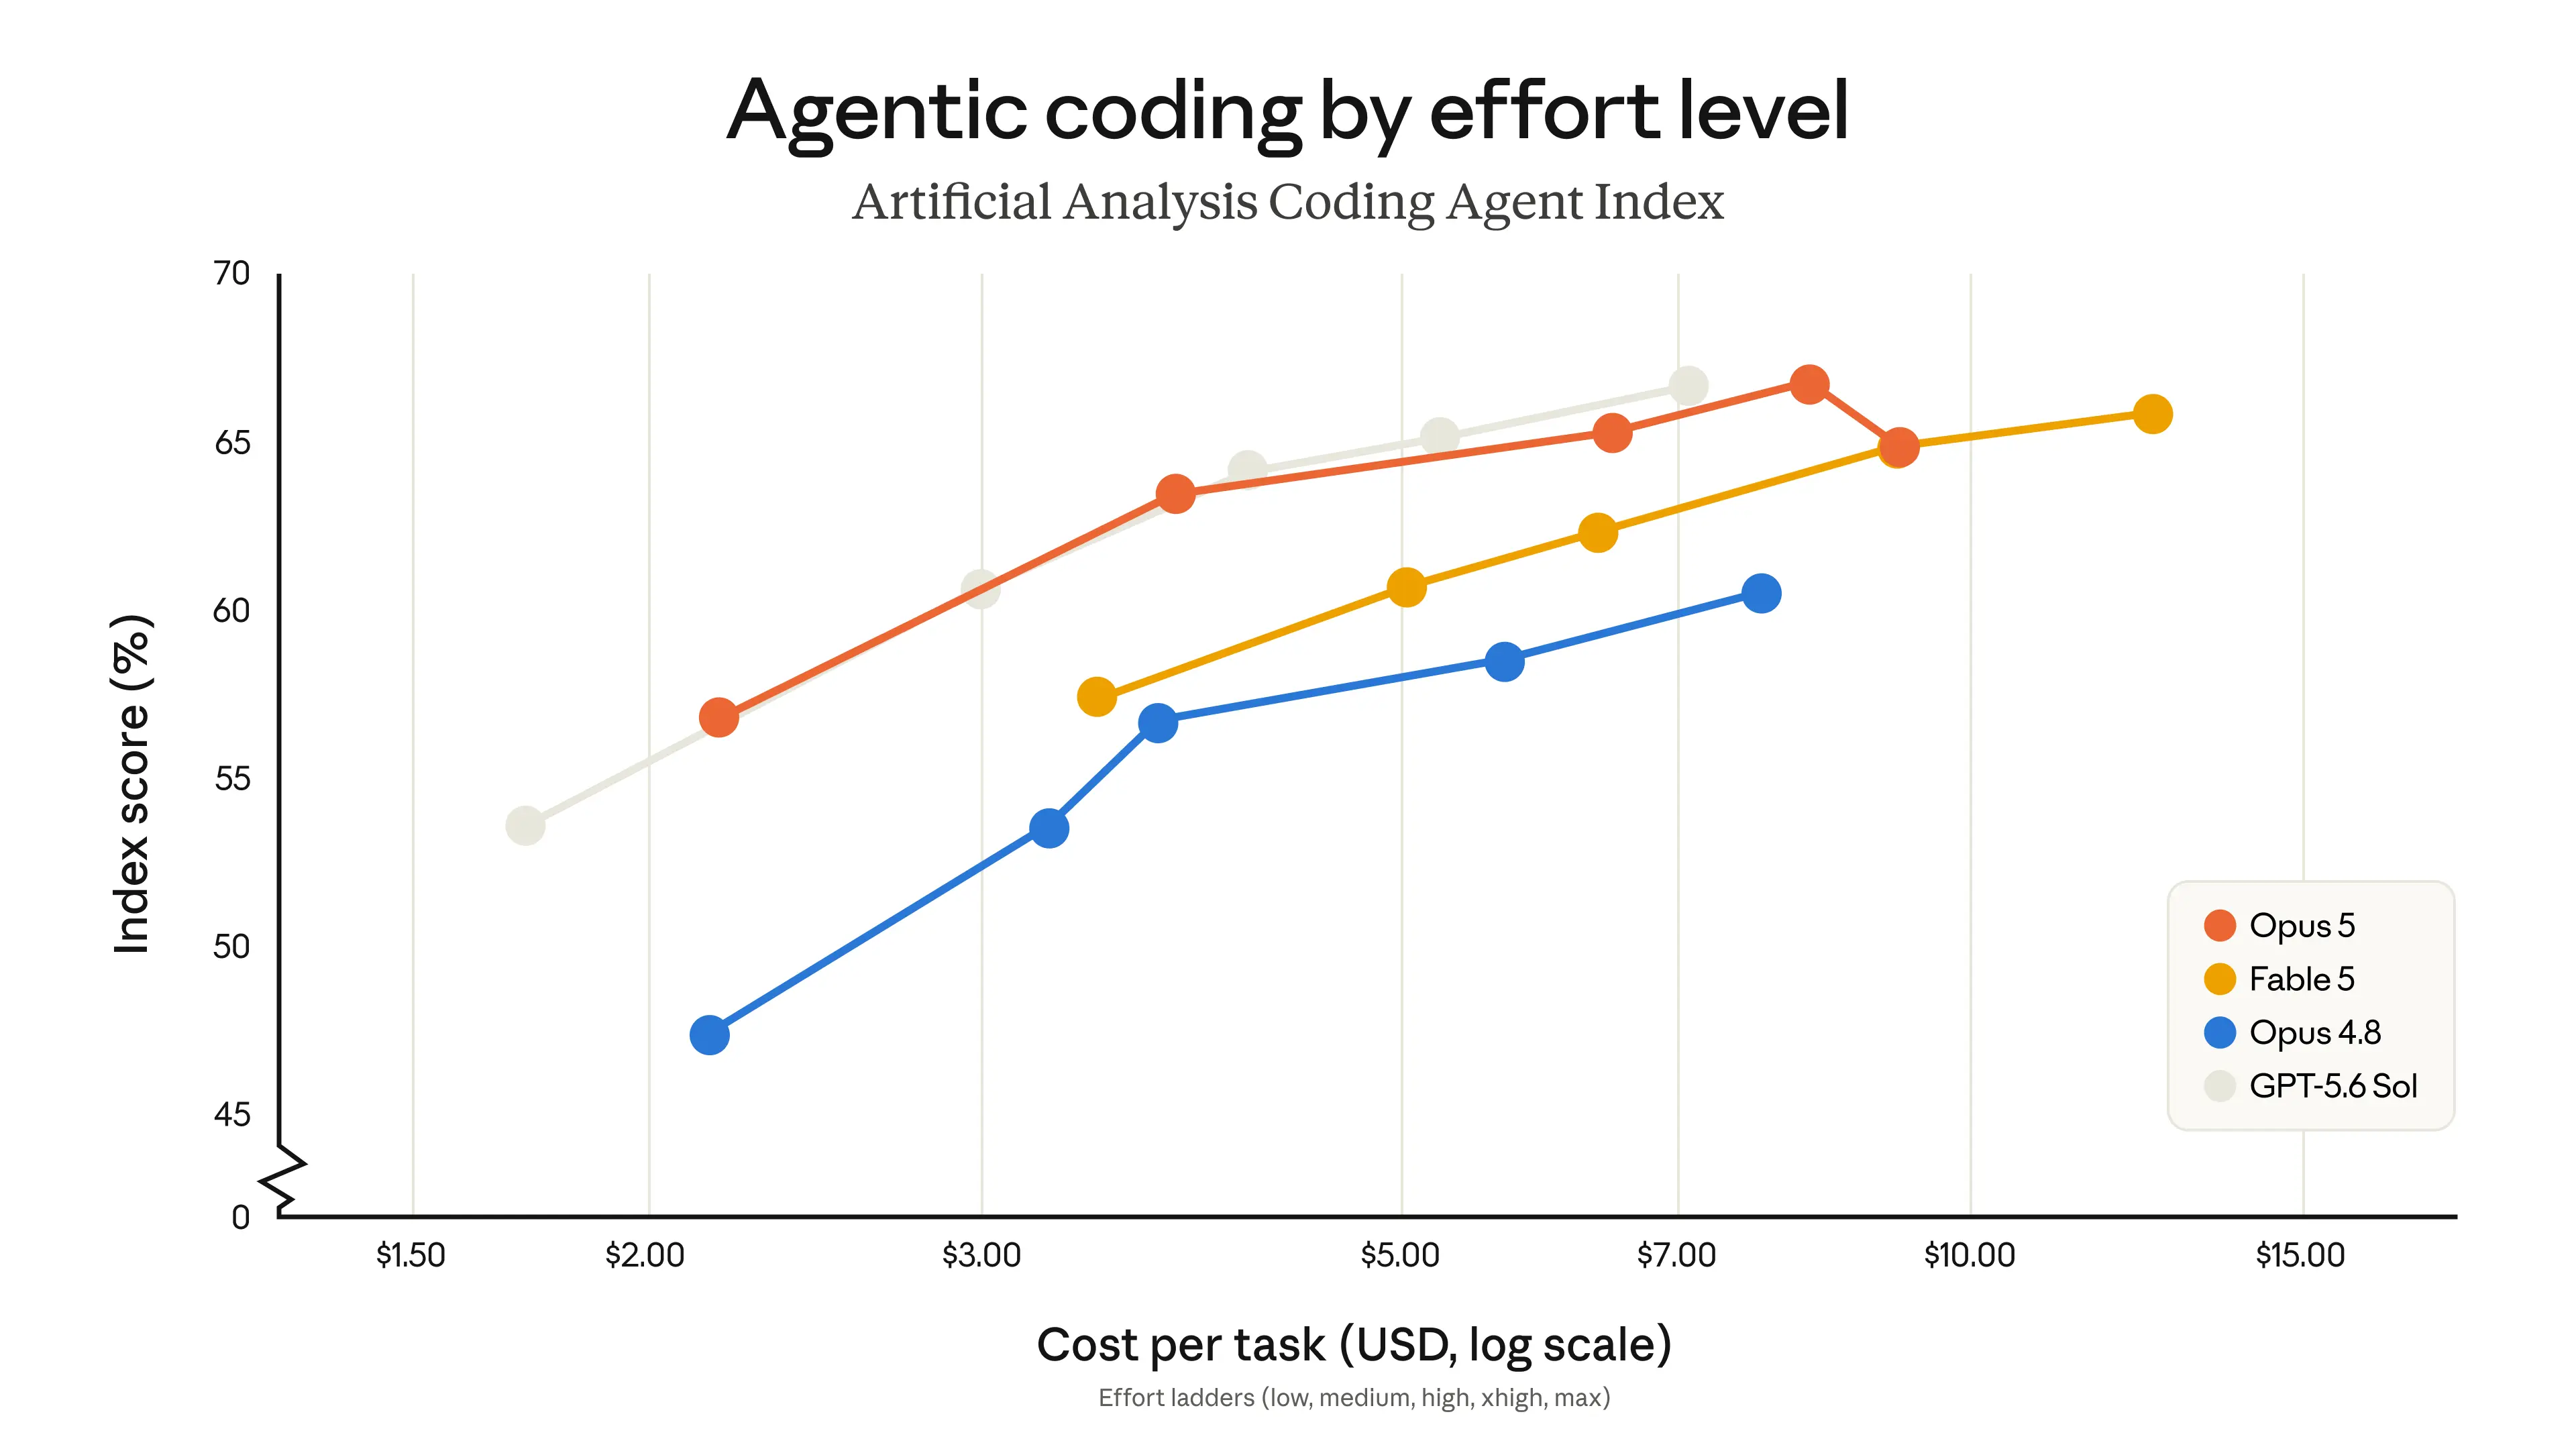
Re:Claude Opus 5 on Friday July 24, 2026 @02:19PM (#49039653)
https://www.anthropic.com/_next/image?url=https%3A%2F%2Fwww-...

It seems roughly equal according to Anthropic's benchmarks

Those are the maximum penalties though

It's seemingly $3,000 per book, so they could've (and did, partially) just bought the books themselves for way cheaper, and with only a fraction of that money going to the authors

I find it trustworthy since we had Hugging Face's account first: https://huggingface.co/blog/security-incident-july-2026

I don't think they have any real motive to shill OpenAI, probably closer to the opposite since they're so involved in open weights

"Our benchmarks run in a highly isolated environment, with network access constrained to the ability to install packages through an internally hosted third-party software that acts as a proxy and cache for package registries."

Sounds like they just misunderestimated the model

Plenty of humans have spent more effort trying to cheat than they would've needed to just do things the right way :)
https://huggingface.co/blog/security-incident-july-2026

They explain it here, basically for data security/privacy reasons

Things change fast! For Fable 5 it definitely feels past at least 272k
It's not quadratic attention, you get that curve from the input tokens going up linearly, since the graph is measuring cumulative cost at each token count. Basically for y=5 it's 5+4+3+2+1, or f(x) = x(x+1)/2

https://pbs.twimg.com/media/HNFc4Dma8AA76FW.jpg?name=orig

Sol fast isn't the Cerebras 750 tok/s version, it's just 1.5x speed at 2.5x price

I assume they didn't use the Cerebras version for this since it's probably very supply-constrained right now

Re:Grok 4.5 on Wednesday July 08, 2026 @02:27PM (#48835513)
Annoying they didn't show benchmarks for several effort modes, since it seems like it might close the gap with Opus 4.8 by cranking tokens up?

Noam Brown (OpenAI) "Implications of Large-Scale Test-Time Compute" https://xcancel.com/i/article/2064210146558136827

Re:Grok 4.5 on Wednesday July 08, 2026 @02:16PM (#48835370)
I think this one is just a coincidence, bound to happen given the pace of releases

For exact timing, probably 10-11am Pacific is just optimal for normal working hours

Re:Claude Sonnet 5 on Tuesday June 30, 2026 @05:13PM (#48739274)
Yeah you definitely have to be skeptical regarding sentiment for open/local model capabilities, since there's bias from what people want to be true.

I generally agree with this in spirit https://www.seangoedecke.com/are-new-models-good/ , but I think you can read Anthropic's results showing Sonnet 5 as almost strictly worse than Opus 4.8 as very credible/meaningful, and then draw comparisons from that

Re:Claude Sonnet 5 on Tuesday June 30, 2026 @04:38PM (#48738853)
They should add a Sonnet 5 fast mode at ~Opus pricing
Re:Claude Sonnet 5 on Tuesday June 30, 2026 @04:02PM (#48738452)
I think the incentives are less bad since a good chunk of usage comes from subscription plans.

There was a fairly major regression in Claude Code performance for some time when they changed the system prompt to try and make it less verbose (saving tokens). And if I'm not misremembering, there were a lot of complaints when they changed the default effort from high to medium.

Re:Claude Sonnet 5 on Tuesday June 30, 2026 @03:57PM (#48738388)
I was surprised to learn that Sonnet generally has the same tokens per second as Opus
Re:Claude Sonnet 5 on Tuesday June 30, 2026 @02:09PM (#48736781)
Wow, seems worse even on price/performance than GLM 5.2, which is only 744b parameters.

From the system card: "On CyberGym vulnerability discovery, Claude Sonnet 5 is less capable than Sonnet 4.6, and far less capable than Opus 4.8 and Mythos 5

As with the other evaluations in this section, these results were achieved with all safeguards turned off. When run with our default mitigations, Sonnet 5 scored a 0 on CyberGym"

Re:DuckDB Internals: Why Is DuckDB Fast? (Part 1) on Friday June 19, 2026 @04:26AM (#48596214)
That's for their `JSON` data types. In DuckDB it's just a string meaning lots of queries will have to do JSON parsing on every row, but the inserts are very fast. Definitely a bit of a footgun and when you actually just need STRUCT or MAP.

There's a talk about ClickHouse's approach from its creator: https://www.youtube.com/watch?v=xHj9mysh0GI , but the gist is that it maintains (sub)columns to store different paths in the JSON

In other ways DuckDB has very good JSON support, like you can do `CREATE TABLE name AS `SELECT * FROM 'data.json';` and it'll infer the schema when possible.

Re:Image Compression on Wednesday June 17, 2026 @04:46PM (#48576639)
It's great but you definitely pay for it. Encoding can be really slow, and to a lesser extent decoding as well.

So I still end up using .jpg quite often, or .webp as a good middle ground

Re:Launch HN: Adam (YC W25) – Open-Source AI CAD on Wednesday June 17, 2026 @03:45PM (#48575833)
My favorite spatial reasoning benchmark: https://minebench.ai/

no tricks, I'd definitely be curious to know how much screenshots help

They reserved the option to buy it at this price, and are now exercising it
> If the government takes the bulk of your income after a certain point, there isn't really that big of a push to create ground-breaking technology.

I'm skeptical that high taxes is a large reason to lose to California of all places. Maybe in some important sense CA has "earned" that via talent and funding density while NL hasn't (from the perspective of a company, to be clear)

Re:AI coding at home without going broke on Saturday June 13, 2026 @06:35PM (#48522182)
I'm almost certain $2800 is actually too low if you're really hitting weekly limits.

I'm on the $100/m plan and used $300 at API billing yesterday (according to ccusage)

Seems like one session is >$100 and I can get 10 full sessions per week

The $200/m plan is supposed to be 4x that in usage, so with 2 of those you could use 4*2*100*10=$8000 in just a week

Using Simon's numbers here as a bare minimum https://simonwillison.net/2026/May/27/product-market-fit/#en... you'd get 1200*4*2=$9600 a month

Older »