Re:GPT-5.4
by bicx on Thursday March 05, 2026 @02:47PM
(#47266371)
That last benchmark seemed like an impressive leg up against Opus until I saw the sneaky footnote that it was actually a Sonnet result. Why even include it then, other than hoping people don't notice?
[ Parent
| on HN ]
It's only that one number that is for sonnet.
Re:GPT-5.4
by 0123456789ABCDE on Thursday March 05, 2026 @03:46PM
(#47267051)
except for the webarena-verified
Sonnet was pretty close to (or better than) Opus in a lot of benchmarks, I don't think it's a big deal
Re:GPT-5.4
by 0123456789ABCDE on Thursday March 05, 2026 @03:54PM
(#47267142)
maybe gp's use of the word "lots" is unwarranted
https://artificialanalysis.ai indicates that sonnect 4.6 beats opus 4.6 on GDPval-AA, Terminal-Bench Hard, AA Long context Reasoning, IFBench.
see: https://artificialanalysis.ai/?models=claude-sonnet-4-6%2Ccl...
I was basing it off my recollection of this:
https://www.anthropic.com/_next/image?url=https%3A%2F%2Fwww-...
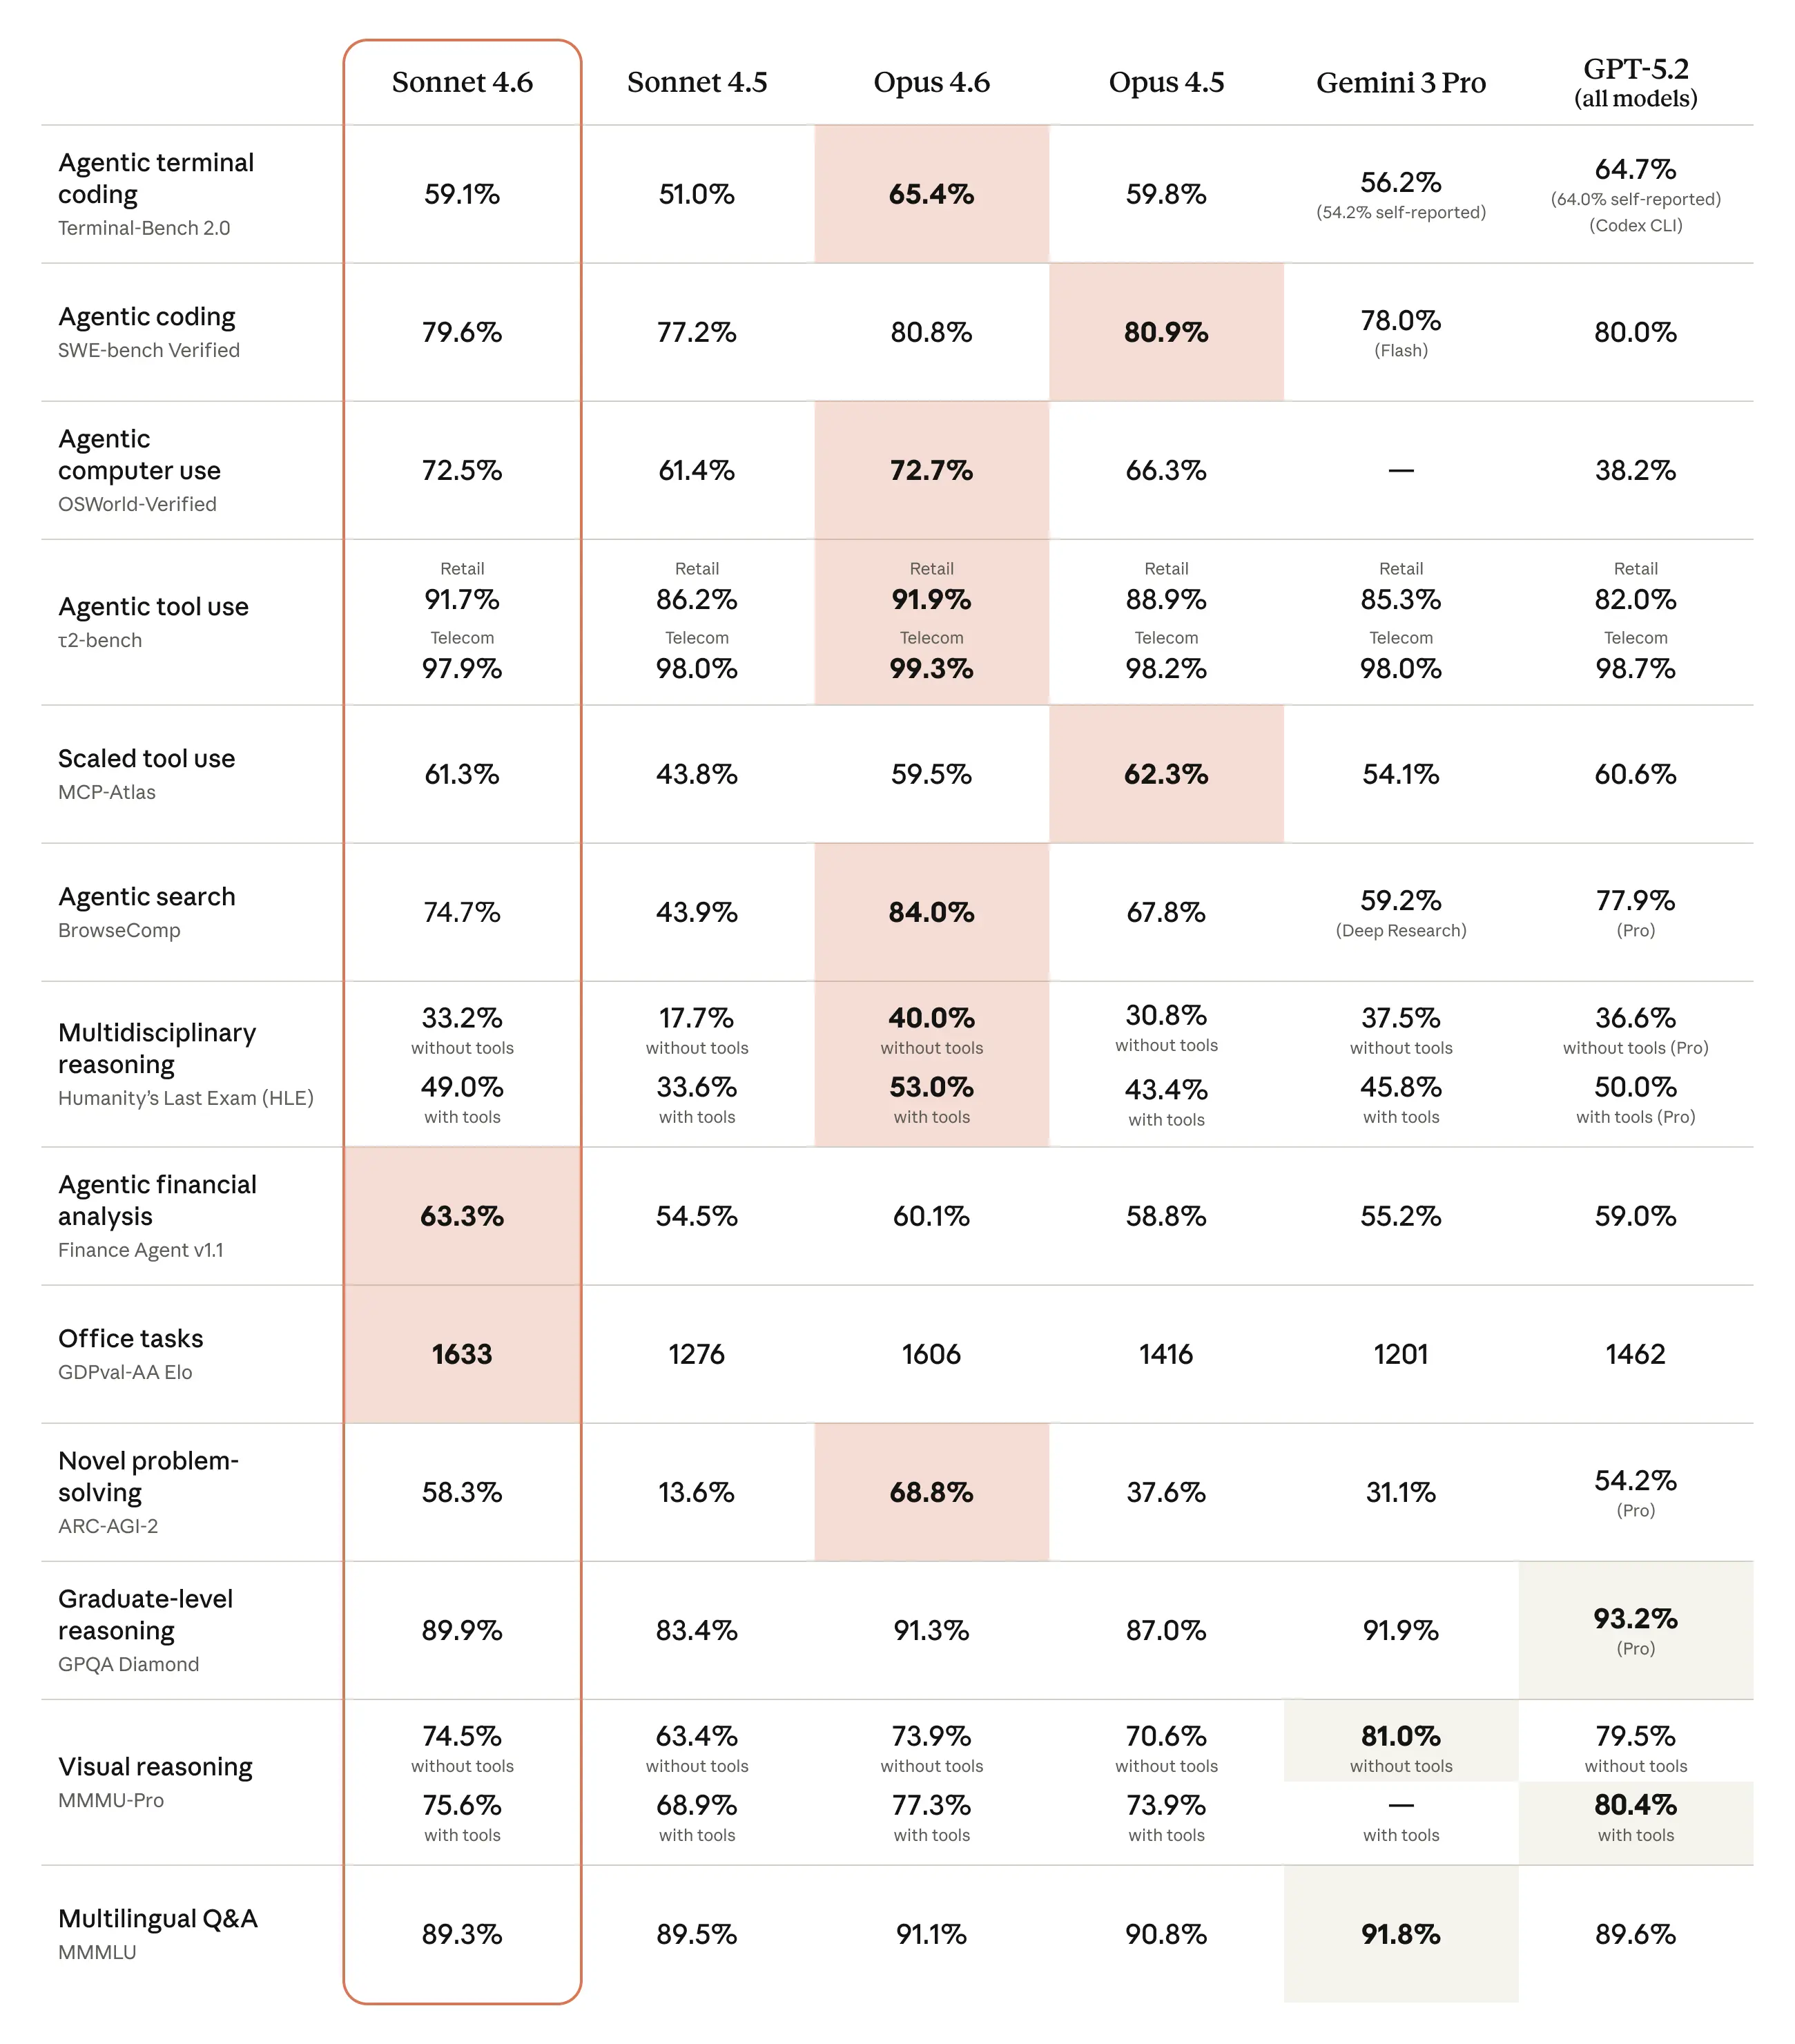
basically 9/13 are very close