News for hackers. Stuff that matters.
Re:Apple M3 Ultra by dheera on Wednesday March 05, 2025 @11:23AM (#43268692)
It will cost 4X what it costs to get 512GB on an x86 server motherboard.
Re:Apple M3 Ultra by valine on Wednesday March 05, 2025 @11:27AM (#43268746)
What would it cost to get 512GB of VRAM on an Nvidia card? That’s the real comparison.
Re:Apple M3 Ultra by zitterbewegung on Wednesday March 05, 2025 @11:49AM (#43269077)
Since the GH200 has over a terabyte of VRAM at $343,000 and the H100 has 80GB that makes that $195,993 with a bit over 512GB of VRAM . You could beat the price of the Apple M3 Ultra with an AMD EPYC build.
Re:Apple M3 Ultra by treesciencebot on Wednesday March 05, 2025 @06:38PM (#43274302)
GH200 is nowhere near $343,000 number. You can get a single server order around 45k (with inception discount). If you are buying bulk, it goes down to sub-30k ish. This comes with a H100's performance and insane amount of high bandwith memory.
Re:Apple M3 Ultra by wmf on Wednesday March 05, 2025 @06:45PM (#43274376)
They probably meant 8xH200 for $343,000 which is in the ballpark.
Re:Apple M3 Ultra by zitterbewegung on Wednesday March 05, 2025 @07:43PM (#43274757)
Yes this is what I meant since 8 would cover 512GB of Ram
Re:Apple M3 Ultra by dheera on Wednesday March 05, 2025 @11:35AM (#43268867)
Apples to oranges. NVIDIA cards have an order of magnitude more horsepower for compute than this thing. A B100 has 8 TB/s of memory bandwidth, 10 times more than this. If NVIDIA made a card with 512GB of HBM I'd expect it to cost $150K.

The compute and memory bandwidth of the M3 Ultra is more in-line with what you'd get from a Xeon or Epyc/Threadripper CPU on a server motherboard; it's just that the x86 "way" of doing things is usually to attach a GPU for way more horsepower rather than squeezing it out of the CPU.

This will be good for local LLM inference, but not so much for training.

Re:Apple M3 Ultra by pklausler on Wednesday March 05, 2025 @12:18PM (#43269477)
This prompts an "old guy anecdote"; forgive me.

When I was much younger, I got to work on compilers at Cray Computer Corp., which was trying to bring the Cray-3 to market. (This was basically a 16-CPU Cray-2 implemented with GaAs parts; it never worked reliably.)

Back then, HPC performance was measured in mere megaflops. And although the Cray-2 had peak performance of nearly 500MF/s/CPU, it was really hard to attain, since its memory bandwidth was just 250M words/s/CPU (2GB/s/CPU); so you had to have lots of operand re-use to not be memory-bound. The Cray-3 would have had more bandwidth, but it was split between loads and stores, so it was still quite a ways away from the competing Cray X-MP/Y-MP/C-90 architecture, which could load two words per clock, store one, and complete an add and a multiply.

So I asked why the Cray-3 didn't have more read bandwidth to/from memory, and got a lesson from the answer that has stuck. You could actually see how much physical hardware in that machine was devoted to the CPU/memory interconnect, since the case was transparent -- there was a thick nest of tiny blue & white twisted wire pairs between the modules, and the stacks of chips on each CPU devoted to the memory system were a large proportion of the total. So the memory and the interconnect constituted a surprising (to me) majority of the machine. Having more floating-point performance in the CPUs than the memory could sustain meant that the memory system was oversubscribed, and that meant that more of the machine was kept fully utilized. (Or would have been, had it worked...)

In short, don't measure HPC systems with just flops. Measure the effective bandwidth over large data, and make sure that the flops are high enough to keep it utilized.

Re:Apple M3 Ultra by worthless-trash on Wednesday March 05, 2025 @09:09PM (#43275509)
That is a great story. Please never hesitate to drop these in.

Do you have a blog?

Re:Apple M3 Ultra by musicale on Thursday March 06, 2025 @12:49AM (#43276826)
> so you had to have lots of operand re-use to not be memory-bound

Looking at Nvidia's spec sheet, an H100 SXM can do 989 tf32 teraflops (or 67 non-tensor core fp32 teraflops?) and 3.35 TB/s memory (HBM) bandwidth, so ... similar problem?

Re:Apple M3 Ultra by pklausler on Thursday March 06, 2025 @01:29AM (#43277059)
There is caching today.
Re:Apple M3 Ultra by ryao on Thursday March 06, 2025 @09:52AM (#43280896)
The cache hitrate is effectively 0 for LLMs since the datasets are so huge.
Re:Apple M3 Ultra by LeifCarrotson on Wednesday March 05, 2025 @12:15PM (#43269449)
Yep, it's apples to oranges. But sometimes you want apples, and sometimes you want oranges, so it's all good!

There's a wide spectrum of potential requirements between memory capacity, memory bandwidth, compute speed, compute complexity, and compute parallelism. In the past, a few GB was adequate for tasks that we assigned to the GPU, you had enough storage bandwidth to load the relevant scene into memory and generate framebuffers, but now we're running different workloads. Conversely, a big database server might want its entire contents to be resident in many sticks of ECC DIMMs for the CPU, but only needed a couple dozen x86-64 threads. And if your workload has many terabytes or petabytes of content to work with, there are network file systems with entirely different bandwidth targets for entire racks of individual machines to access that data at far slower rates.

There's a lot of latency between the needs of programmers and the development and shipping of hardware to satisfy those needs, I'm just happy we have a new option on that spectrum somewhere in the middle of traditional CPUs and traditional GPUs.

As you say, if Nvidia made a 512 GB card it would cost $150k, but this costs an order of magnitude less than that. Even high-end consumer cards like a 5090 have 16x less memory than this does (average enthusiasts on desktops have maybe 8 GB) and just over double the bandwidth (1.7 TB/s).

Also, nit pick FTA:

> Starting at 96GB, it can be configured up to 512GB, or over half a terabyte.

512 GB is exactly half of a terabyte, which is 1024 GB. It's too late for hard drives - the marketing departments have redefined storage to use multipliers of 1000 and invented "tebibytes" - but in memory we still work with powers of two. Please.

Re:Apple M3 Ultra by dheera on Wednesday March 05, 2025 @12:18PM (#43269479)
Sure, if you want to do training get an NVIDIA card. My point is that it's not worth comparing either Mac or CPU x86 setup to anything with NVIDIA in it.

For inference setups, my point is that instead of paying $10000-$15000 for this Mac you could build an x86 system for <$5K (Epyc processor, 512GB-768GB RAM in 8-12 channels, server mobo) that does the same thing.

The "+$4000" for 512GB on the Apple configurator would be "+$1000" outside the Apple world.

Re:Apple M3 Ultra by KingOfCoders on Wednesday March 05, 2025 @02:03PM (#43270754)
But this is how it wonderfully works. +$4000 does two things: 1. Make Apple very very rich 2. Make people think this is better than a $10k EPYC. Win-Win for Apple. At the point when you have convinced that you are the best, higher price just means people think you are even better.
Re:Apple M3 Ultra by kombine on Wednesday March 05, 2025 @06:21PM (#43274158)
An X86 server comparable in performance to M3 Ultra will likely be a few times more energy hungry, no?
Re:Apple M3 Ultra by MBCook on Thursday March 06, 2025 @12:14AM (#43276654)
> The "+$4000" for 512GB on the Apple configurator would be "+$1000" outside the Apple world.

That requires an otherwise equivalent PC to exist. I haven’t seen anyone name a PC with a half-TB of unified memory in this thread.

Yeah it’s $4k. Yeah that’s nuts. But it’s the only game in town like that. If the replacement is a $40k setup from Nvidia or whatever that’s a bargain.

Re:Apple M3 Ultra by egorfine on Wednesday March 05, 2025 @12:39PM (#43269711)
> we still work with powers of two. Please.

We do. Common people don't. It's easier to write "over half a terabyte" than explain (again) to millions of people what the power of two is.

Re:Apple M3 Ultra by johnklos on Wednesday March 05, 2025 @02:31PM (#43271131)
Anyone who calls 512 gigs "over half a terabyte" is bullshitting. No, thank you.
Re:Apple M3 Ultra by egorfine on Wednesday March 05, 2025 @03:02PM (#43271572)
Wasn't me.
Re:Apple M3 Ultra by egorfine on Wednesday March 05, 2025 @03:02PM (#43271571)
...aaand I'm being downvoted for pointing out apple's language and possible reason for its obvious factual incorrectness...
Re:Apple M3 Ultra by bick_nyers on Wednesday March 05, 2025 @12:32PM (#43269631)
About $12k when Project Digits comes out.
Re:Apple M3 Ultra by valine on Wednesday March 05, 2025 @01:26PM (#43270330)
That will only have 128GB of unified memory
Re:Apple M3 Ultra by dragonwriter on Wednesday March 05, 2025 @01:33PM (#43270421)
128GB for 3K; per the announcement their ConnectX networking allows two Project Digits devices to be plugged into eachother and work together as one device giving you 256GB for $6k, and, AFAIK, existing frameworks can split models across devices, as well, hence, presumably, the upthread suggestion that Project Digits would provide 512GB for $12k, though arguably the last step is cheating.
Re:Apple M3 Ultra by justincormack on Wednesday March 05, 2025 @02:58PM (#43271510)
the reason Nvidia only talk about two machines over the network is I think they only have one network port, so you need to add costs for a switch.
Re:Apple M3 Ultra by bick_nyers on Wednesday March 05, 2025 @03:13PM (#43271709)
If you want to split tensorwise yes. Layerwise splits could go over Ethernet.

I would be interested to see how feasible hybrid approaches would be, e.g. connect each pair up directly via ConnectX and then connect the sets together via Ethernet.

Re:Apple M3 Ultra by Cane_P on Thursday March 06, 2025 @09:49AM (#43280858)
It clearly have two ports. Just watch on the right side of the picture:

https://www.storagereview.com/wp-content/uploads/2025/01/Sto...
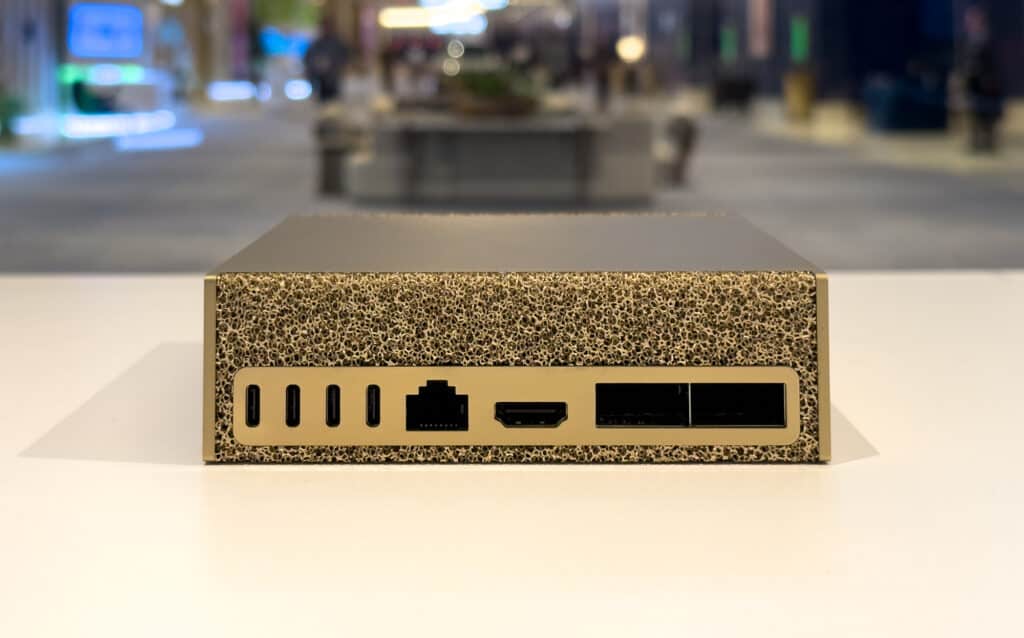
You will however get half of the bandwidth and a lot more latency if you have to go through multiple systems.

Re:Apple M3 Ultra by MBCook on Thursday March 06, 2025 @12:08AM (#43276627)
Apple is shipping today. No future promises.
Re:Apple M3 Ultra by matt-p on Wednesday March 05, 2025 @12:18PM (#43269487)
Not really like for like.

The pricing isn't as insane as you'd think, 96 to 256GB is 1500 which isn't 'cheap' but, it could be worse.

All in 5,500 gets you a ultra with 256GB memory, 28 cores, 60 GPU cores, 10Gb network - I think you'd be hard pushed to build a server for less.

Re:Apple M3 Ultra by kllrnohj on Wednesday March 05, 2025 @01:05PM (#43270056)
5,500 easily gets me either vastly more CPU cores if I care more about that or a vastly faster GPU if I care more about that. Or for both a 9950x + 5090 (assuming you can actually find one in stock) is ~$3000 for the pair + motherboard, leaving a solid $2500 for whatever amount of RAM, storage, and networking you desire.

The M3 strikes a very particular middle ground for AI of lots of RAM but a significantly slower GPU which nothing else matches, but that also isn't inherently the right balance either. And for any other workloads, it's quite expensive.

Re:Apple M3 Ultra by seanmcdirmid on Wednesday March 05, 2025 @01:09PM (#43270116)
You'll need a couple of 32GB 5090s to run a quantized 70B model, maybe 4 to run a 70b model without quantization, forget about anything larger than that. A huge model might run slow on a M3 Ultra, but at least you can run it all.

I have a Max M3 (the non-binned one), and I feel like 64GB or 96GB is within the realm of enabling LLMs that run reasonable fast on it (it is also a laptop, so I can do things on planes or trips). I thought about the Ultra, if you have 128GB for a top line M3 Ultra, the models that you could fit into memory would run fairly fast. For 512GB, you could run the bigger models, but not very quickly, so maybe not much point (at least for my use cases).

Re:Apple M3 Ultra by matt-p on Wednesday March 05, 2025 @01:47PM (#43270584)
That config would also use about 10x the power, and you still wouldn't be able to run a model over 32GB whereas the studio can easily cope with 70B llama and plenty of space to grow.

I think it actually is perfect for local inference in a way that build or any other pc build in this price range would be.

Re:Apple M3 Ultra by kllrnohj on Wednesday March 05, 2025 @01:50PM (#43270606)
The M3 Ultra studio also wouldn't be able to run path traced Cyberpunk at all no matter how much RAM it has. Workloads other than local inference LLMs exist, you know :) After all, if the only thing this was built to do was run LLMs then they wouldn't have bothered adding so many CPU cores or video engines. CPU cores (along with networking) being 2 of the specs highlighted by the person I was responding to, so they were obviously valuing more than just LLM use cases.
Re:Apple M3 Ultra by kridsdale1 on Wednesday March 05, 2025 @02:42PM (#43271298)
The core customer market for this thing remains Video Editors. That’s why they talk about simultaneous 8K encoding streams.

Apple’s Pro segment has been video editors since the 90s.

Re:Apple M3 Ultra by dagmx on Wednesday March 05, 2025 @08:14PM (#43275008)
Bad game example because cyberpunk with raytracing is coming to macOS and will run on this.
Re:Apple M3 Ultra by hot_gril on Wednesday March 05, 2025 @08:18PM (#43275052)
Well that's what (s)he meant, the Mac Studio fits the AI use case but not other ones so much.
Re:Apple M3 Ultra by jltsiren on Wednesday March 05, 2025 @09:52PM (#43275862)
Consumer hardware is cheap, if 192 GB of RAM is enough for you. But if you want to go beyond that, the Mac Studio is very competitively priced. A minimal Threadripper workstation with 256 GB is ~$7400 from Puget Systems. If you increase the memory to 512 GB, the price goes up to ~$10900. Mostly because 128 GB modules are about as expensive as what Apple charges for RAM. A Threadripper Pro workstation can use cheaper 8x64 GB for the same capacity, but because the base system is more expensive, you'll end up paying ~$11600.
Re:Apple M3 Ultra by TylerE on Thursday March 06, 2025 @02:36AM (#43277473)
The Mac almost fits in the palm of your hand, and runs, if not silently, practically so. It doesn't draw excessive power or generate noticeable heat.

None of those will be true for any PC/Nvidia build.

It's hard to put a price on quality of life.

Re:Apple M3 Ultra by smith7018 on Wednesday March 05, 2025 @11:26AM (#43268715)
You can build an x86 machine that can fully run DeepSeek R1 with 512GB VRAM for ~$2,500?
Re:Apple M3 Ultra by hbbio on Wednesday March 05, 2025 @12:07PM (#43269343)
How would you compare the tok/sec between this setup and the M3 Max?
Re:Apple M3 Ultra by aurareturn on Wednesday March 05, 2025 @01:06PM (#43270077)
3.5 - 4.5 tokens/s on the $2,000 AMD Epyc setup. Deepseek 671b q4.

The AMD Epyc build is severely bandwidth and compute constrained.

~40 tokens/s on M3 Ultra 512GB by my calculation.

Re:Apple M3 Ultra by hbbio on Wednesday March 05, 2025 @03:08PM (#43271645)
Thanks!

If the M3 can run 24/7 without overheating it's a great deal to run agents. Especially considering that it should run only using 350W... so roughly $50/mo in electricity costs.

Re:Apple M3 Ultra by aenis on Wednesday March 05, 2025 @11:40PM (#43276479)
Out of curiosity, if you dont mind: what kind of an agent would you run 24/7 locally?

I'd assume this thing peaks at 350W (or whatever) but idles at around 40w tops?

Re:Apple M3 Ultra by MBCook on Thursday March 06, 2025 @12:17AM (#43276663)
I’m guessing they might be thinking long training jobs as opposed to model use in an end product if done sort.
Re:Apple M3 Ultra by sgt on Wednesday March 05, 2025 @01:37PM (#43270459)
What kind of Nvidia-based rig would one need to achieve 40 tokens/sec on Deepseek 671b? And how much would it cost?
Re:Apple M3 Ultra by aurareturn on Wednesday March 05, 2025 @01:56PM (#43270691)
Around 5x Nvidia A100 80GB can fit 671b Q4. $50k just for the GPUs and likely much more when including cooling, power, motherboard, CPU, system RAM, etc.
Re:Apple M3 Ultra by SkiFire13 on Wednesday March 05, 2025 @04:01PM (#43272343)
How many tokens/s would that be though?
Re:Apple M3 Ultra by sgt on Thursday March 06, 2025 @01:46AM (#43277186)
That's what I'm trying to get to. Looking to set up a rig, and AMD Epyc seems reasonable but I'd rather go Mac if it's giving many more tokens per second. It does sound like the Mac with M3 Ultra will easily give 40 tokens/s, where as the Epyc is just internally constrained too much, giving 4-5 tokens/s but I'd like someone to confirm that, instead of buying the HW and finding out myself. :)
Re:Apple M3 Ultra by aurareturn on Thursday March 06, 2025 @10:19PM (#43287150)
Probably a lot more. Those are server-grade GPUs. We're talking prosumer grade Macs.

I don't know how to calculate tokens/s for H100s linked together. ChatGPT might help you though. :)

Re:Apple M3 Ultra by SkiFire13 on Saturday March 08, 2025 @05:51AM (#43299179)
Well, ChatGPT quotes 25k-75k tokens/s with 5 H100 (so very very far from the 40 tokens/s), but I doubt this is accurate (e.g. it completly ignored the fact they are linked together and instead just multiplied the estimation of the tokens/s for one H100 by 5).

If this is remotely accurate though it's still at least an order of magnitude more convenient than the M3 Ultra, even after factoring in all the other costs associated with the infrastructure.

Re:Apple M3 Ultra by sgt on Wednesday March 05, 2025 @03:17PM (#43271745)
So the M3 Ultra is amazing value then. And from what I could tell, an equivalent AMD Epyc would still be so constrained that we're talking 4-5 tokens/s. Is this a fair assumption?
Re:Apple M3 Ultra by Aeolun on Wednesday March 05, 2025 @05:18PM (#43273464)
The Epyc would only set you back $2000 though, so it’s only a slightly worse price/return.
Re:Apple M3 Ultra by adgjlsfhk1 on Wednesday March 05, 2025 @09:01PM (#43275428)
No. The advantage of Epic is you get 12 channels of ram so it should be ~6x faster than a consumer cpu.
Re:Apple M3 Ultra by sgt on Thursday March 06, 2025 @01:27AM (#43277040)
I realize that but apparently people are still getting very low tokens/sec on Epyc. Why is that? I don't get it, as on paper it should be fast.
Re:Apple M3 Ultra by wolfgangK on Wednesday March 05, 2025 @08:19PM (#43275058)
IMO, it would be more interesting to have a 3-way comparison of price/performance between DeepSeek 671b running on :

1. M3 Ultra 512 2. AMD Epyc (which Gen ? AVX512 and DDR5 might make a difference in both performance and cost , Gen 4 or Gen 5 have 8 or 9 t/s https://github.com/ggml-org/llama.cpp/discussions/11733 ) 2. AMD Epyc + 4090 or 5090 running KTransformers (over 10 t/s decode ? https://github.com/kvcache-ai/ktransformers/blob/main/doc/en...)

Re:Apple M3 Ultra by ta988 on Wednesday March 05, 2025 @11:37AM (#43268912)
You will have to explain to me how.
Re:Apple M3 Ultra by bmelton on Wednesday March 05, 2025 @11:58AM (#43269217)
Re:Apple M3 Ultra by muricula on Wednesday March 05, 2025 @03:17PM (#43271743)
Is that a CPU based inference build? Shouldn't you be able to get more performance out of the M3's GPU?
Re:Apple M3 Ultra by wmf on Wednesday March 05, 2025 @06:46PM (#43274388)
Inference is about memory bandwidth and some CPUs have just as much bandwidth as a GPU.
Re:Apple M3 Ultra by johnmaguire on Wednesday March 05, 2025 @11:53AM (#43269135)
Re:Apple M3 Ultra by AnthonBerg on Wednesday March 05, 2025 @12:35PM (#43269664)
That’s not going to yield the same bandwidth or memory latency though, right?
Re:Apple M3 Ultra by rbanffy on Wednesday March 05, 2025 @01:15PM (#43270178)
You'd need a chip with 8 memory channels. 16 DIMM slots, IIRC.