I like the Llama models personally. Meta aside. Qwen is fairly popular too. There’s a number of flavors you can try out. Ollama is a good starting point to try things quickly. You’re def going to have to tolerate things crashing or not working imo before you understand what your hardware can handle.
Their strategy is to sell lower-VRAM cards to consumers with the understanding that they can make more money on their more expensive cards for professionals/business. By doing this, though they're creating a gap in the market that their competitors could fill (in theory).
Of course, this assumes their competitors have half a brain cell (I'm looking at YOU, Intel! For fuck's sake give us a 64GB ARC card already!).
I use Firefox and have an 8Gb card and only encounter problems when I have more than about 125 windows with about 10-20 tabs each.
Yes, I am a tab hoarder.
And yes, I am going to buy a 16Gb card soon. :P
lol okay. "doing it wrong" for a tenth of the cost.
There's a reason large companies are buying H100s and not 4090s. Despite what you guys think, serious ML work isn't done on the consumer cards for many reasons: FP16/FP8 TFLOPS, NVLINK, power consumption, physical space, etc.
I know my 10 GB 3080 ran out of VRAM playing it on Ultra, and i was getting as low as 2 fps because I'm bottlenecked by the PCI-Express bus as it has to constantly page the entire working set of textures and models in and out.
I'm getting a 5090 for that, plus I want to play around with 7B parameter LLMs and don't want to quantize below 8 bits if I can help it.
And that's at 1440p, not even 4K. The resulting stutters are... not pretty.
One normally uses some ultra texture pack to utilize current gen card's memory fully on many games.
PC gamers would say that a modern mid-range card (1440p card) should really have 16GB of vram. So a 5060 or even a 5070 with less than that amount is kind of silly.
Conversely, this means you can pay less if you need less.
Seems like a win all around.
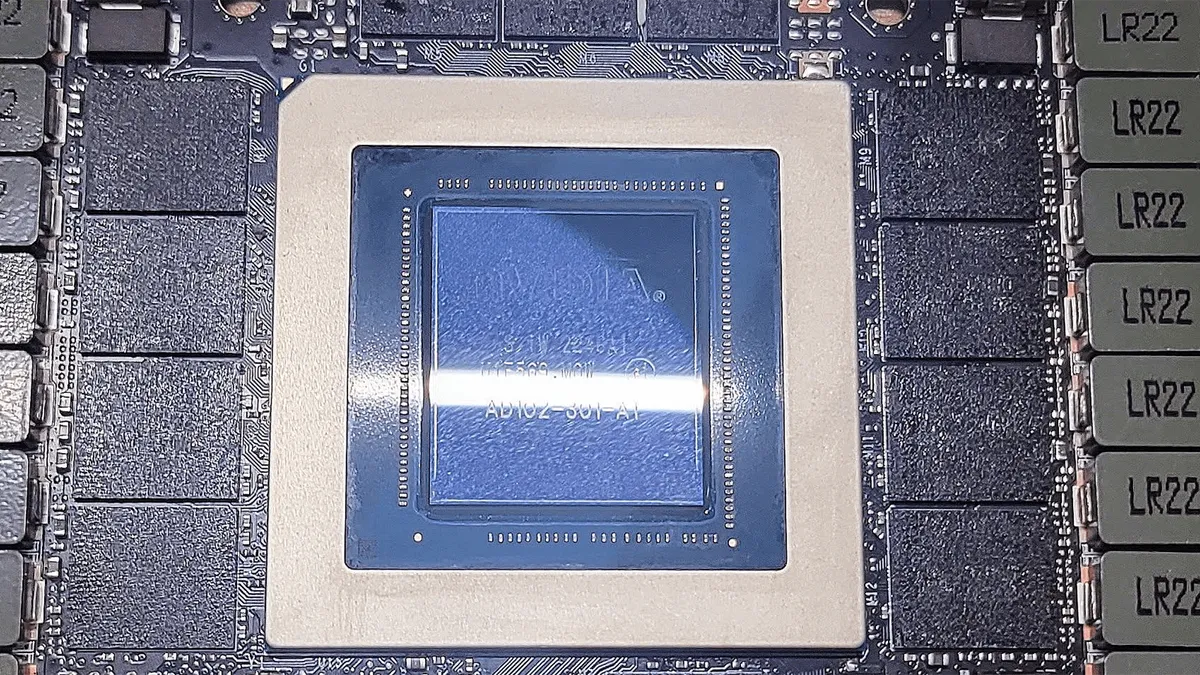
This isn't like a cutdown die, which is a single piece with disabled functionality...the memory chips are all independent (expensive) pieces soldered on board (the black squares surrounding the GPU core):
https://cdn.mos.cms.futurecdn.net/vLHed8sBw8dX2BKs5QsdJ5-120...
And yet it just so happens they work effectively the same. I've done research on an RTX 2070 with just 8 GB VRAM. That card consistently met or got close to the performance of a V100 albeit with less vram.
Why indicate people shouldn't use consumer cards? It's dramatically (like 10x-50x) cheaper. Is machine learning only for those who can afford 10k-50k USD workstation GPU's? That's lame and frankly comes across as gate keeping.
Honestly I can't really imagine how a person could reasonably have this stance. Just let folks buy hardware and use it however they want. Sure if may be less than optimal but it's important to remember that not everyone in the world has the money to afford an H100.
Perhaps you can explain some other better reason for why people shouldn't use consumer cards for ML? It's frankly kind of a rude suggestion in the absence of a better explanation.
Which may be true although there are more differences than just VRAM and I assume those market segments have different perceptions of the real value Gamers want it cheaper/faster, institutions want it closer to state of the art, more robust to lengthy workloads (as in year long training sessions), and better support from nvidia. Among other things.
For more of the fast VRAM you would be in Quadro territory.
These are monumentally different. You cannot use your computer as an LLM. Its more novelty.
I'm not even sure why people mention these things. Its possible, but no one actually does this out of testing purposes.
It falsely equates Nivida GPUs with Apple CPUs. The winner is Apple.
32 GB VRAM on the highest end GPU seems almost small after running LLMs with 128 GB RAM on the M3 Max, but the speed will most likely more than make up for it. I do wonder when we’ll see bigger jumps in VRAM though, now that the need for running multiple AI models at once seems like a realistic use case (their tech explainers also mentions they already do this for games).