I have one of these too... It's kind of frightening how hard ffmpeg is to use without some kind of custom frontend. I have probably dozens of bash/python scripts to invoke ffmpeg for different common tasks.
- One to extract audio
- One to extract all the individual streams from a container
- A couple different transcoding scripts
- One specifically for gifs
- One to crop video
- A few that I can't remember the purpose of... and can't tell from reading the source
With the exception of cropping I can do all of the above from memory. Maybe I just use ffmpeg a lot.
You could threaten to kill me and I wouldn't be able to user ffmpeg from memory. I just don't have to use it often enough. So I created a script w/ the settings I usually want to encode certain things that I need to encode semi-often. It definitely doesn't make it easier to remember ffmpeg command line options because I don't have to use them.
kubectl and our home grown command line tools to interact with our build and deployment? I know most of it by heart of course because I use it daily. I really don't like some of the scripts that we have and do it "by hand" instead because I have to use it all often enough that I want to know what is really going on underneath in case things don't go the way they should (and there's always something). I am able to diagnose and fix or work around all these issues with ease because of it, while lots of other people just run the wrapper scripts and if something doesn't work they very often aren't able to even troubleshoot the simplest problems. I'm that guy w/ ffmpeg ;)
They have these huge lists (written down in some tool or another) of commands to do specific things and they copy and paste them. It's heart wrenching to see them search for these sometimes (even if they find them) and then they copy and paste them. But they sometimes (many times) don't work or are super simple things. Like the `kubectl get pod` thing I mentioned, they might have that in one of those lists under some heading like "dev environment commands" or somesuch together with 10 or 15 others.
Because they never actually tried to understand the simple logic and meaning behind these command line tools and only ever copy and pasted, they get very easily tripped up by even the simplest things, such as replacing the parts that need to be adjusted for their specific situation, even if clearly marked, such as `kubectl -n <yournamespace> get pod` (or one that comes up even more often in troubleshooting sessions 'The command from the docs does not work and I made sure I copy and paste so I don't mistype it' and if you ask what they did it was `kubectl -n examplenamespace get pod`). Or they might have written down a command from the onboarding docs that combined multiple things into one command line. To fix issues with their environment, they have to basically nuke everything and start from scratch, because only then will their copy and pasted command actually work. They haven't learned to decompose these and use the parts individually or recompose them.
For me (and probably for GP), my cookbook is stuff that took me more than a few minutes of tinkering or reading manpages to figure out, and it’s stuff that I use maybe once every couple weeks — not often enough to memorize, and annoying if I have to figure it out again.
curl cht.sh/ffmpeg
That means you have to become an expert level user to become fluent (where the user would call it “easy”)
It’s an UX that would exclude entry level computer user (since entry level here means not even knowing where the shell is for ffmpeg) and would perhaps be a barrier intermediate computer users.
If you can remember 3 or 4 things you can do most stuff without looking anything up, however:
    -i -> input file
    -vcodec / -acodec -> video and audio codec; "copy" specifies copying the input stream
    -vn / -an / -sn -> disable the video / audio / subtitles in the output file
    -ss / -t -> specify the start time and length of the conversion from the input file
I certainly have. Interestingly, one was the same "sanity check" program for my internet connection, because of the same ISP you mention. Amazing coincidence...I don't think. :-)
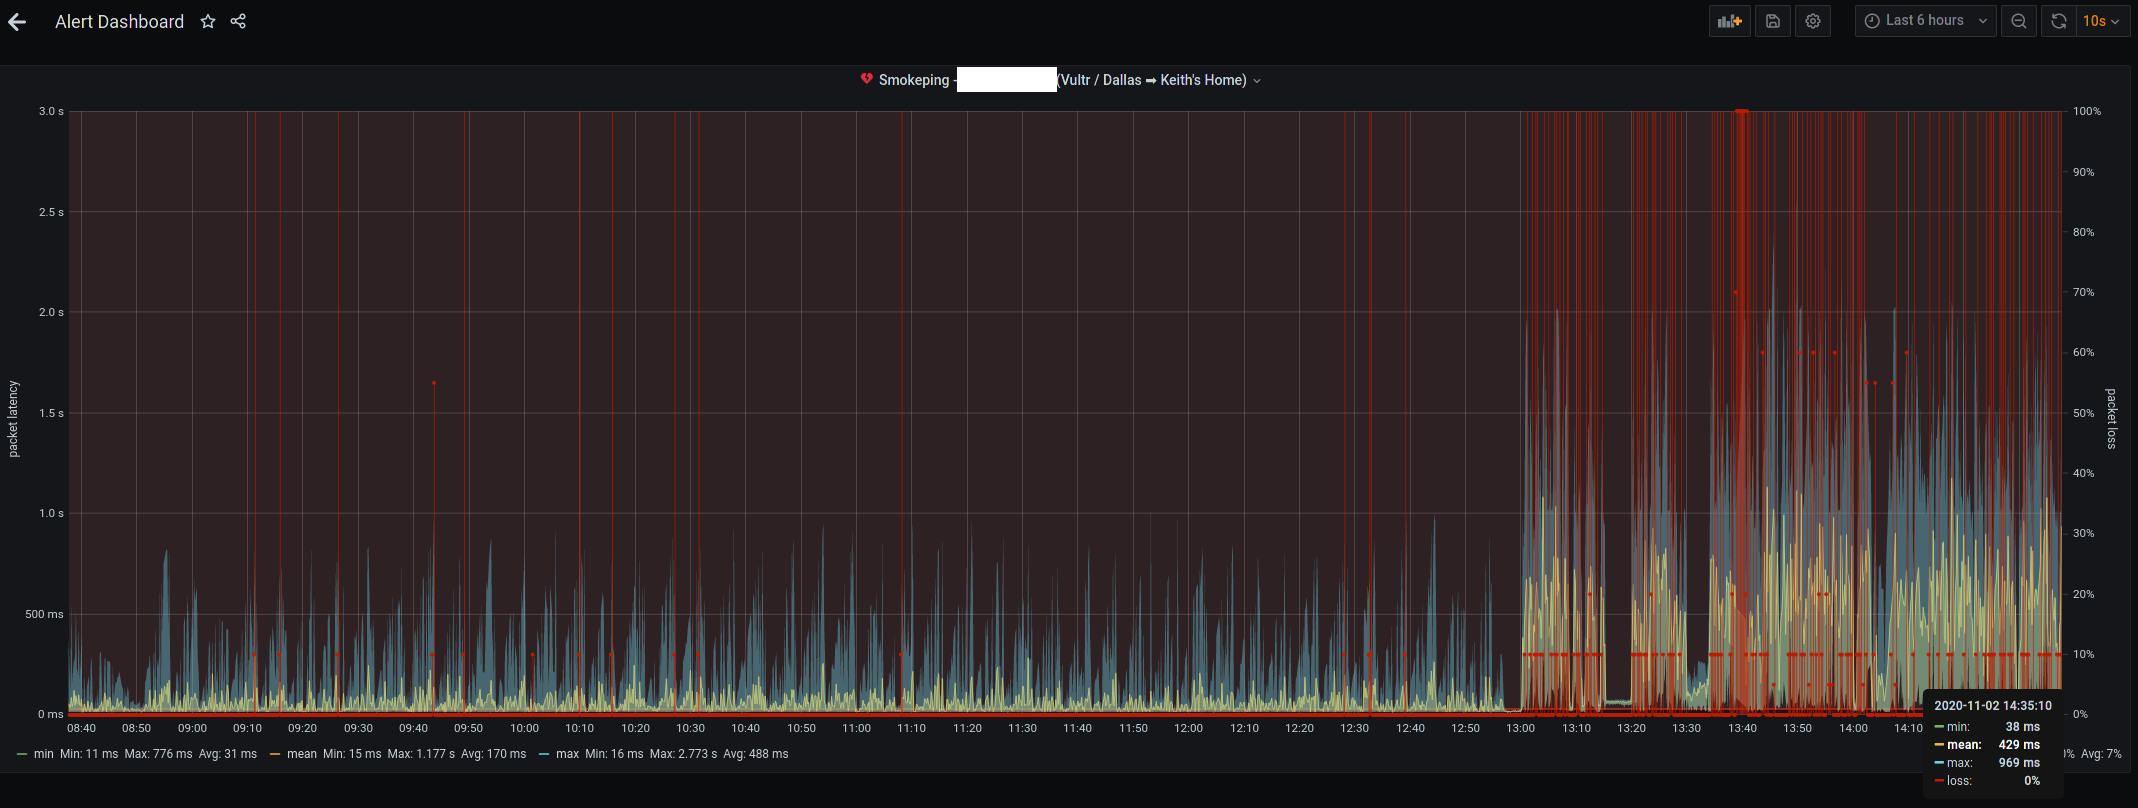
Here [0] is a screenshot of the Comcast cable connection from a year and a half ago. I have since switched to AT&T gigabit fiber. Here [1] is a screenshot from today.
[0]: https://knightoftheinter.net/img/20201102143900.png
[1]: https://knightoftheinter.net/img/Screenshot_20220413_171934....

Comcast "service" has probably driven the creation of more trivial internet connection test programs than any college course in the world.
Raising my hand in agreement!
A couple highlights:
- Video syncing library before those became cool (2014). Originally built on top of firebase; now rewriting with my own backend. Very slow going :)
- Twilio server + interface. I'm my own service provider (thanks to Twilio)
What does this mean? You run a pbx that implements twilio's apis and can be accessed via twilio's api endpoints? Or something else?
I run a server that lets me receive calls wherever I am (SIP or forwarding, as required) and send messages. Like a self-hosted Google Voice but more flexible and with a greater choice of numbers + forwarding destinations.
All my server does is respond to HTTP requests from Twilio and send HTTP requests when I send a message.
Somewhere in the Twilio interface, you can define a SIP endpoint, but I forget where it is. That's enough for placing calls and does not require running a server.
Almost forgot to mention that I receive text notifications via pushover because I am not an Apple developer ... so no app for me.
I suspect the venn diagram of that is very close to the venn diagram of hn readers and everybody else.
I think "doesn't everyone here" is implied there.
That would be the disagreement then I think: you and him have different models of the majority HN reader. Based on my experience in the industry and on hn, I also don't think the typical hn commenter represents the average technical employee. Perhaps the typical hn reader does, but then I have a lot less information about that group.
I don't think it's right to say he's "out of touch" for an off the hand remark like that, even regardless of this discussion.
e: also, there is a poll option for hn posts, it might be interesting to find out more about who does/doesn't do this.
I’m an engineer but I only write programs for money and not for myself
It's funny, I've never thought of doing this, but now realise it would be quite handy. Not just for connectivity but also some quick bandwidth/latency tests, and perhaps even a few basic internal network checks too.
The number of times I'm trying to troubleshoot Zoom calls these days... it would be handy to have a little bash script to run to rule out obvious issues.
For my specific use case, a big one would also be a quick automated check for whether my primary network connection is Wifi or Ethernet since I swap between the two and often forget which I'm currently using (which can impact connection quality if it's not the one I intended).
I have since ported over most of my common ones to this.
I love pronounceable passwords, but there's research indicating that such generators typically produce lower than expected entropy. Do you mind sharing what algorithm you use?
This representation is my favorite:
The 84-bit number 10231239242746186561668573 can be represented as: ...
In 12-bit words of 5 letters or less: hits towel bloke gala blah jimmy barry
Diceware is good too.
A word of warning: be careful playing around with stochastic text generation if you're susceptible to delusions and hallucinations. You'd have to be pretty far gone to think "hits towel bloke gala blah jimmy barry" was a message from God, but of course we all know people who have fallen into that kind of belief, and the strain on credulity gets smaller as the text model gets more sophisticated.
By contrast, trying every phrase of 20 words or less in every book that has ever been published would only take something like 129 million × 19 × 500,000 = 1.225 quadrillion tries. At a billion tries a second, that's only two weeks. (And if the password hash is inadequately salted, the attacker can use a rainbow table and put in that effort ahead of time and distribute it across all the victims.)
An attacker with more resources might devote a million CPUs to the problem, which would cut the time to success from 300 million years down to only 300 years (assuming a billion tries a second). In the next few decades it will become practical to devote much larger amounts of computation to problems like this, so such an attack might succeed, but currently it is beyond the capabilities of all but a few adversaries. And, as I understand it, Grover's algorithm will enable a large enough quantum computer to solve your password in only 2⁴² tries, which is only about four trillion tries, under an hour at the billion-tries-per-second speed I suggested above. I'm not sure, but I think it would need to prevent qubit decoherence for that period of time.
You can get equivalent security with a shorter password that looks like random gibberish, such as b7fc d750 9a52 ad6a e48c a, eedgckeimbjdefhcjclmghh, mgujdlrgdfmadtlidu, 1qvrx21zego0scvyi, 17uUPBKnfX7fSNY, >4h)&crV,+E{O, or 宜潨阰揫難侌, but those are a lot harder to memorize. They're shorter to type, though, and they're less vulnerable to side-channel attacks.
Looking random isn't good enough, though. They need to actually be random.
  #!/bin/bash
  pickaword() {
        WORDFREQFILE=/usr/share/dict/cracklib-small;
        WORDLENGTH=$1;
        awk -v wordlength="$WORDLENGTH" 'length($1) == wordlength {print $1}' "$WORDFREQFILE"|shuf|head -n 1;

    }
  [[ ! -z $1 ]] && numWords=$1 || numWords=4
  separator="-"
  count=0
  currentWord=""
  while [[ $count -lt $numWords ]]; do
    [[ $count != 0 ]] && echo -n $separator
    num=$((3 + RANDOM % 10))
    word=$(pickaword $num)
    echo -n "$word"
    count=$(($count + 1));
  done
  echo ""
Modulo operations like these are another thing to avoid. To get equal chances for each word, the simplest thing to do is e.g.
    do
      wordlistlength = 10e3
      randomnumber = os.urandom(1) * 256 + os.urandom(1)
    while randomnumber > wordlistlength
    return wordlist[randomnumber]
Further, I see that cracklib-small is 52k words. That's not good or bad, but it makes the default 4-word phrase 52e3⁴ ~ 63 bits of entropy, which isn't terrible but in my opinion on the short side as a default. It will be perfectly fine if you only ever want to defend against online attacks, but in some cases (think disk encryption or password manager) offline cracking should be kept in mind and for the rest you should usually use a password manager anyhow (so then memorability doesn't matter).
Or perhaps more succinctly: please don't roll your own crypto.
I understand that this is of course very unlikely to be abused if it's just for yourself and nobody knows of this weakness in your credentials (security through obscurity works... until it doesn't), but one day someone will use this as inspiration or it will spread somehow, say through an HN comment... just use good password generators or at least keep insecure ones secret.
Btw: many standard Debian(-based) installations have /usr/share/dict/words available so you don't need an extra install; I haven't seen cracklib used before but that might just be me.
Also, why do we avoid modulo operations?
$RANDOM provides 15 bits of randomness (32768 possible values) from an LCG[1] - https://en.wikipedia.org/wiki/Linear_congruential_generator
LCGs are multiply followed by add followed by modulus, which is usually implied by a mask or a native word bit length rolling over. You should observe that multiplies have patterns in the lower digits which an add will only offset, and the modulus will only throw away high bits rather than mix them back in to the low bits. Consider the low digit in multiples of 7 (what you'd get picking a number between 0 and 9 inclusive via modulus):
    7 -> 7
   14 -> 4
   21 -> 1
   28 -> 8
   35 -> 5
   42 -> 2
   49 -> 9
   56 -> 6
   63 -> 3
   70 -> 0
   77 -> 7
   84 -> 4
   91 -> 1
   98 -> 8
  105 -> 5
  112 -> 2
  119 -> 9
  126 -> 6
  133 -> 3
  140 -> 0
But again, don't use an LCG for generating your password.
[1] I looked at the source. Bash looks like it tries to use random(3) if it's available, otherwise it seems to use this, which doesn't have an add:
x(n+1) = 16807 * x(n) mod (m)- It contains unusual proper names such as della, ervin, eaton, moran
- It contains a few strange letter sequences such as aaaa, ll, nbis
- It contains some words with punctuation such as ain't, don't, he'll
- It contains individual letters and non-word bigrams like tl, wq, zf
- It contains numbers and variants such as 46, 99 and 99th
- It contains many vulgar words
- Diceware passwords need spaces to be correctly decoded, e.g. in and put are in the list as well as input
[1] https://www.eff.org/deeplinks/2016/07/new-wordlists-random-p...
I think you copy-pasted it from elsewhere on HN, causing the end to be cut off.
Actually, I do mind. And so should you! I developed it myself, however, and feel reasonably confident about it.
Note that this advice is for the average, common site. If you have special considerations for your bank, broker, or similarly high-value sites, different advice might apply of course (but this is not really the place for that and there are already enough recommendations online).
I wonder which way round is actually the right way to say it?
    with open('/dev/urandom', 'rb') as f:
return base64.urlsafe_b64encode(f.read(12)) </dev/urandom tr -dc a-zA-Z0-9 | head -c 16
Security level: log((26+26+10)¹⁶)/log(2) ~ 2⁹⁵ (95 bits of entropy), comparable with adding those 12 extra symbols: log((26+26+10+12)¹⁶)/log(2) ~ 2⁹⁹. (Adding a character makes more sense than adding a symbol if you want more security, all else being equal of course.) If a stupid application still has outdated password requirements (thankfully this is rare among the applications I use) then one can of course add the classic ! at the end.
cat /usr/share/dict | shuf -n 4 | tr '\n' '-'
> Please don't use $RANDOM or $((RANDOM)) or standard `shuf` for password generation. These RNGs are not cryptographically secure. Use input from /dev/urandom instead.
The same with gshuf.
I use an alias to add this switch by default.
(Sorry I had to)
Could you elaborate on this? I feel like this is something that could save people hours of time. I'm so incredibly sick of the various decompression flags and tools, (de)compressing something on the commandline should be as easy as it is with a GUI.
tar xzvf "extract ze vucking files"
Off the top of my head, the most used ones are:
* A replacement front-end for "tar" and various compressors
* A script to synchronize my music library to a compressed version for playing in my car
* A secure-but-readable password generator
* A system to batch compress folders full of video files. (For ripped blu-ray discs, mostly.)
* A replacement front-end for "ffmpeg", see above
* A "sanity check" program for my internet connection to see if the problem is me, or Comcast
* A front-end for "rm" that shows a progress bar when deleting thousands of files. (Deletes on ZFS are unusually slow.)
And lots more tiny things.