News for hackers. Stuff that matters.
Re:How can you be fooled by the U+202E trick? (2013) by klabb3 on Wednesday February 16, 2022 @12:38AM (#30356733)
With most attack vectors, like buffer overflows, csrf, SQL injection, I (and many developers that aren't security domain experts) am acutely aware of best practices and mitigations. I know exactly where they can appear and how to prevent them. (Well not literally but it's a simple web search away).

With unicode, I really don't know what to do. What strings need to be sanitized (or validated)? File names? Urls? How do I sanitize them without causing agony for most of the world? Are there other unicode attack vectors?

Re:How can you be fooled by the U+202E trick? (2013) by cryptonector on Wednesday February 16, 2022 @01:27AM (#30356937)
For starters, there's the Unicode Technical Report (UTR) #36 [0], "Unicode Security Considerations". It covers this particular issue in section 2.5 [1].

The general answer is to not allow (e.g., ignore it, remove it, but do not render it) in any identifiers, filenames, domainname labels, usernames, and other security-sensitive strings, U+202E between characters of scripts that are not bi-directional and which flow in the same direction. More generally, do not allow mixing of scripts in certain contexts -- for example, do not allow mixed scripts in a single domainname label. Some of these rules need to be implemented by, e.g., DNS registries, and may need to be tailored to their specific needs (e.g., you might find that .kr has to allow mixing of ASCII letters and Hangul characters because it's common in South Korea to add "ing" to names to make brands out of them).

UTR #36 doesn't go far enough, in my opinion.

  [0] https://unicode.org/reports/tr36/
  [1] https://www.unicode.org/reports/tr36/#Bidirectional_Text_Spoofing
Re:How can you be fooled by the U+202E trick? (2013) by chrismorgan on Wednesday February 16, 2022 @01:48AM (#30357023)
It should be noted that the problems of U+202E and such are not inherent to all Bidi_Control characters: Right-to-Left Marker, Left-to-Right Marker and Arabic Language Marker are all safe (and useful)—though UTR #36 suggests going far enough (e.g. “use only LTR or RTL, and if RTL, first and last characters must be strong”) that they wouldn’t be useful. It’s specific to the characters that override the default stuff, which means Embedding, Isolate and Override characters.

The Trojan Source paper has a decent treatment of the area too, seen in a different application: https://trojansource.codes/trojan-source.pdf.

Re:How can you be fooled by the U+202E trick? (2013) by phkahler on Wednesday February 16, 2022 @06:39AM (#30358747)
The problem seems to be that Unicode has gone a bit too far. No need to have the ability to do this.
Re:How can you be fooled by the U+202E trick? (2013) by dtech on Wednesday February 16, 2022 @08:15AM (#30359552)
The need seems quite obvious when mixing LTR and RTL languages, e.g. embed an American company or English phrase in a RTL language text.
Re:How can you be fooled by the U+202E trick? (2013) by phkahler on Wednesday February 16, 2022 @09:17AM (#30360223)
Why does it need to overwrite or obscure existing characters?
Re:How can you be fooled by the U+202E trick? (2013) by _nalply on Wednesday February 16, 2022 @04:03PM (#30365641)
The Right-To-Left Override (U+202E) does not obscure nor overwrite existing characters. It is an instruction to switch the text direction to right-to-left like for Arabic and Hebrew.

In the article it is shown how this can be misused to show executable files as a different file type:

    file[U+202e]fdp.exe shown as fileexe.pdf
        ~~~~~~~~^^^^^^^
           |       |--- read this right-to-left, i.e. exe.pdf     
           |----------- this is the Unicode character Right-To-Left Override
Re:How can you be fooled by the U+202E trick? (2013) by kazinator on Wednesday February 16, 2022 @06:08PM (#30367116)
It certainly obscures and overwrites. When you replace "fdp.exe" by "exe.pdf", you're obscuring and overwriting the leading "f" by "e", then the "d" by "x" and so on.
Re:How can you be fooled by the U+202E trick? (2013) by dtech on Thursday February 17, 2022 @03:52PM (#30378493)
It doesn't overwrite or obscure, it switches rendering direction. E.g. \u202E\u41\u42\u43 starts outputting from the right: \u41 from the right, then 42, then 43. That's CBA, altough in normal English you'd render that as ABC.
Re:How can you be fooled by the U+202E trick? (2013) by jrochkind1 on Wednesday February 16, 2022 @08:08AM (#30359481)
More programming languages/platforms need to include built-in routines for various kinds of unicode sanitization.
Re:How can you be fooled by the U+202E trick? (2013) by kazinator on Wednesday February 16, 2022 @06:10PM (#30367127)
Or maybe Unicode shouldn't include this crap in the first place?

If you "sanitize" Unicode you're just removing that functionality. Remove that character, and the right to left reversal wont' be there, right?

If you have to break it in the name of security and sanity, it shouldn't exist in the first place.

Re:How can you be fooled by the U+202E trick? (2013) by jrochkind1 on Wednesday February 16, 2022 @07:30PM (#30367911)
The functions/codepoints are there for reasons. If you want to research the reasons and decide that text processing doens't need them, that's one thing. But to simply dismiss it off-hand with the argument "if you have to remove it for security it shouldn't exist in the first place" is just ridiculous. It's like saying "if you have to properly escape parameters in SQL to avoid injection attacks, SQL shouldn't exit in the first place!"

I am continually baffled about why the HN comment sections are such a hotbed of anti-unicode sentiment. Perhaps most of y'all don't have to write software that deals with non-English text in any significant way.

If you just didn't have buffers you wouldn't have to avoid buffer overflow attacks! Come on.

Re:How can you be fooled by the U+202E trick? (2013) by kazinator on Wednesday February 16, 2022 @08:04PM (#30368285)
> if you have to properly escape parameters in SQL to avoid injection attacks, SQL shouldn't exit in the first place!"

Yes, this aspect of SQL is poorly conceived because the only way is to manipulate it with text processing.

Parameters should be inserted into a query language using AST manipulation, like a Lisp backquote.

Now within a particular program, we can wrap something like that around SQL generation, and solve the escaping problems in one place.

That approach doesn't apply to character data, which has to be literal and primitive in many situations.

Re:How can you be fooled by the U+202E trick? (2013) by cryptonector on Wednesday February 16, 2022 @10:22AM (#30361091)
Yes.
Re:How can you be fooled by the U+202E trick? (2013) by rich_sasha on Wednesday February 16, 2022 @03:02AM (#30357445)
It feels like the whole “everything is Unicode now” movement was misguided to me.

Some things are meant to be simple, and Unicode is massively complex. True, these are rare-ish corner cases, but every programmer knows it’s only ever a matter of time until you hit any possible corner case.

I’m not saying, screw people whose languages don’t fit into ASCII (I’m one of them btw), but I really don’t want to know the vagaries of Unicode representation to inspect a file name.

Maybe Unicode needs a “safe mode” where only outright characters are allowed? Or maybe the unavoidable complexity is a design flaw, for some uses anyway.

I feel like we’re close to someone discovering Unicode is Turing-complete...

Re:How can you be fooled by the U+202E trick? (2013) by ajuc on Wednesday February 16, 2022 @06:03AM (#30358508)
The problem in this case was that we depend on convention (filenames and extensions) for security.

Operating system should already know if a file is executable and desktop should be using this information when presenting files instead of conventional names.

Yes it would mean that when you download a file you have to set the executable attribute before you can run it. It's already almost exactly like that on Linux. That's a good thing.

Re:How can you be fooled by the U+202E trick? (2013) by thaumasiotes on Wednesday February 16, 2022 @06:21AM (#30358629)
> Operating system should already know if a file is executable and desktop should be using this information when presenting files instead of conventional names.

That already happens. If you set the "Details" view in Windows, it will display one file per row with various columns showing file metadata, including the file type. So for the example in the post, you'd see "[Word icon] annexe.doc - [the date] - Application" as opposed to "[Word icon] annexe.doc - [the date] - Microsoft Word 97 - 2003 Document".

Re:How can you be fooled by the U+202E trick? (2013) by ajuc on Wednesday February 16, 2022 @06:38AM (#30358741)
I meant more like huge red and green exclamation mark near the file icon, not "type: Application" hidden in rarely shown places.

In linux it's pretty obvious: https://www.rootusers.com/wp-content/uploads/2018/01/gnome-t...
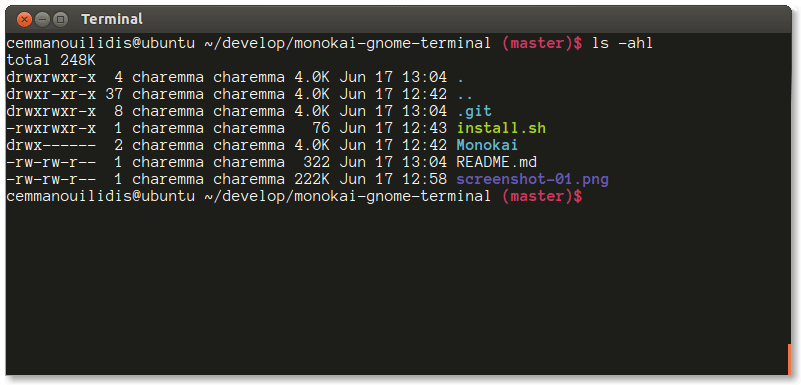
The main advantage is that the UI for opening documents (vim file) is different from the UI for running executables (./file) which is different from the UI for running executables as administrator (sudo ./file).

This makes it impossible to accidentally execute a file that looks like a document.

Re:How can you be fooled by the U+202E trick? (2013) by trasz on Wednesday February 16, 2022 @07:13AM (#30359014)
On Linux you have another problem though: you can have several files with the exact same name, just encoded differently.
Re:How can you be fooled by the U+202E trick? (2013) by jcelerier on Wednesday February 16, 2022 @07:53AM (#30359367)
As a desktop user, it makes me physically ill everytime I have to do that. I'd honestly pay for someone to make auto-executing the default on most common Linux distros. Like, in 20+ years of using computers, I don't remember one time where I downloaded something and did not want to run it afterwards.
Re:How can you be fooled by the U+202E trick? (2013) by loudmax on Wednesday February 16, 2022 @08:40AM (#30359757)
Fortunately for the rest of us, common Linux distro maintainers have a better understanding of security than you appear to.

If I download a pdf, I don't want it to run. I probably want to open it, but if I've gone through the trouble of downloading it onto the filesystem as opposed to just opening it in the web browser, there may be other things I want to do with it. Maybe I want to print it, or maybe I want to break it up into component parts. Or maybe I want to transfer it to a sandboxed environment before I open it because I don't trust it.

If you don't want to take an active role in maintaining security on your computer, then by all means use a commercial operating system. Pay a license and let Microsoft and Apple make those decisions for you. They have competent people who can program reasonable default settings for the average user. If you're running Linux or an open source operating system, you've already decided to take these responsibilities into your own hands.

Re:How can you be fooled by the U+202E trick? (2013) by jcelerier on Wednesday February 16, 2022 @09:49AM (#30360640)
> If you don't want to take an active role in maintaining security on your computer, then by all means use a commercial operating system. Pay a license and let Microsoft and Apple make those decisions for you. They have competent people who can program reasonable default settings for the average user. If you're running Linux or an open source operating system, you've already decided to take these responsibilities into your own hands.

That is a beyond ridiculous take. The last Windows OS that did not make me mad was Win98, and every time I have to use Mac machines I want to gouge my eyeballs out. I want an OS that lets me shoot myself in the foot as much as I want.

> If you're running Linux or an open source operating system, you've already decided to take these responsibilities into your own hands.

no, I just want to use the fastest possible OS for my use case on my hardware, which is Linux.

Re:How can you be fooled by the U+202E trick? (2013) by devit on Wednesday February 16, 2022 @08:31AM (#30359678)
Here's a gift for you:

inotifywait -m -e create "$(xdg-user-dir DOWNLOAD)"|while read d e f; do chmod +x "$d/$f"; done

You can add "-r" if you want to also do it on subdirectories, and you can specify another directory instead of the default downloads directory.

Though I don't really recommend doing this since you should not be executing downloaded binaries often enough for this to be worth doing.

Re:How can you be fooled by the U+202E trick? (2013) by jcelerier on Wednesday February 16, 2022 @09:47AM (#30360614)
> Though I don't really recommend doing this since you should not be executing downloaded binaries often enough for this to be worth doing.

I literally do this multiple times per day. What in hell do you folk do with your computers?

Thanks for the script ! There's a few tens of thousands of files in my downloads folder, I hope this isn't going to pollute the inotify fds too much...

Re:How can you be fooled by the U+202E trick? (2013) by assbuttbuttass on Wednesday February 16, 2022 @09:56AM (#30360751)
I usually install programs through the distro package manager. Out of curiosity, what are you doing that requires downloading so many executables from the web?
Re:How can you be fooled by the U+202E trick? (2013) by pixl97 on Wednesday February 16, 2022 @10:48AM (#30361504)
>requires downloading so many executables from the web?

Hopefully not leaking company information to clever attackers.

I work with a number of clients in high security environments where you have to get permissions to perform operations like execution (or even setting chmod x on a file). It really does limit people running random things and causing destruction.

Re:How can you be fooled by the U+202E trick? (2013) by alpaca128 on Wednesday February 16, 2022 @11:24AM (#30361991)
When you seriously download and run multiple executables a day I wouldn't call that a common use-case. At least 99.9% of my downloaded files are not executables. Those are usually pulled via the package manager or git, so basically I only download an AppImage if both the repos and flatpak can't install it.

I have no idea in what situation I'd need to load so many executables via the browser.

Re:How can you be fooled by the U+202E trick? (2013) by jcelerier on Thursday February 17, 2022 @05:53AM (#30371749)
I mostly use appimages
Re:How can you be fooled by the U+202E trick? (2013) by marcosdumay on Wednesday February 16, 2022 @10:47AM (#30361491)
I can't remember the last time I had to do it. Not on the last 4 years for sure.

Executables tend to come compressed with a lot of other files nowadays, and compression software knows to set the executable bit when extracting them.

Re:How can you be fooled by the U+202E trick? (2013) by thfuran on Wednesday February 16, 2022 @08:21AM (#30359597)
You've never in your life acquired an image or text document from the internet?
Re:How can you be fooled by the U+202E trick? (2013) by jcelerier on Wednesday February 16, 2022 @09:46AM (#30360592)
when I do my OS has no trouble opening them in my image or text viewer. The issue is when I download something that should be executable, and I have to paintaskingly open a terminal, and

    cd ~/Téléchargements; chmod +x <try to remember the first letter><hit tab 15 times><miss it><go check inside the firefox download manager><restart><end up typing the whole name> 
before being able to run it.
Re:How can you be fooled by the U+202E trick? (2013) by armada651 on Wednesday February 16, 2022 @10:28AM (#30361193)
This seems like more of a UI issue than anything. Could be fixed by simply presenting the user with a prompt asking whether they want to allow this file to execute as a program if it's missing the permissions.
Re:How can you be fooled by the U+202E trick? (2013) by kazinator on Wednesday February 16, 2022 @06:12PM (#30367161)
Honoring that right-to-left reversal character is also a "UI Issue".

The Windows UI could just render that character as a tofu box, and not evoke its reversal semantics.

Re:How can you be fooled by the U+202E trick? (2013) by ajuc on Wednesday February 16, 2022 @10:33AM (#30361269)
This is bad for variety of reasons.

Consider writing a bash script that makes a subdirectory with current date if it doesn't exist, downloads url from the command line argument into that directory, changes the permissions and runs it.

Then your workflow could be:

- keep terminal open

- Alt+tab to firefox, browse, copy link to executable file

- Alt+tab to terminal, ./handle.sh <paste the link> ENTER

- Alt+tab to firefox again

- rinse and repeat

There's many benefits - you don't get thousands of files in one directory (which can lead to performance degradation and even random errors), there's little risk that you run the wrong file, you don't waste as much time.
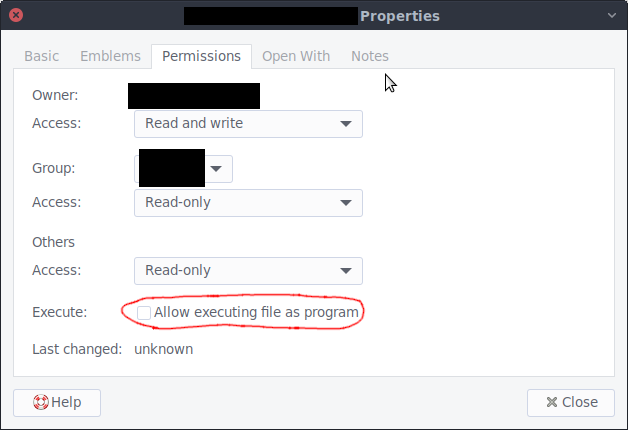
Re:How can you be fooled by the U+202E trick? (2013) by 6yyyyyy on Wednesday February 16, 2022 @12:48PM (#30363149)
No need to open a terminal

https://files.catbox.moe/tkefli.png

Re:How can you be fooled by the U+202E trick? (2013) by jcelerier on Wednesday February 16, 2022 @04:27PM (#30365940)
the idea of having to go in those damned menus one more time just to launch an app sends shivers down my spine. I already barely tolerate windows and macOS's prompts when downloading executables.
Re:How can you be fooled by the U+202E trick? (2013) by marcosdumay on Wednesday February 16, 2022 @10:43AM (#30361416)
Hum... How do you run it?

If it's from a GUI, file browsers have the capacity to that that bit too.

Re:How can you be fooled by the U+202E trick? (2013) by dotancohen on Wednesday February 16, 2022 @04:31AM (#30357940)

  > Maybe Unicode needs a “safe mode” where only outright characters are allowed?
What is safe for me may not be safe for you. I need RLM characters in my terminal emulator [1], you probably don't. And who knows, maybe RLM characters could prove to be an attack vector, by e.g. displaying filenames or other text backwards.

Every Unicode character and code point exists because somebody, somewhere, needs it.

[1] https://bugs.kde.org/show_bug.cgi?id=450219

Re:How can you be fooled by the U+202E trick? (2013) by kazinator on Wednesday February 16, 2022 @06:16PM (#30367186)
> Every Unicode character and code point exists because somebody, somewhere, needs it.

Not quite. That and because some twits are willing to cave in and add it, because adding crap to Unicode gives them a sense of purpose which makes them blind to the harm they are causing.

Re:How can you be fooled by the U+202E trick? (2013) by mtizim on Wednesday February 16, 2022 @05:35AM (#30358340)
I highly doubt that last statement is true: 𓂺, ꙮ, 𒀱 .
Re:How can you be fooled by the U+202E trick? (2013) by dtech on Wednesday February 16, 2022 @08:21AM (#30359592)
You can definitely argue about whether Unicode should support long-dead or undeciphered languages, but those aren't the characters that cause problems in practice, or at least not more than any random emoji would and those have been embraced with fervor.
Re:How can you be fooled by the U+202E trick? (2013) by tragomaskhalos on Wednesday February 16, 2022 @07:50AM (#30359349)
Egyptologists would disagree re your first there: it is D53 in the Gardiner sign list, used to spell words including 'urinate', 'poison', 'husband' and 'in the presence of' !
Re:How can you be fooled by the U+202E trick? (2013) by dotancohen on Wednesday February 16, 2022 @05:54AM (#30358462)
Point taken! I rephrase:

Every Unicode character and code point exists because somebody, somewhere, thought that somebody would find it useful.

Re:How can you be fooled by the U+202E trick? (2013) by thaumasiotes on Wednesday February 16, 2022 @06:13AM (#30358578)
That isn't true either; many Unicode characters exist solely because they were part of some other encoding standard that Unicode preserved in its entirety. For example, all of ASCII is preserved in that way. That's also why 囍, a character which does not have any linguistic use, is in there - it was included in an earlier Chinese encoding standard. Nobody thinks it was a good idea to separate U+2126 OHM SIGN from U+03A9 GREEK CAPITAL LETTER OMEGA either.
Re:How can you be fooled by the U+202E trick? (2013) by wzdd on Wednesday February 16, 2022 @07:02AM (#30358928)
Is that true? It seems like screen readers would benefit from knowing the difference between Ohms and Omega, particularly if the surrounding text is in Greek.
Re:How can you be fooled by the U+202E trick? (2013) by thaumasiotes on Wednesday February 16, 2022 @09:16AM (#30360206)
> It seems like screen readers would benefit from knowing the difference between Ohms and Omega, particularly if the surrounding text is in Greek.

Sure, just like they benefit from knowing the difference between 'V' and volts; 'J' and Joules; 'K' and Kelvins; 'A' and Amperes; π the letter, π the circle constant, and π the exotic particle; 'm', meters, and mass; 's', seconds, and position; 'g', grams, and gravity...

假設所有的意義都有自己的符號,那就太好啊

Re:How can you be fooled by the U+202E trick? (2013) by projektfu on Wednesday February 16, 2022 @07:50AM (#30359350)
What is the likelihood that a Greek article about electronics would use the Ohm sign when the Omega is right there on the keyboard?
Re:How can you be fooled by the U+202E trick? (2013) by dotancohen on Wednesday February 16, 2022 @08:24AM (#30359621)
English language physics texts routinely use the proper symbols, despite the fact that e.g. V is right there on the keyboard.
Re:How can you be fooled by the U+202E trick? (2013) by thaumasiotes on Wednesday February 16, 2022 @09:05AM (#30360074)
Omega is the proper symbol for Ohms. English-language physics texts use V when they're denominating in volts, too.
Re:How can you be fooled by the U+202E trick? (2013) by klabb3 on Wednesday February 16, 2022 @03:14PM (#30365095)
So there is no "v that signals the author knows some trivia"? Disappointed.
Re:How can you be fooled by the U+202E trick? (2013) by dtech on Wednesday February 16, 2022 @08:18AM (#30359572)
In order to be in the original encoding standard somebody thought it was useful at some point
Re:How can you be fooled by the U+202E trick? (2013) by hnfong on Thursday February 17, 2022 @12:07AM (#30369711)
囍 is a really bad example of Unicode bloat since it's actually used very frequently.

The real issue are the thousands of characters that appeared incidentally in some ancient text, either as typo or as a weird interpretation of a common character, which then ended up in the Kangxi dictionary, and then subsequently imported en-masse into Unicode.

Example, 𠒇 - the only known use (in non-ancient times) of this character was being the official name of 雷莊𠒇, winner of the 2017 Miss Hong Kong Pageant. According to her, she intended to write 雷莊兒 when she applied for her official documents, but somehow the officials interpreted it as 𠒇, which is really an archaic form of 兒 (at best). Reportedly she's changing her name back to 雷莊兒

Thousands of such characters exist, if you look at the page where 𠒇 is supposed to originate, more than half of this is obsolete -- https://www.kangxizidian.com/v1/?page=125#gv

(So yeah, you're correct in essence but picking on 囍 as an example probably doesn't really get your point across...)

Re:How can you be fooled by the U+202E trick? (2013) by thaumasiotes on Thursday February 17, 2022 @03:30AM (#30370778)
You've completely missed my point. Unicode is only intended to represent writing systems. It doesn't matter whether they're ancient, modern, common, or rare, but they're supposed to be writing systems.

囍 is used frequently, but it is not part of any writing system and does not convey any linguistic message. The opposite is true for 𠒇 - it is not used frequently, but it is part of a writing system and is used to convey linguistic messages.

Re:How can you be fooled by the U+202E trick? (2013) by hnfong on Thursday February 17, 2022 @04:57AM (#30371367)
The reason the point about 𠒇 holds is that it really isn't a character. I didn't claim it was "rare", I said it was a typo or a misinterpretation of an actual character (for the case of 𠒇 it is a misrepresented form of 兒.)

To presume a character is "real" merely because it exists in the Kangxi dictionary is as valid reasoning as presuming a character is "real" because it exists in "some other encoding standard" that you've been dismissive about. It's just that Kangxi is the de-facto Han character encoding scheme before computer encodings were invented. (Unihan even contains all details about the radical, stroke and even page number where it was sourced from)

A lot of those characters appeared once in some ancient text, and took the Kangxi form due to transcriptions from scribes across the centuries, but we actually have no evidence that they are "real" (at any point in time). Some of these characters are known alternative forms of common characters, or are only known to appear in some ancient text before Han characters were standardized. Some are plain typographical errors. It's like a 3 year old child learning to write "ABC", which looks a bit weird, and then the unicode committee assigned 3 code points to them.

Re:How can you be fooled by the U+202E trick? (2013) by thaumasiotes on Thursday February 17, 2022 @07:12AM (#30372246)
> Some of these characters are known alternative forms of common characters, or are only known to appear in some ancient text before Han characters were standardized.

Those are entirely valid for Unicode. Han unification in Unicode is already considered a mistake. That's why "unified" code points now also have explicit, higher-numbered 'equivalent' code points that unambiguously refer to a particular graphical form. The graphical form is the whole point of Unicode.

Re:How can you be fooled by the U+202E trick? (2013) by kerneloops on Wednesday February 16, 2022 @07:48AM (#30359320)
The character 囍 means "double happiness" literally, and is often used in wedding ceremonies among other places here in China. It is also included in the Xinhua dictionary, the semi-official dictionary in mainland China.
Re:How can you be fooled by the U+202E trick? (2013) by thaumasiotes on Wednesday February 16, 2022 @05:02PM (#30366382)
> The character 囍 means "double happiness" literally, and is often used in wedding ceremonies among other places here in China.

It's used by being hung on the wall, like a painting[1]. Like I said, it has no linguistic use, and thus it is not part of a writing system, which puts it outside the stated scope of Unicode. It is the exact equivalent, for weddings, of the upside-down 福 character that is hung for New Year's, or the wreath that Americans hang for Christmas.

But it does not correspond to anything in any language; there is no Chinese sentence whose spelling would include 囍. Note that the 新华 dictionary entry says "Double 喜. Generally used at happy occasions such as weddings.", and there are zero examples of the character being used. ( https://zidian.aies.cn/NDQ4MA==.htm )

The wording of the 新华 entry is almost identical with the beginning of the 汉语大词典 entry, and it's instructive to quote the rest of the entry:

> Character used at happy occasions. Commonly called "double 喜"[2]. Generally used at occasions such as weddings. Often cut from red paper (or gold leaf), or written on red paper, [then] pasted onto a door, window, or wall, in order to indicate a happy occasion.

[1] Actually, a much closer comparison would be the traditional magical talismans that use elements from the writing system in a freeform way to express various desired goals. https://en.wikipedia.org/wiki/Fulu

[2] This dictionary is nice enough to make the fact completely explicit that 双喜 is the name of the character rather than a definition. 汉语大词典 doesn't even attempt to provide a definition for this character.

Re:How can you be fooled by the U+202E trick? (2013) by mmis1000 on Wednesday February 16, 2022 @08:49PM (#30368607)
> it is not part of a writing system, which puts it outside the stated scope of Unicode.

Literally all emojis are not part of a writing system nor have proper linguistic use. Who on the earth write emoji by hand or even spoke it? Unicode already broaden the scope for so long, whether it is good or bad, nobody cares now. And beside that, a lot of symbols are also culture dependent. If you are not used to live at there, you just have no idea what it actually means.

Re:How can you be fooled by the U+202E trick? (2013) by thaumasiotes on Thursday February 17, 2022 @03:36AM (#30370807)
> Literally all emojis are not part of a writing system nor have proper linguistic use.

Yes, that's true, and they've been a constant source of problems for Unicode ever since the decision was made to let them in. They stand in violation of Unicode's declared principles and purpose.

Note that 囍 is not considered an emoji by the Unicode standards, though that's what it is in fact.

> Who on the earth write emoji by hand or even spoke it?

But there is an example of this - the name of https://en.wikipedia.org/wiki/I_Heart_Huckabees [wikipedia title uses the word "heart", but the actual title uses the symbol] was frequently spoken aloud.

Re:How can you be fooled by the U+202E trick? (2013) by mmis1000 on Thursday February 17, 2022 @05:27AM (#30371578)
I think the problem of emoji are more about they are in extended plane and they are colorful. The 'utf8' in sql assume we will never use extended plain and we actually used, which is the cause of former problem. Some of the chinese characters are also suffer from the form problem. And a lot of old system just can't draw the symbol in other color because it is designed prior to the exist of emojies.
Re:How can you be fooled by the U+202E trick? (2013) by WalterGR on Wednesday February 16, 2022 @05:57AM (#30358479)
Egyptian Hieroglyphics, Cyrillic glyph variant, and Cuneiform respectively.

I had to look them up so I might as well save others the time.

Re:How can you be fooled by the U+202E trick? (2013) by AnIdiotOnTheNet on Wednesday February 16, 2022 @08:14AM (#30359534)
I think I agree. Trying to encode all of human written language in one standard is just too huge a scope, and then you shove all that complexity into every layer of computing except just being in the kind of documents that need that level of complexity.

It's definitely an extreme view[0], and I'm open to being argued out of it, but I really think we should use a different and much simpler encoding for the vast majority of things even if it doesn't perfectly reproduce the written text of the language. Writing systems encoded the language in a way fit for the medium of paper, and maybe we need to consider computers a different medium and adapt our language to them differently too.

[0] and probably anglo-centric.

Re:How can you be fooled by the U+202E trick? (2013) by staticassertion on Wednesday February 16, 2022 @12:47AM (#30356768)
I don't think you do anything tbh. It's not really like those other situations where there's a straightforward, static answer.

The problem is honestly just that unicode is used to convey things like "this is a PDF" or "this is going to execute code" and it's attacker controlled. It's a terrible UX that's been abused for as long as paths have existed.

So I guess hope that operating systems will find a better UX for "this executes" and that they'll stop "a process executed" from being a game over situation for users.

Re:How can you be fooled by the U+202E trick? (2013) by klabb3 on Wednesday February 16, 2022 @01:00AM (#30356828)
I think you're right about paths but aside from that we have website urls, usernames or similar identifiers.. People look at those and assume that they can compare them. If I see `google.com` I assume it consists of certain characters that represent a specific institution. Are we doomed to live with ascii for the forseeable future or is there some form of reduced set of unicode that we can use without these types of impersonation attacks?
Re:How can you be fooled by the U+202E trick? (2013) by BoorishBears on Wednesday February 16, 2022 @04:42AM (#30357992)
you shouldn't get away with an IDN Homograph attack in any modern browser

They just turn your url into punycode, and more recently display that instead of the raw url: https://en.m.wikipedia.org/wiki/Punycode

Re:How can you be fooled by the U+202E trick? (2013) by account42 on Wednesday February 16, 2022 @09:47AM (#30360605)
> and more recently display that instead of the raw url

Technically, punicode is the raw URL and old enough browsers will display all non-ASCII domains as punycode. It was only for a short while that browsers naively decoded punicode without restrictions.

Re:How can you be fooled by the U+202E trick? (2013) by staticassertion on Wednesday February 16, 2022 @01:10AM (#30356866)
That's basically why Google wants to get rid of urls. They're terrible at conveying trust.
Re:How can you be fooled by the U+202E trick? (2013) by toomanydoubts on Wednesday February 16, 2022 @01:26AM (#30356926)
>That's basically why Google wants to get rid of urls.

Wink-wink ;)

Re:How can you be fooled by the U+202E trick? (2013) by rightbyte on Wednesday February 16, 2022 @02:09AM (#30357151)
Google want you to search on Google to see ads and be spied upon, not use a direct url.
Re:How can you be fooled by the U+202E trick? (2013) by cryptonector on Wednesday February 16, 2022 @01:30AM (#30356952)
There are certainly things that can be done. UTR #36 covers some of the things that can be done.

Besides refusing to render U+202E when it is between characters of scripts that aren't bi-directional and flow in the same direction, the UI could display the string in ways that make it clear (e.g., different color, maybe add a warning tooltip, maybe add a dialog around an operation that could be dangerous, or maybe refuse to perform dangerous operations).

Re:How can you be fooled by the U+202E trick? (2013) by account42 on Wednesday February 16, 2022 @09:50AM (#30360651)
Another option for filenames would be to recognize that the basename and extensions are distinct parts and the extension should always be displayed after the basename no matter what is in the basename. Of course, this adds lots of complexity so ¯\_(ツ)_/¯
Re:How can you be fooled by the U+202E trick? (2013) by cryptonector on Wednesday February 16, 2022 @10:21AM (#30361076)
Problem is that there's cases like foo.tar.gz. What's the extension there?
Re:How can you be fooled by the U+202E trick? (2013) by samwillis on Wednesday February 16, 2022 @03:58AM (#30357737)
There are two broad types of attack vectors, those that target a program, and those that target a person.

Most Unicode attack vectors seem to target people, they are ways to obscure from a person the true intention of what something is. As a developer it’s our job to try and mitigate this through how we display the data, warn about risks and block particular attacks. So it’s about working out how to prevent a user from making a mistake.

It seems to me in this case obviously Unicode became “a thing” after the development of a file extension. Clearly if it had been the other way around the file extension would have no meaning, maybe that’s what we need to move towards, store that metadata elsewhere on the file system.

Fundamentally Unicode from and “untrusted” origin shouldn’t be trusted in an executable context.

Re:How can you be fooled by the U+202E trick? (2013) by dgrunwald on Wednesday February 16, 2022 @04:46AM (#30358015)
We don't need to store the metadata differently. The on-disk format is still unambiguous: the part after the last dot is the extension. It's only the graphical display that is ambiguous, because the last dot is not necessarily the rightmost dot. This is easily solved with a UI change, e.g. move the file extension from the "file name" column to a separately rendered "file extension" column.

One could even translate the file extension into something more user-friendly (e.g. .exe -> Application), making it a "file type" column. Which is of course what Windows Explorer has been doing for decades already. Of course, that results in everyone turning the classic file extension back on...

Re:How can you be fooled by the U+202E trick? (2013) by samwillis on Wednesday February 16, 2022 @06:35AM (#30358721)
I think one of the troubles here is the difference between a GUI and a command line type app. Very true on a GUI you can hide the extension and display file type in a column, which is what Windows and MacOS both increasingly do. However on the command line its still fundamentally part of the filename, to fix that is a larger job and my suggestion is that it should not be part of he filename, but metadata on the file/filesystem.

The other problem with hiding the extension is that you then have "file name" collisions, two files will appear to have the same name but only differentiate by the "type". I think that's wrong.

Re:How can you be fooled by the U+202E trick? (2013) by rurban on Thursday February 17, 2022 @01:48AM (#30370231)
Apply the Unicode security guidelines for identifiers (TR39) to names, simple as that. Identifiers such as variable names, filenames, Login names, domain names, emails should be identifiable.

Eg. use my libu8ident. For technical details see the C++ proposal to use secure identifiers: https://rurban.github.io/libu8ident/doc/P2528R1.html

Re:How can you be fooled by the U+202E trick? (2013) by dotancohen on Wednesday February 16, 2022 @04:28AM (#30357925)

  > With unicode, I really don't know what to do. What strings need to be sanitized (or validated)?
Just yesterday I filed a bug on the KDE terminal emulator [1] for stripping away too many characters. I'm sure that the fine devs had no idea which characters are safe to leave in and which are not. I certainly have no idea myself.

[1] https://bugs.kde.org/show_bug.cgi?id=450219