The really exciting stuff is how they're doing that! Research into that question is generally called interpretability, and it's probably what I'm most interested in at the moment.
Holy.shi..
As I have been observing the ways AI struggles and the ways it produces output, I’ve had this growing suspicion that LLMs have been somehow showing us things about the human brain, but it wasn’t until this moment that I had any validation of the theory.
I’m very curious about the insights that will give us in to LLMs. My initial instinct is that it won’t work unless you have essentially the entire state remembered since each “point” in the LLM can lead anywhere. I’m imagining an experiment where the task is “Get a person who’s never been to this city before from point X to point Y without describing the destination and while providing as little information as possible”. Giving them the full map with directions is the equivalent to giving the LLM the full previous conversation.
Intuitively there is low-hanging fruit (just provide the directions of single optimized route), but it feels like it gets chaotic quite quickly after that. How many steps could you leave out of turn-by-turn directions before the person is hopelessly lost?
This is based on my current understanding of LLMs so YMMV, but I’m definitely curious about ways we can start from a remembered state.
And how does the NN represent the token at the output layer? Is it a binary representation of the token number?
Or does it have a neuron for each token it knows and ChatGPT takes the most activated neuron as the answer?
But I personally think it's a coincidence, and it just so happens that 50k tokens are enough for the level of complexity the models have right now.
Tokens are part of words, approx 4 characters or 75% of word.
It gives a list of tokens with their probabilities on output.
It's a short list with highest probabilities.
Temperature controls which tokens to pick - usually 0% = top one only (consistent results), closer to 100% means more randomness (more "creativity").
It's "glorified markov chain" in the same sense that sqlite is just "glorified bubble sort".
For example: if you limited all inout/output to the same 100 words, could you stay within the token limit permanently?
At the moment, image models are mostly diffusion models while LLMs are mostly autoregressive. With a few other examples. Google has for example created both an autoregressive image model, Parti, and a diffusion model, Imagen.
It's still early for non-autoregressive LLMs.
* empty string
* Berlin
* Berlin city
* Berlin is a city
* Berlin is a city in Germany
* Berlin is the capital of Germany
* Berlin is the capital of Germany, located in the North East.
* Berlin is the capital. It is located in the North East of Germany.
* Berlin is the populous capital city of Germany. It is in the North East of Germany, by the river Spree.
* Berlin is the capital city of Germany with 3.6 million inhabitants. It is located in the North East of Germany. It's centred on the river Spree. ...
At every step, the diffusion slightly rephrases to add more information content and detail to that of the previous level, by inserting, replacing and deleting tokens.
It is usually more costly to sample from these diffusion style models (which is not the case for diffusion for images, as unlike text, images tend to have a fixed size). But, one might imagine this approach to scale up to generate texts of arbitrary lengths. Just keep on adding more and more detail on your text, and you'll end up with a book or a coherent novel.
Interesting. Can't you just start with 4K of randomly assigned tokens and tweak it until it's right (including the tokens for EOF), like they do for images where they start with noise and move towards an image?
But for this approach adding "noise" would be much less straightforward, wouldn't it? You'd have to have some way to work out how to take "Berlin is the capital city of Germany with ..." down to an empty string in a way that marginally removes detail. For some passages this could be rather difficult to do. I feel like gathering training data would be a huge trial here.
You could then greedily take the most probable single token, or select a bit more randomly (that's where temperature comes in) in a few different ways. You can do better still by exploring a few of the possible top options to select a high probability chain of tokens. That's because the most probable next token may not be the start of the most probable sequence of tokens. That's called beam search.
Other than that, things like gpt can't go back and edit what they've outputted, so it's much more like listening to someone talk from the top of their head and writing down everything they say. They can say something wrong, followed by correcting themselves. The fact that the output becomes the input makes it much more obvious why "lets think through step by step" helps them reason, they can do simpler things then see the simpler steps they've already done to answer the more complex parts.
There are other decoding approaches, other than beam search:
https://arxiv.org/abs/2202.00666
> Other than that, things like gpt can't go back and edit what they've outputted
Actually, they can, they may emit a backspace token [1]
[1] https://arxiv.org/abs/2306.05426, https://news.ycombinator.com/item?id=36425375
https://blog.fastforwardlabs.com/images/2019/05/Screen_Shot_...
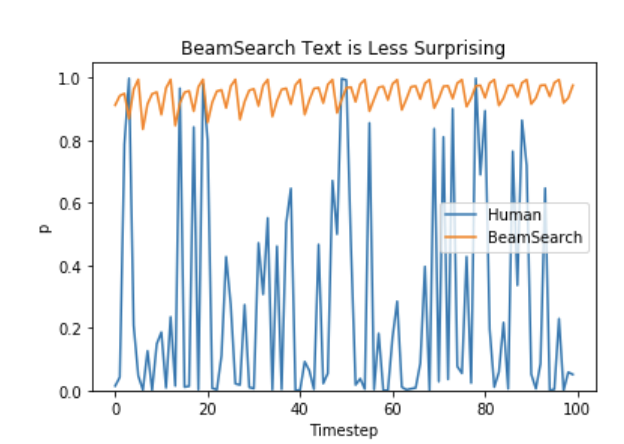
The way most GPT models are set up, they don't edit, but there was a lot of work (made redundant by OpenAI) on using gap filling tasks (masking) to iteratively improve or construct or otherwise edit and formulate logic using the encoder-decoder models of yesteryear - in many ways, I think it would have been more exciting if that approach powered the likes of 'think step-by-step' results.
There's nice stuff you can do with the probabilities, a shame it's more restricted with the chat models. I hope they add some lightweight thing you could pass with your request to constrain the response.
However, it's important to note that the numbers which the models returns for the next tokens can only be interpreted as probabilities for foundation models. For fine-tuned models (instruction SL, RLHF) the numbers represent how good the model judges the next token to be. This also leads to a phenomenon called mode collapse.
> Human: Describe Berlin
> Bot: Berlin is a city in Germany. It has been the capital of Germany since 1871 and it's also known as "the city that never sleeps".
So if you ask ChatGPT "Describe Berlin", what happens is that the NN is called 6 times with these inputs:
ChatGPT's answer: Is that how LLMs work?