> Crystalline employs information loss as the basis of its security.
If encryption loses information, there’s no way decryption can bring it back.
In the extreme
  def encrypt(s):
    return “(TOP SECRET)”
    def decrypt("(TOP SECRET)"):
return sa. The author cannot decrypt it either, unless he's cheating somehow, or
b. It's not really losing information and the author is lying.
> That immediately shows that the person writing it doesn't know cryptography. You simply can't get the security of one-time pad [..]
Talking about a one-time pad at all in the context of making something actually secure for internet usage, shows that the talker doesn't know about cryptography.
A one-time pad having "perfect security" is only true in the context of a particular security model that doesn't generally hold true on the internet - one where the adversary cannot change the ciphertext whilst it is in transit.
Under a more realistic security model, we need a message authentication code or some other equivalent, to protect against adversaries changing the ciphertext. It's a well-known theorem of modern cryptography that in fact if you don't have secure authentication under this model, then you cannot achieve secure privacy. In other words, your ciphertext has to be bigger than the plaintext for security on the internet.
(There is in fact a one-time-pad equivalent for MACs where your key is the length of the plaintext and the ciphertext ends up being several multiple times the length of the plaintext, but crackpots when making security arguments about "one-time pads" generally aren't referring to this and aren't even aware of the existence of this. It's a relatively unknown construction and nobody really talks about it in the context of serious modern cryptography.)
However, this meant there where leftover bits of each key. Though if you think of each bit as a different key then sure, just start each message with the offset.
The idea of a one-time-pad is that you're basically just randomly flipping the bits of your input, which means the output of an OTP cipher is indistinguishable from random data.
If you're using the same key multiple times though, then the output of the cipher (considered over time) won't be random, and you'll be able to detect patterns from the original input in the cipher output (e.g., the shape of an image, frequency of certain letters).
The thing is, if you know the same key has been used a second time, then yes, having both outputs (can? will? must? could?) helps to acquire the key.
But how do you know they're using the same one? Or how are you sure, they're not? All you have, are two pieces of random data.
The output of any _one_ use of the pad is, yes, but the point is to consider all of the data that an attacker may have. If you re-use the key multiple times, then the entirety of the cipher texts an attacker has is not random. (See also: https://xkcd.com/221/)
> But how do you know they're using the same one? Or how are you sure, they're not?
You'll be able to tell because you'll see patterns in the data: https://upload.wikimedia.org/wikipedia/commons/f/f0/Tux_ecb....
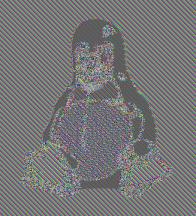
You encrypt the data ABCD -> EDGF.
You encrypt the data DEFG -> HGJI
Someone intercepts the data, and has: EDGF and HGJI
And now?
Or maybe like this: Since OTP and data are interchangeable, due to matching lengths, isn't using the same OTP with different data, essentially the same like using the same data with a different key?
Story time: The USSR once reused an OTP key (after years or even decades, can't recall), but a US' three letter agency had the old ciphertext (A') and reused that to break the new ciphertext (B'). They probably had some scheme with a broadcaster saying "use codebook 1234, the secret is GARBLED DATA". At least that's the story a cryptography lecturer told us (and the fragments I remember).
I guess one thing to note is that, if what you were transmitting was just random noise to begin with, OTP re-use may not matter/be evident. But essentially all data that people care about transmitting isn't random noise, it has some structure, and that structure comes through with OTP re-use (more and more the more you re-use and the more data you re-use with).
AIUI, the Enigma machine (not quite an OTP but I think similar) was broken in part because of just a few key re-uses https://en.wikipedia.org/wiki/Cryptanalysis_of_the_Enigma#Op...
From my limited knowledge of the matter, that alone doesn't give you the cypher - you'll need to know additional information about the messages to get the cypher (statistics of words, conditional probabilities of letter sequences etc.). But without the one reuse of your cypher, you couldn't apply these techniques.
That ASCII example is rather extreme, but all messages have patterns as long as you’re given enough of them you can break a reused OTP.
Here's a good illustration of the principle: https://crypto.stackexchange.com/questions/59/taking-advanta...
Obviously it's more complicated with text (where you have less information filled in); for that you have to do crib dragging which is a bit more involved but not fundamentally difficult.
I've always assumed it was just adding the key-value to the data-value, as is described in the Wikipedia article[0].
And those two can't be the same, e.g. with both data and key value 'a' (0x5c), I'd get 0x0 with XOR and 0xb8 with addition.
EDIT: Ah, damnit, second paragraph, it says: "On July 22, 1919, U.S. Patent 1,310,719 was issued to Gilbert Vernam for the XOR operation used for the encryption of a one-time pad."
Everything I've posted in this thread about OTP was under the assumption of an additive cipher. My bad.
Edit for your edit: All of this discussion applies the same for additive OTP as it does for XOR OTP; once you have depths you can start applying the OTP (however it's done) “in reverse” as it were to begin extracting patterns in the data.
You can easily discover reused keys if you can guess any part of either plaintext. From that guessed fragment, you can recover both plaintexts and the entire key (pad) using the "Zig Zag" method.
(P=plaintext, C=cyphertext, K=reused_pad, ⊕=XOR)
If we capture two ciphertexts that reused the same key
    C1 = P1 ⊕ K
    C2 = P2 ⊕ K
D = C1 ⊕ C2 = P1 ⊕ P2
Professor Brailsford's explanation[1] of the method on Computerphile is nice introduction to this type of cryptanalysis.
In 09:05 ([0]) you can see why, namely that K and K cancel each other out.
I don't think this would be the case with an additive cipher.
EDIT: Continuing the thought with an additive cipher:
  P1 + P2 = C1 + C2 + 2K
  2K = P1 + P2 - (C1 + C2)
  K = P1/2 + P2/2 - C1/2 - C2/2
    C1 = P1 + K
    C2 = P2 + K
    C1 - C2 = P1 - P2
  P1 + P2 = C1 + C2 - 2K
  2K = C1 + C2 - (P1 + P2)
It does not appear he's uploaded slides yet but here is link to session: https://bsidessf2020.sched.com/event/Ybgu/break-crypto-like-...
He said he was going to check in his code to GitHub so may be able to find same with some detective work.
Essentially you could xor two encrypted images with the same OTP and see them sort of superimposed on one another.
Depends how motivated your enemy is
Would like to know, if my assessment on additive OTP is correct, if anyone knows?
EDIT: I mean, of course you still shouldn't, but where the XOR catastrophically fails after just a single reuse, the additive one should be more robust, even with reuse. The Venona Decrypts were additive-OTP, I postulate, the decryption rate would've probably been higher with XOR-OTP.
Like if ciphertext is "supersecret" then it feels like plaintext can't be more obvious and OTP must be "00000000000", but there's nothing anywhere to logically/mathematically support it. OTP could be something else and plaintext could be "hackernews" or "ycombinato".
In reality a simple XOR with a random sequence preserve enough entropy of data that I've heard you could make out voices if used on media, so payloads must be scrambled, but that's not recovery, only a guess. ANY reuse breaks that notion and make it not an OTP cryptography.
> Designed to be as secure as a one-time pad, without a weakness due to the use of repeating keys,
That immediately shows that the person writing it doesn't know cryptography. You simply can't get the security of one-time pad without having a key the size of the data, and if you do, just use it as the pad.