SQLAlchemy author here. I can't imagine how someone would not consider SQLAlchemy to treat "SQL" as the "source of truth" as well. All of SQLAlchemy's constructs map directly to SQL syntactically. Our most grumpy users are the ones who don't know SQL. This blog post would certainly benefit from some actual examples. "ORM-light tools that coerce responses into native structs and allow for type-checking are less offensive to me." - that is...an ORM?
There is certainly a lot of information in a schema, and you definitely want your ORM's idea of the database and the database's idea of it to be in close alignment, but I feel like any serious attempt would find all sorts of holes like the above when it actually came to doing it.
Is multiple applications talking to a shared DB schema a common practice, especially nowadays?
In my mind, each app/service should have a DB schema which only it talks to, and other apps/services needing data in that DB go through services exposed by that app/service (REST, RPC, GraphQL, whatever) rather than talking to its DB directly. That means you can rearchitect the DB schema, change which DB you use completely, etc., and only the app/service which owns that DB needs to be modified.
>"ORM-light tools that coerce responses into native structs and allow for type-checking are less offensive to me." - that is...an ORM?
Yeah...its a light ORM that focuses on turning a result set into an object but not the syntax remapping of queries. Object mapping is almost universally liked but ORMs usually include query syntax mappings and not the addition of a transaction lifecycle into your data objects.
The biggest problem for me is this "proxy" behaviour. When you start treating objects as proxies for database rows, your database logic inevitably leaks into your business logic. Someone returns an ActiveRecord `User` object from a database method and now random other parts of your application are intricately linked to your database implementation.
On top of that you suffer terrible performance problems. Even if you're smart enough to avoid the whole N+1 query issue, you lose control (and more importantly visibility) over where database updates are coming from, and your ORM is either not smart enough to efficiently apply updates, or so smart that building the query takes longer than actually running it! (I have this problem with SQLAlchemy right now, where it's taking several seconds per request CPU bound in the ORM). Undoing this is literally impossible without a near total rewrite.
And it all serves no purpose! The application-specific interface to its database is usually quite simple. You can just have it be a literal interface/trait/whatever and implement each method by executing a bit of SQL, or calling a stored procedure, or however you like. Arguments and return values should be plain-old-data (no magic proxy objects) and each method should correspond roughly to a transaction so that the rest of the application doesn't have to worry about that database-specific stuff.
There are a ton of other benefits to doing stuff this way, too many to list here, but it really helps with complex migrations (like if you need to migrate from one database to another), maintainability, testing, etc.
for the write? writes are not usually much of a performance issue except when people are inserting thousands of rows. You can replace flush with direct INSERT/UPDATE or use the bulk API. Pre-setting primary key values will also improve performance by an order of magnitude. Share some of your code and profile results on the mailing list and we can look into speeding it up.
SQLAlchemy always provides many techniques to optimize areas that have performance problems, not to mention the primary direction for most major releases is that of new performance features and improvements year after year, despite having to deal with the dog-slow cPython interpreter. No "total rewrite" of your application should be needed.
This is not just for writes, but also for loading complex relationships from the database: we've gone to great lengths to ensure we're using relationships optimally so as to cache query results and not fall into the N+1 query problem, but our application spends all its time inside SQLAlchemy.
The only way to get the performance improvements we needed was to stop using it as an ORM altogether. However, the ORM was too intricately tied with our business logic to do that without a near total rewrite.
What we've actually ended up doing to do this rewrite more incrementally is to create a Rust service which implements just the "GET" end-points: this gives us an order of magnitude performance improvement despite it using the exact same database and fetching the exact same data. Most of the business logic did not need to be duplicated as it is not used from "GET" requests, but users of our application will get much snappier loading times, and it will generally feel much better.
it most certainly does provide many techniques to reduce in-Python computation. Have you read the performance section in the FAQ and worked through the examples given ? Have you looked into baked queries , querying for columns and not objects ? These are often quick wins that make a huge difference. The baked queries concept is going to be much more cleanly integrated in an upcoming release.
> This is not just for writes, but also for loading complex relationships from the database: we've gone to great lengths to ensure we're using relationships optimally so as to cache query results and not fall into the N+1 query problem, but our application spends all its time inside SQLAlchemy.
that's typical because a CRUD application is all about its object model and SQLAlchemy is doing all of that work. if you wrote your own object layer using Core then you'd see all the time spent in your own objects<->core layer. This is just the reality of Python.
Here's a runsnakerun I make some years ago of the PyMYSQL driver loading data over a network-connected database: https://techspot.zzzeek.org/files/2015/pymysql_runsnake_netw... Notice how just the Python driver spends TWO THIRDS of the time an the actual waiting for the database 1/3rd ? that's Python. If the database is on localhost, that pink box shrinks to nothing and all of the time is spent in Python, just reading strings and building tuples. It's a very slow language.
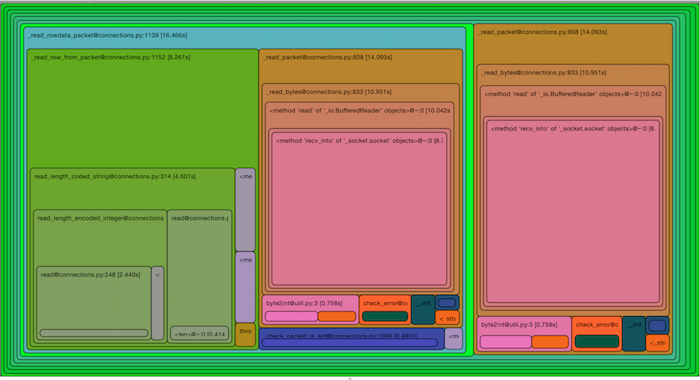
Rust language however is blazingly fast and is one of the fastest languages you can use short of straight C code. This is not the fault of an ORM, this is just the reality of Python. You certainly wouldn't think that if you used an ORM that runs under Rust, it would be as slow as your Python application again. It would continue to be extremely fast. The Hibernate ORM is an enormous beast but runs immensely faster than SQLAlchemy because it's running on the JVM. These are platform comparisons. SQLAlchemy is really fast for the level of automation it provides under pure Python. You made the right choice rewriting in a fast compiled language for your performance critical features but that has little to do with whether or not you use an ORM. As long as your database code was in your Python application, you'd end up writing an ORM of your own in any case, it would just be vastly more code to maintain.
Most of those techniques boil down to "use SQLAlchemy as a query builder rather than an ORM" - something I wholeheartedly agree with and would love to do, but it is next to impossible because these ORM objects have leaked into the business logic of the application.
> that's typical because a CRUD application is all about its object model and SQLAlchemy is doing all of that work. if you wrote your own object layer using Core then you'd see all the time spent in your own objects<->core layer. This is just the reality of Python.
I'm not trying to say SQLAlchemy is a bad implementation - it's a great implementation with tons of powerful features. I just believe that using anything as an ORM is a bad idea and directly leads to these performance and maintainability issues. Whether that's ActiveRecord, SQLAlchemy or even if someone implemented a similar ORM in Rust.
Some of the performance issues are due to python, but that's not the whole story: if I use SQLAlchemy as a query builder, and only return plain-old-data, I do not see nearly the same performance issues. Not because SQLAlchemy ORM is badly written, just because it has to do more work, create more objects, with more "magic properties", maintain more entries in the session, etc. etc.
CPU time building a query is rarely the business bottleneck until you're at a huge scale - scaling up the engineering team uniformly and having business logic at abstraction level closer to the rapidly evolving Product specs is the bottleneck that ActiveRecord solves for, and does pretty well.
If you'd like something that avoids object/hidden state - check out how Elixir/Phoenix's Ecto[1] was designed - it avoids many of the shortcomings of ActiveRecord and SLQAlchemy:
Once you fetch something from the db, you have it in variables in memory. With or without an ORM. That could no longer be sync'd with the db a ms later. That you will probably re-use for more than one access (if you need it more than once), because issuing the same SQL again the second time you need to reference any data returned, in a given routine, would be insane.
But if I had to increment specifically, and were using ActiveRecord... I'd use the ActiveRecord increment! method. Which has the proper db-atomicity semantics you want, it does execute `UPDATE x SET n = n+1 WHERE pk = y ...`
MyModel.objects.filter(pk=...).update(myfield=F('myfield') + 1)
Having to think about these things because the abstraction is leaky instead of just using the SQL where the transformation is explicit is not worth the hassle.
Using Clojure and yesql was a real pleasure for this - Clojure is immutable so you're working with values all over the place - and working with SQL query is just passing values in it and getting values out - no magic mapping - it's just values - if you want the latest value - query again, if you want to store a new value - send the new value. No mutation, no magic, just data.
Nope. The DBMS is making the same transaction isolation guarantees to an ORM as to any other client.
I think the larger "source of truth" issue is how the schema is represented.
All of these systems that provide their set of schema objects that are then pushed to the database. This works fine for LAMP stacks, but as soon as you grow it becomes apparent that you've put the horse before the cart.
Sprinkling calls to order.save! or order.update(foo: bar) in random places is a recipe for disaster.
Indeed. Its a rookie mistake but hey, you work with rookies all the time! Orms can be useful but they certainly allow for some dangerous patterns that are hard to notice if you're a young developer.
My preferred solution for existing DBs is Ruby's Sequel or ROM if you want to go nuts. But I'm a diehard Rails lover and will choose ActiveRecord over all other solutions if I can. To me there's only one decent ORM and everything else is either good for special purposes or junk.
Also, there is a whole section called "ORMs take over connection management and migration" and not a single point as to why connection management handled by the ORM is bad, only comments on migrations. Moreover, migrations are not an unsolved problem at all.
In Ruby, ActiveRecord solves all scenarios I have encountered gracefully, and trust me, I have dealt with tons of edge case projects.
For Python, I recommend Alembic: https://pypi.org/project/alembic/