News for hackers. Stuff that matters.
Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by mattkevan on Wednesday March 27, 2024 @09:57AM (#39839159)
I've used GPT-4 for programming since it came out and it's massively improved my productivity, despite being frustrating at times. It quickly forgets details and starts hallucinating, so I have to constantly remind it by pasting in code. After a few hours it gets so confused I have to start a new chat to reset things.

I've been using Claude pretty intensively over the last week and it's so much better than GPT. The larger context window (200k tokens vs ~16k) means that it can hold almost the entire codebase in memory and is much less likely to forget things.

The low request quota even for paid users is a pain though.

Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by biddit on Wednesday March 27, 2024 @10:17AM (#39839450)
> The larger context window (200k tokens vs ~16k)

Just to add some clarification - the newer GPT4 models from OpenAI have 128k context windows[1]. I regularly load in the entirety of my React/Django project, via Aider.

1. https://platform.openai.com/docs/models/gpt-4-and-gpt-4-turb...

Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by danielbln on Wednesday March 27, 2024 @10:42AM (#39839860)
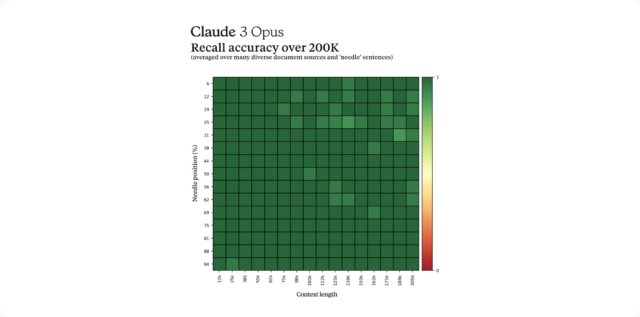
GPT-4 has much worse recall compared to Claude-3 though, compare these two haystack tests:

https://github.com/gkamradt/LLMTest_NeedleInAHaystack/raw/ma...

https://cdn.arstechnica.net/wp-content/uploads/2024/03/claud...
Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by aubanel on Wednesday March 27, 2024 @07:09PM (#39845726)
Be aware the haystack test is not good at all (in its current form). It's a single piece of information inserted in the same text each time, a very poor measurement of how well the LLM can retrieve info.
Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by bufferoverflow on Wednesday March 27, 2024 @08:13PM (#39846262)
Seems like a very good test for recall.
Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by aubanel on Thursday March 28, 2024 @02:01PM (#39855200)
Even in the most restrictive définition of recall as in "retrieve a short contiguous piece of information inside an unrelated context", it's not that good. It's always the exact same needle inserted in the exact same context. Not the slightest variation apart from the location of the needle.

Then if you want to test for recall of sparse information or multi-hop information, it's useless.

Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by BA2255 on Thursday April 11, 2024 @02:25AM (#39998966)
For my education, how do you use the 200k contenxt the normal chats like Poe, or chatgpt don't accept longer than 4k maximum. Do you use them in specific Playgrounds or other places?
Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by aubanel on Monday April 15, 2024 @03:13AM (#40037767)
The calls with long context are done through specific APIs, that you can call for instance in Python or Javascript.

Here's a quick start guide with OpenAI: https://platform.openai.com/docs/quickstart?context=python

Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by acedTrex on Wednesday March 27, 2024 @10:42AM (#39839851)
I see so many people say that llms have improved their programming and i am truly baffled by how. They are useful on occasion and i do use chatgpt and copilot daily but if they disappeared today it would be at worst a minor annoyance.
Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by dontreact on Wednesday March 27, 2024 @10:46AM (#39839921)
It’s a tool you learn to use and improve with. How many hours of practice have you given the tool?

Personally I’ve been practicing for almost 3 years now going back to CoPilot so I would guess I have at very minimum a few hundred hours of thinking about how (what to prompt for, what to check the output for) and probably more importantly when (how to decompose the task I am doing into parts for which some the LLM can reliably execute) to use the tool.

Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by stavros on Wednesday March 27, 2024 @03:00PM (#39843228)
I don't think it's a failure of the prompting, but of the tool itself. It just isn't good for any higher-level tasks, and those I know how to do anyway. It's good for menial API work, as a sibling comment says, and using it I can avoid reading API docs, but that's about it.

I tried to have it rewrite in Go a small Python script (a hundred or so lines) that I wrote, and it basically refused, saying "here's the start, you write the rest now". As others said, if it went away it'd be a minor inconvenience of me having to read a bit more documentation.

Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by dontreact on Thursday March 28, 2024 @10:23PM (#39859945)
Yes to me that’s obviously not a good use, and I have experience to know not to attempt hundred line rewrites of files.

I order to reflect on my mental about this. It’s that i more often break down parts problem into sub routines that are 30 or so lines. These are nailed about 95% of the time and when there’s something wrong it’s obvious.

Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by dontreact on Thursday March 28, 2024 @10:24PM (#39859947)
I also wonder if it’s a language effect and the models are just way better at python
Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by bun_terminator on Wednesday March 27, 2024 @11:04AM (#39840226)
Same here. The most use I made of it were

1) making it write some basic code for an API I don't know. Some windows API calls in particular 2) Abusing it as a search engine since google barely qualifies for one anymore

For actual refactoring, the usual tools still blow it out of the water IMO. Same for quality code. It just doesn't compile half the time.

Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by Balgair on Wednesday March 27, 2024 @03:43PM (#39843679)
I mean, I'm not so much of a programmer as a person that can hack together code. Granted, my job is not 'programmer', it's 'R&D'.

For example, I had to patch together some excel files the other day. Data in one file referenced data in ~60 other files in a pretty complicated way, but a standardized one. About 80,000 rows needed to be processed across 60,000 columns. Not terrible, not fun though.

Now, I'm good at excel, but not VBA good. And I'm a 'D-' in python. Passing, but barely. Writing a python program to do the job would take me about a full work day, likely two.

But, when I fired up GPT3.5 (I'm a schlub, I know!) and typed in the request, I got a pretty good working answer in about, ohhh, 15 seconds. Sure, it didn't work the first time, but I was able to hack at it, iterate with GPT3.5 only twice, and I got my work done just fine. Total time? About 15 minutes. Likely a 64X increase in productivity.

So, maybe when we say that our programming is improved, what we actually mean is that our productivity is improved, not our innate abilities to program.

Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by mattkevan on Wednesday March 27, 2024 @04:06PM (#39843946)
I’m a designer who likes to code things for fun and would make a terrible programmer.

For me llms are fantastic as they enable me to build things I never could have without.

I imagine they wouldn’t be as useful for a skilled programmer as they can do it all already.

Can’t remember the source, but I read a paper a while back that looked at how much ChatGPT actually helped people in their work. For above average workers it didn’t make much difference, but it made a big improvement for below average workers, bringing them up to the level of their more experienced peers.

Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by shriek on Thursday March 28, 2024 @07:46AM (#39849987)
Yeah, I'm curious how others are using too. For boilerplate code and configs, they're great in a sense that I don't have to open docs for reference but other than that I feel like maybe I'm not fully using it to its full potential like others are mentioning.
Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by cosmojg on Wednesday March 27, 2024 @10:16AM (#39839433)
> The low request quota even for paid users is a pain though.

Why not use the API directly? Their Workbench interface is pretty nifty if you don't feel like hooking the API up to your tools of choice.

Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by danielbln on Wednesday March 27, 2024 @10:44AM (#39839891)
The workbench UI sucks, what's nifty about it? It's cumbersome and slow. I would recommend using a ChatUI (huggingface ChatUI, or https://github.com/lobehub/lobe-chat) and use the API that way.
Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by cosmojg on Thursday March 28, 2024 @01:11AM (#39847993)
Right, but it's certainly easier for people who might not even know what "API" stands for, and that's quite nifty. As far as self-hosted frontends go, I can personally recommend SillyTavern[1] in the browser, ChatterUI[2] on mobile, and ShellGPT[3] for CLI. LobeChat looks pretty cool, though! I'll definitely check it out.

[1] https://github.com/SillyTavern/SillyTavern

[2] https://github.com/Vali-98/ChatterUI

[3] https://github.com/TheR1D/shell_gpt

Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by bredren on Wednesday March 27, 2024 @09:59AM (#39839188)
Which languages are you primarily writing in?

Do you mean you are throttled by it more often? (~“You must wait X mins to make more queries”)

Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by danw1979 on Wednesday March 27, 2024 @10:55AM (#39840087)
The lack of API credits for Claude Pro subscribers is also a bit of an oversight. I’d like to be able to consume my daily quota via the API as well as the chatbot.
Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by lfkdev on Wednesday March 27, 2024 @10:32AM (#39839687)
Just use the API, do as many requests as you want
Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by ramijames on Wednesday March 27, 2024 @10:19AM (#39839495)
How do both compare to copilot?
Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by varispeed on Wednesday March 27, 2024 @10:06AM (#39839293)
It is still remarkably better than working with junior developers. I can ask it to code something based on specification and most of the time it will do better job than if I send the same task to a human.

It often makes some small mistakes, but little nudge here and there corrects them, whereas with human you have to spend a lot of time explaining why something is wrong and why this and that way would rectify it.

The difference is probably because GPT has access to a vast array of knowledge a human can't reasonably compete with.

Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by throwaway35777 on Wednesday March 27, 2024 @10:42AM (#39839861)
> It is still remarkably better than working with junior developers

It really bugs me when people imply AI will replace only certain devs based on their title.

Seniority does not equal skill. There are plenty of extremely talented "junior" developers who don't have the senior title because of a slow promo process and minimum time in role requirements. They can and do own entire projects and take on senior-level responsibilities.

I've also worked with a "senior" dev who struggled for over a month to make a logging change.

Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by bigcoke on Wednesday March 27, 2024 @10:53AM (#39840052)
that's more or less how I use gpt-4, "how to <describe some algorithm in some language><maybe some useful context with a short code example>", most of time it output something useful that I can work with, but if a junior work is to be my gpt-4, that's a waste of human resource.
Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by aiisjustanif on Wednesday March 27, 2024 @10:25AM (#39839573)
> It is still remarkably better than working with junior developers.

Definitely not all junior developers. I have yet to see it do well at handling code migrations, updating APIs, writing end to end tests, and front end code changes with existing UX specifications to name a few things.

Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by greenavocado on Wednesday March 27, 2024 @10:40AM (#39839821)
Wow, you have good junior developers.
Re:Claude 3 beats GPT-4 on Aider's code editing benchmark by throwaway35777 on Wednesday March 27, 2024 @10:50AM (#39839986)
Work at a good company and you'll find that the juniors are pretty capable.