When stereotypes clash with historical facts, facts should win.
Hallucinating diversity where there was none simply sweeps historical failures under the rug.
If it wants to take a situation where diversity is possible and highlight that diversity, fine. But that seems a tall order for LLMs these days, as it's getting into historical comprehension.
Failures and successes. You can't get this thing to generate any white people at all, no matter how explicitly or implicitly you ask.
You sure about that mate?
There could have been multiple versions of Gemini active at any given time. Or, A/B testing, or somehow they faked it to help Google out. Or maybe they fixed it already, less than 24 hours after hitting the press. But the current fix is to not do images at all.
> In 2023, The New York Times described Pool's podcast as "extreme right-wing", and Pool himself as "right-wing" and a "provocateur".
They're just straight up lying about him.
Nobody should.
They’re literally semi-random graphic artifacts that we humans give 100% of the meaning to.
Always doing that would be preferable to the status quo, where it does it just often enough to do damage while retaining a veneer of credibility.
The model isn’t trying to replicate reality, it’s trying to minimize some error metric.
Sure it may be inspired by reality, but should never be considered an authority on reality.
And yes, the words an LLM write have no meaning. We assign meaning to the output. There was no intention behind them.
The fact that some models can perfectly recall _some_ information that appears frequently in the training data is a happy accident. Remember, transformers were initially designed for translation tasks.
They're graphic artifacts generated semi-randomly from a training set of human-created material.
That's not quite the same thing, as otherwise the "adjustment" here wouldn't have been considered by Google in the first place.
I think, with respect to the point I was making, they are the same thing.
Unless I format my prompts very specifically, diffusion models are not good at following them. Even then I need to constantly tweak my prompts and negative prompts to zero in on what I want.
That process is novel and pretty fun, but it doesn’t imply the model is good at following my prompt.
LLMs are similar. Initially they seem good at following a prompt, but continue the conversation and they start showing recall issues, knowledge gaps, improper formatting, etc.
It’s not dishonest to say semi-random. It’s accurate. The detokenizing step of inference, for example, is taking a sample from a probability distribution which the model generates. Literally stochastic.
[edit]
Statistical inference machines following human language prompts that include "please" and "thank you" have absolutely 0 ideas of what a fact is.
"A stick bug doesn't know what it's like to be a stick."
But I would counter that there are certainly rules in art.
Both historical (expectations and real history) and factual (humans have a number of arms less than or equal to 2).
If you ask Gemini to give you an image of a person and it returns a Pollock drip work... most people aren't going to be pleased.
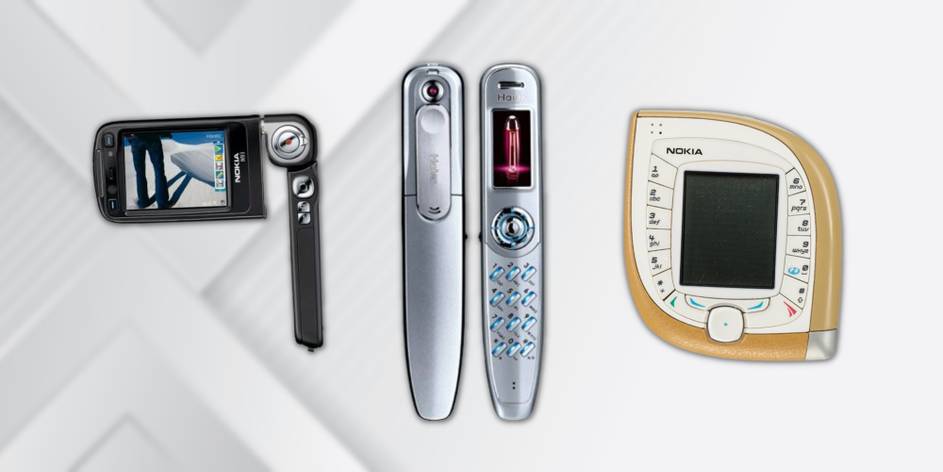
It might be "perfectly reasonable" to have that as an option, but not as a default. If I want an image of anything other than a human, you'd expect the sterotypes to be fulfilled. If I want a picture of a cellphone, I want an ambiguous black rectangle, even though wacky phones exist[1]
[1] https://static1.srcdn.com/wordpress/wp-content/uploads/2023/...
And the stereotype the person asking would expect will heavily depend on where they're from.
Before you ask for stereotypes: Whose stereotypes? Across which population? And why does those stereotypes make sense?
I think Google fucked up thoroughly here, but they did so trying to correct for biases also gets things really wrong for a large part of the world.
If the data is lumpy in one area then I figure let the model represent the data and allow the human to determine the direction of skew in a transparent way.
The Nerfing based upon some internal activism that's hidden is frustrating because it'll call into question any result as suspect to bias towards unknown Morlocks at Google.
For some reason Google intentionally stopped historically accurate images from being generated. Whatever your position, provided you value Truth, these adjustments are abhorrent.
Try these exact prompts in Midjourney and you will get exactly what you would expect.
No, it's not reasonable. It goes against actual history, facts, and collected statistics. It's so ham-fisted and over the top, it reveals something about how ineptly and irresponsibly these decisions were made internally.
An unfair use of a stereotype would be placing someone of a certain ethnicity in a demeaning context (eg, if you asked for a picture of an Irish person and it rendered a drunken fool).
The Google wokeness committee bolted on something absurdly crude, seems like "when showing people, always include a black, an asian and an native american person" which rightfully results in a pushback from people who have brains.
Google has a history of pushing woke agendas with funny results. For example, there was a whole thing about searching for "happy white man" and "happy black man" a couple years ago. It would always inject black men somewhere in the results searching for white men, and the black man results would have interracial couples. Same kind of thing happened if you searched for women of a particular race.
The sad thing in all of this is, there is actively racism against white people in hiring at companies like this, and in Hollywood. That is far more serious, because it ruins lives. I hear interviews with writers from Hollywood saying they are explicitly blacklisted and refused work anywhere in Hollywood because they're straight white men. Certain big ESG-oriented investment firms are blowing other people's money to fund this crap regardless of profitability, and it needs to stop.
It’s really hard to get these things right: if you don’t attempt to influence the model at all, the nature of the imagery that these systems are being trained on skews towards stereotype, because a lot of our imagery is biased and stereotypical. It seems perfectly reasonable to say that generated imagery should attempt to not lean into stereotypes and show a diverse set of people.
In this case it fails because it is not using broader historical and social context and it is not nuanced enough to be flexible about how it obtains the diversity- if you asked it to generate some WW2 American soldiers, you could rightfully include other ethnicities and genders than just white men, but it would have to be specific about their roles, uniforms, etc.
(Note: I work at Google, but not on this, and just my opinions)