What I've seen again and again from people in the field is a gross underestimation of the long tail on these problems. They see the rapid results on the easier end and think it will translate to continued process, but the reality is that every order of magnitude improvement takes the same amount of effort or more.
On top of that there is a massive amount of subsidies that go into training these models. Companies are throwing millions of dollars into training individual modules. The cost here seems to be going up, not down, as these improvements are made.
I also think, to be honest, that machine learning researchers tend to simplify problems more than is reasonable. This conversation started with "highly scalable system from scratch, or an ultra-low latency trading system that beats the competition" and turned into "the parsing of and generation of this kind of code"- which is in many ways a much simpler problem than what op proposed. I've seen this in radiology, robotics, and self driving as well.
Kind of a tangent, but one of the things I do love about the ML industry is the companies who recognize what I mentioned above and work around it. The companies that are going to do the best, in my extremely bias opinion, are the ones that use AI to augment experts rather than try to replace them. A lot of the coding AI companies are doing this, there are AI driving companies that focus on safety features rather than driver replacement, and a company I used to work for (Rad AI) took that philosophy to Radiology. Keeping experts in the loop means that the long tail isn't as important and you can stop before perfection, while replacing experts altogether is going to have a much higher bar and cost.
Try at least 12 [0]
(I would say 15 but my 45-second search didn't yield anything that far back)
[0] https://spectrum.ieee.org/how-google-self-driving-car-works
This is a bit like seeing Steve Mann's wearable computers over the years ( https://cdn.betakit.com/wp-content/uploads/2013/08/Wearcompe... ) and then today anyone with a smartphone and smart watch has more computing power and more features than most of his gear ever had, apart from the head mounted screen. More processing power, more memory, more storage, more face recognition, more motion sensing, more GPS, longer runtime on battery, more bandwidth and connectivity to e.g. mapping, more assistants like Google Now and Siri.
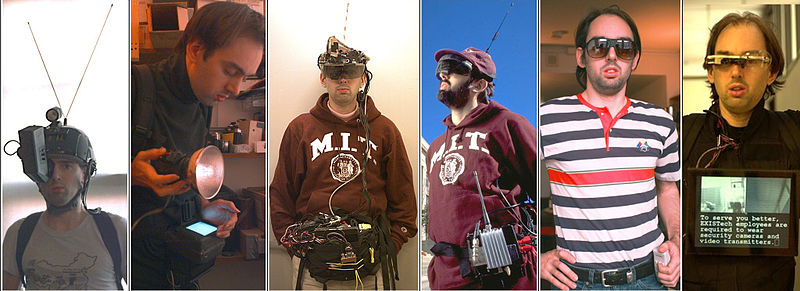
And we still aren't at a level where you can be doing a physical task like replacing a laptop screen and have your device record what you're doing, with voice prompts for when you complete different stages, have it add markers to the recording, track objects in the scene like and solve for questions like 'where did that longer screw go?' or 'where did this part come from?' and have it jump to the video where you took that part out. Nor reflow the video backwards as an aide memoire to reassembling it. Or do that outside for something like garage or car work, or have it control and direct lighting on some kind of robot arm to help you see, or have it listen to the sound of your bike gears rattle as you tune them and tell you or show you on a graph when it identifies the least rattle.
Anything a human assistant could easily do, we're still at the level of 'set a reminder' or 'add to calendar' rather than 'help me through this unfamiliar task'.
RE: changing you laptop screen. My buddy wants an 'AR for Electronics' that can zoom in on components like a magnifying glass (he wants head mounted), identify components by marking/color/etc and call up schematics on demand. So far, nothing seems to be able to do that basic level of work.
AI companies such as Vicarious have been promising AI that makes this easier. Their idea was that generic robots with the right grips and sensors can be configured to work on a variety of assembly lines. This way a factory can be retooled between jobs quicker and with less cost.
Fanuc, the robot manufacturer, famously does run a lights-out factory, and has since 2001. It was the dream of Fanuc's founder. Baosteel now has a lights-out steel coiling facility. Both of these are more PR than cost effective.
There are many factories where there are very, very few people for large rooms full of machines, though.
This comment from 7 days ago covers it adequately:
It's a cautionary tale to people who are working in ML to be not too optimistic on "the future", but in my opinion being cautiously optimistic(not on AGI though) isn't harmful by itself, and I stand by that. Well at least until we hit the next wall and plunge everyone into another AI winter(fourth? fifth?) again.
As a plus, we do actually see some good progress that benefited the world like in biotech. Even though we are still mostly throwing random stuffs at ML to see if it works. Time will tell I guess.
I think even three years ago, most people would have thought the reverse.
So Kurzweil was imagining the turing test as the capstone to a decade of more and more capable ai products, not as "kind of early interesting success that may (or may not) presage really useful AI."
("The Turing test" is a pretty hazy target. I have no doubt that a chatgpt that was not trained to loudly announce that it was an AI could convince lots of people that it's a real human, right now. I think it's also the case that people with some experience with it could pretty quickly find ways to tell what it is.)
Otherwise you risk claiming ELIZA passed it, because a couple people thought so. Or that one Google employee this time.
Not because goal posts keep moving, but because we can only do 80% of the remaining distance each time, and the remaining 20% is still obvious.
If I were to make a point as to why your notes on self-driving cars and in-warehouse robots may not transfer to the case of software development, it's that they are fundamentally two very different problems with very different issues attached to them. It unfortunately is very much apples to oranges. They are both NP-hard but very different kinds of NP-hard.
A software program is a closed-loop target, though it is NP-hard. But we're optimizing for a different kind of metric here that is well-defined. Any kind of self-directed reinforcement-or-otherwise autoregressive-in-the-world algorithm is going to have an extraordinarily long tail of edge cases.
What I was talking about when I mentioned the geometry of the problem is not the parsing of the code, but the geometry of a near-optimal solution. Certainly, scale will be expensive, but Sutton is our friend here. That's why it's more "trivial" than problems that require humans in the loop -- you don't need humans to parse, structure, generate, and evaluate the data flow of a software code base, though admittedly if models like RHLF become popular as you noted, the endpoints that generate code under those geometric constraints -- those will become extremely expensive.
I think the geometric problem is very hard but the hurdle of scaled language models is more technically impressive to me.
What's nice is that unlike needing to generate a long, 1d story, too, there's more robustness with a huge field of possibility that's had years of work on the software side of things. It's not that it's going to be easy, but I think we've all grown as we've seen how hard self-driving cars are, and it's just not that kind of scenario, since all consequences of the 'world' within the repo-generation case are (for the most part) self-contained.
I hope that helps elucidate the problems a bit. To me, my optimism is much more rare, and only generally when I feel like I have a solid grasp of the fundamentals of it enough (i.e. I roughly know deliverability and have decent known error bounds on the sub-problems).
That said, I heartily agree with you that when all else fails -- assistive is good. What I see a "complete solution" doing well is creating a Kolmogorov-minimal, complete starting point and things evolving from there. Whether that works or not remains to be seen.
Those are the most precarious jobs in the industry. Many of those people might become LLM whisperers, taking their clients requests and curating prompts. Essentially becoming programmers over the prompting system. Maybe they’ll write a transpiler to generate prompts? This would be par of the course with other languages (like SQL) that were originally meant to empower end-users.
The problem with current AI generated code from neural networks is the lack of an explanation. Especially when we’re dealing with anything safety critical or with high impact (like a stock exchange), we’re going to need an explanation of how the AI got to its solution. (I think we’d need the same for medical diagnosis or any high-risk activity). That’s the part where I think we’re going to need breakthroughs in other areas.
Imagine getting 30,000-ish RISCV instructions out of an AI for a braking system. Then there’s a series of excess crashes when those cars fail to brake. (Not that human written software doesn’t have bugs, but we do a lot to prevent that.). We’ll need to look at the model the AI built to understand where there’s a bug. For safety related things we usually have a lot of design, requirement, and test artifacts to look at. If the answer is ‘dunno - neural networks, ya’ll’, we’re going to open up serious cans of worms. I don’t think an AI that self evaluates its own code is even on the visible horizon.
I gave some code to ChatGPT asking to simplify it and it returned the correct code but off by one. It was something dealing with dates, so it was trivial to write a loop checking for each day if the new code matched in functionality the old one.
You will never have certainty the code makes any sense if it's coming from one of these high tech parrots. With a human you can at least be sure the intention was there.
I was able to give ChatGPT the requirements for all of them. The types of bugs I found during the first pass:
- the AWS SDK and the underlying API only returns 50 results in one call most of the time. From the SDK you have to use the built in “paginators”. ChatGPT didn’t use them the first time. But once I said “this will only return the first 50 results”. It immediately corrected the script and used the paginator. I have also had to look out for similar bugs from junior devs.
- The usual yaml library for Python doesn’t play nicely with CloudFormation templates because of the function syntax that starts with an “!”. I didn’t know this beforehand. But once I told ChatGPT the error, it replaced the yaml handling with cfn-flip.
- I couldn’t figure out for the life of me how to combine the !If function in CloudFormation with a Condition, and a Yaml block that contain another !Select function with two arguments. I put the template block without the conditional and told ChatGPT “make the VPC configuration optional based on a parameter”. It created the Parameter section, the condition and the appropriate Yaml.
I’ve given similar problems to interns/junior devs before and ChatGPT was much better at it.
Which ok I get why you think ChatGPT is more useful.
Now if ChatGPT would be able to actually work on the problem rather than returning generated text, that would be a completely different beast. And I think that this workflow will come in the near future because it's pretty obvious idea. Get task specification, generate tests, generate code, fix code until tests work, refactor code until it meets some standards, etc.
You give junior devs way too much credit. They rarely test corner cases.
ChatGPT probably works great if you use it to speedrun normal best practices in software engineering. Make it start by writing tests given a spec, then make it write code that will pass the specific tests it just wrote. I’m guessing it’ll avoid a lot of mistakes, much like any engineer, if you force it to do TDD.
“Given an XML file with the format {[1]} and a DynamoDB table with two fields “Key”, “Value”, write a Python script that replaces the Value in the xml file when the corresponding key is found. Use argparse to let me specify both the input xml file and the output XML”
It spit out perfect Python code. I hadn’t used XML in well over a decade and I definitely didn’t know how to read xml in Python. I didn’t want to bother about learning.
I actually pasted an XML sample like the link below.
[1] https://learn.microsoft.com/en-us/troubleshoot/developer/vis...
I think you have that exactly backwards.
Most junior developers most places may not have the experience of a senior developer, and thus be able to do the translation from business logic to code quite as fast and accurately the first time, but this kind of derogatory attitude toward them is incredibly condescending and insulting.
ChatGPT doesn't know what it's doing. It doesn't know anything, and unlike the most junior developer barely trained, it can't even check its output to see if it matches the desired output.
And for goodness' sake, get rid of the absurd idea that all the competent developers are in Silicon Valley. That's even more insulting to the vast majority of developers in the entire world.
Define "we". There are all kinds of people with all kinds of opinions. I didn't notice any consensus on the questions of AI. There are people with all kinds of educations and backgrounds on the opposite sides and in-between.
For example...
Hows that self-driving going? Got all those edge-cases ironed out yet?
Oh, by next year? Wierd, that sounds very familiar...
Remember about Tesla's autopilot was released 9 years ago, and the media began similar speculation about how all of the truckers were going to get automated out of a job by AI? And then further speculation about how Taxi drivers were all going to be obsolete?
Those workers are the ones shifting the goal posts though as a "self-defense mechanism", sure, sure... lol.
With self-driving, we barely ever saw anything obviously resembling human abilities, but there was a lot of marketing promising more.
With language models when GPT-2 came out everyone was still saying it is a "stochastic parrot" and even GPT-3 was one. But now there's ChatGPT, and every single teenager is aware that that tool is capable of replacing them with their school assignments. And as a dev I am aware that it can write code. And yet not many people expected any of this to happen this year, neither were those capabilities promised at any point in the past.
So if anything, self-driving was always overhyped, while the LLMs are quite underhyped.
One difference, though, is that it‘s economically not much use to have self-driving if the backup driver has to be in the car or present. While partially automating programming would make it possible to use far less programmers for the same amount of work.
Now you could say that LLMs enable Google to do what it does now with fewer employees, but the same thing is true for every other competitor to Google. So the question is how will Google try and maintain dominance over it's competitors now? Likely they will invest more heavily in AI and probably make some riskier decisions but I don't see them suddenly trying to cheap out on talent.
I also think that it's not a zero sum game. The way that technology development has typically gone is the more you can deliver, the more people want. We've made vast improvements in efficiency and it's entirely possible that what an entire team's worth of people was doing in 2005 could be managed by a single person today. But technology has expanded so much since then that you need more and more people just to keep up pace.
While I wouldn't dare offer particular public prognostications about the effect transformer codegens will have on the industry, especially once filtered through a profit motive - the specific technical skill a programmer is called upon to learn at various points in their career has shifted wildly throughout the industry's history, yet the actual job has at best inflected a few times and never changed very dramatically since probably the 60s.
Which, of course, is what we've always done; modern programming, with its full-featured IDEs, high level languages, and feature-rich third-party libraries is mostly about gluing together things that already exist. We've already abstracted away 99% of programming over the last 40 years or so, allowing a single programmer today to build something in a weekend that would have taken a building full of programmers years to build in the 1980s. The difference is, of course, this is going to happen fairly quickly and bring about an upheaval in the software industry to the detriment of a lot of people.
And of course, this doesn't include the possibility of AGI; I think we're a very long way from that, but once it happens, any job doing anything with information is instantly obsolete forever.
10 years ago we were still working on MNIST prediction accuracy. 10 years forward from here all bets are off. If the model has super human quantitative reasoning and a mastery of language I am not sure how much programming we will be doing compared to moving to a higher level of abstraction.
On the other hand, I think there will be so many new software jobs because of the volume of software built over the next 20 years. The volume of software built over the next 20 years is probably unimaginable sitting where we are.
In this case, it could be that you are just talking to different people and focusing on their answers. I am more than happy to believe that Copilot and ChatGPT, today, cause a bunch of people fear. Does it cause me fear? No.
And if you had asked me five years ago "if I built a program that was able to generate simple websites, or reconfigure code people have written to solve problems similar to ones solved before, would that cause you to worry?" I also would have said "No", and I would have looked at you as crazy if you thought it would.
Why? Because I agree with the person you are replying to (though I would have used a slightly-less insulting term than "trash engineers", even if mentally it was just as mean): the world already has too many "amateur developers" and frankly most of them should never have learned to program in the first place. We seriously have people taking month or even week long coding bootcamps and then thinking they have a chance to be a "rock star coder".
Honestly, I will claim the only reason they have a job in the first place is because a bunch of cogs--many of whom seem to work at Google--massively crank the complexity of simple problems and then encourage us all to type ridiculous amounts of boilerplate code to get simple tasks done. It should be way easier to develop these trivial things but every time someone on this site whines about "abstraction" another thousand amateurs get to have a job maintaining boilerplate.
If anything, I think my particular job--which is a combination of achieving low-level stunts no one has done before, dreaming up new abstractions no one has considered before, and finding mistakes in code other people have written--is going to just be in even more demand from the current generation of these tools, as I think this stuff is mostly going to encourage more people to remain amateurs for longer and, as far as anyone has so far shown, the generators are more than happy to generate slightly buggy code as that's what they were trained on, and they have no "taste".
Can you fix this? Maybe. But are you there? No. The reality is that these systems always seem to be missing something critical and, to me, obvious: some kind of "cognitive architecture" that allows them to think and dream possibilities, as well as a fitness function that cares about doing something interesting and new instead of being "a conformist": DALL-E is sometimes depicted as a robot in a smock dressed up to be the new Pablo Picasso, but, in reality, these AIs should be wearing business suits as they are closer to Charles Schmendeman.
But, here is the fun thing: if you do come for my job even in the near future, will I move the goal post? I'd think not, as I would have finally been affected. But... will you hear a bunch of people saying "I won't be worried until X"? YES, because there are surely people who do things that are more complicated than what I do (or which are at least different and more inherently valuable and difficult for a machine to do in some way). That doesn't mean the goalpost moved... that means you talked to a different person who did a different thing, and you probably ignored them before as they looked like a crank vs. the people who were willing to be worried about something easier.
And yet, I'm going to go further: if the things I tell you today are what are required to make me worry happen and yet somehow I was wrong and it is the future and you technically do those things and somehow I'm still not worried, I guess you can continue to complain about the goalposts being moved, but is it really my fault?
The reality is that humans aren't always good at telling you what you are missing or what they need; and I appreciate that it must feel frustrating providing a thing which technically implements what they said they wanted and it not having the impact you expected--there are definitely people who thought that, with the tech we have now long ago pulled off, cars would be self-driving... and like, cars sort of self-drive? and yet, I still have to mostly drive my car ;P--then I'd argue the field still "failed" and the real issue is that I am not the customer who tells you what you have to build and, if you achieve what the contract said, you get paid: physics and economics are cruel bosses whose needs are oft difficult to understand.
As programmers, we keep talking about programming jobs and how AI will eliminate them all. But nobody is talking about eliminating other jobs. When will a robot vacuum be able to clean my apartment as quickly as I? Why isn't there a robot that takes my garbage out on Tuesday night? When will AI plan and build a new tunnel under the Hudson River for trains? When will airliners be pilotless? If AI can't do this stuff, what makes software so different? Why will AI be good at that but not other things? It seems like the only goal is to eliminate jobs doing things people actually like (art, music, literature, etc.), and not eliminate any tedium or things that is a waste of humanity's time whatsoever.
(On the software front, when will AI decide what software to build? Will someone have to tell it? Will it do it on its own? Why isn't it doing this right now?)
My takeaway is that this all raises a lot of questions for me on how far along we actually are. Language models are about stringing together words to sound like you have understanding, but the understanding still isn't there. But, I suppose we won't know understanding until we see it. Do we think that true understanding is just a year or two away? 10? 50? 100? 1000?
You could make the same argument as with self-driving cars, that people already get hurt this way and maybe the robot is in fact safer. But it's still a hard sell that Sunny-01 has only accidentally killed 1/10 as many children as parents have—the number has to be more like zero.
Let's solve automating trains first then we can do airliners.
Since all a codebase like that is is a kind of directed graph, then augmentations to the processing of the network to allow for the simultaneous parsing of and generation of this kind of code may not be as far off as you thinking.
I say this as an ML researcher of coming up and around the bend towards 6 years of experience in the heavily technical side of the field. Strong negative skepticism is an easy way to bring confidence and the appearance of knowledge, but it also can have the downfall of what has happened in certain past technological revolutions -- and the threat is very much real here (in contrast to the group that believes you can get AGI from simply scaling LLMs, I think that is very silly indeed).
Thank you for your comment, I really appreciate it and the discussion it generated and appreciate you posting it. Replying to it was fun, thank you.