Try at least 12 [0]
(I would say 15 but my 45-second search didn't yield anything that far back)
[0] https://spectrum.ieee.org/how-google-self-driving-car-works
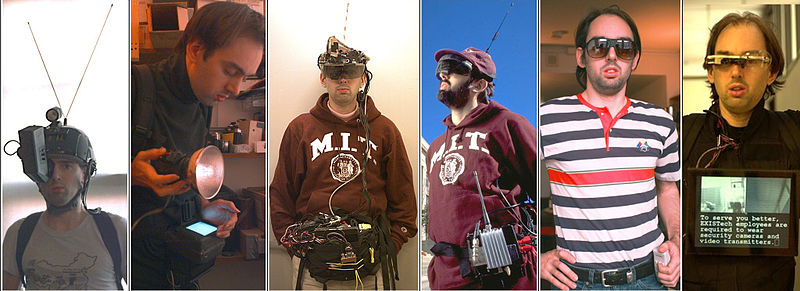
This is a bit like seeing Steve Mann's wearable computers over the years ( https://cdn.betakit.com/wp-content/uploads/2013/08/Wearcompe... ) and then today anyone with a smartphone and smart watch has more computing power and more features than most of his gear ever had, apart from the head mounted screen. More processing power, more memory, more storage, more face recognition, more motion sensing, more GPS, longer runtime on battery, more bandwidth and connectivity to e.g. mapping, more assistants like Google Now and Siri.
And we still aren't at a level where you can be doing a physical task like replacing a laptop screen and have your device record what you're doing, with voice prompts for when you complete different stages, have it add markers to the recording, track objects in the scene like and solve for questions like 'where did that longer screw go?' or 'where did this part come from?' and have it jump to the video where you took that part out. Nor reflow the video backwards as an aide memoire to reassembling it. Or do that outside for something like garage or car work, or have it control and direct lighting on some kind of robot arm to help you see, or have it listen to the sound of your bike gears rattle as you tune them and tell you or show you on a graph when it identifies the least rattle.
Anything a human assistant could easily do, we're still at the level of 'set a reminder' or 'add to calendar' rather than 'help me through this unfamiliar task'.
RE: changing you laptop screen. My buddy wants an 'AR for Electronics' that can zoom in on components like a magnifying glass (he wants head mounted), identify components by marking/color/etc and call up schematics on demand. So far, nothing seems to be able to do that basic level of work.
AI companies such as Vicarious have been promising AI that makes this easier. Their idea was that generic robots with the right grips and sensors can be configured to work on a variety of assembly lines. This way a factory can be retooled between jobs quicker and with less cost.
Fanuc, the robot manufacturer, famously does run a lights-out factory, and has since 2001. It was the dream of Fanuc's founder. Baosteel now has a lights-out steel coiling facility. Both of these are more PR than cost effective.
There are many factories where there are very, very few people for large rooms full of machines, though.
This comment from 7 days ago covers it adequately:
It's a cautionary tale to people who are working in ML to be not too optimistic on "the future", but in my opinion being cautiously optimistic(not on AGI though) isn't harmful by itself, and I stand by that. Well at least until we hit the next wall and plunge everyone into another AI winter(fourth? fifth?) again.
As a plus, we do actually see some good progress that benefited the world like in biotech. Even though we are still mostly throwing random stuffs at ML to see if it works. Time will tell I guess.
I think even three years ago, most people would have thought the reverse.
So Kurzweil was imagining the turing test as the capstone to a decade of more and more capable ai products, not as "kind of early interesting success that may (or may not) presage really useful AI."
("The Turing test" is a pretty hazy target. I have no doubt that a chatgpt that was not trained to loudly announce that it was an AI could convince lots of people that it's a real human, right now. I think it's also the case that people with some experience with it could pretty quickly find ways to tell what it is.)
Otherwise you risk claiming ELIZA passed it, because a couple people thought so. Or that one Google employee this time.
Not because goal posts keep moving, but because we can only do 80% of the remaining distance each time, and the remaining 20% is still obvious.
If I were to make a point as to why your notes on self-driving cars and in-warehouse robots may not transfer to the case of software development, it's that they are fundamentally two very different problems with very different issues attached to them. It unfortunately is very much apples to oranges. They are both NP-hard but very different kinds of NP-hard.
A software program is a closed-loop target, though it is NP-hard. But we're optimizing for a different kind of metric here that is well-defined. Any kind of self-directed reinforcement-or-otherwise autoregressive-in-the-world algorithm is going to have an extraordinarily long tail of edge cases.
What I was talking about when I mentioned the geometry of the problem is not the parsing of the code, but the geometry of a near-optimal solution. Certainly, scale will be expensive, but Sutton is our friend here. That's why it's more "trivial" than problems that require humans in the loop -- you don't need humans to parse, structure, generate, and evaluate the data flow of a software code base, though admittedly if models like RHLF become popular as you noted, the endpoints that generate code under those geometric constraints -- those will become extremely expensive.
I think the geometric problem is very hard but the hurdle of scaled language models is more technically impressive to me.
What's nice is that unlike needing to generate a long, 1d story, too, there's more robustness with a huge field of possibility that's had years of work on the software side of things. It's not that it's going to be easy, but I think we've all grown as we've seen how hard self-driving cars are, and it's just not that kind of scenario, since all consequences of the 'world' within the repo-generation case are (for the most part) self-contained.
I hope that helps elucidate the problems a bit. To me, my optimism is much more rare, and only generally when I feel like I have a solid grasp of the fundamentals of it enough (i.e. I roughly know deliverability and have decent known error bounds on the sub-problems).
That said, I heartily agree with you that when all else fails -- assistive is good. What I see a "complete solution" doing well is creating a Kolmogorov-minimal, complete starting point and things evolving from there. Whether that works or not remains to be seen.
What I've seen again and again from people in the field is a gross underestimation of the long tail on these problems. They see the rapid results on the easier end and think it will translate to continued process, but the reality is that every order of magnitude improvement takes the same amount of effort or more.
On top of that there is a massive amount of subsidies that go into training these models. Companies are throwing millions of dollars into training individual modules. The cost here seems to be going up, not down, as these improvements are made.
I also think, to be honest, that machine learning researchers tend to simplify problems more than is reasonable. This conversation started with "highly scalable system from scratch, or an ultra-low latency trading system that beats the competition" and turned into "the parsing of and generation of this kind of code"- which is in many ways a much simpler problem than what op proposed. I've seen this in radiology, robotics, and self driving as well.
Kind of a tangent, but one of the things I do love about the ML industry is the companies who recognize what I mentioned above and work around it. The companies that are going to do the best, in my extremely bias opinion, are the ones that use AI to augment experts rather than try to replace them. A lot of the coding AI companies are doing this, there are AI driving companies that focus on safety features rather than driver replacement, and a company I used to work for (Rad AI) took that philosophy to Radiology. Keeping experts in the loop means that the long tail isn't as important and you can stop before perfection, while replacing experts altogether is going to have a much higher bar and cost.