Platform integration: libc, winapi, winapi-build, winapi-i686-pc-windows-gnu, winapi-x86_64-pc-windows-gnu, ws2_32-sys, fuchsia-zircon, fuchsia-zircon-sys, kernel32-sys, redox_syscall
Primitive algorithms: itoa, memchr, unicode-xid
Proc macro / pinning utilities: proc-macro2, autocfg, cfg-if, lazy_static, quote, syn, pin-project, pin-project-internal, pin-project-lite, pin-utils
Data structures: bitflags, bytes, fnv, hashbrown, indexmap, slab
Core Rust asyncio crates: mio, miow, iovec, tokio, tokio-util, futures-channel, futures-core, futures-sink, futures-task, futures-util,
Logging: log, tracing, tracing-core
The following are effectively sub-crates of the project: http, http-body, httparse, httpdate, tower-service, h2
Not sure what these are for: net2, socket2, try-lock, want
If those platform crates are just backends for libc (or similar to libc), why aren't they all folded in a single project? Having them as separate crates open the gate for supply-chain attacks without really allowing greater control or expressiveness. You are always going to pull all of them in, you are unlikely to ever use them directly, and they have no more impact on compilation than features.
Having to use proc-macro2+quote+syn for macros feels wrong, considering it's a language feature.
Having to pull in 4 crates for pinning also seems wrong. This could easily be a single utility crate, and if you really need all this cruft to use Pin (a language feature) most of this should probably be in std.
The async I/O feels like definite bloat. Not only is that a lot of futures-* crates, but I know from first-hand experience that those tend to implement multiple versions of some primitives (like streams) that are incompatible.
They're not, they're to the specific platform's APIs. The libc crate is a package that targets libc on every platform.
> Having to use proc-macro2+quote+syn for macros feels wrong, considering it's a language feature.
In order to ship procedural macros as a feature, they're pretty minimal. There's a tradeoff here; others could be chosen, but weren't for good reasons.
> Having to pull in 4 crates for pinning also seems wrong.
This is covered by https://news.ycombinator.com/item?id=24730280; that is, it's a transitive dependency issue.
> The async I/O feels like definite bloat.
Really depends, network calls are a textbook use-case for async I/O. And there's so many futures crates specifically so that you can only depend on the bits you need.
> Since Rust 1.36, this is now the HashMap implementation for the Rust standard library. However you may still want to use this crate instead since it works in environments without std, such as embedded systems and kernels.
I don't know if that use case is important to Hyper or not.
I wish it relied only on OpenSSL.
Also I find the dependency on OpenSSL one major pain in my Rust projects. When you want to build a statically linked binary you need to supply a statically built OpenSSL and if your distro doesn't come with one (like Ubuntu) you are on your own. Yes, there is a Docker container that comes with all the prerequisites but I think that's a bit heavy for my purposes.
I wish there was a single switch in Cargo.toml and every dependency would automagically use rustls.
I think any dependency adds a level of burden, but some things are better delegated to library. I think crypto is a good case, btw I think OpenSSL is not the only one lib for TLS with curl.
This sits wrong with me, but thinking about it: I rewrote the sentence about containers in my comment three times before posting it and it still doesn't sound compelling. Maybe you have a point here.
https://daniel.haxx.se/blog/wp-content/uploads/2020/09/curl-...
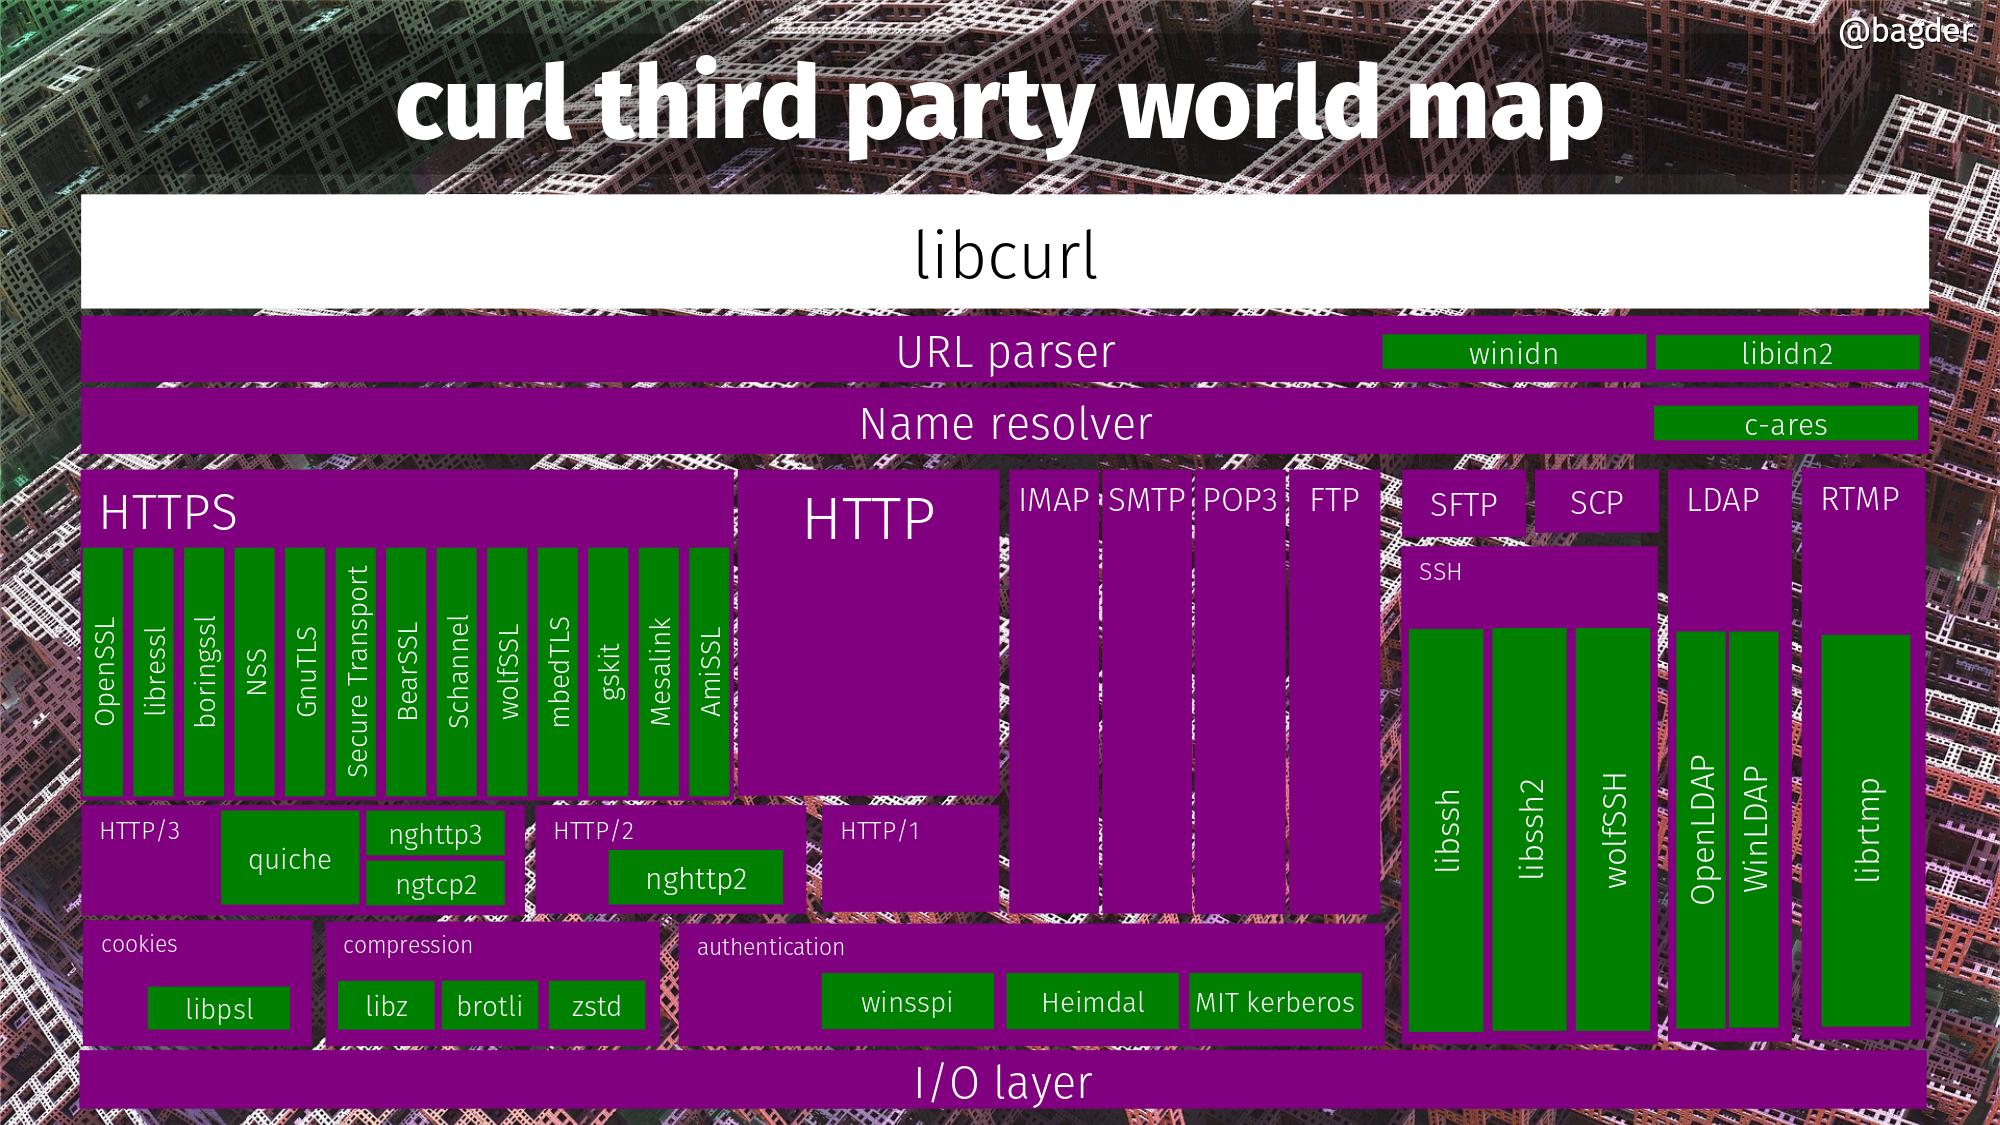
Specifically if you use SChannel, you get the CA roots from Microsoft's CA Root programme, whereas ordinarily you'll end up with (some derivative of) the Mozilla CA root programme.
You also get the local policy root overrides. So for example in many corporate networks with a middlebox ensuring employees don't look at porn, the middlebox is trusted according to Windows Group Policy. Now your Curl program works the same way as Internet Explorer does, if the site is trusted in IE then it's trusted in Curl.
On the other hand, this means that the SChannel enabled Curl trusts different things from the Curl on platforms with OpenSSL. Maybe this new setup works "fine" in SChannel Curl, but only when you try from a Linux do you discover that your new site doesn't work at all any more without Microsoft's trust list, which explains the thousands of new tickets filed by (mostly Linux using) customers whose product just mysteriously broke even though it looked fine on your Windows test machine and you've just closed a dozen of those tickets as WORKSFORME...
Looking at the authors and publishers numbers from https://github.com/rust-secure-code/cargo-supply-chain it's clear a lot of these are maintained by the same set of trusted folks.
My main worry about Rust dependencies is not so much the number, it's that it's still a fairly young ecosystem that hasn't stabilized yet, packages come and go fairly quickly even for relatively basic features. For instance for a long time lazy_static (which is one of the dependencies listed here) was the de-facto standard way of dealing with global data that needed an initializer. Apparently things are changing though, I've seen many people recommend once_cell over it (I haven't had the opportunity to try it yet).
Things like tokio are also moving pretty fast, I wouldn't be surprised if something else took over in the not-so-far future.
It's like that even for basic things: a couple of years ago for command line parsing in an app I used "argparse". It did the job. Last week I had to implement argument parsing for a new app, at first I thought about copy/pasting my previous code, but I went on crates.io and noticed that argparse hadn't been updated in 2years and apparently the "go to" argument parsing lib was now "clap". So I used clap instead. Will it still be used and maintained two years from now? Who knows.
Some parts of the ecosystem are more stable than others. That's true. And it takes work to know which things are stable and which aren't.
And yet, some things just take a longer time to improve. lazy_static has been stable and unchanged for a very long time and it works just fine. You don't need to switch to once_cell if you don't want to. lazy_static isn't going anywhere. The real change here, I think, is that we're hoping to get a portion of once_cell into std so that you don't need a dependency at all for it.
The async ecosystem is definitely moving more quickly because it just hasn't had that much time to stabilize. If you're using async in Rust right now then you're probably an early adopter and you'll want to make sure you're okay with the costs that come with that.
I guess what I'm saying is that it's an other problem with the current package ecosystem: you often end up finding multiple packages purporting to do what you need, and it can be tricky to figure out which one you want. As an example, if you want a simple logging backend the log crate currently lists 6 possibilities: https://crates.io/crates/log
I picked "simple_logger" basically at random.
I'm trying to remember the last language I've used where people didn't say that.
Hmm... clojure? Nop.
Javascript? Nop nop nop.
Python? Hahaha I can't even remember all the package managers: virtualenv, venv, pipenv, poetry, ...
The STL package contains lots of things, but most of them are pretty ugly to use and quite a few of them are quite complicated to use because they are generalized for as many use cases as possible. There are so many authors out there that decide they can do memory management manually, write their own thread or process pools, implement sorting in a different way, rewrite basic algorithms for list operations like mapping, filtering, zipping, reducing...
Simply counting the number of dependencies isn't a great indicator for dependency bloat. There are extremes on both ends : no deps --> I know everything better and reimplemented the world, and thousands of deps --> I put a one liner in a package ma! One should not judge too quickly.
> These complaints are valid, but my argument is that they’re also not NEW, and they’re certainly not unique to Rust ... The only thing new about it is that programmers are exposed to more of the costs of it up-front.
While thats true, it completely misses the point. The point is not that dependencies exist, or even that a package might have many dependencies.
The point is, Rust (and NPM) I have found many times dont care or even consider the impact of a large amount of dependencies, and often take no steps to mitigate or reduce that number.
As others said, some features could be split off into other crates. Maybe someone only needs HTTP, or maybe they need HTTPS but no Async. Or maybe they dont need logging. With Hyper and others you just have to build everything whether you want it or not.
I agree with this, but that's not what your original post says. Or at least, it’s not what I understood from reading it. :)
> The point is, Rust (and NPM)
and C, in many real-world cases, which is why the above post matters.
Same in Rust. Actually, it's quite better than in C. The only time Rust projects fail to compile is when they pull in some C library and something there (like configure.ac) messed up. :D
And if this C project does anything interesting it pulls in bunch of C libraries that came precompiled with your OS, and might be stale and contain unpatched security vulns.
C/C++ developers pointing at other languages about dependency hell is a curiosity.
This is the primary reason I try to avoid projects built with npm. Fucking dependency hell. If the project hasn't been actively maintained in the last 3 months your chances of getting it to work drop precipitously.
People love to trash Perl on HN. But among many other things that Perl devs understood, they deeply understood issues that come up with dependencies. Most CPAN modules are namespaced, have unit tests, and unit tests run when modules are installed. Not only that, the people behind CPAN understood that it is a community effort and you, as a library author, have certain responsibilities to your community.
https://pause.perl.org/pause/query?ACTION=pause_04about
None of that exists in npm. We have scopes in npm, and that's about it. CPAN makes npm look like a child's toy.
That's funny, because it's only "new" if your experiences primarily lie in newer languages and communities. There's a lot of criticism of C, but one thing it does is make dependencies pretty explicit. Some say that's good, some say that's bad, I guess it can be both at different times.
Let's say you open up a new C codebase: What are its dependencies? You'll have to hunt through its README (hopefully it's up to date!), other build instructions, maybe CMake, maybe some custom build system, etc.
What version of dependencies does it use? If the code has been vendored, you at least know what code its using - but where do you look for updates to that code? Do you manually go out to wherever it was copied from now and then and look for updates? If the code isn't vendored, then how was it installed? From the package manager? If so, what operating system and version was used during development? If its not from a package, its might have been downloaded and installed manually? Again, where was it downloaded from? Where was it installed? What options did it use when it was compiled?
How do you handle transitive dependencies? Probably by hand. How well documented are they?
C suffers plenty of dependency issues.
Also if you are dynamic linking, ldd(1) can give you a pretty good picture.
TLS implementions are often giant hairballs but one that many things depend on. You can think of it as a somewhat "system level" dependency.
Also, I coud imagine Rust's type-system raises the bar of dependencies that can be mangaged before everything breaks down. So a lib with 100 deps in NPM isn't the same as a lib with 100 deps in Cargo.
Edit: I mean if you don't use ~ or ^ in your nose dependencies,. Just explicit versions.
I am all about improving the world, don't get me wrong, but saying "hey this software works just like all the other software" isn't really the insult that you seem to think that it is.
Well, it's common knowledge that most existing software is compete and utter crap, as evidenced by the fact that our first thought upon hearing that a particular piece of software is no longer being updated is not "oh good, it is (probably) finished and we can rely on it", but rather "on no, now the innumerable defects no doubt still latent in it will remain unfixed". So "this software is just as bad as all the other software" is, while not a very grave insult in a relative sense, still quite damning in absolute terms.
One good thing about stat counters for packages combined with GitHub for issue tracking of you can kind of tell.
It does take some level of die diligence and isn't easy. But neither is anything relying on say system installed libraries in C projects.
I'd rather have the package managers than not.
- a significant (eg, at least as complex as wget) software project,
- that has been unmaintained (no updates, code has the same MD5/etc hash),
- with a significant userbase (not sure exactly how to define that one),
- for a significant amount of time (at least five years),
- which is generally regarded as finished and bug-free (not in need of further development) rather than abandoned?
Because I can't think of a single one, and the only ones that even come close are video games where the known bugs were co-opted into gameplay features. The general consensus seems to be that any system that doesn't have automatic updates running is de-facto insecure (which, since every update mechanism I've heard of can introduce new code (ie new security vulnerabilities), means any system whatsoever is insecure).
(I don't quite disagree with the tacit assertion that actually getting things right on - if not the first try - then at least one of the first thirty or so is a extremely, maybe even unreasonably high standard, but it manifestly is a standard that basically all existing nontrivial software projects fail to meet.)
They could have said it straight "Guys highly optimized, safe compilation of medium size project will be in range of 20-30 min". And that would great and honest way to deal. Instead we get oh, we have reduced compile times from 26 minutes to 21 minutes so it is 19% improvement in just one year and there is more to come. Now this is hard work and great but I am sure Rust committers understand when people say fast compile times they most likely comparing to Go etc which would be under a minute for most mid size projects. And this is very well not going to happen.
Same is now to Cargo dependency situation. Cargo and NPM are ideologically in agreement that people in general should just pull it from package manager instead of rewriting even little bit of code. And again instead of owning it there will be list of shallow reasoning: others do it too, reusing is better that rewriting, cargo is so awesome that pulling crate is much easier and so on.
TBH you seem to have a really odd bias against Rust, you repeatedly take something about it that's positive and try to spin it as negative, like possibly even for years? Maybe examine that.
Plus some of the dependencies are also dependencies of the standard library (hashbrown, cfg-if, libc).
- Secure. Does this contain malicious code, exploits or otherwise known bugs that could be fixed but aren't? This of course is hard, and will never be perfect. There are static security scans though, espcially in a language like rust, that should be able to verify what the code does before its being published for consumption via carog. NPM is trying to do something similiar. This isn't foolproof and more sophisicated exploits always will exist, but getting low hanging and mid-level fruit should be within reach, which is a net win
- Is it quality? This is beyond just secure, but does it provide real utility value? One thing we always hear is DRY, which may mean sometimes you consume alot of dependencies, since the problem space you work in involves a lot of things, so why re-invent every single fix if something exists and you can glue together to start making impact in your problem domain? I don't think this is an issue espcially if #1 is true
So I don't know, I think its fine to have a lot of dependencies, I think the justification for those dependencies is often related to the complexity of the work involved. I'd expect a cURL replacement to have quite a few dependencies, since its complicated software with lots of edge cases, so for instance not re-inventing a HTTP parser is a great idea.
Now if only we all shared as developers this sentiment in terms of upstreaming contributions back too. The more we contribute and share with each other the more productive we can be.
Of course, sometimes package managers do terrible jobs at ensuring some sort of base quality, around security or otherwise, and thats never great. So its important to be aware of the trade offs you make when you source your dependencies.
By no means does this excuse developers from not understanding their dependency tree either. Its really the opposite.
Either you depend on other's work for that, or you roll your own. Choose your poison.
* tracing is only present for logging purposes. does curl need it? It should be configurable.
* itoa is only present for performance purposes, and only seems used by the server.
* It seems that a bunch of projects in the dependency tree use pin-project which is heavyweight and instead could use pin-project-lite. Some already do, which creates both being used, so you are worse off than just with pin-project alone...
* hyper contains code for both http servers and clients. Even if the dependencies are the same (and as seen above they are not), having to compile the server code for the client means an increase in compile time. It would be cleaner to provide separate server and client flags to make it possible to turn one off.
Technically it’s still a dependency but the standard library is maintained with a standard that is rarely matched by third party libraries, and can dramatically simplify the ecosystems’ dependency graph.
E.g. the async ecosystem offers you to pick between runtimes of different complexity and tradeoffs. Std only picked up the essential traits that allow other crates to interoperate with each other and the language itself to define async functions.
I mean, you can go both ways with this. Standard libraries are significantly more difficult to work on than third party libraries, and I've seen a lot of code in standard libraries that is objectively worse than ecosystem equivalents because of it.
From looking at the list of crates above, I see a lot that are often part of the stdlib of other languages, such as HTTP, concurrency/nio primitives, and logging.
My perception of Rust's not including such fundamental primitives in the standard library is that Rust is still very much experimental, and the ecosystem values tinkering and experimenting with new ideas. The cost of that is increased dependency hell, especially over time. There's obviously huge value in experimentation for the industry, but it makes me hesitate to use Rust for projects where I just need to get stuff done, and stay done.
You may have that perception, and that is fine, but it's not likely to be a thing that changes significantly, even when Rust is quite old. There's just not a lot of advantage to being in the standard library, and numerous downsides.
> There's just not a lot of advantage to being in the standard library, and numerous downsides.
Look at those huge lists of dependencies and the complaints of Cargo dependency hell. That's the downside. Every node in your dependency graph has overhead for everyone involved, and it's even worse when it's something as fundamental as HTTP.
I write a lot of Rust that never touches HTTP.
I'm less experienced with rust, but with nude, there's many times I'll use a specific dependency over another because it's already in the dependency tree.
Aside, it's rough actually trying to keep node dependencies in check in a project. Especially in web UI projects using npm.
Now, I am somewhat supposed that say tokio or similar hasn't made it in the box yet, it allows for much greater experimentation.
Aside, I wouldn't be surprised to see MS generate a massive sure if libraries if they shift more internals development to rust. Not sure if it'll be good/bad or otherwise.
[0] https://internals.rust-lang.org/t/scaling-back-my-involvemen...
1. CURL without https seems insufficient nowadays. 2. CURL could be improved by running multiple downloads at once. I'm not sure that curl command line utility could do it, but certainly libcurl.so has this ability, it allows client code to work with multiple connections. 3. Any application having UI could benefit from async: input/output and main task are async by nature. For example, curl might want to show progress/status to a terminal despite of a stalled connection.
So maybe Hyper is too much of a code for a curl, but it is arguable that it is not.
2. I'm not sure that CURL should necessarily support multiple concurrent downloads. It could also be argued it's more UNIX-y to make it just do one thing and allow the caller to run multiple CURL processes at the same time
3. You wouldn't necessarily need async to achieve these goals. You could easily have a synchronous http implementation which allows for printing to the console between receiving chunks of data from the network. And if you really didn't want blocking to have a "spinning" activity indicator or something, you could still achieve it with threads.
I think ultimately you'd have to decide based on the relative cost of including an entire runtime vs. just launching a second thread.
One could do a spinning indicator, but not a label STALLED. To get this one need to restart read(2) every while, and there we come to implementation with complexity on par with async. Things become even more interesting if a program wants to process user input in async. UNIX-way is to send signals, but it is just plain ugly. dd from coreutils allows to use signals to trigger it to print progress, it is very inconvenient way to do it.
> I think ultimately you'd have to decide based on the relative cost of including an entire runtime vs. just launching a second thread.
I'm not so sure. Runtime for user-space context-switching is very small. I did it for educational purposes at some time in the past with C. It is operation like save registers, switch stacks, restore registers and jump to another thread. If you have more than two threads, then you'd need some kind of structure to store all contexts and to decide which one to choose next. Add some I/O code (like epoll) to track state of file descriptors, and you are done. One could do it without async, but it wouldn't become much smaller, because it would be the same logic, just instead of stack switching program would recreate stack frames.
The latter is a better question because:
* It's directly connected to your security posture. * It's a stable metric across languages with different norms about module size.
bytes, futures-core, futures-channel, futures-util, http, http-body, httpdate, httparse, h2, itoa, tracingfeatures, pin-project, tower-service, tokio, want
https://gist.github.com/seg-lol/0d22cf5002f890305cfd094f9ed1...
*edit, passed in -e no-dev to `cargo tree`, thanks @est31 for the suggestion
autocfg, bitflags, bytes, cfg-if, fnv, fuchsia-zircon, fuchsia-zircon-sys, futures-channel, futures-core, futures-sink, futures-task, futures-util, h2, hashbrown, http, http-body, httparse, httpdate, indexmap, iovec, itoa, kernel32-sys, lazy_static, libc, log, memchr, mio, miow, net2, pin-project, pin-project-internal, pin-project-lite, pin-utils, proc-macro2, quote, redox_syscall, slab, socket2, syn, tokio, tokio-util, tower-service, tracing, tracing-core, try-lock, unicode-xid, want, winapi, winapi-build, winapi-i686-pc-windows-gnu, winapi-x86_64-pc-windows-gnu, ws2_32-sys