The big difference is it looks deliberate, instead of just code written by someone trying to micro-optimize, be very clever, or who just didn't realize tolower() exists. Most people will pause before just replacing it, and likewise it should trigger questions in the PR.
And if that test also happens to validate that the documentation is accurate, that is a nice side benefit.
You might be being serious, so I'll indulge. How would a test that will never break, for a function that would never be changed (because look at it), that lives in a different part of the directory structure, be worth even one second extra time or thought to write it, over-and-above the descriptive comment that is longer than the code itself, and lives discoverably right next to the code itself?
The cost of writing a single test case is not more than the cost of diagnosing what change broke your code for Turkish users.
Now there's always a point where maybe the infrastructure for testing that kind of thing doesn't exist, so writing your one "simple" test case takes a bunch of time, but on the plus side, future similar "simple" test cases will be easy at that point. And no one has to track down why your code is broken in turkey.
Many years ago while I worked on IM/IMEs on Mac and windows I spent maybe a week working on code that allowed an IME to be implemented in JS (within the webkit test harness), so it was possible to test, and prevent regressions that kept on being reintroduced by people changing layout and/or editing code in ways that are "obviously correct" for US/English keyboards. The win from that week is many regressions that were caught before they were even committed, and the ability to completely rewrite the text input system to support IMEs on non-mac platforms.
At that point, just leave the test and check it in.
Often, though, you can verify that your code works using a REPL.
I'm also a huge fan of how doc-tests in some languages that make the tests are part of the documentation, and neatly 'cohere' them to the function itself. At which point I'm happy to leave them in, as the tests-as-documentation are harder to miss, and are actually instructive.
Machine-time to run tests is cheap (if it's not in your codebase, then I agree that your benefit calculus may be different) - human cognition and awareness to prevent mistakes is valuable.
> a test that will never break, for a function that would never be changed
I'll refer you to the OPs low-tech to-lower function, which is reductively simple, and never should be altered, with a comment as to why.
> Comments can be ignored, moved, misinterpreted.
Don't disagree with this. Someone lacking competence and care may ignore a comment, is incapable of comprehension, or just moves things for no reason. This should be caught at review.
Tests aren't infallible either. They can be invalidated, disabled because someone lacking competence decided it was the easiest way to move forward. This should be caught at review.
Edit: I'll address some of your other points more specifically...
> The only way to make the build fail if someone has (incorrectly) replaced the "complex toLower" with the (incorrect) "built-in toLower" is to delete or change the corresponding test
In OP's precise example, a worse thing can happen. They can shrug their shoulders and just use the built-in directly. Human-context business-value explication has more powerful benefit here.
> which rings way more alarm bells than a vague recollection of "hey, didn't there used to be a comment around here that said we shouldn't change this?"
If no-one's reviewing when someone changes the actual code and it's adjacent comments, who's reviewing the changes to the tests?
> human cognition and awareness to prevent mistakes is valuable.
Extra code comes at a maintenance and cognition cost. Maybe one trivial test seems like a minor cost, but how about the maintenance of 1000s of tests that (ought to) always pass?
Locale name is iv-IV.
Maybe I should have my own tolower() function that I can call so I only have to write the comment once but it just feels ridiculous somehow.
You know you wrote it 49 times before, but the person reading the code probably doesn't. It only changes your experience not everyone else's.
If it's the same codebase, just write that function :)
Many of these are obvious to many people here, but some aren't.
Even I can admit that some of the stuff in this thread is not obvious at all.
I mean, it's clearly the right thing to do here but I can predict the conversation that will inevitably result... "You wrote your own tolower() function? Why?" "The standard one is horribly broken." "How could a function that lower-cases a letter be broken??? Jesus Kenton your NIH syndrome is out of control." "Sigh..."
(Slightly more seriously, any particular time I need to lower-case something, it takes 10 seconds to write out the code, but would take 10 minutes to find a good place to define a reusable function and exactly what its API should be, and so it never seems worth the effort in the moment. Just like how most messy code comes to be.)
I have noticed some coworkers have their ego gratified by being right while everyone else is wrong. Instead of simply explaining what they are doing when they are doing it, they will do something that looks wrong in a very noticeable way and wait for the backlash. The backlash gives them an opportunity to show everyone else how they were right while everyone else was wrong and also an opportunity to play victim. However, in SW development - it is not just the technical details - your behavior also matters in a big way.
In this particular case, the correct approach is to create your own library function with appropriate comments. This is why the concept of a library function was invented. It is its entire raison-d'etre. However, you are doing everything but that. Including providing justifications in hacker news comments instead of your source code.
Now inevitably, someone will change your inline code to use to_lower. This will give you an opportunity to scream bloody murder, show how other engineers don't really understand technical details, correct them and also play victim. Create a library utility with comments and link it in - End of story.
But seriously, I'm not here to lecture you, but personally I'd appreciate having a teammate educate me on the undesired behavior and have a nice function I could use to ensure my own code doesn't break user input
But I too feel the cognitive (and social!) burden of introducing a new function. It's not just "where do I put this", but "how do I convince the team I know what I'm doing since 15 years of experience clearly isn't enough and developers (mostly rightly) ignore positional authority and seniority".
#include <kentonv.h>https://github.com/capnproto/capnproto/tree/master/c++/src/k...
Is there something similar for C and C++? It could help in your case, by making your well-meaning colleagues aware of the issue.
At least Android developers are advised to use Locale.US: https://developer.android.com/reference/java/util/Locale
> The default locale is not appropriate for machine-readable output. The best choice there is usually Locale.US – this locale is guaranteed to be available on all devices, and the fact that it has no surprising special cases and is frequently used
It would be indeed interesting to see in which features these two locales actually differ.
On many documents, including Turkish passport and identity card and many (all?) other passports, names are written in all caps. Maybe toLower() is not that useful, but toUpper() is crucial in any application where you are dealing with real person names.
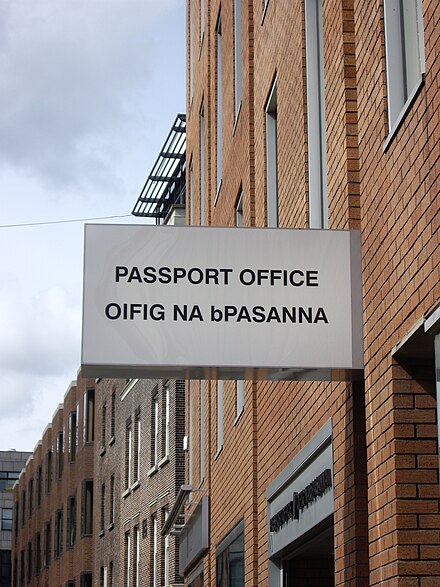
Plus, there's the issue of diacritical marks. Irish keeps long marks over capitals, but French drops accents. Do you plan to do é => É (required for Irish - POBLACHT NA hÉIREANN is the all-caps version of Poblacht na hÉireann [the Republic of Ireland]) or é => E (common practice for French)? You have to get it right, and you have to know the language to do that. (Poblacht na hÉireann also illustrates the fact that initial caps is also a language-dependent idea; you absolutely can't write Poblacht Na Héireann - that makes my eyes burn just looking at it.)
(And before you say, well, Irish isn't a language spoken by very many people, remember that it's an official language of the European Union. If you're writing software to be used by EU agencies, you're going to have to care.)
Official position of both Académie française and Office québécois de la langue française is that accents must be preserved in capital letters. However, it is common in France to drop them, while they are almost always preserved in Québéc. I have heard that the reason is that European French keyboard layout makes it difficult to type accented capital letters, unlike Québécois French layout which makes writing them easy. But I am not sure if this is the cause rather than the effect of the practice.
I have an anecdote on this: on birth certificates, family names are written in capital letters. It turns out my partner name ends with a É which was written as E in her birth certificate. She never noticed (it had never prevented her to get national ID with her name properly accented) until we had our first kid which has both our names, and they refused to have the name accented until we had my partner's birth certificate updated (which as you can imagine is quite an adventure, since you need to dig ancient family birth certificates to prove it was originally written with an accent...).
What's weird is I sometimes, even 10 years ago, would get an email from people in France, and it would have an accented A. Like, how did they do that..
korean is worse. they base off of 10k, not 1000. so a million is hundred ten_thousand. bagman. but as bad as that is, it's no 97 amirite.
http://j.poitou.free.fr/pro/img/tkn/tw-image.jpg

This idiocy carried over. The recent layout update makes dead accents more accessible:
But I haven't seen much adoption yet.
Even more if you consider that the minus sign there is not the character - that is used by every programming language.
And there are two more on the 8 key.
I like the mac international keyboard layout, but it still only provides for 4 of those: the non-breaking hyphen and the "proper" minus sign are lacking.
I like that the "new azerty" provides for pretty much every diacritic, even those which are not in use in french.
toLower and toUpper should only be used for presentation, but all case-insensitive operations need to be done with casefold.
There are similarly tons of cases where you reduce everything to lowercase without accents for searching and indexing purposes. Depending on your setup, your database might handle that for you, but there are edge cases where you need to do it at the application level.
Long story short, every string has a locale, and you should never change the case of something without specifying its locale. Either be explicit that it's American English or ASCII or Latin1 or whatever... or that it's something else. Never leave someone reading the code guessing.
I am skeptical if someone thinks they need to do this and how they will get it done.
Eg. Looping through and capitalizing the first gylph after breaking whitespace regardless of locale is not the way to go, but I guarantee you a nontrivial amount of people reading this would write exactly that if asked to solve the high level problem.
I find it annoying when software or even in some cases human typists try to enforce English language title case. Some other languages have different rules for titles and capitalization and seeing the English rules enforced out of context can be jarring.
I use the citation manager Zotero a lot. It's necessary to store all the titles of journal articles and books in sentence case (e.g. "Issues regarding the economy of France") because some publications require citations to use sentence style (remains unchanged) while others require title style ("Issues Regarding the Economy of France").
And obviously the solution cannot be naive, but is language-dependent, so that in English words like "the" or "in" don't get capitalized. And as the rules for titles are obviously language-dependent, so it goes without saying that the algorithm would have to be localized.
(Note that while it's relatively trivial to convert from sentence case to title case in English, it's impossible to automate in the opposite direction, because you never know if a capitalized term in the title is a proper noun or not.)
Strictly speaking you can't do that either:
  "Latine et videtur".totitle = "Latine et Videtur"
  "I et some food".totitle = "I Et Some Food"
It's not an uncommon requirement, though probably not often in a locale sensitive way, so you can often get away with just doing the right thing for one locale.
To do it generally, you probably need to research appropriate handling per locale (likely, what your client wants done in the particular locale, since I'm not sure there is usually just one way; I know there are multiple variations in en-US), and then have a master function that takes the text and target locale and applies the correct locale-specific title casing rules.
I most often use title case mappings in the context of replacements of names into diagnostic messages. I.e. you have n types of objects and m messages like “${foo} not found” or “More than one ${foo} required”, and perform title case mapping on ${foo} depending on whether it is at the start of the message (sentence) or not.
So yes, it's extremely common. It's done on tons of websites, for tons of mail addresses (ever receive an all-uppercase address on a delivery? same issue.), and tons and tons and tons of emails and legal documents (woe to those with last names like McCormick).
If you are collecting data which include people's names or addresses you probably want localization to be applied correctly so that you can compare data coming from different sources and possibly with different cases. Having your name spelled differently in different documents can cause a non trivial amount of problems with an overzealous bureaucracy.
How do you lowercase without localization? Remember all text isn't English. Unless you're actually asking if anyone has ever had a use case for lower-casing non-English text?
It's horrifically wrong, of course, but no one is going to think you're a reasonable person for insisting that correct wins over nice.
Imagine a real-world scenario where you're displaying a list of names of users, where the users got to type in their own names. You can either use what users typed in, or you can do something like process it so it's in the American idea of initial caps. You can't possibly do localization, since it's a list of names of people in the US, so it's melting pot of names from all over the world, and you never asked for user input of what you'd use to localize it anyway [and no, you absolutely can't figure that out from just the name itself]. You can't use what users typed in, because the design team thinks that looks like a horrible mess (and it is; users are laughably bad at data entry). So the design team wins, and you butcher everything by pretending that toLower() plus toUpper() for the first character of every word is a sensible thing to do. (And yes, that's a painful real-world example of software I've shipped and that was used by millions of people.)
Maybe for automatically changing the case of user input (auto-correcting capitalization, etc.).
Yes. In a system I'm about done with, there is a sortable chart of dates and times. In some languages day and month names are capitalized, and in some they are not.
Also got my address screwed up on account of living at a half address.. 1/2 some street #42
It's only tolower() and toupper() specifically that are broken because they expect to be able to do their job on a single byte, which is no longer possible with UTF-8.
Meanwhile, using tolower() to lower-case an HTTP header name won't give you the correct results if the locale is set to Turkish with the ISO 8859-9 character set, which is 8-bit, and where tolower('I') will produce the byte 0xFD which is 'ı' in this character set.
But if you consider the other writing systems, having case conversion feature in locale library actually harm the localization effort. It's not easy to make it no-op. The implementation of locale library are generally poor quality because the implementer has no idea how other languages works.
Another example is singular/plural support. It just burden the localization effort because for languages which no such concept, the localization work must ensure that presence of such library doesn't harm their language.
Some people is under the delusion that locale library must have more features to support his native languages not so important traits. While what really necessary is just forget about supporting minor language traits that are not universal among the languages.
The text should be considered binary blob and most program should pass it left to right without modification.
https://en.m.wikipedia.org/wiki/Email_address#Internationali...
https://doc.rust-lang.org/std/string/struct.String.html#meth...
[1] https://www.icao.int/publications/pages/publication.aspx?doc...
Human text is much much more complex than any computing protocol you're ever going to engage with.
The question is "which one should be default", and that's a more complicated question.
Well, it's always been exclusively in American English, but I've certainly used it in cases where I was doing text transforms for display, so, yeah, though it's not the most common case.
It seems to me that in practice, it's extremely rare to want to change case of real, natural-language text. When I have natural-language text, it's just a blob to me, and I don't want to touch it.
The only time I ever want to lower-case or capitalize something, I'm working with identifiers meant for computer -- not human -- consumption. Usually, specifically, I'm dealing with identifiers that have annoyingly been defined to be case-insensitive even though the only humans that ever see them are programmers and programmers hate case-insensitivity. HTTP headers are a common example.
I mostly write C++, and I end up writing code like:
Later on, some well-meaning developer on my team will come along and say "Ugh what is this NIH syndrome?" and then they "clean it up" as: And then I have to say NOOOOOOO DON'T DO THAT YOU HAVE NO IDEA WHAT tolower() REALLY DOES!I struggle to imagine any real use case where you'd actually want locale-dependent tolower() other than, maybe, a word processor -- but if you're writing a word processor, you're probably not going to be depending on the language's built-in string APIs to do your text manipulation.