News for hackers. Stuff that matters.
Re:Linux founder tells Intel to stop inventing magic instruc... by gameswithgo on Monday July 13, 2020 @01:29PM (#23823259)
On the one hand AVX-512 is incredible, the performance gains from AVX-2 to AVX-512 are often more than the 2x you would hope for. On the other hand, when you can use AVX-512 you can often use a GPU instead, to greater benefit. So linus may be right, overall.
Re:Linux founder tells Intel to stop inventing magic instruc... by rumanator on Monday July 13, 2020 @01:50PM (#23823487)
> On the one hand AVX-512 is incredible, the performance gains from AVX-2 to AVX-512 are often more than the 2x you would hope for.

Your assertion sounds like a gross exaggeration. Some benchmarks show only a few percent improvements (i.e.14% improvements on synthetic benchmarks), and results range between no improvements and almost 2x in some synthetic benchmarks.

https://www.phoronix.com/scan.php?page=article&item=gcc9-sky...

Re:Linux founder tells Intel to stop inventing magic instruc... by gameswithgo on Monday July 13, 2020 @03:07PM (#23824369)
Those look like benchmarks comparing just autovectorized compilation of some tools and measuring overall runtime. I am referring to cases of hand tuned use SIMD. The bSIMD project used to have a suite of benchmarks up and some where very very impressive for AVX-512. The page appears to be gone or moved now though.

To be clear I am not suggest "avx-512 will cause programs to run twice as fast or more", just that specific functions that used to use AVX-2, may be more than twice as fast if you move them to AVX-512.

Re:Linux founder tells Intel to stop inventing magic instruc... by rumanator on Monday July 13, 2020 @04:55PM (#23825468)
> Those look like benchmarks comparing just autovectorized compilation of some tools and measuring overall runtime. I am referring to cases of hand tuned use SIMD.

I presented data that showed that AVX-512 in reality only brings margins performance improvements.

If you have any data that shows otherwise then feel free to present it.

Still, hand-tuned assembly is hardly a relevant example, let alone selling point, as it creates hypothetical expectations that are never ever matched in reality.

Re:Linux founder tells Intel to stop inventing magic instruc... by vardump on Monday July 13, 2020 @05:51PM (#23825978)
"Still, hand-tuned assembly is hardly a relevant example, let alone selling point, as it creates hypothetical expectations that are never ever matched in reality."

There's a ton of hand tuned assembly running on your system in numerous libraries. Media and data compression? Hand tuned assembly. Matrix math? You guessed it. C-standard library functions? Yes, really.

Re:Linux founder tells Intel to stop inventing magic instruc... by greyhair on Tuesday July 14, 2020 @12:02PM (#23833519)
Maybe for media, crypto, things like that, but we all have the source for the C-standard libaries, and there is not all that much assembly in there given the size of the code base.

Certainly you have required architecture instructions for things like instruction scheduling (isync/dsync), stack manipulation (setjump/longjump and others) or floating point, but though it looks like a lot of assembly source, it is really just a little bit for each of the many supported architectures in the tree. And most of it isn't performance related, it is just plain required because architectures vary on things like instruction scheduling and stack/cache manipulation.

Re:Linux founder tells Intel to stop inventing magic instruc... by vardump on Monday July 13, 2020 @03:51PM (#23824884)
Some SIMD optimization cases can occasionally exceed scalar versions by more than lane width multiply. Often because of branch elision, but also less dependency chains stalls due to the larger register file. There are also some special instructions that can be very useful in SIMD case (packing, unpacking, permutation, etc.).
Re:Linux founder tells Intel to stop inventing magic instruc... by CoolGuySteve on Monday July 13, 2020 @03:08PM (#23824384)
I agree about GPUs. Intel used to have a low-end CPU with a 128MB L4 cache that was shared with the iGPU. It turns out having that large cache improved a lot of regular software too. I'd rather see die space used for that than AVX512.

The only AVX512 instructions that actually seem essential imo are the VNNI extensions.

There are a lot of use cases for a neural network that is trained on the GPU but where inference is done on a bunch of CPUs because it's cheaper than buying/renting inference hardware.

Re:Linux founder tells Intel to stop inventing magic instruc... by cogman10 on Monday July 13, 2020 @03:32PM (#23824664)
I think you are thinking AVX takes up more diespace than it does. Only a tiny fraction of all CPU diespace is dedicated to the actual CPU. The rest goes primarily to cache and partially to the various controllers on the CPU (memory controller, PCI-Express controller, etc).

There's a reason AMD is and Intel are able to cram full GPUs onto the same die as the CPU.

Re:Linux founder tells Intel to stop inventing magic instruc... by Dylan16807 on Monday July 13, 2020 @03:59PM (#23824949)
https://imgur.com/r/intel/4SG36

Yeah, here's a good image of how much space it costs to add a 'second' AVX-512 unit to certain SKUs. Cutting AVX-512 support entirely would save a bit more space, and the total would be enough to make a difference, but it's not an extreme amount.

https://software.intel.com/sites/default/files/managed/5f/99... https://twitter.com/GPUsAreMagic/status/1256866465577394181 these too (speculative)

Re:Linux founder tells Intel to stop inventing magic instruc... by jagger27 on Monday July 13, 2020 @04:43PM (#23825364)
And the GPUs are usually the bigger component.
Re:Linux founder tells Intel to stop inventing magic instruc... by corysama on Monday July 13, 2020 @01:44PM (#23823417)
In my observations, GPUs are the way they are largely because Physics demands sacrifices if you want that kind of performance. Those same demands apply to CPUs, but Intel has been fighting against them because software engineers hate to change anything about how they code. Well... the fight was lost years ago and Intel is conceding to Physics by integrating architecture that was originally designed for a CPU-GPU hybrid.

With AVX-512 and CUDA, Intel and Nvidia are trying to find the best developer experience they can to deal with the inevitable future of computing that is somewhere between those two experiences currently.

Re:Linux founder tells Intel to stop inventing magic instruc... by Const-me on Monday July 13, 2020 @04:18PM (#23825152)
> inevitable future of computing that is somewhere between those two experiences currently.

Not sure that ever happens. The two are very different in their performance characteristics. CPUs have to stay focused on single-threaded performance.

Single threaded performance = minimizing latency, that’s why in CPUs so many transistors and electricity is spent on cache hierarchy and coherency protocol, instructions reordering, ILP, microops fusion, prefetcher, branch prediction incl. indirect one, and so on.

GPUs don’t care about single-threaded performance, all they care is throughput on massively parallel tasks. They ignore memory latency, switching threads until data arrives, makes caches much simpler. They don’t need high clock frequencies (this alone improves their flops/watt by a large factor), don’t do branch prediction, memory model is less strict, and so on. That’s how they can spend that many transistors on FPUs and ALUs.

P.S. Intel tried many-slow-cores with Larrabee / knights landing / etc., all they got was a very expensive lesson, people didn’t want that stuff. I’ve heard a rumor initially Sony wanted to use another Cell CPU for the GPU in PS3, again, didn’t worked well enough and they negotiated with NVidia instead.

Re:Linux founder tells Intel to stop inventing magic instruc... by corysama on Monday July 13, 2020 @05:24PM (#23825733)
All true. Problem is that single-threaded latency minimization has been tapped out for a long time now. Physics says No. Memory is high-latency because of the speed of light. Larger caches have diminishing returns. Clocks can't go faster without melting the chips. There is no more prediction and pipelining to be dug out of a serial stream of instructions.

We can still add more transistors. But, there is nowhere for them to contribute but in going wider. High latency, high throughput. High concurrency and careful management of the memory hierarchy are the only ways to pull that off. When you accept that fate, you start out with the Cell processor and you pass through Nvidia's Ampere chip --which has somewhat more thread independence and better automatic caching than past GPUs, but also finally gained manual async DMAs to local SRAM like the Cell had. Where we'll end up, I don't know.

Re:Linux founder tells Intel to stop inventing magic instruc... by paulmd on Monday July 13, 2020 @07:08PM (#23826681)
> All true. Problem is that single-threaded latency minimization has been tapped out for a long time now. Physics says No. Memory is high-latency because of the speed of light. Larger caches have diminishing returns. Clocks can't go faster without melting the chips. There is no more prediction and pipelining to be dug out of a serial stream of instructions.

Someone should probably tell AMD and Intel they need to stop, then, because Ice Lake was +18% IPC, Tiger Lake will likely be another 5-10%, and Zen3 will be around 15% higher IPC.

What has truly stalled IPC is 10nm. Intel has had higher-IPC architectures for a long time, they simply couldn't manufacture them. And AMD was coming so far from behind that it took them 3 generations of Zen to even catch up to Intel.

The last few years have been a rather unfortunate "CPU dark age" but things are finally breaking loose once again. Ice Lake launched 9 months ago, Intel backported Tiger Lake to 14nm and that will launch probably around Christmas or CES, Milan is launching probably within the next 6-8 weeks, and Tiger Lake is launching this month.

Re:Linux founder tells Intel to stop inventing magic instruc... by Const-me on Monday July 13, 2020 @06:44PM (#23826456)
When I look at general-purpose single-threaded benchmarks, I see a good progress. I’m pretty sure we’ll see very good progress on that, because Intel/AMD competition, also because inexpensive SSDs removed the storage bottleneck.

I agree on physical limitations, but the research still goes on, smart people still able to use these extra transistors in a way that’s useful for performance. Even for single-threaded one.

Another thing, software is progressively better at using many cores. It’s much easier to move large pieces of code to another CPU thread (like some browsers do with JS compiler) keeping it sequential code, than it is to re-write code as a large set of small tasks / threads. Many useful algorithms can’t use fine-grained parallelism much, or at all, e.g. streaming stuff like gzip or parsers.

Re:Linux founder tells Intel to stop inventing magic instruc... by corysama on Monday July 13, 2020 @07:10PM (#23826701)
I really miss the 286->Pentium days when you had to buy a new machine every year because it would be literally 50-100% faster at everything. Every year! These days people call a 9% single-thread improvement a good year. https://www.cpubenchmark.net/year-on-year.html

https://www.karlrupp.net/wp-content/uploads/2018/02/42-years...
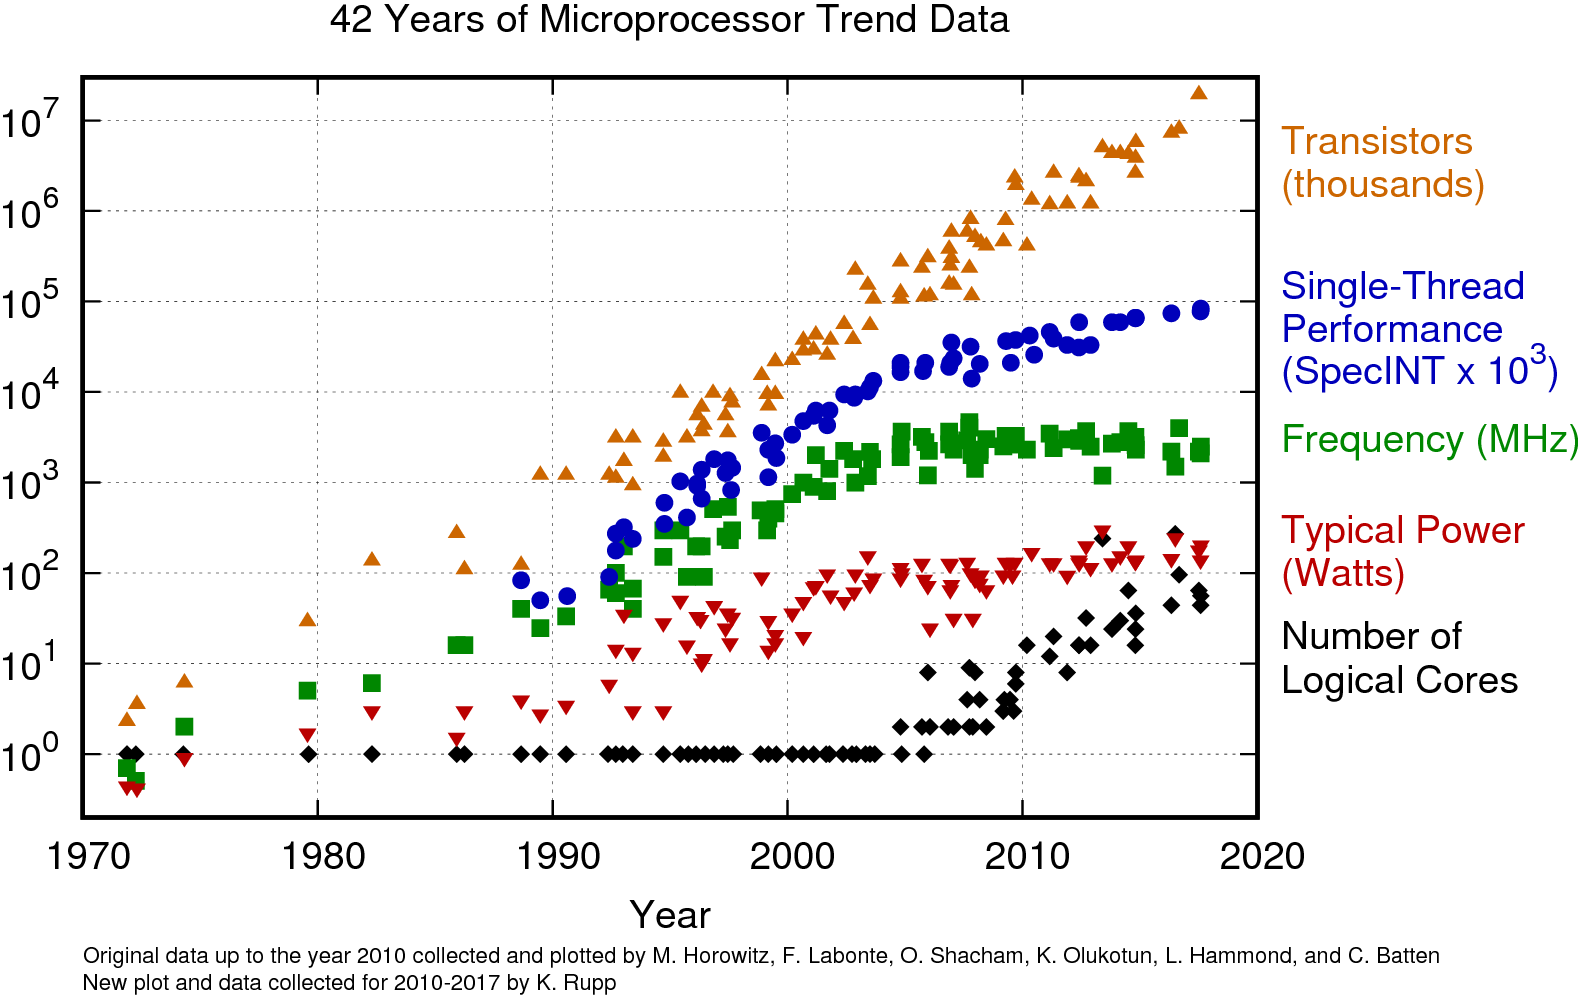
BTW: Thanks for http://const.me/articles/simd/simd.pdf I came across it recently and posted it to https://www.reddit.com/r/simd/

Re:Linux founder tells Intel to stop inventing magic instruc... by PaulHoule on Monday July 13, 2020 @05:13PM (#23825653)
CUDA is night-and-day different from Intel's nightmare.

CUDA in particular hides the exact width of the processing elements from the programmer, so you don't have to rewrite your CUDA applications to take advantage of the next generation of GPU the way you have to do with AVX1,2,3,...

Mind you, NVIDIA's drivers compile your shaders to their proprietary instruction set, which is a path not taken in conventional CPU architecture even though it keeps coming up. (e.g. the belt)

Re:Linux founder tells Intel to stop inventing magic instruc... by dragandj on Monday July 13, 2020 @08:01PM (#23827095)
FWIW, Intel supports OpenCL for their CPUs, so you can use similar general parallel programming code which is compiled down to AVX-512 (fairly) transparently.
Re:Linux founder tells Intel to stop inventing magic instruc... by mvanveen on Monday July 13, 2020 @02:25PM (#23823906)
In many cases within regulated environments getting access to GPU in e.g. a customer's on-prem solution is prohibitive.

In enterprise ML contexts on tabular data problems we found there are a lot of cases where even training can be greatly sped up by leveraging AVX instruction support in e.g. tensorflow builds. The gains from AVX instructions could boost training time by ~20% on the GAN use cases I profiled.

Re:Linux founder tells Intel to stop inventing magic instruc... by btilly on Monday July 13, 2020 @02:53PM (#23824232)
So you're saying that we need to solve organizational stupidity by complicating all chips for everyone so that bad organizations can get a performance boost on specialized tasks?

What percentage of consumers with these chips installed do you think are getting a performance win? Do you think it might be as high as 1%?

Do you think that the same resources devoted elsewhere might be worth more than 1% to that 99%? Whether that is in reduced cost, reduced bugs, or a boost for more widely used operations.

Yes, if you target a specific use case for a specific set of people, you can give them a nice win. But you shouldn't lose sight of the fact that CPUs cover a lot of use cases for a lot of people. And simplifying then focusing on the core mission is better for everyone in the end.

Re:Linux founder tells Intel to stop inventing magic instruc... by anoncareer0212 on Monday July 13, 2020 @03:10PM (#23824405)
Linus somewhat waved away the idea of tradeoffs, which is fine, he was speaking in generalities.

Turning factual reports of where the tradeoff was helpful into a strawman insulting the reporter, and the users who benefit, is neither charitable nor illuminating.

Re:Linux founder tells Intel to stop inventing magic instruc... by smabie on Monday July 13, 2020 @01:43PM (#23823410)
Are you sure l? Gains between 10% and 50% are pretty common, but I've never heard of a 100% or greater improvement.
Re:Linux founder tells Intel to stop inventing magic instruc... by otherjason on Monday July 13, 2020 @02:19PM (#23823841)
Yes, these applications do exist. The speedups mainly come from the more flexible instruction set that AVX-512 provides (so in many cases you can replace several instructions with just one), plus the increased register set (32 architectural SIMD registers versus 16 on previous generations).

If your algorithm isn't sensitive to either one of these, then yes, the speedups are often smaller, particularly if the limiting factor in performance is memory bandwidth and/or latency (AVX-512 doesn't help at all there), or if the speedups aren't enough to overcome clock throttling (which IMO is a bit overblown; most people cite the Cloudflare blog article from a few years ago that complained about throttling on Xeon Silver processors, but throttling is much less of an issue on higher-TDP Gold/Platinum CPUs). However, I have seen specific applications that are >100% faster with AVX-512.

Re:Linux founder tells Intel to stop inventing magic instruc... by TinkersW on Monday July 13, 2020 @03:44PM (#23824804)
If you write SoA code, know what are you doing, and aren't memory bound, 100% speedup isn't unreasonable.

Current AVX512 implementations might not always get there, as I believe some instructions are dual issuing at 256bit under the hood.

Re:Linux founder tells Intel to stop inventing magic instruc... by solinent on Monday July 13, 2020 @03:15PM (#23824460)
Yes, in my opinion, the CPU model is dying as we fail to miniaturize we will be forced towards data parallel algorithms which benefit from speedups through SIMD.

Ultimately AVX will be the future of Intel if they want to compute with GPUs and if everyone stays silicon.

Re:Linux founder tells Intel to stop inventing magic instruc... by cogman10 on Monday July 13, 2020 @03:36PM (#23824718)
My view is that data parallel is here to stay and what's likely to happen is we'll see more power pumped into the instructions. Things like "If lane A > lane B add C to lane D"

Eventually, I see us going basically full EPIC. That is "here's a batch of instructions that can happen in parallel, run it".