News for hackers. Stuff that matters.
Re:NewSQL overview by ddorian43 on Friday February 13, 2015 @08:05AM (#9044079)
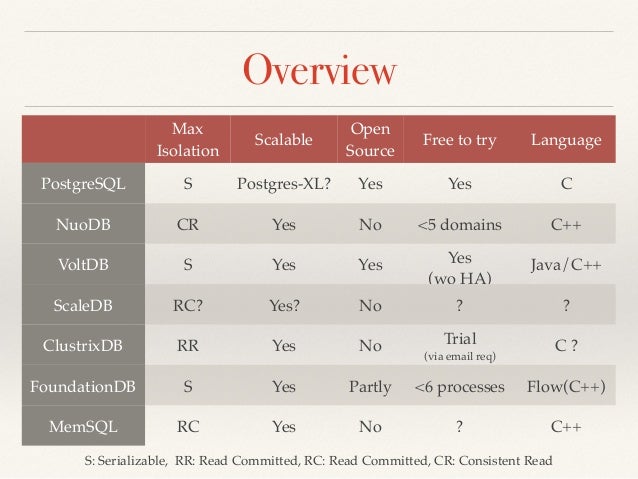
Is there any open-source/free newsql db ?
Re:NewSQL overview by alexandre_m on Friday February 13, 2015 @09:56AM (#9044595)
CockroachDB is promising.

https://github.com/cockroachdb/cockroach

Inspired by Google Spanner.

Re:NewSQL overview by mathnode on Friday February 13, 2015 @08:17AM (#9044126)
Slide 27. VoltDB.

Or use posgres-xc, or mariadb 10 with galera and maxscale. Postgres has JSON storage. MariaDBB has dynamic and virtual columns, and the CONNECT engine which can now directly create new or edit existing JSON files using the SQL interface, instead of dedicated functions for JSON manipulation.

https://mariadb.com/kb/en/mariadb/connect-json-table-type/

Re:NewSQL overview by ddorian43 on Friday February 13, 2015 @08:25AM (#9044151)
voltdb free has no HA

postgres-xc/xl has no HA

Maxscale looks like it doesn't yet offer sharding
Re:NewSQL overview by jeremysmyth on Friday February 13, 2015 @10:30AM (#9044791)
Re:NewSQL overview by jrullmann on Friday February 13, 2015 @10:12AM (#9044686)
Take a look at the Overview slide of the presentation, where this information is listed for each database the author discussed: http://image.slidesharecdn.com/newsql-2015-150213024325-conv...
Re:NewSQL overview by anonetal on Friday February 13, 2015 @10:28AM (#9044784)
With the recent SQL-like query language, I think Cassandra comes pretty close to satisfying the requirements as well, as long as you don't require multi-key transactions.
Re:NewSQL overview by codeordie on Friday February 13, 2015 @02:04PM (#9046409)
It's not bad, and Apache Spark adds SQL on top of some other nosql DBs, but they are still hard to use.

Cassandra for example: you can't just put a secondary index on a table to enable sorting on it. There are secondary indexes, but they aren't useful for that (they don't perform well on high cardinality data).

Want a different sort? Make a new table. And duplicate the data, since there are no JOINs.

I find this really cumbersome.

Re:NewSQL overview by pkolaczk on Saturday February 14, 2015 @05:21AM (#9049275)
This is because the top priority for Cassandra is being scalable and always-on in the first place. New features are added only if they meet these goals. Therefore you have guarantee it will always scale and it has no single point of failure, not even a temporary one, regardless of which feature you use.

Some other new database engines do it in different order - first adding as many RDBMS features as possible and then making some of them kinda scalable (in some circumstances, if the phase of the moon is right, etc.). Sure, that might feel less cumbersome at the beginning on a single laptop (feels like good old RDBMS), but once you scale it out, it is far from being all roses.

BTW, duplicating (denormalizing) data is the way to go if you really need scalability. In general case, joins or traditional indexes with references from the index leaves to the original data do not scale on distributed data sets.

Re:NewSQL overview by ddorian43 on Tuesday February 17, 2015 @07:20AM (#9061804)
You can do joins on the same partition-key + indexes(with references) only inside the partition-key.
[deleted]
Re:NewSQL overview by ddorian43 on Friday February 13, 2015 @01:06PM (#9045883)
that's for olap, while I was talking for oltp
Re:NewSQL overview by gliush on Friday February 13, 2015 @02:13PM (#9046480)
As a short answer - not yet, but it looks like in 2-3 years there will be at least one.