Re:MaxxBench – "Nice DeepSWE score. But is it true?"
by pianopatrick on Saturday November 07, 2026 @03:14PM
(#50407628)
That has unfortunate implications for the cost of using AI for coding.
Re:MaxxBench – "Nice DeepSWE score. But is it true?"
by verdverm on Sunday November 08, 2026 @10:24AM
(#50414057)
Hard to say.
1. we would need to see this comparison over generations of big vs small
2. most work does not require the best models, there are multiple reasons token prices have leveled off and are now decreasing
Re:MaxxBench – "Nice DeepSWE score. But is it true?"
by peri-cl on Saturday November 07, 2026 @04:14PM
(#50408135)
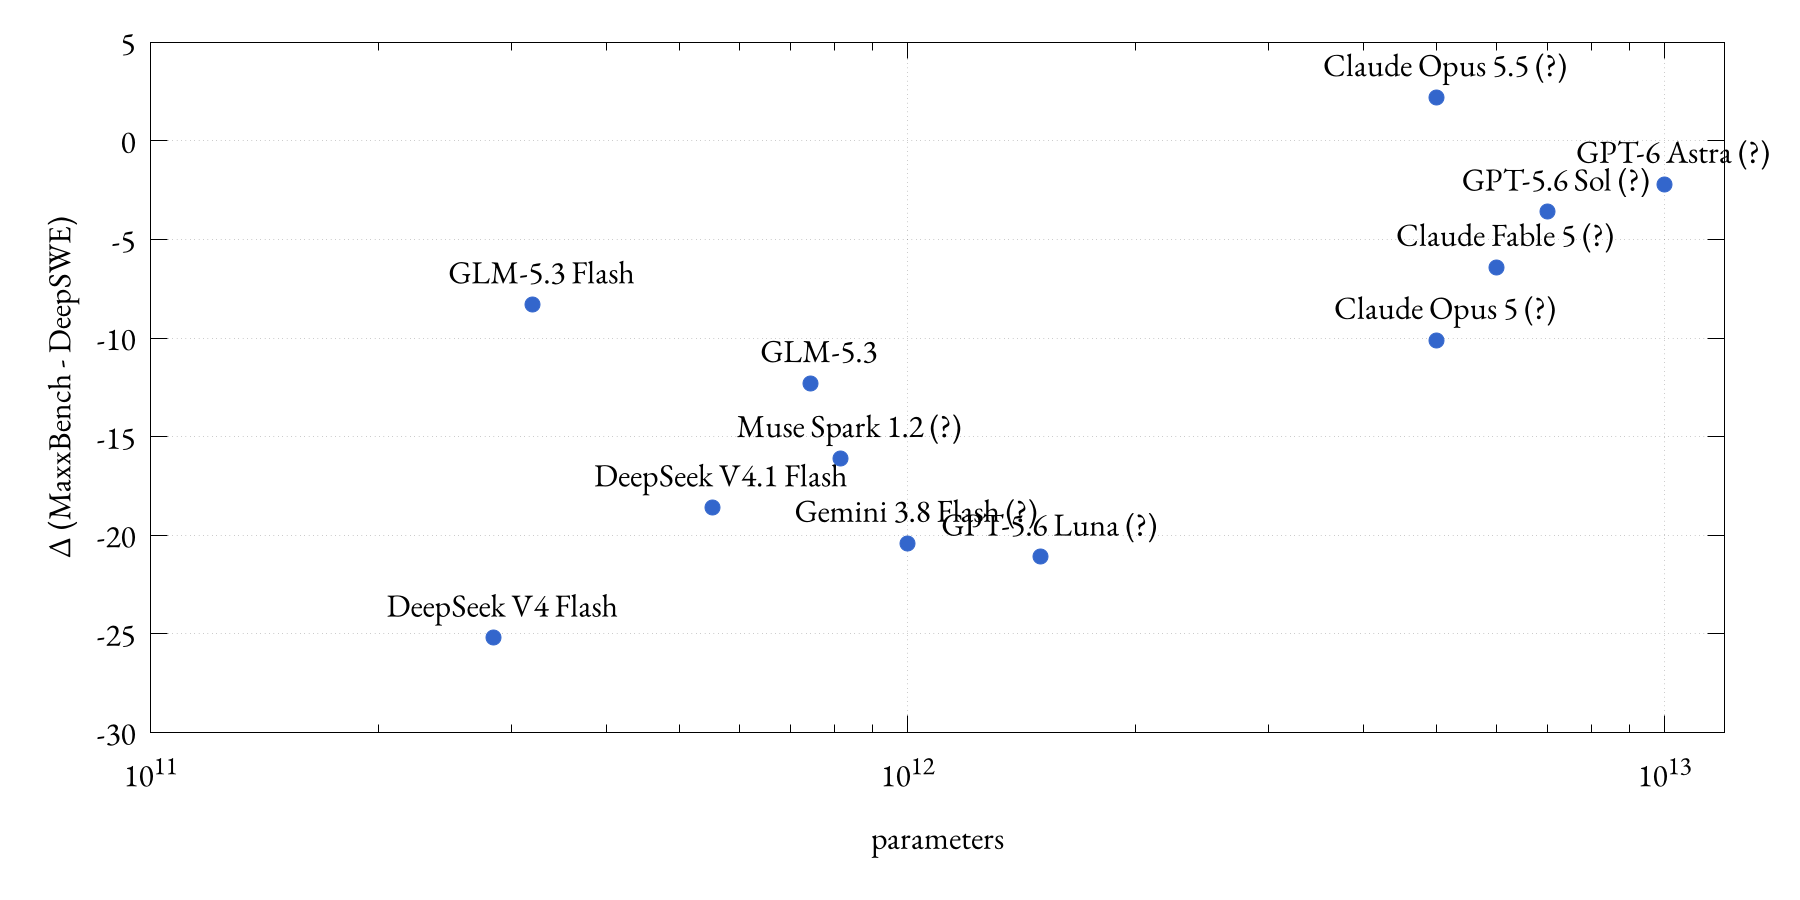
late edit to add: Here's a scatterplot to illustrate what I *speculate* is happening here ("(?)" means parameter counts are "community estimates"; i.e. garbage data; but they're on a log scale anyway),
Re:MaxxBench – "Nice DeepSWE score. But is it true?"
by druskacik on Saturday November 07, 2026 @04:50PM
(#50408365)
Another hypothesis is that it's distilled models which collapse the most (small models from big labs are distilled versions of their large models).
It's not unreasonable to assume Kimi 3.1 is also a distilled model even though it's large (the difference being that it's a distilled from US models). I wouldn't be surprised if it also collapsed on this benchmark.
Re:MaxxBench – "Nice DeepSWE score. But is it true?"
by Tade0 on Saturday November 07, 2026 @06:01PM
(#50408879)
There's an interesting way to find this out: ask the model "What are you?" hundreds of times. Around 1% of replies at default temperature are really left field.
For instance, I had Qwen3.8 Flash Next reply with "I'm Kilo Code, a coding agent designed to ...".
That was in llama.cpp's UI - no harness whatsoever.
Look at GPT 5.6-Sol vs. GPT 5.6-Luna in particular.
(The GLM's shouldn't follow this pattern because they're misnamed: GLM-5.3 and GLM-5.3-flash are different architectures. The -flash is an early version of a new pretrain).
If this *is* the main factor, I'd expect Kimi K3.1 and Carbon would also do well on this test, while Haiku 6 would collapse. It's a falsifiable prediction.