News for hackers. Stuff that matters.
Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by dnhkng on Tuesday March 10, 2026 @09:20AM (#47322904)
Author here. I found that duplicating a specific block of 7 middle layers in Qwen2-72B, without modifying any weights, improved performance across all Open LLM Leaderboard benchmarks and took #1. As of 2026, the top 4 models on that leaderboard are still descendants.

The weird finding: single-layer duplication does nothing. Too few layers, nothing. Too many, it gets worse. Only circuit-sized blocks of ~7 layers work. This suggests pretraining carves out discrete functional circuits in the layer stack that only work when preserved whole.

The whole thing was developed on 2x RTX 4090s in my basement. I'm now running current models (GLM-4.7, Qwen3.5, MiniMax M2.5) on a dual GH200 rig (see my other post). Code and new models coming soon.

Happy to answer questions.

Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by Balinares on Tuesday March 10, 2026 @12:09PM (#47325175)
The idea that there may be a cognitive lingua franca hiding in the layers is fascinating and gives me hope for a neat idea: pluggable knowledge banks.

MoE notwithstanding, a model trained on the whole Internet and a few hundred thousands stolen books carries way more knowledge than is actually needed for any given workflow. It would be great if we could ship slimmed down models into which we'd plug the knowledge banks useful for today's work, and only those.

It would also mean that you could keep a model's knowledge fresh without retraining the whole of it.

Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by gitpusher on Tuesday March 10, 2026 @01:14PM (#47326102)
> pluggable knowledge banks.

plugs in knowledge bank LLM: ... I know kung fu.

Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by dormento on Tuesday March 10, 2026 @01:32PM (#47326336)
This is interesting. Would this mean less space for hallucination as well (depending on the breadth of knowledge applied to a specific task)?
Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by pennomi on Tuesday March 10, 2026 @03:00PM (#47327457)
Agreed, I suspect that LLMs in the future will have separate (possibly standardized) decoding/encoding layers that plug into logic layers.
Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by ay on Tuesday March 10, 2026 @09:31PM (#47330862)
Isn’t that what LoRA does ?
Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by CuriouslyC on Tuesday March 10, 2026 @10:36PM (#47331202)
LoRAs are better at steering models to produce correct answers from their data set than imparting new knowledge.
Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by kgeist on Thursday March 19, 2026 @04:59AM (#47436627)
https://arxiv.org/abs/2603.01097

>Overall, our findings position LoRA as the complementary axis of memory alongside RAG and ICL, offering distinct advantages.

Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by rapatel0 on Tuesday March 10, 2026 @11:04AM (#47324257)
I think you may have cracked latent space reasoning. I've had a hunch that something like this would work, but couldn't figure out how the training would back propagate. But you've shown that you just need to duplicate existing layers.

Have you tried a simple inline loop over the duplicated layers? Would be interesting to see performance. Also, would be interesting to compare with a MOE model. See if these layers are acting like different agreeing "experts" or if there is reasoning happening in the latent space.

Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by dnhkng on Tuesday March 10, 2026 @12:18PM (#47325289)
Yes, I've tried duplicating indvidual layers, but its not useful.

I think this hasn't been tried before because it's totally unintuitive that feeding the output from later layers into previous ones would actually do anything. And in fact, it usually is detrimental. I guess it takes really bored hobbyists with too much compute to check this stuff.

I have done some interesting work on applying multiple layer duplications in different regions of the model too, going so far as to train a meta-model (actually just XGBoost) to predict the merges. Seems to work, buts thats a whole other blog post.

This works with MoE, and yes, I would be interested in looking into this in more detail. But my wife might disagree with this time sink...

Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by rapatel0 on Tuesday March 10, 2026 @03:29PM (#47327766)
Clarification. Duplicating multiple groups of layers in a "reasoning" loop

Normal:

  L1 -> L2 -> L3 -> L4 -> out
Unrolled (current framing):

  L1 -> [L2->L3] -> [L2->L3] -> L4 -> out
Looped (proposed):

       --<--loop----
       |           |

  L1 -> [L2->L3] x N --> L4 -> out
"reasoning loop"

Note: ascii rendering HN is not trivial

Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by gavinray on Tuesday March 10, 2026 @04:00PM (#47328081)
The commenter "Skerit" below linked to a recent implementation of this:

https://ouro-llm.github.io/

See the left-hand side of the diagram here, which is your exact proposal:
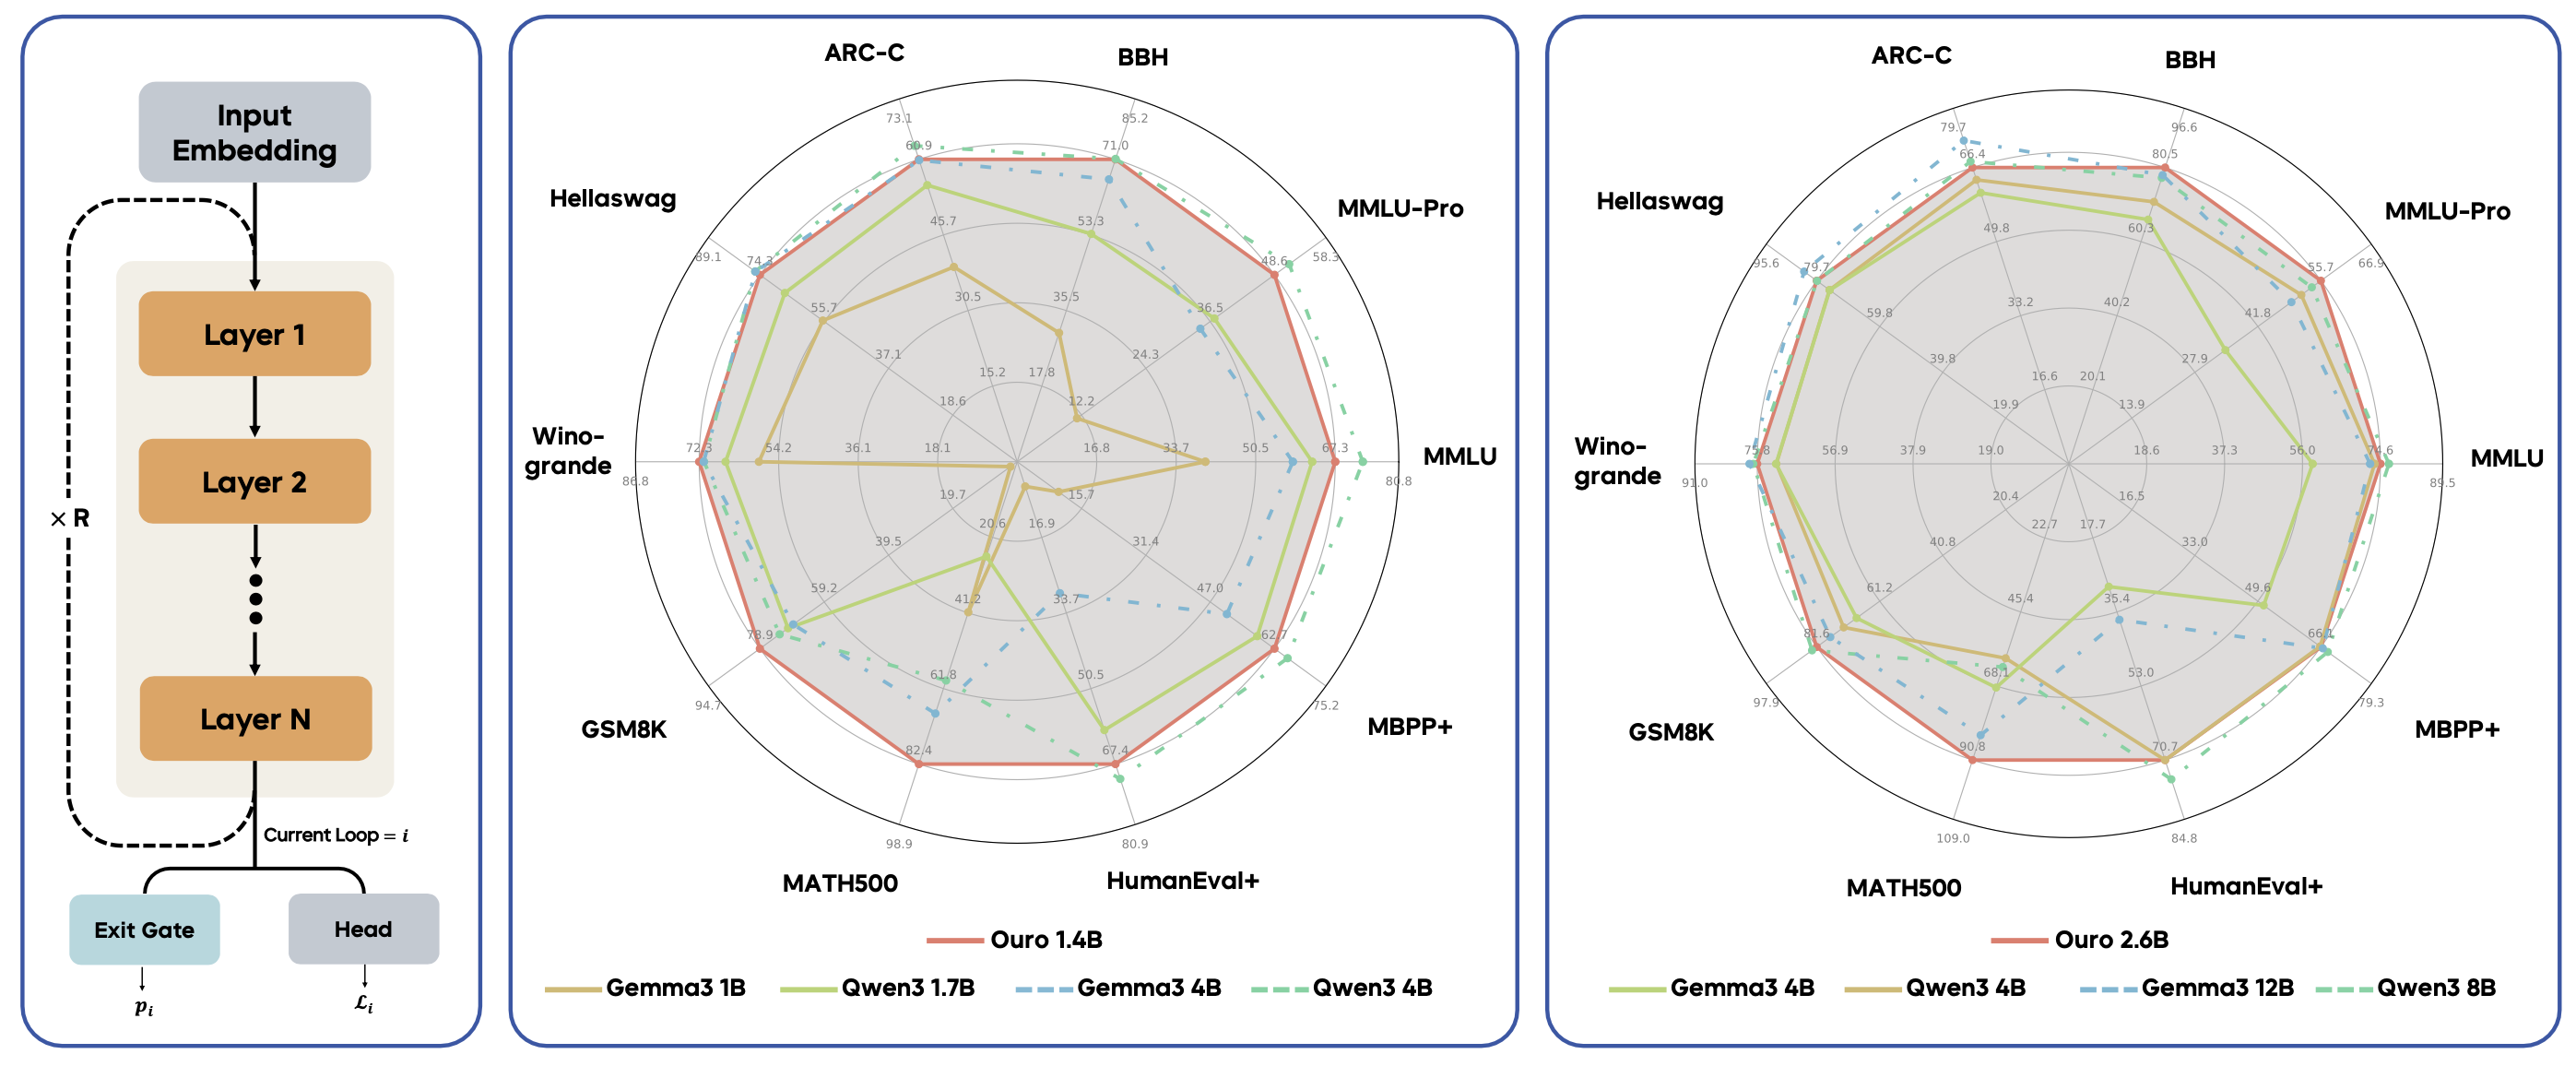
https://ouro-llm.github.io/static/images/ouro_main.png

Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by skerit on Tuesday March 10, 2026 @12:59PM (#47325894)
This is kind of what LoopLM is doing, no? https://arxiv.org/abs/2510.25741
Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by rapatel0 on Tuesday March 10, 2026 @05:47PM (#47329182)
Thanks. This is cool
Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by digdugdirk on Tuesday March 10, 2026 @11:37AM (#47324724)
Super cool! Do you do any analysis or have any tools that help you identify these circuits? I came across this [1] recently, and wanted to try to identify specifically strong "circuits" in what seems to be a similar way to what you did.

[1] https://weightwatcher.ai/

Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by dnhkng on Tuesday March 10, 2026 @11:47AM (#47324862)
I build my own analysis tools. I'm just finishing up running the current generation of LLMs (MiniMax M2.5 and the Qwen3.5 family), and then I will put it all on Github.

It less 'tool', than an assorted set of scripts, tailored to my unusual hardware setup. But it should be easy to extend; I would have released this earlier but I had the (stupid) idea to 'write a paper' on this. Aiming for that delayed this a year. Blogs are the way to go (for me).

Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by naasking on Tuesday March 10, 2026 @11:10AM (#47324329)
This layer duplication strikes me as a bit of "poor man's" version of looped language models:

https://ouro-llm.github.io/

Pretty cool though. LLM brain surgery.

Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by dnhkng on Tuesday March 10, 2026 @11:51AM (#47324922)
Agrees, but one thing to note:

I really think from the experiments that 'organs' (not sure what to term this), develop during massive pretraining. This also means maybe looping the entire models is actually not efficient. Maybe a better way is [linear input section -> loop 1 -> linear section -> loop 2 -> linear section -> ... -> loop n -> linear output]?

This would give 'organs' space to develop.

Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by radarsat1 on Tuesday March 10, 2026 @03:31PM (#47327788)
it also reminds me a bit of this diffusion paper [1] which proposes having an encoding layer and a decoding layer but repeats the middle layers until a fixed point is reached. but really there is a whole field of "deep equilibrium models" that is similar. it wouldn't be surprising if large models develop similar circuits naturally when faced with enough data.

finding them on the other hand is not easy! as you've shown, i guess brute force is one way.. it would be nice to find a short cut but unfortunately as your diagrams show, the landscape isn't exactly smooth.

I would also hypothesize that different circuits likely exist for different "problems" and that these are messy and overlapping so the repeated layers that improve math for example may not line up with the repeated layers that improve poetry or whatever, meaning the basic layer repetition is too "simple" to be very general. that said you've obviously shown that there is some amount of generalizing at work, which is definitely interesting.

[1] https://arxiv.org/abs/2401.08741

Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by jauntywundrkind on Tuesday March 10, 2026 @11:29AM (#47324606)
The dual GH200 build was amazing. Awesome to see someone with such talent & flare in one area also doing great in another area. Thanks for noting that that was you. https://news.ycombinator.com/item?id=46222237
Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by afpx on Tuesday March 10, 2026 @12:52PM (#47325808)
Thank you so much for sharing this in a delightful blog post. One of the more enjoyable things I've read in a while. Very motivating!
Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by user_7832 on Tuesday March 10, 2026 @12:54PM (#47325835)
Thanks for the post, really cool stuff you did!

Extra thanks for making it written in a readable and approachable way! I don't have much of a background in this topic, but still managed to understand about 70-80% of it :) You're a good writer

Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by phn on Tuesday March 10, 2026 @02:47PM (#47327282)
A fascinating thing for me after reading this is: how can it be that the "circuit input" is compatible with its output to the point where the performance improves? The training process never saw this particular connection just like it didn't see layer 60 output into layer 3 or whatever.

Great read, makes you wonder what else is encoded in these models that might be useful!

Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by nixon_why69 on Tuesday March 10, 2026 @11:31PM (#47331479)
I think the intuition is that the first N layers decode into "thought language" while the last N encode back to desired output language. So if there are well defined points where it transitions between decoding/understanding, thinking, and rendering back to language, those 2 transition points should be in the same vector space of "LLM magic thinking language".
Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by 3abiton on Tuesday March 10, 2026 @03:24PM (#47327723)
Man, that was such an enjoyable read. I loved your story on the wild server hunt, back when it was posted on r/localllama. I think one thing that is missing from the whole AI "discussion" is this train of thought of how we go from abstract mathetmatical formulation to intuitive understanding of the underlying functionality, and you showcased it beautifully in this article. Similarly to 3blue1brown who also did an amazing series on transformers. Kudos!
Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by himmi-01 on Tuesday March 10, 2026 @05:42PM (#47329138)
How did you get this idea? What was the inspiration behind it? I mean who would of duplication :) ?!
Re:Show HN: How I Topped the HuggingFace Open LLM Leaderboar... by lifis on Tuesday March 10, 2026 @06:40PM (#47329671)
Have you tried replicating those middle layers 3 or more times instead of just 2?