A similar concern has sparked some worries about "AI overhang" https://www.lesswrong.com/posts/75dnjiD8kv2khe9eQ/measuring-...
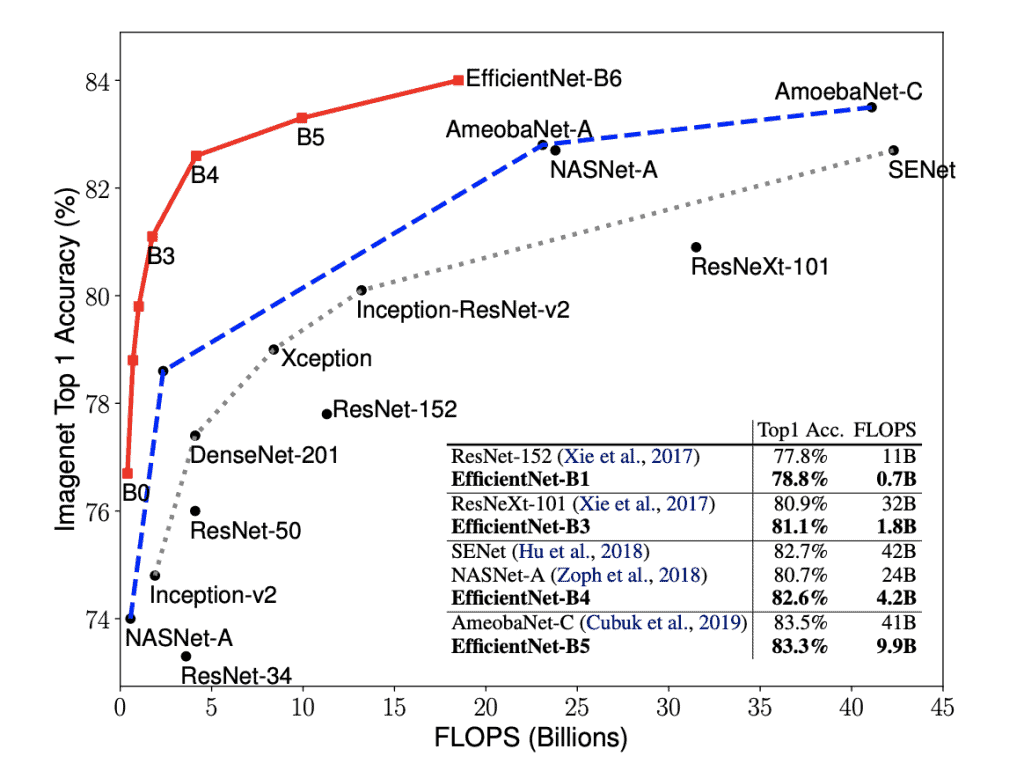
Most of the compute in ML research seems to be going into architecture search. Once the architecture is found, training and net finetuning/transfer learning is comparatively cheap, and then inference is cheaper still. This implies we could see 10-100x gains in AI algorithms using today's hardware, or sudden surprising appearance of AI dominance in an unexpected field. (Object grasping in unstructured environments? Art synthesis?) A task could go from totally impossible to trivial in a year. In retrospect, the EfficientNet scaling graph should have alarmed more people than it did: https://learnopencv.com/wp-content/uploads/2019/06/Efficient...
Waymo has been puttering along for years, not announcing much of interest. This may have caused some complacency about self-driving cars, which is a mistake. Algorithms only get better, while humans stay the same. Once Waymo can replace some human drivers some of the time, things will start changing very quickly.
But that happened 1y+ ago [1][2] without much changing since?
[1] https://www.theverge.com/2019/12/9/21000085/waymo-fully-driv...
[2] https://blog.waymo.com/2020/10/waymo-is-opening-its-fully-dr...
There is a reason Waymo is progressing at what looks like snail speed from outside observers, and that reason is that it’s the only ethical pace for development and testing of what could eventually become broadly available fully autonomous vehicles.
Both have their advantages and disadvantages. Waymo requires huge databases and a constant network connection. But it's good enough to be used in real-life without a backup driver, in certain select locations that is. If there's a road construction somewhere, don't expect the Waymo car to handle it unless they update their database.
Tesla on the other hand attempts to solve the problem with minimal database use, where most of the info coming from road markings and traffic signs. A much harder problem.
It’s obviously complex, though, bad PR likely delays things as well.
No it's not. Only Google spends significant time with automatic architecture search, and many people think this is really to try to sell cloud capacity.
> Once the architecture is found, training and net finetuning/transfer learning is comparatively cheap
Training isn't cheap for significant problems.
Getting the data is very expensive, and compute is a significant expense for large datasets.
> This implies we could see 10-100x gains in AI algorithms using today's hardware
Actually, most of the time we see 10-100% (percent! not times) gains from architecture improvements, whether they be manual or automatic.
But that is very significant, because a 10% improvement can suddenly make something useful that wasn't before.
Maybe not automatic architecture search but a lot does go into testing different architectures and changes to them in a more manual manner. Though yes, those tests are run on a smaller scale so for those huge models, training will be a bigger portion compared to architecture search than for smaller models.
If you don't you might not realize they are comparing ResNet (designed for ultimate performance) vs EffcientNet to show how close it gets in accuracy in the FLOPs budget.
Note that the best accuracy for EffcientNet is roughly 1-2% better than ResNet/ResNeXT/SENet/etc but does have a much better FLOPs budget.
But these other architectures were never optimised for FLOPs. It wasn't event a consideration when designing them.
And EffcientNet is about a (manually designed) technique for scaling neural networks up in accuracy. Only EffcientNet-B0 is designed by AutoML, the others are scaled up. See the paper[1] for complete details.
Like-for-like should be against MobileNet etc. EfficentNet is better, but the comparison is more reasonable in general.
https://machinethink.net/blog/mobile-architectures/ is a really good overview.
Yeah, the HN commentary on Alphafold has a high heat-to-light ratio. I'm eager to read the paper because the previous description of the method sounded remarkably similar to methods that have been around for ages, plus a few twists.
The devil is going to be in the details on this one.
Sorry for the ignorance but what does this mean?
So in this context I suppose that gp implies that these threads don't provide much meaningful discussion but rather lots of hand waving.
I even predicted DeepMind's CASP 14 network would be transformer-based back in 2018, but I couldn't have told you the details of that transformer, just that it was a no-brainer to move from fixed width convolutions to arbitrary width attention sums because sequence motifs and long-range interactions are of arbitrary width in the sequence.
All that seems to have changed with AlphaFold 2 because unlike GPT-XXX, this isn't a parlor trick with memorized text. This is actually useful and the FOSSing of the network will spawn all sorts of new applications of the approach.
So now I wonder what will replace Transformers because nothing lasts forever and there are a lot of smart people trying all sorts of new ideas.
Fundamentally, everything in this space (= non-physical methods) is about inferring structure from things that are closely related. And you can't solve the problem at all for non-trivial proteins using physics, so here we are.
I'd appreciate if you could expand a bit on what you meant here, sounded interesting.
People take these simple models, chain them together in different ways, adjust the free parameters (i.e. weights) by fitting to known data, and thus create "force fields" that can be used to estimate the energies and/or forces on a molecule, given only the coordinates of the atoms. These methods work OK for some limited problems, but tend to fly off the rails as simulation times get longer, or if atomic systems have more electrostatics, motion, "weird" atoms (like heavy metals), etc.
This (Alphafold) kind of work is completely different, in that it starts from data, and uses the physical models only to do final refinements (if at all).
It's a little like making a robot that is very, very good at something pointless (say, using a yo-yo). Who knows where it might lead, but if they make the best damned yo-yo bot in the world, they deserve whatever praise they get from the yo-yo community.
Superhuman game AI has existed for decades. It's entirely unsurprising that one can play a strategy game, and no one thought it wasn't possible.
I'll send you $500 USD if AlphaFold derivatives lead to a single new therapy or drug that helps real patients in the next 5 years.
'bah, whatever, both Newton and Leibniz were hacks. Everyone knew calculus would have been invented anyway. It's basically a consequence of some stuff Archimedes did.'
This was actually fairly obvious 20 years ago and it's been disappointing to me to see how long it took somebody to make this improvement, but really, it couldn't have been done without recent algorithmic improvements and huge amounts of CPU time.
The phrase 'who pissed in your cheerios' comes to mind... Here's hoping that if you ever build something worthwhile it is received with a bit more compassion.
Something along these lines was speculated to be to be used by Fabian Fuchs [0] soon after the original CASP competition. Basically, it's a huge win for the geometric deep learning people, and indicates an exciting direction for mainstream academia to move in.
I may be cynical about general expertise, as a support person, but large datasets have long been stock in trade of areas I'm more or less familiar with, whether "large" is TBs or PBs like CERN experiments. (When I were a lad, it was what you could push past the tape interface in a few days -- data big in cubic feet...)
Very few players wrangle petabytes effectively. Many players have petabytes, but they're just piles of disorganized data that couldn't be used for training ML. Moving petabytes is still a huge pain and few folks have proficiency in giving ML algorithms high performance access to the data.
For example, multi-complex proteins are not well predicted yet and these are really important in many biological processes and drug design:
https://occamstypewriter.org/scurry/2020/12/02/no-deepmind-h...
A disturbing thing is that the architecture is much less novel than I originally thought it would be, so this shows perhaps one of the major difficulties was having the resources to try different things on a massive set of multiple alignments. This is something an industrial lab like DeepMind excels at. Whereas universities tend to suck at anything that requires a directed effort of more than a handful of people.