nmitchko
Re:Show HN: DeepSeek-V4 Latent Reasoning – moving "thinking" into late...
on Sunday August 09, 2026 @03:12PM (#49234638)
The goal of this auxiliary module is to have the model recurse pre-emit trained on good thinking traces. This includes a 6-to-1 compression of thinking tokens.
Therefore output tokens are decodeable, but are trained compressed. So they are approximations of faster thinking.
Interpretability is a mixed bag even with trained tools on top of existing models.
Re:Show HN: DeepSeek-V4 Latent Reasoning – moving "thinking" into late...
on Sunday August 09, 2026 @10:45AM (#49231901)
Fair criticism, i’ll rewrite it… as this is a pet project and post based on another HN comment.
Re:Show HN: DeepSeek-V4 Latent Reasoning – moving "thinking" into late...
on Sunday August 09, 2026 @10:44AM (#49231894)
After vLLM startup I observed this on first request only then all further conversations were fine, new and original. Can’t figure out why but seems to be fine after that.
Re:Show HN: DeepSeek-V4 Latent Reasoning – moving "thinking" into late...
on Sunday August 09, 2026 @10:42AM (#49231873)
My main motivation is to be able to tune the thinking effort without polluting token IO. Inspiration came from the CoLaR paper and other works showing that repeating laters in an LLM got better results.
Re:Show HN: DeepSeek-V4 Latent Reasoning – moving "thinking" into late...
on Sunday August 09, 2026 @10:40AM (#49231864)
I am on my own GPUs so thought it be cool to reduce token output. you can charge per latent loop as a token i guess.
I wanted a knob to keep thinking going until it was sure it was done.
Re:Show HN: DeepSeek-V4 Latent Reasoning – moving "thinking" into late...
on Sunday August 09, 2026 @10:39AM (#49231857)
I can do that, main difference seems to be this ablation seems to over think simple prompts, but can do a proper eval (might take 2-3 days)
Re:Show HN: DeepSeek-V4 Latent Reasoning – moving "thinking" into late...
on Sunday August 09, 2026 @10:38AM (#49231851)
Fair critique, ill rewrite (this is just my personal pet project but thought was cool to share here)
Re:DeepSeek V4 Flash 0731
on Sunday August 09, 2026 @07:52AM (#49230591)
Re:DeepSeek V4 Flash 0731
on Saturday August 08, 2026 @06:12AM (#49220375)
It’s an adaptation of CoLaR, but my implementation is a little different:
- Dedicated stop head to fire when latent thinking hits threshold
- MTP support with training taking draft support as first class
- different architectural layer 35 -> layer 42 writeback. So latents skip roughly 6.2 tokens of reasoning per token, then never make it to decoded output
Re:DeepSeek V4 Flash 0731
on Friday August 07, 2026 @05:19PM (#49216358)
Perhaps it might be interesting: a latent thinking version is here https://huggingface.co/nmitchko/DeepSeek-V4-Flash-0731-Laten...
Does no thinking emissions for context saving.
Re:DeepSeek-V4-Flash-0731-Latent-Reasoning. A model thinking in latent...
on Thursday August 06, 2026 @09:41AM (#49196565)
Author of this model - I was curious how large models do adaptive thinking and it got me down the path of implementing a model with latent only thinking.
The part I think is most interesting is that the reasoning never touches your context window. The model thinks in a compressed 1024-dim latent space, then decodes just the answer, so a ~6-token reasoning step collapses into one latent step. It also self-terminates: a learned stop head ends the thinking when it's done, so easy questions budget a few steps and hard ones run up to ~256.
The tradeoffs: Blackwell-only (NVFP4), on a vLLM fork (upstream can't serve it due to hash-MoE routing), the trace isn't interpretable, and eval is BBH-only. Happy to answer questions about the closed-loop runtime:: getting the latent injection onto the cudagraph fast path was the fiddly part.
DeepSeek-V4-Flash-0731-Latent-Reasoning. A model thinking in latent space
Re:The Doctor Is Not the Mother: DS4 Latent Reasoning
on Thursday July 16, 2026 @09:35PM (#48942448)
Poster: The cool part is that the model literally talks itself out of giving the cached wrong answer with a latent only thinking budget.
The Doctor Is Not the Mother: DS4 Latent Reasoning
Re:AlphaEvolve: Gemini-powered coding agent scaling impact across fields
on Thursday May 07, 2026 @02:32PM (#48053014)
A fantastically simple solution to improving algorithms, I wish I had this years ago in activation engineering: https://blog.n.ichol.ai/llm-activation-engineering-an-easy-f...
How do I access AlphaEvolve?
Re:Ah, peptides. where to begin?
on Tuesday April 07, 2026 @09:26AM (#47675063)
I used those two in combination to fix pain after 3x surgeries to repair a torn pec + infection. They work and helped me heal from being at a 3/10 constant pain down to baseline.
Not something I would do at any point for fun. But anecdotally, it's materially better than other alternatives offered/available.
Re:In 2025, Meta paid an effective federal tax rate of 3.5%
on Thursday February 26, 2026 @10:40AM (#47167542)
Can someone make a startup that allows me to do this as an individual?
Re:Show HN: Semantic search over the National Gallery of Art
on Friday October 10, 2025 @05:36PM (#45544055)
In case anyone wants to do this themselves, check out the pipeline here: https://github.com/isc-nmitchko/iris-document-search
Colnomic and nvidia models are great for embedding images and MUVERA can transform those to 1D vectors.
Re:Qwen3-Omni: Native Omni AI model for text, image and video
on Monday September 22, 2025 @03:57PM (#45338664)
Next steps for AI in general:
  - additional modalities
  - Faster FPS (inferences per second)
  - Reaction time tuning (latency vs quality tradeoff) for visual and audio inputs/outputs
  - built-in planning modules in the architecture (think premotor frontal lobe)
  - time awareness during inference (towards an always inferring / always learning architecture)
Re:LLMD: A Large Language Model for Interpreting Longitudinal Medical ...
on Friday October 18, 2024 @06:59PM (#41884245)
No other models that are public worth comparing to... Hippocratic advertises good benchmarks but that might be marketing fluff.
Have you checked out dataset building with nemotron? The nemotron synthetic data builder is quite powerful.
Moreso, check out model merging. It's possible if you merge some of your model against llama3.1 base it may perform much better.
Check out max labonne's work on hugging face
Re:LLMD: A Large Language Model for Interpreting Longitudinal Medical ...
on Friday October 18, 2024 @09:37AM (#41879345)
Interesting they don't compare to open-bio. Page 7 charts are quite weak.
Re:Show HN: We built pitchpilot, an AI synthesizer to tailor presentat...
on Wednesday July 17, 2024 @10:35AM (#40986395)
We're excited to share pitchpilot with the HN community. Our beta users have found the embedded audio particularly useful for enterprise sharing. We're keen to keep improving, and our mission is to make communication easier.
In the roadmap is adding video export, digital twin presentations, and real-time presentations. We don't wrap a public LLM, so we don't share any data.
Show HN: We built pitchpilot, an AI synthesizer to tailor presentations
Hey HN,We’re Nick and Roman. We’re solutions engineers who spend a lot of time prepping for and delivering product presentations and demos. We realized that we were spending too much time tailoring scripts for our client presentations and sales demos, practicing our pitch and (sometimes) nailing our delivery.So we built pitchpilot to save time customizing the pitch and adding the right voice to...
Re:US intelligence community is embracing generative AI
on Sunday July 07, 2024 @01:09PM (#40898900)
Given that Generative AI can now read brain scans [1] and this, I wonder how far away we are from "you thought negatively about something, the authorities are on their way".
[1] -- https://www.biorxiv.org/content/10.1101/2022.11.18.517004v3
Re:Superfast Microsoft AI is first to predict air pollution for the wh...
on Wednesday June 05, 2024 @09:47AM (#40584707)
Tin-foil hat time:
1. First, models will predict pollution. The outcomes will help shape urban policy. But these won't solve crime or stop people from driving.
2. Second, models will predict individual behavior and track person level emissions. The outcomes will force behavior changes, mostly freedom limiting.
3. Third, and finally, models will predict thoughts. The the thought of driving instead of walking might trigger a response.
It's a slippery slope and we need to draw a line between prediction and policy.
Re:Launch HN: Metriport (YC S22) – Open-source API for healthcare data...
on Thursday May 23, 2024 @02:07PM (#40457902)
How does this compare to ehealthexchange or other qhins that have many years of experience and charge lower costs?
Re:Qwen1.5-110B
on Friday April 26, 2024 @08:48AM (#40168793)
It truly feels like the space race in terms of building LLMs right now. Question is, who lands on the moon first?
Re:Show HN: NeuralFlow – Visualize the intermediate output of Mistral 7B
on Thursday February 15, 2024 @08:09AM (#39382221)
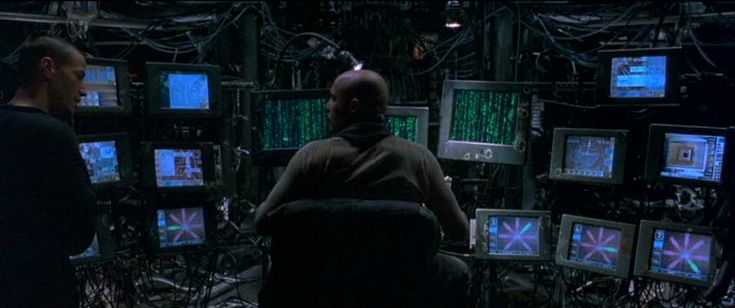
This reminds me of the matrix movie scene when they look at the encrypted thoughts of the matrix.
https://cdn.swisscows.com/image?url=https%3A%2F%2Fi.pinimg.c...
Re:Lucidrains/self-rewarding-lm-PyTorch: Self-Rewarding Language Model...
on Wednesday January 24, 2024 @10:35PM (#39125939)
Great work, will try this tonight.
Only question, why do you name variables with the λ symbol?