News for hackers. Stuff that matters.
Re:We made Grok 4.5, GPT-5.5, and Claude build the same apps by HeavyStorm on Wednesday July 08, 2026 @09:41PM (#48839886)
Excellent idea, most terrible execution. Comparison are completely subjective, problem space is too simplistic for today's AI, the resultstable simply ignores that a face isn't a cube (therefore, gpt 5 shouldn't have 100% success) and the retry is uneven. Also, given the random nature of AI, sampling once each model isn't very scientific.

This feels like a kid trying to do science. The will is there, but lacks experience.

Re:We made Grok 4.5, GPT-5.5, and Claude build the same apps by sinuhe69 on Wednesday July 08, 2026 @10:54PM (#48840416)
It said “3D-looking Rubrik cube”. Maybe your cube looks different but I’m pretty sure for everyone else, the GPT result doesn’t look like a 3D-looking Rubrik cube.
Re:We made Grok 4.5, GPT-5.5, and Claude build the same apps by hyperhello on Wednesday July 08, 2026 @10:19PM (#48840167)
It’s still science if you say “this appears to be a specimen of X” even if you don’t do a genetic test. Things don’t automatically graduate to science either by repetition or by formal verification. What makes a rubics cube is obvious enough that you can pass or fail.
Re:We made Grok 4.5, GPT-5.5, and Claude build the same apps by looksjjhg on Wednesday July 08, 2026 @11:18PM (#48840556)
Show us how it’s done then, talk is cheap
Re:We made Grok 4.5, GPT-5.5, and Claude build the same apps by remus on Thursday July 09, 2026 @02:15AM (#48841656)
> This feels like a kid trying to do science. The will is there, but lacks experience.

It's funny, when I saw the title I was hoping the article would include some sort of blind ranking, where you could see the outputs (without knowing which model they came from) and score them on some criteria. Could have been a fun way to get a better ranking of the results.

Re:We made Grok 4.5, GPT-5.5, and Claude build the same apps by coldtea on Thursday July 09, 2026 @05:24AM (#48843163)
>Comparison are completely subjective

Nothing wrong with that.

In this case, the requirement is clear enough, and the result is similar enough to judge it subjectively.

Even code-wise, if tests pass and the features are there in all cases, the rest of what matters (architecture, code quality, style, readability) is all subjective too.

Re:We made Grok 4.5, GPT-5.5, and Claude build the same apps by drcongo on Thursday July 09, 2026 @06:33AM (#48843679)
GPT somehow wins the particle sandbox thing too despite its heavy attractors not attracting anything.
Re:We made Grok 4.5, GPT-5.5, and Claude build the same apps by logicalappeals on Thursday July 09, 2026 @08:38AM (#48844944)
> This feels like a kid trying to do science.

lol. These are the comments that keep bringing me back here. Great feedback delivered with a dash (or more) of salt.

Re:We made Grok 4.5, GPT-5.5, and Claude build the same apps by 6510 on Thursday July 09, 2026 @11:53AM (#48847984)
I wouldn't be surprised if multiple versions of both the cube and Breakout code are available some place online.

https://upload.wikimedia.org/wikipedia/en/c/cd/Breakout_game...
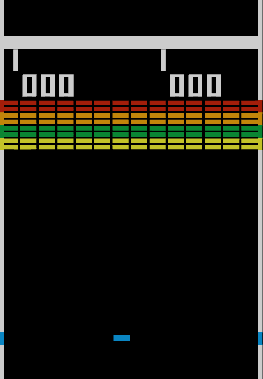
https://upload.wikimedia.org/wikipedia/commons/1/1a/Screensh...
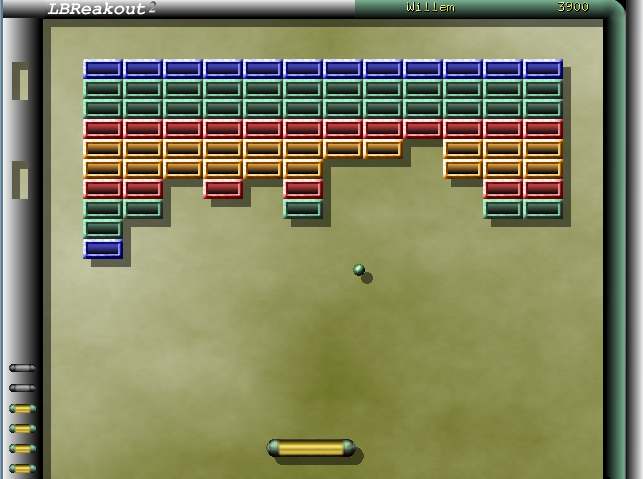
That the tiles are much to thick makes Grok the most reasonable result.

Re:We made Grok 4.5, GPT-5.5, and Claude build the same apps by dang on Friday July 10, 2026 @06:19PM (#48866040)
You broke the HN guidelines badly with this, first because of the name-calling and personal attack, and second because it is a shallow dismissal in exactly the sense we ask people not to post here:

"Please don't post shallow dismissals, especially of other people's work. A good critical comment teaches us something." - https://news.ycombinator.com/newsguidelines.html

On the plus side, your comment does contain some specific observations which could have made for a good comment—one that communicates interesting information respectfully. If you'd please post that way in the future, we'd appreciate it.