There's basically no reason to run other open source models now that these are available, at least for non-multimodal tasks.
I'm still withholding judgement until I see benchmarks, but every point you tried to make regarding model size and parameter size is wrong. Qwen has more variety on every level, and performs extremely well. That's before getting into the MoE variants of the models.
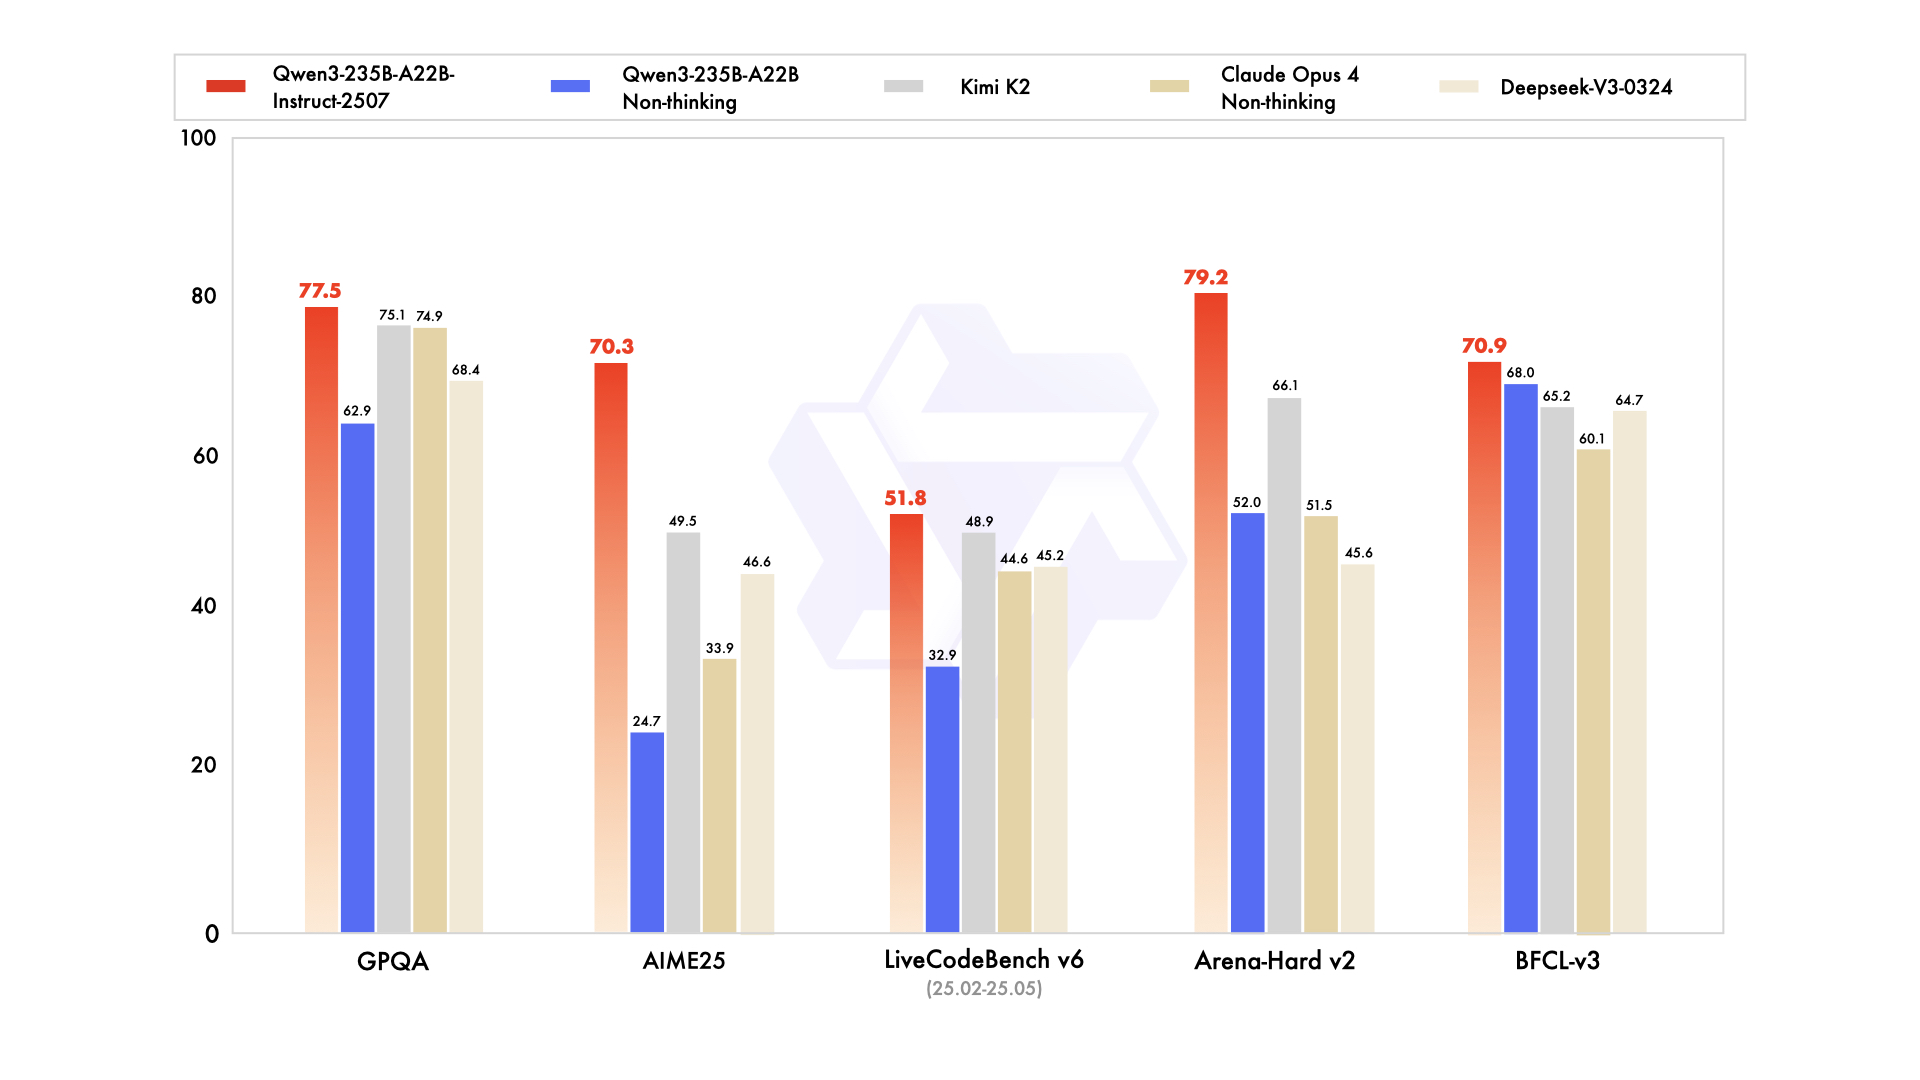
It's cool to see OpenAI throw their hat in the ring, but you're smoking straight hopium if you think there's "no reason to run other open source models now" in earnest. If OpenAI never released these models, the state-of-the-art would not look significantly different for local LLMs. This is almost a nothingburger if not for the simple novelty of OpenAI releasing an Open AI for once in their life.
So are/do the new OpenAI models, except they're much smaller.
Qwen-0.6b gets it right.
So far I have mixed impressions, but they do indeed seem noticeably weaker than comparably-sized Qwen3 / GLM4.5 models. Part of the reason may be that the oai models do appear to be much more lobotomized than their Chinese counterparts (which are surprisingly uncensored). There's research showing that "aligning" a model makes it dumber.
We seem to censor organized large scale complaints and viral mind virii, but we never quite forbid people at home to read some generated knowledge from an obscure hard to use software.