Any concerns about open source “AI celebrity talks” like yours can be used in contexts that would allow LLM models to optimize their market share in ways that we can’t imagine yet?
Your talk might influence the funding of AI startups.
#butterflyEffect
Simon, hope you are comfortable in your new role of AI Celebrity.
Karpathy used it as an example in a recent interview: https://www.msn.com/en-in/health/other/ai-expert-asks-grok-3...
Also, as the old saying goes, the only thing worse than using benchmarks is not using benchmarks.
The number of subject-verb-objects are near infinite. All are imaginable, but most are not plausible. A plausibility machine (LLM) will struggle with the implausible, until it can abstract well.
Until there is enough unique/new subject-verb-objects examples/benchmarks so the trained model actually generalized it just like you did. (Public) Benchmarks needs to constantly evolve, otherwise they stop being useful.
clarification: I enjoyed the pelican on a bike and don't think it's that bad =p
people expect LLMs to say "correct" stuff on the first attempt, not 10000 attempts.
Yet, these people are perfectly OK with cherry-picked success stories on youtube + advertisements, while being extremely vehement about this simple experiment...
...well maybe these people rode the LLM hype-train too early, and are desperate to defend LLMs lest their investment go poof?
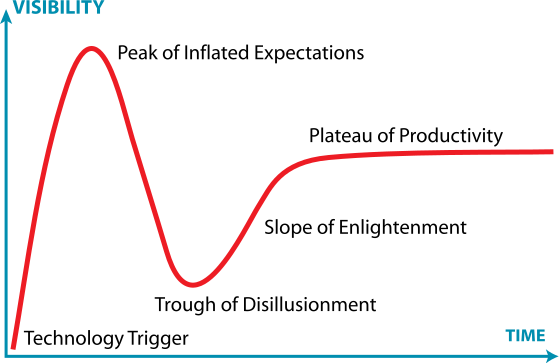
obligatory hype-graph classic: https://upload.wikimedia.org/wikipedia/commons/thumb/9/94/Ga...
In your case, it would be neat to have a bunch of different models (and maybe MTurk) pick the winners of each head-to-head matchup and then compare how stable the Elo scores are between evaluators.
I've been considering an expanded version of this where each model outputs ten images, then a vision model helps pick the "best" of those to represent that model in a further competition with other models.
(Then I would also expand the judging panel to three vision LLMs from different model families which vote on each round... partly because it will be interesting to track cases where the judges disagree.)
I'm not sure if it's worth me doing that though since the whole "benchmark" is pretty silly. I'm on the fence.