Re:TopoNets: High performing vision and language models with...
by dang on Friday January 31, 2025 @12:01AM
(#42884830)
Submitted title was "Inducing brain-like structure in GPT's weights makes them parameter efficient". We've reverted it now in keeping with the site guidelines (https://news.ycombinator.com/newsguidelines.html).
Since the submitter appears to be one of the authors, maybe they can explain the connection between the two titles? (Or maybe they already have! I haven't read the entire thread)
Re:TopoNets: High performing vision and language models with...
by mayukhdeb on Friday January 31, 2025 @10:21AM
(#42888541)
Thanks for clarifying your reason for renaming the title.
The explanation for the original title is this plot from our publication in ICLR 2025: https://toponets.github.io/webpage_assets/FigureEfficiencyNa...
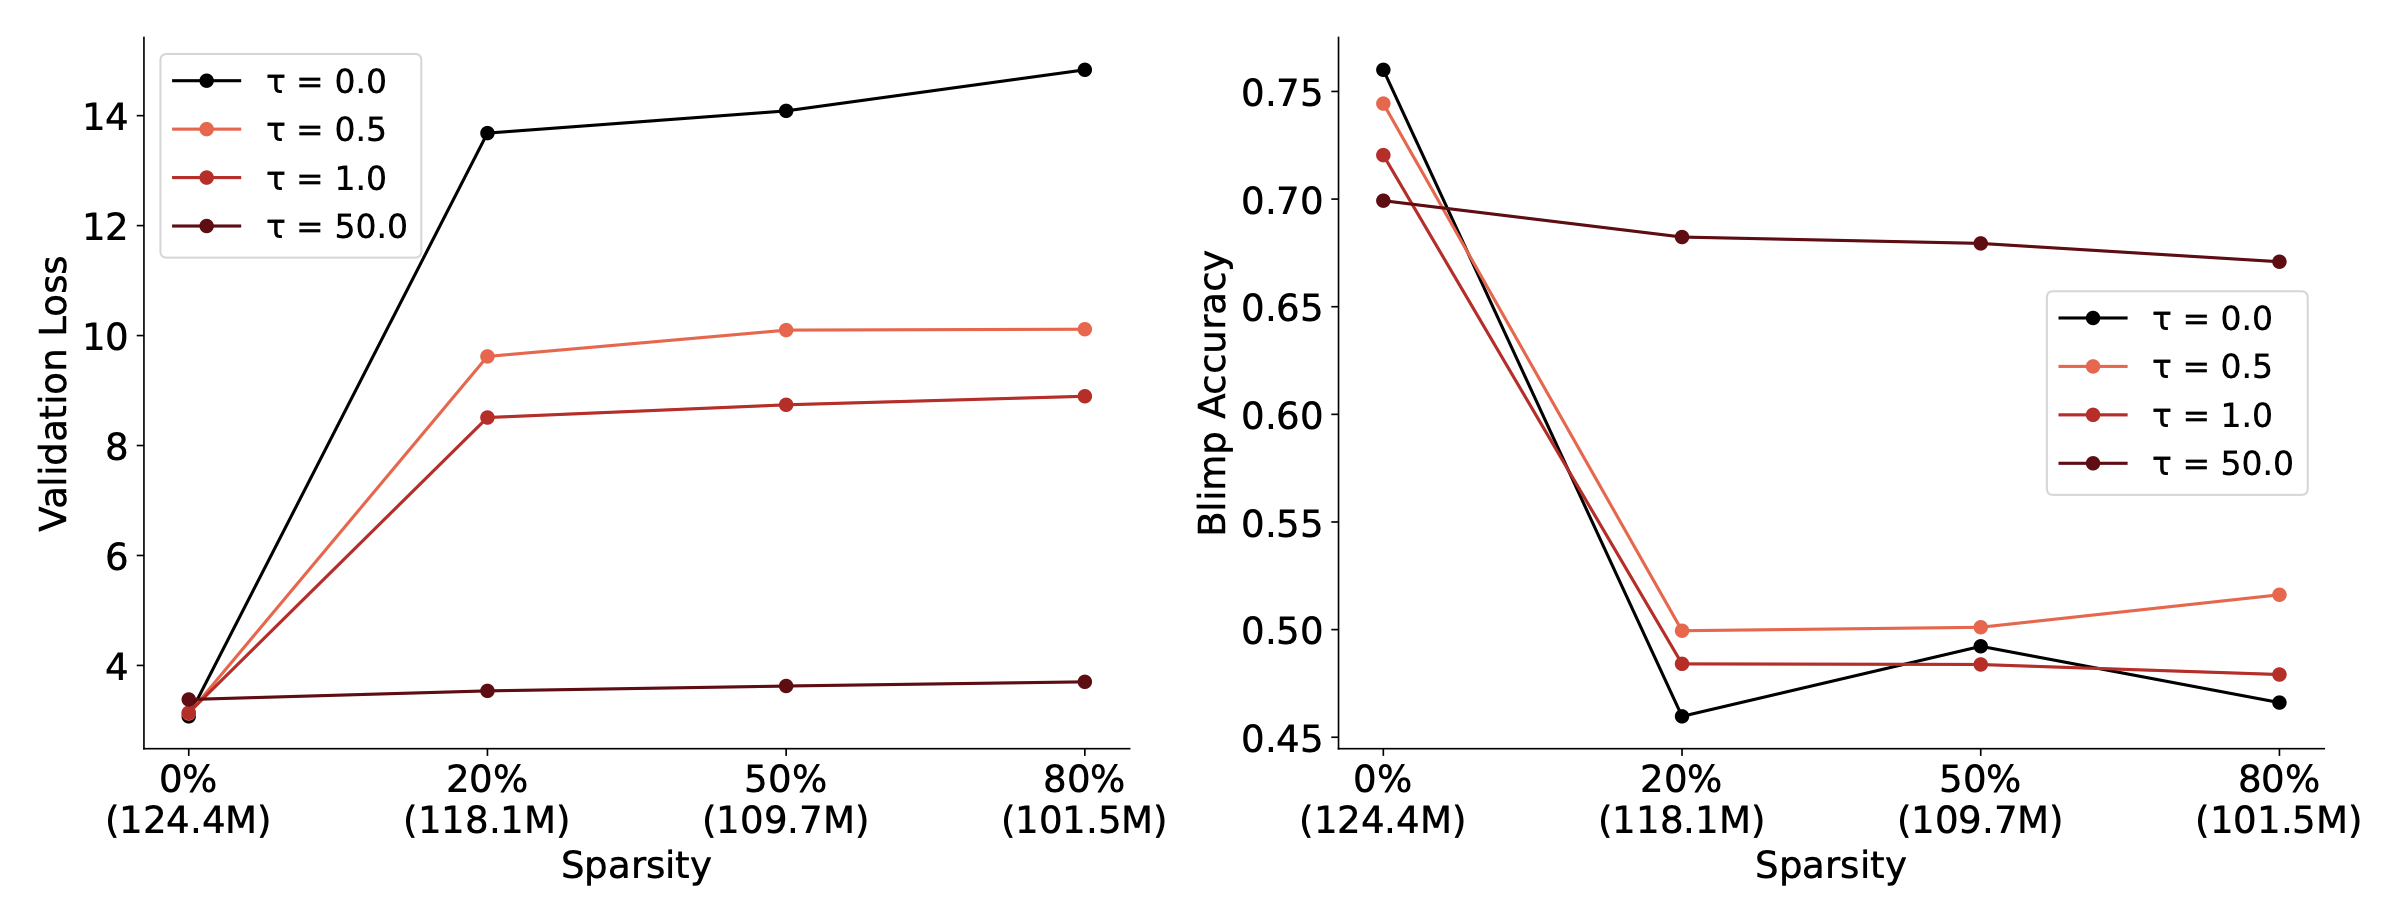
You can find more details on the website: https://toponets.github.io (see section: "Toponets deliver sparse, parameter-efficient language models")
We find out that inducing topographic structure in the weights of GPTs made them compressible (during inference) without losing out on performance.
I encourage you to revert the name if you find it justified after looking into the evidence I've shown here. Thanks.
Even with their new method, models with topography seem to perform worse than models without.