News for hackers. Stuff that matters.
Re:Demystifying GPU Compute Architectures – By Babbage by einpoklum on Tuesday February 06, 2024 @05:30PM (#39281712)
The main problem with GPU architectures is that the manufacturers hide their details from us. Hell, they don't even document the instruction sets! At least NVIDIA doesn't. And they often don't tell us what the hardware actually _does_, and rather offer a mental model of how we can think about it.

Specifically, those structural diagrams of functional-units within SM's you see in the blog post? That comes from NVIDIA. And they explicitly state that they do _not_ guarantee that this is what the hardware is actually like. The hardware works "as-if" it were made up of this kind of units. And even more specifically - it's not clear whether there even is such a thing as a "tensor core", or whether it's just some hack for doing lower-precision FP math somewhat faster.

-----

Anyway, if the architectures weren't mostly _hidden_, we would make them far less mysterious within a rather short period of time.

Re:Demystifying GPU Compute Architectures – By Babbage by wolletd on Tuesday February 06, 2024 @05:45PM (#39281898)
Just to be fair: as also stated at the beginning of the post, CPUs are far more complex nowadays than they represent themselves to the outside.

They don't work like a von-Neumann machine, they act like one. Granted, we know a lot more about the inner workings of modern CPUs thn GPUs, but a lot of real-life work still assumes that the CPU works "as-if" it was a computer from the 70s, just really, really fast.

Re:Demystifying GPU Compute Architectures – By Babbage by WithinReason on Wednesday February 07, 2024 @03:59AM (#39286165)
A lot of effort goes into CPU design to ensure you don't have to care, unlike GPUs.
Re:Demystifying GPU Compute Architectures – By Babbage by amelius on Wednesday February 07, 2024 @04:40AM (#39286469)
Is that really a smart choice, given that we have compilers that can deal with the gory details?
Re:Demystifying GPU Compute Architectures – By Babbage by myrmidon on Wednesday February 07, 2024 @07:34AM (#39287775)
Relying on the compiler to compensate for an unwieldy instruction set architecture is something that was tried explicitly with the Intel Itanium and failed hard.

\rant I feel that generally people often have a notion of the "compiler is unbeatable at optimizing", which is completely false: You can always start from compiler output when optimizing and you often have easy options that are inaccessible for the compiler because of language semantics/calling conventions etc. (=> but hand optimizing at instruction level is time consuming, time is expensive, and what the compiler does is basically free ;).

Re:Demystifying GPU Compute Architectures – By Babbage by WithinReason on Wednesday February 07, 2024 @10:30AM (#39289724)
Compilers can absolutely not deal with the complexity of GPUs.
Re:Demystifying GPU Compute Architectures – By Babbage by dist-epoch on Tuesday February 06, 2024 @05:47PM (#39281919)
GPU instructions sets change every year/generation.

Your software would not run next year if you directly targeted the instruction set.

NVIDIA does document their PTX instruction set (a level above what the hardware actually runs):

https://docs.nvidia.com/cuda/parallel-thread-execution/index...

Re:Demystifying GPU Compute Architectures – By Babbage by Xeamek on Tuesday February 06, 2024 @05:51PM (#39281977)
...But literally the exact same is the case for CPUs and yet we do have public and constant instruction set for decades now?

Altough ofcourse CPU's instruction are also just a frontend api that behind the scenes is implemented using microcode, which probably is much less stable.

But the point is, if we could move one level 'closer' on gpus, just like we have it on cpus, it would stop the big buisness gate-keeping that exsists when it comes to current day GPU apis/libraries

Re:Demystifying GPU Compute Architectures – By Babbage by fancyfredbot on Tuesday February 06, 2024 @06:05PM (#39282117)
PTX is more or less the same as x86. What's even better is that unlike x86, Nvidia allows you to see and step through the SASS instructions which PTX compiles into. Although SASS is not documented, seeing it alongside the PTX makes it possible to infer the meaning. In contrast to this you can't see the micro-ops running on x86 cpus (although people have inferred quite a lot about them).
Re:Demystifying GPU Compute Architectures – By Babbage by dist-epoch on Tuesday February 06, 2024 @05:57PM (#39282039)
That's not true, you can run a 30 years old binary on modern CPUs. The machine code you feed to the CPU didn't change much.

That's not true for GPUs, the machine code changes very frequently. You feed your "binary" (PTX, ...) to the driver, and the driver compiles it to the actual machine code of your actual GPU.

Re:Demystifying GPU Compute Architectures – By Babbage by Xeamek on Tuesday February 06, 2024 @06:17PM (#39282246)
But that's not inherent due to gpus completely revolutionizing their aproach every generation, is it?

The main difference is that with cpu, the translation unit is hidden inside the cpu itself. With gpus, the translation is moved from the device to the driver.

Old openGL code also will run in card that is newer then code itself.

The only difference is that with the cpus, it's open standard what is the instruction set, while on gpus, instruction sets are defined by third parties (DX12,Vulkan,OpenGL) while it falls to nvidia to implement them.

Re:Demystifying GPU Compute Architectures – By Babbage by dist-epoch on Tuesday February 06, 2024 @07:13PM (#39282805)
OpenGL code is actually running on the CPU. From this CPU running code you can send shaders to the driver, in source code form or bytecode form, and the driver does the final compilation to GPU machine code.
Re:Demystifying GPU Compute Architectures – By Babbage by Xeamek on Tuesday February 06, 2024 @08:16PM (#39283260)
Pedantry. Yes you are running your code on the cpu, but you are using opengl defined api to do so. Having a text generation and parsing, or having a function calls passed to/from drivers- those a simply implementation details
Re:Demystifying GPU Compute Architectures – By Babbage by toasterlovin on Wednesday February 07, 2024 @01:16AM (#39285138)
Modern CPUs being able to run 30 year old binaries as-is is pretty different than a GPU requiring a driver to compile byte code into machine code at runtime.
Re:Demystifying GPU Compute Architectures – By Babbage by Xeamek on Wednesday February 07, 2024 @11:16AM (#39290351)
How is that different?
Re:Demystifying GPU Compute Architectures – By Babbage by toasterlovin on Wednesday February 07, 2024 @01:38PM (#39292397)
You seem like you're being purposefully obtuse about this, so I'm going to disengage after this. But, generally speaking, a programming language which compiles to machine code which is executed directly by the CPU is widely considered to have a significantly different architecture than one which is compiled to byte code to be executed by a virtual machine. This architectural choice has many downstream ramifications. And the difference in execution model between CPUs and GPUs is similar in nature and comes with similar ramifications. Such as, for example, operating system support for GPUs.
Re:Demystifying GPU Compute Architectures – By Babbage by Xeamek on Wednesday February 07, 2024 @08:08PM (#39296568)
Being obtuse is when you don't accept currently popular bounds of abstractions are God given axioms.
Re:Demystifying GPU Compute Architectures – By Babbage by einpoklum on Tuesday February 06, 2024 @06:27PM (#39282352)
> GPU instructions sets change every year/generation.

1. It's every two-to-three years.

2. It's not like they change into something completely different.

3. PTX is not a hardware instruction set, it's just an LLVM IR variant

4. I don't need to only target an instruction set directly, but it does help to know what instructions the hardware actually executes. And this is just like for CPUs (ok, not just like, because CPUs have u-ops, and I don't know that GPUs have those).

Re:Demystifying GPU Compute Architectures – By Babbage by dist-epoch on Tuesday February 06, 2024 @07:04PM (#39282722)
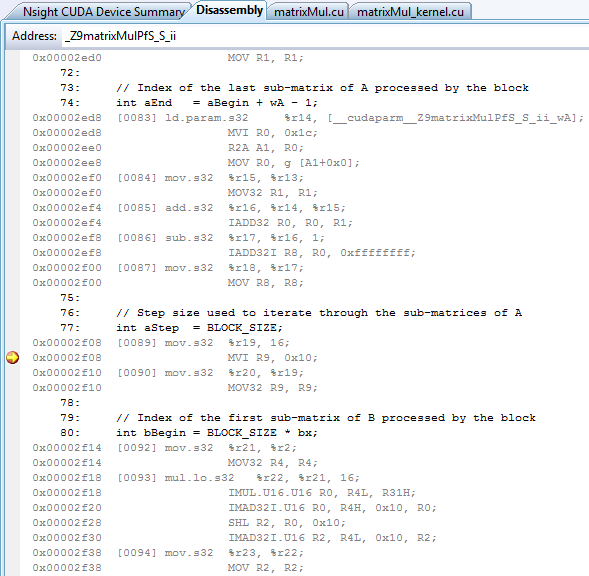
4. The actual instruction set is called SASS. You can view it with Nsight, which can show all 3 levels, CUDA+PTX+SASS:

https://docs.nvidia.com/nsight-visual-studio-edition/3.2/Con...
Re:Demystifying GPU Compute Architectures – By Babbage by einpoklum on Tuesday February 06, 2024 @07:28PM (#39282928)
You can view it, but there's no documentation for it, nor a listing of all instructions. You need to guess what the instructions actually do. Sometimes it's not so difficult, like IADD3; but sometimes it's not at all trivial.
Re:Demystifying GPU Compute Architectures – By Babbage by av3csr on Wednesday February 07, 2024 @01:07AM (#39285086)
The only "documentation" we have is in the form of the binary utility docs, which has a list of SASS instructions

https://docs.nvidia.com/cuda/cuda-binary-utilities/index.htm...

though there is no guarantee this is exhaustive, no opcodes either (though you could reverse engineer it using cuobjdump -sass and a hex editing like I've been doing). I'm pretty sure some of the instructions in the list are deprecated as well (95% percent sure that PMTRIG does nothing >Volta)

Re:Demystifying GPU Compute Architectures – By Babbage by refulgentis on Tuesday February 06, 2024 @09:44PM (#39283840)
4 hours after posting, this is currently the second comment.

The first comment assures me "NVIDIA are really keen you understand their hardware, to the extent they will give you insanely detailed tutorials on things like avoiding shared memory bank conflicts."

I don't know who to believe!

Re:Demystifying GPU Compute Architectures – By Babbage by einpoklum on Wednesday February 07, 2024 @03:30PM (#39293873)
I'd say NVIDIA is somewhat keen on you being able to utilize their hardware. So, they gave you some tutorials (absolutely not insanely detailed), documentation about the API, and a bunch of programming advice and recommendations. They also provide you with a mental model you could use to think about the GPU's work. But - that is all not the same as telling you what actually happens. They don't even publish instruction latency formulae, for example.
Re:Demystifying GPU Compute Architectures – By Babbage by atq2119 on Tuesday February 06, 2024 @10:12PM (#39284002)
On the claim that instruction sets are undocumented: https://gpuopen.com/amd-isa-documentation/

Of course this doesn't apply to Nvidia, but MI-300 seems to be pretty viable for machine learning, so if you want things to change across the industry, more people need to put their money where their mouths are.

Re:Demystifying GPU Compute Architectures – By Babbage by Arelius on Wednesday February 07, 2024 @12:02AM (#39284698)
Indeed, Nvidia has been awful about sharing documentation. The best docs I know of out Nvidia, are actually provided by Nintendo. AMD on the otherhand, while is far from perfect, does try to provide documentation.

CDNA docs, for instance: https://www.amd.com/content/dam/amd/en/documents/instinct-te...