Here's some info about M1 memory bandwidth: https://www.anandtech.com/show/17024/apple-m1-max-performanc...
On the contrary, a 3080 laptop does reach 400GB/s, I'm personally seeing this routinely on AI workloads, so that's part of the explanation for subpar perf here (the other ones being probably matrix math and mixed precision)
A6000 is ~$5k per card. I guess you're referring to something like an A100 on that other spec, which is $10k/card (for 40GB of memory).
I do a fair bit of neural/AI art experimentation, where memory on the execution side is sometimes a limiting factor for me. I'm not training models, I'm not a hardcore researcher--those folks will absolutely be using NVIDIA's high-end stuff or TPU pods.
128GB in a Studio is super compelling if it means I can up-res some of my pieces without needing to use high-memory-but-super-slow CPU cloud VMs, or hope I get lucky with an A100 on Colab (or just pay for a GPU VM).
I have a 128GB/Ultra Studio in my office now. It's a great piece of kit, and a big reason I splurged on it--okay, maybe "excuse"--was that I expect it'll be useful for a lot of my side project workloads over the next couple of years...
Only the workflow is the custom part--the core here is literally the original jcjohnson implementation. Occasionally I look around at recent work in the area, but most seems focused on fast (video-speed) inference or pre-baked style models. I've never seen something that retains artistic flexibility.
My original gut feeling on style transfer was that it would be possible to mold it into a neat tool, but most people bumped into it, ran their profile photo against Starry Night, said "cool" and bounced off. And I get that--parameter tuning can be a sloooow process. When I really explore a series with a particular style I start to feed it custom content images made just for how it's reacting with various inputs.
Here's a piece that just finished a few minutes ago: https://mwegner.com/misc/styled_render-BMrHXWz_2RBaUq8pAYKfL...
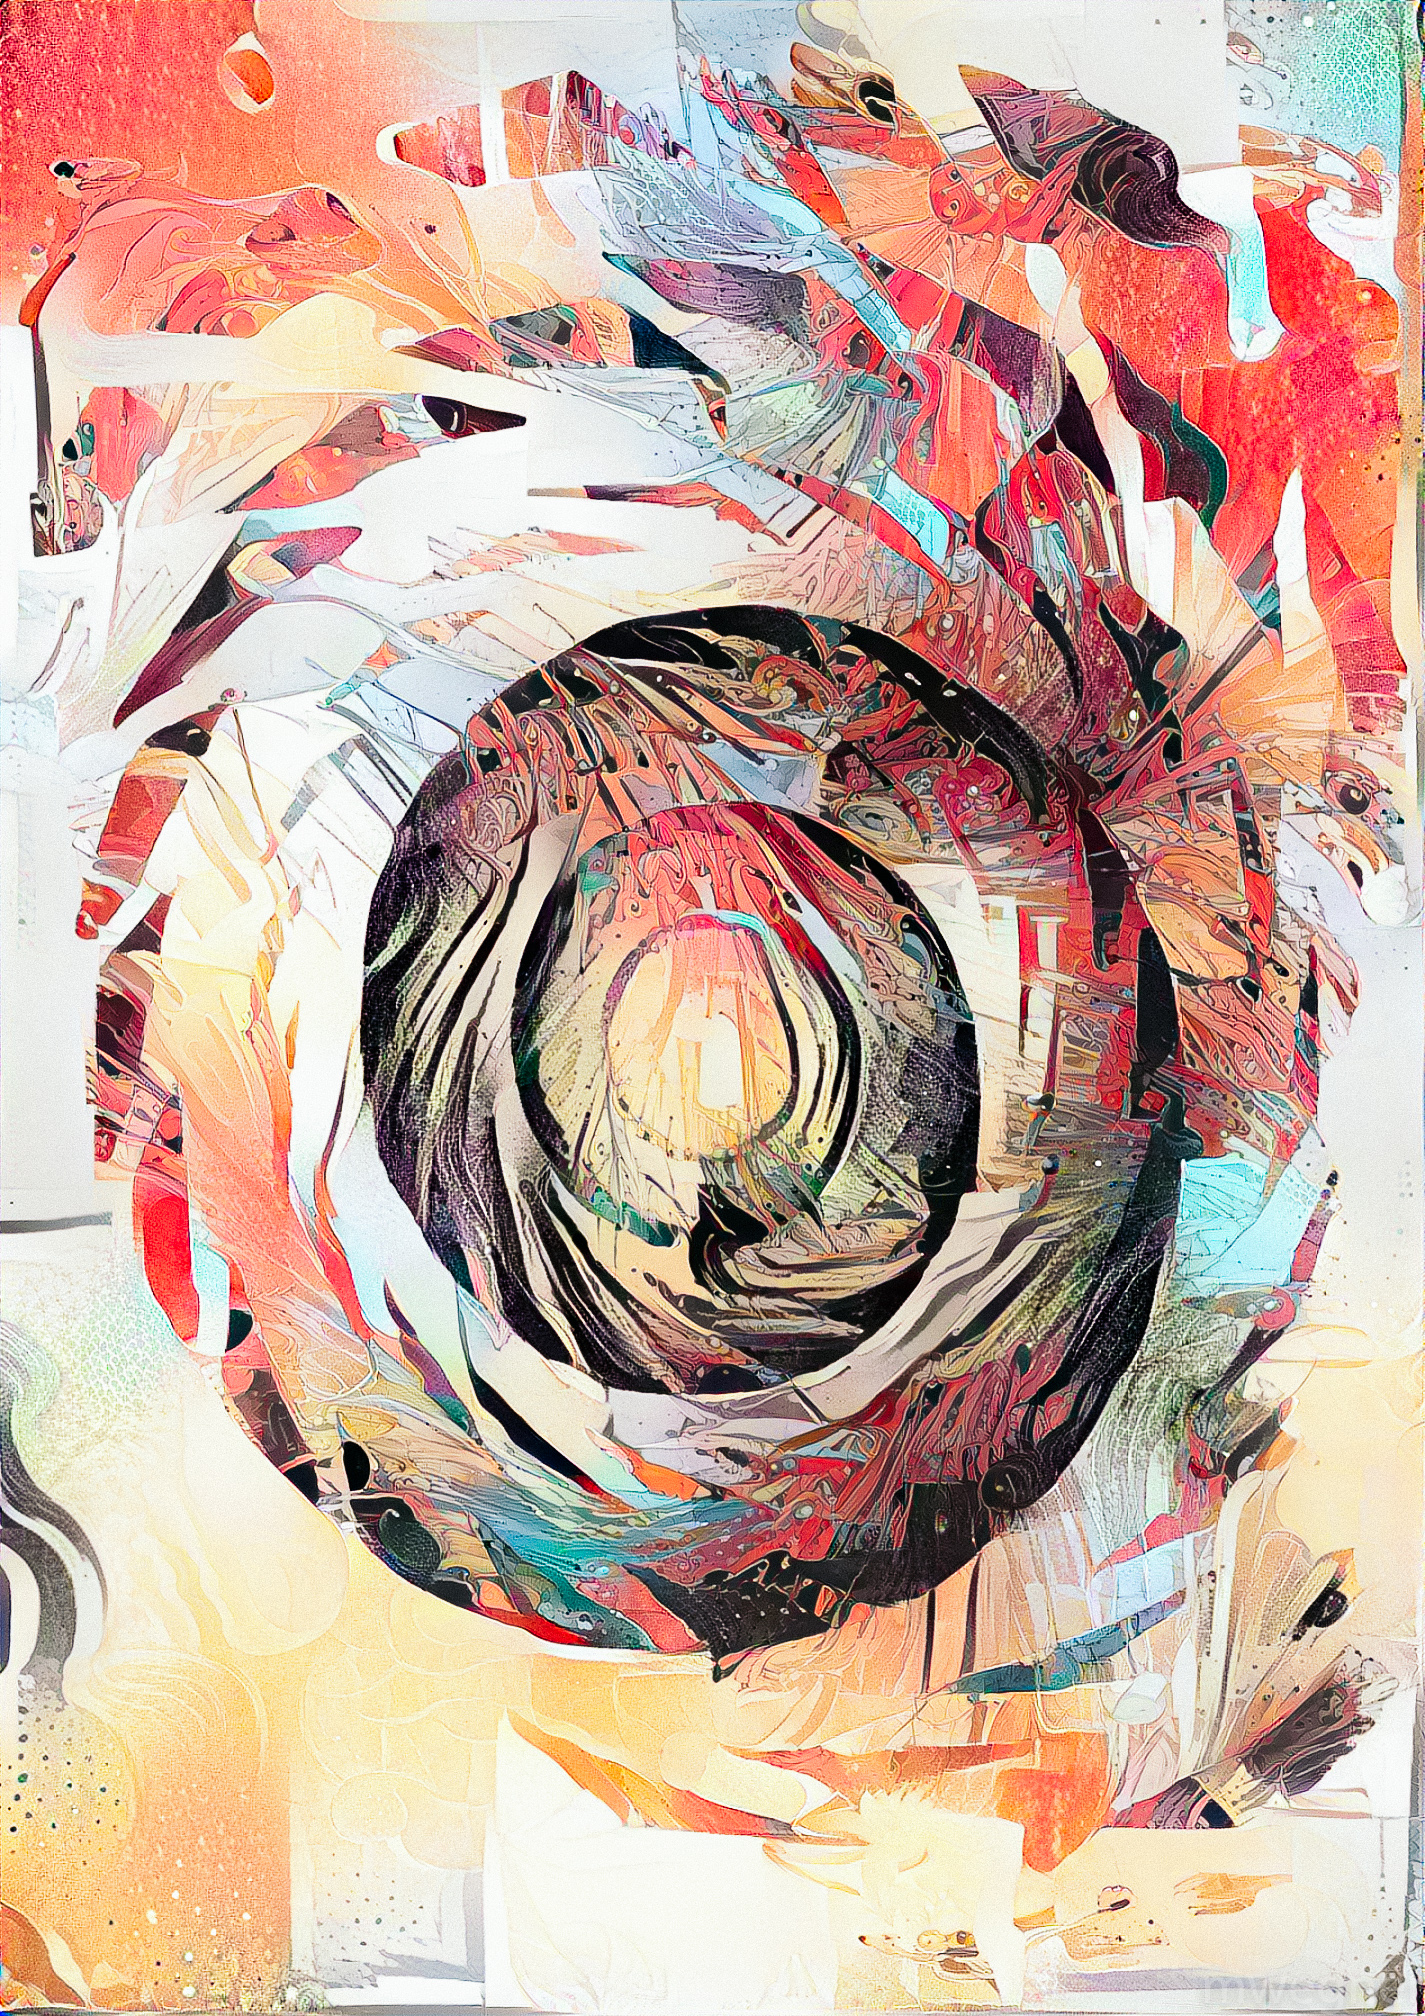
That's from a local server in my garage with a K80. At some point I had two K80s in there (so basically four K40s with how they work), but dialed it back for power consumption/power reasons.
I do have a 3090 in the house, and a decent amount of cloud infra that I sometimes tap. The jcjohnson implementation is so far back that it doesn't even run against modern hardware. At some point I need to sort that out, or figure out how to wrangle a more modern implementation into behaving in the way that I like.
I don't really post these anywhere, although do throw them over the wall on Twitter if anyone is curious to see more. These are a mix of things, although the CLIP/Midjourney/etc stuff is pretty easy to spot: https://twitter.com/mwegner/media
As for 128GB memory on-inference models that a consumer would be interested in, I got nothing, though it certainly seems like it would be fun to mess around with haha
Apple is simply behind in the GPU space.
> At $4800, an M1 Ultra Mac Studio appears to be far and away the cheapest machine you can buy with 128GB of GPU memory. With proper PyTorch support, we'll actually be able to use this memory for training big models or using big batch sizes. For the kind of DL work I do where dataloading is much more of a bottleneck than actual raw compute power, Mac Studio is now looking very enticing.
The reason why it's cheaper is that its memory is at a fraction (around 20-35%) of the memory bandwidth of a 128GB equivalent GPU set up, which also has to be split with the CPU. This is an unavoidable bottleneck of shared memory systems, and for a great many applications this is a terminal performance bottleneck.
That's the reason you don't have a GPU with 128GB of normal DDR5. It would just be quite limited. Perhaps for some cases it can be useful.