At a first approximation, Haskell pretends the world is a piece of state, not a pure function.
Mercury literally pretends the world is a piece of state. You explicitly say "Here, run this code. The world before it runs is on variable `a`, place the world after it runs on variable `b`".
Can you elaborate on what those flaws are?
Personally, I wonder if uniqueness types in languages like the sadly forgotten Clean (a close relative of Haskell) would have been better than the whole Monad/Arrow thing. All of that abstract theoretical stuff is certainly fascinating but it's never seemed worth all the bother to me.
On the other hand, in SML you get all the benefits of strong HM type inference/checking, immutability by default, etc, etc.. while also still being able to just `print` something or modify arrays in place. SML's type system isn't higher-order like Haskell's so its solution to the same problem Haskell solves with type classes isn't quite as elegant but otherwise SML is the C to Haskell's C++.
- Monad is just an interface (with nice do-notation, to be sure), but it's elevated to an almost mythic status. This (a) causes Monad to be used in places which would be better without (e.g. we could be more generic, like using Applicative; or more concrete by sticking to IO or Maybe, etc.) and (b) puts off new comers to the language, thinking they need to learn category theory or whatever. For this reason, I try to avoid phrases like "the IO monad" or "the Maybe monad" unless I'm specifically talking about their monadic join operation (just like I wouldn't talk about "the List monad" when discussing, say, string splitting)
- They don't compose. Monad on its own is a nice little abstraction, but it forces a tradeoff between narrowing down the scope of effects (e.g. with specific types like 'Stdin a', 'Stdout a', 'InEnv a', 'GenRec a', 'WithClock a', 'Random a', etc.) and avoiding the complexity of plugging all of those together. The listed advantages of SML are essentially one end of this spectrum: avoiding the complexity by ignoring the scope of effects; similar to sticking with the 'IO a' type in Haskell (although even there, it's nice that Haskell lets us distinguish between pure functions and effectful actions).
Haskell has some standard solutions to composing narrowly-scoped effects, like mtl, but I find them to be a complicated workaround to a self-imposed problem, rather than anything elegant. I still hold out some hope that algebraic effect systems can avoid this tradeoff, but retro-fitting them into a language can bring back the complexity they're supposed to avoid (e.g. I've really enjoyed using Haskell's polysemy library, but it requires a bunch of boilerplate, restrictions on variable names and TemplateHaskell shenanigans to work nicely).
The ironic thing is that these algabraic effect systems have a feel/control flow pattern that's quite similar to exception handling from the OO languages or interrupt handlers in low-level code.
It's much easier to just say "this piece of code is impure, it may do X, Y, and Z and if so then ..." than to try and shove everything ad-hoc into the abstract math tree. But then you lose the purity of your language and it's really awkward in a language whose primary concern is purity. That may be a reason why algebraic effects seem a bit more natural in OCaml.
Ignoring maths that underlie computation when writing software is like ignoring math that underlies mechanics when building houses: for some time you can get by, but bigger houses will tend to constantly fall or stand a bit askew, and the first woodpecker to fly by would ruin the civilization, just as the saying goes.
Uniqueness types were a nice idea indeed. I suspect linear types (or their derivative in Rust) do a very similar thing: data are shared XOR mutable.
Analogy to monads is this: yes, there are mathematical formalisms that can describe complex systems. Everything can be described by math! That’s literally its one job. But will the formalisms actually help you when the job you’re doing has insufficient achievable precision (eg finding market fit for a website)?
Writing code is a much more precise activity that cutting wood. Using "cheats" can get you somewhere, but due to the precise nature of the machine logic, the contraption is guaranteed to bend and break where it does not precisely fit, and shaving off the offending 1/8" is usually not easy, even if possible.
In my experience, this is exactly the problem Haskell's core abstractions—monads among them—help with!
What do you need when you're trying to find product-market fit? Fast iteration. What do Haskell's type system and effect tracking (ie monads) help with? Making changes to your code quickly and with confidence.
Haskell provides simple mathematically inspired tools that:
1. Make clean, well-factored code the path of least resistance.
2. Provide high-level, reusable libraries that keep your code expressive and easy to read at a glance despite the static types and effect tracking.
3. Give you guardrails to change your code in systematic ways that you know will not break the logic in a wide range of ways.
If I had a problem where I'd need to go through dozens of iterations before finding a good solution—and if libraries were not a consideration—I would choose Haskell over, say, Python any day. And I say this as someone who writes a lot of Python professionally these days. (Curse library availability!)
Honestly, Haskell has a reputation of providing really complicated tools that make your code really safe—and I think that's totally backwards. Haskell isn't safe in the sense that you would want for, say, aeronautical applications; Haskell programs can go wrong in a lot of ways that you can't prevent without extensive testing or formal verification and, in practice, Haskell isn't substantially easier to formally verify than other languages. And, on the flipside, Haskell's abstractions really aren't complicated, they're just different (and abstract). Monads aren't interesting because they do a lot; they're interesting because they only do a pretty small amount in a way that captures repeating patterns across a really wide range of types that we work with all the time (from promises to lists to nullable values).
Instead, what Haskell does is provide simple tools that do a "pretty good" job of catching common errors, the kind of bugs that waste a lot of testing and debugging time in run-of-the-mill Python codebases. This makes iteration faster rather than slower because you get feedback on whole classes of bugs immediately from your code, without needing to catch the bug in your tests or spot the bug in production.
Knowing a little bit of maths, but not much category theory, the wiki entry for Monads(Category Theory) is pretty clear. First sentence: A Monad is an endofunctor (a functor mapping a category to itself), together with two natural transformations required to fulfill certain coherence conditions. Easy.
Knowing a bit of programming, but not much Haskell, reading the entry for Monad (functional programming) or any blog post titled "A Monad is like a ...", it almost seems as if the author is more confused about what a Monad is than me. The first sentences of the Wikipedia article for example are a word-salad. With dressing.
From an outsider's perspective, it's almost as if a monad in functional programming is not a 1:1 translation of the straightforward definition of category theory, leading to an overall sense of confusion.
The formal definitions are straightforward enough, but the definitions alone don't really motivate themselves. A lot of mathematical maturity is about recognizing that a good definition gives a lot more than is immediately apparent. Someone without that experience will want to fully understand the definition, and fairly so -- but a plain reading defies that understanding. That is objectively frustrating.
> As a bit of an aside, it's interesting that the CS (Haskell, mainly) descriptions of a Monad are much more complicated than the math.
I actually do agree with this, though. I feel like monads are much simpler when presented via "join" (aka "flatten") rather than "bind"; and likewise with applicative functors via monoidal product (which I call "par") rather than "ap". "bind" and "ap" are really compounds of "join" and "par" with the underlying functorial "map". That makes them syntactically convenient, but pedagogically they're a bit of a nightmare. It's a lot easier to think about a structural change than applying some arbitrary computation.
Let's assume the reader knows abut "map". Examples abound; it's really not hard to find a huge number of functors in the wild, even in imperative programs. In short, "map" lets us take one value to another, within some context.
Applicative functors let us take two values, `f a` and `f b`, and produce a single `f (a, b)`. In other words, if we have two values in separate contexts (of the same kind), we can merge them together if the context is applicative.
Monads let us take a value `f (f a)` and produce an `f a`. In other words, if we have a value in a context in a context, we can merge the two contexts together.
Applicative "ap", `f (a -> b) -> f a -> f b`, is "par" followed by "map". We merge `(f (a -> b), f a)` to get `f (a -> b, a)`, then map over the pair and apply the function to its argument.
Monadic "bind", `(a -> f b) -> f a -> f b`, is "map" followed by "flatten". We map the given function over `f a` to get an `f (f b)`, then flatten to get our final `f b`.
It's a lot easier to think about these things when you don't have a higher-order function argument being thrown around.
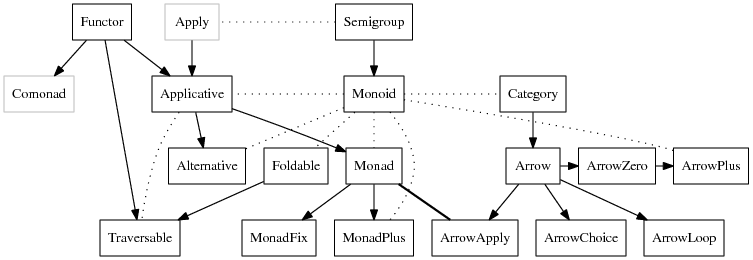
[0] https://wiki.haskell.org/wikiupload/d/df/Typeclassopedia-dia...
It's used pervasively in low-level code because the idealism of monads just doesn't cut it. In my opinion, this proves that the pragmatism of side effects is a necessary evil for actually getting things done in a performant way.
Lazy evaluation has the same kind of issues. Most humans don't think that way, so performance suffers. This may be a universal problem as in my experience, Haskell doesn't have good tooling to help with this issue.
Always immutable is another large issue. Yes, there's a ton of safety in immutability and it's the right tool for MOST code. Compilers aren't prefect and there seem to be an endless stream of situations where the compiler can't figure out if it is safe to mutate "immutable" data to gain performance. For the foreseeable future, the ability to mutate can have huge performance dividends.
Finally, Haskell and it's libraries are prone to rather academic programming styles and techniques. These are amazing and beautiful. They also can be hard to grep even if you know the math. When you consider that the overwhelming majority of programmers don't know the math, it seems plain that these constructs are a detriment to pragmatic, non-academic usage.
> It's used pervasively in low-level code because the idealism of monads just doesn't cut it. In my opinion, this proves that the pragmatism of side effects is a necessary evil for actually getting things done in a performant way.
It seems like you aren't very familiar with the ways Haskell programmers deal with side effects and mutation. UnsafePerformIo is sometimes needed, and there are a few common idiomatic ways to use it, but there are usually better options. What at first looks like an impenetrable wall between the IO monad and pure code is actually surprisingly permeable, just not (usually) in ways that violate expected semantics. For instance, you can read a file into a string in the IO monad and pass the string into pure code to process it. The string is lazy, so the pure code actually triggers the file to be read as it's consumed.
Another escape hatch is the ST Monad. It allows you to run imperative computations (i.e. use mutable variables and arrays) within pure code. Since the ST computations are deterministic, they don't violate any important guarantees about pure code. You can't read and write files from the ST Monad, but if you want to do array-based quicksort or something similar it's available.
Some aspects of Haskell are hard to work with. You're right that laziness introduced some performance issues that can be tedious to fix, and some of the libraries are hard to use. However, it's a perfectly reasonable tool for many general-purpose programming applications. It's not a replacement for C, but you could say the same thing about C# or Java or any other language with a garbage collector.
(edit: fixed grammar typo)
On the other hand, in a program that handles a small number of files and doesn't live long after file access anyway (say a small script to do grab a couple things, crunch a few numbers, and throw the result at pandoc), there's nothing wrong with lazy IO and it can be quite convenient.
    {-# LANGUAGE OverloadedStrings #-}
    import qualified Data.ByteString.Lazy.Char8 as BS

    main = BS.interact go

    go :: BS.ByteString -> BS.ByteString
    go input = -- Generate output here
    main = interact go

    go :: String -> String
go input = -- Generate output hereAnyways, the problem is that you might open a file, read it into a string, close the file, and then pass the string into some pure function. The problem is that the file was closed before it was lazily read, and so the string contents don't get populated correctly; you get the empty string instead, or whatever was lazily read before the file was closed.
That was a design oversight from the early days. If you know about it, it's pretty easy to work around it in simple applications. There are some more modern libraries for doing file IO in a safer way, but I haven't used them and don't really know what the details are.
https://existentialtype.wordpress.com/2011/05/01/of-course-m...
The module systems have some small differences, but are very similar (I believe OCaml's was inspired by SML's).
Standard ML is also standardized (hence the name), and there are multiple implementations, whereas OCaml is basically defined by its single implementation.
But OCaml does have a larger ecosystem, Opam, more features (first-class modules, polymorphic variants, etc.).
I used it, just for fun, in a static site generator. That was fun and worked great.
Rust's performance is almost certainly much better, with a larger library ecosystem.
(Common) Lisp has macros, which allow me to implement pattern-matching; an even simpler BNF (as short as one line, depending on how you define it); dynamic typing, which makes generics unnecessary, and for all the hate that it receives is regularly deployed to production systems on large scales; tooling that is almost certainly better than SML's; and a condition system, which beats any other type of error-handling system, bar none (meaning that I can make my programs more robust than yours).
Rust is very much a ml variant. It's all the things you claim and probably more. It's also at least an order of magnitude more complex. If you know rust, you'll probably find SML super easy to learn and refreshingly easy to code.
People gravitating toward SML likely want a few things: easy to learn, simple infix syntax with functional support, compile time type static type checks, multithreaded, very fast without a drastic recode.
Common lisp libraries are better, but not drastically so (well, I've never had 5 grand to throw at lisp works, so I can't comment there). CL is more complex to learn (must people can probably learn the entire SML language in the time it takes to master the loop macro). Macros are powerful, but mean that even if you can find a lisp dev, it'll take a long time for them to learn your custom variant of the language.
CL offers unofficial threading, but last I checked it was much harder than the SML solutions. CL is pretty fast out of the box, but if you ever need peak performance, the code changes a lot and can become very finicky (though CL makes seamlessly hiding those bits easier than most languages). Even at it's most optimized, I don't know that it can match milton in performance or memory usage.
Dynamic vs static typing is a battle that's all but over. When you have devs coming and going on a team, type make transitions easier. Loads of dynamic languages have started adding them and even CL sort of does.
CL has loads of interesting features from well known ones like macros/reader macros or metaobject protocol to less known ones like optional dynamic scoping.
I'm just saying why I enjoy SML (not trying to argue that it's the end all, be all of programming). There are other great languages too. Do what you love.
* Doesn't have macros, which in my 16 years of experience is a plus, macros pollute, should at most be an implementation detail
* Has types
* Doesn't have parantheses and the annoying prefix notation
* Your knowledge of SML can be translated easily to OCaml, Java, Scala, which are more or less part of the same family
SML over Rust:
* I don't have to reason about lifetimes, I'm not in a constrained environment
* TCO (tail call optimization)
* At its core, Rust is still an imperative language, it was influenced by ML but not that much as many believe
SML over Scala:
* It doesn't suffer of Haskellism and Extreme Bipolarity (oop/fp) and gets the job done.
> * Has types
Your words betray your ignorance. Common Lisp has a type system. Have you ever written it? Do you actually know anything about it? Moreover, macros are a plus - you clearly have not actually used Lisp macros, which are categorically different than macros in other languages.
> * Doesn't have parantheses and the annoying prefix notation
Spelling mistake. Additionally, the parenthesized syntax is a choice, and one that you get used to quickly. Subjective, and therefore not valid as one of the items you listed.
> * Your knowledge of SML can be translated easily to OCaml, Java, Scala, which are more or less part of the same family
Meanwhile, knowledge of Common Lisp transfers to almost every dynamically-typed language ever made, and a good many static ones - including Java and Scala - because Lisp influenced all of those languages. That is, Lisp knowledge transfers to far more languages than SML knowledge does.
I don't know if Lisp, the language, influenced Java and Scala so much, it was more about its runtime, the garbage collector, etc. The only thing that I liked about Lisp is the composabiltiy, and coupled with objects from Simula created my favorite industrial languages, Java and TypeScript. I'm passionate about parsers, compilers and transformers and this is why I have a fost spot for SML, OCaml. I simply dislike Lisp, interesting language but not for me.
Can you show me a significant body of literature or a whole community that uses "types" to mean "a strong type system"? Because I've never heard that aliasing done before.
> I don't know if Lisp, the language, influenced Java and Scala so much, it was more about its runtime, the garbage collector, etc.
Lisp pioneered lambdas and first-class functions, in addition to garbage collection, all of which were adopted by Scala and Java later.
> I simply dislike Lisp, interesting language but not for me.
I understand! I have things that I like and dislike, too. However, it's extremely frustrating when you ask for an analytical comparison between several languages, and some random person lacking knowledge on at least one of the languages (I suspect you don't know Rust either) comes in and, instead of actually providing relevant information, gives fallacies and opinions.
In Common Lisp objects are values, so runtime tags are attached to data objects => which are actually values => which are stored in variables => which are not typed.
You can make it optionally typed at compile time to help the compiler but that means to annotate your code with 'type' keyword and it's verbose. The compiler does not enforce it.
This isn't really okay. It's fine if you disagree, but I don't get why such aggression is needed.
The syntax is super-easy to learn (The BNF for the whole fits in a mere 2 pages[0]), but contains a lot of features in that small package. Rather than tacking on functional features (eg, Java with lambdas), these features have been carefully considered and streamlined and include bits like proper tail calls and currying.
You get nice bits like actually sound types (hindley-milner types as Milner was also one of the SML spec authors), generics (way better than typical interfaces), type inference that actually works, and modules (super-powerful encapsulation). Pattern matching in all it's awesomeness is also on display.
SML has an amazing concurrency story (CML is rather like golang channels, but better with better typing and a bit more flexibility) and compilers like PolyML or Mlton are very fast (once again, around the same as golang).
Despite this, the language doesn't have the academic flaws of its descendants like Haskell.
SML isn't a lazy language, so reasoning about performance is much easier than some other functional languages. SML doesn't pretend the world is a pure function. You are free to make functions that have side effects. While most primitives and data structures are immutable by default, they either have mutable variants (eg, vector and array) or can be used as if mutable with refs (something like typesafe pointers without all the reference/dereference bits).
[0] https://cse.buffalo.edu/~regan/cse305/MLBNF.pdf