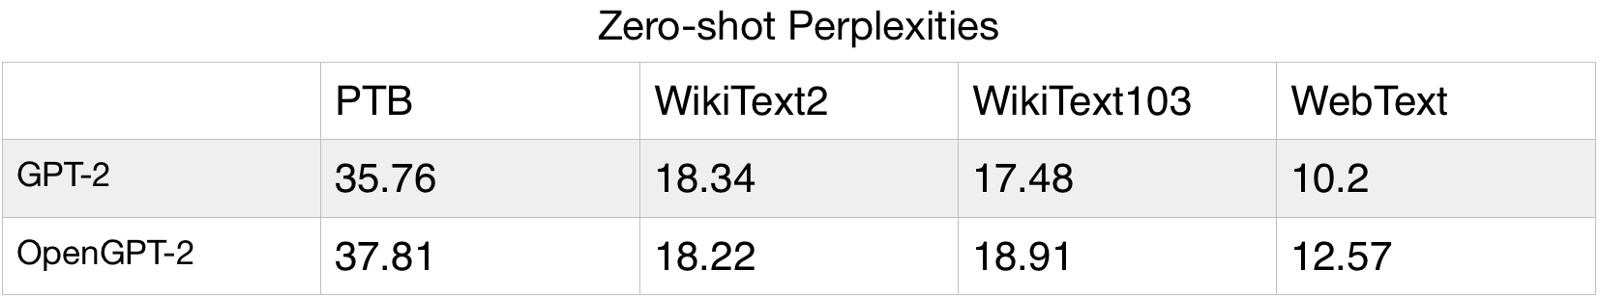
OpenGPT-2's results are near equal to GPT-2's in zero-shot language model perplexity on multiple datasets [1].
The zero shot perplexity results are also exactly where we'd expect the 1.5 billion parameter to be, markedly better than OpenAI's 775M GPT-2 model[2] (the second largest model OpenAI trained) that they released in the last few days.
To me this is about as close a replication as you could expect, especially given OpenAI didn't release many of the exact training details. If OpenAI retrained the 1.5 billion parameter GPT-2 model I wouldn't be surprised to see the same variance in performance simply due to the random initialization of the parameters.
[1]: https://miro.medium.com/max/3200/1*h1JoiQq9f1qOHS-rN4u57A.pn...
[2]: https://www.semanticscholar.org/paper/Language-Models-are-Un...
Between this and the 774M GPT2 release, it's been a pretty good week :)
People who actually do research, they don’t just look at the absolute comparison of published numbers! Do you think that’s how research is done, by chasing whatever has the biggest number? No repeat innovator does that.
It’s an interesting collision of world views for sure. This is a social media forum for a venture capital firm. They’d hate for anyone to discover that the numbers don’t tell the whole story, that actually everybody starts at zero, and that being second, because of the price premium put on first, is a huge opportunity. So even in some narrow, cynical interpretation, your point of view would lose people a ton of money. But I don’t really know anything about that.
It's like if I wrote a paper showing that widgets improve liver health in young men, young women, and adult men. Additionally, widgets make you happy and taller and turn blue. Then you come along and try to replicate my results, showing only that your version of a widget makes young men and women's livers almost as healthy as mine did.
But sure, pretend I said whatever you want to argue against.