willcodeforfoo
Re:Throwaway Apps with Dokku and a Wildcard Domain
on Thursday October 08, 2026 @11:40AM (#50007181)
Author here: I thought I'd write up and share a pattern I've been using lately (especially with Claude code) when spinning up quick apps on Dokku without setting up DNS, GitHub, etc. for each one. Homelabs FTW!
Re:How we configured OpenTelemetry logs in Rails
on Monday August 31, 2026 @08:09PM (#49516372)
Would love to see what people are doing to visualize in Grafana.
Re:Dear people who work at the airport
on Friday August 14, 2026 @10:49AM (#49299453)
Reminds me of a really beautiful song by Nickel Creek, To The Airport: https://genius.com/Nickel-creek-to-the-airport-lyrics
There's a of implicit knowledge in that environment.
Re:Show HN: QUALITY.md – open format/specification, agent skill, and CLI
on Thursday July 02, 2026 @01:19PM (#48764548)
I thought the same about Yaml and Kubernetes/Helm…
MotherDuck Dives
Re:How to think about durable execution
on Friday December 19, 2025 @10:37AM (#46326947)
Unrelated, but gorgeous website!
Re:Show HN: We built an open source, zero webhooks payment processor
on Tuesday November 25, 2025 @01:30PM (#46048987)
I liked it too, reminds me of zed.dev...
Re:Claude Sonnet 4.5
on Monday September 29, 2025 @01:03PM (#45416118)
Re:Darktable 5.0.0 Released
on Tuesday December 31, 2024 @09:08AM (#42558780)
Unrelated, but wondering if anyone here could recommend a Darktable-ish web-based photo organization app, less focused on editing but supporting tagging, starring, etc.?
Re:Visualizing 13M Bluesky users
on Tuesday November 12, 2024 @02:17PM (#42118642)
Love this kind of post! I was surprised to see you really can drink from the firehose:
  brew install websocat
  websocat wss://bsky.network/xrpc/com.atproto.sync.subscribeRepos
Re:What you can get out of a high-quality font
on Tuesday September 10, 2024 @02:52PM (#41504213)
Nothing really to add... other than the type on that page looks gorgeous.
Re:Stapler: I remade a 32 year old classic Macintosh app
on Saturday August 10, 2024 @09:11PM (#41213324)
Nice! Similar to Brett Terpstra's Bunch[1] which has a GUI-less approach.
[1]: https://bunchapp.co/
Re:Show HN: Searchable Kubernetes CSI provider listing
on Monday June 17, 2024 @01:23PM (#40708288)
Hmm, maybe... although that wouldn't help with the aggregating multiple nodes issue, or would require a lot of app-side logic.
In this example, I have 200GB of ephemeral storage available on each node, ideally I'd like something like this:
  node1: /tmp/data1 (200GB free space)
  node2: /tmp/data2 (200GB free space)
  node3: /tmp/data3 (200GB free space)
  node4: /tmp/data4 (200GB free space)
  node5: /tmp/data5 (200GB free space)
Re:Show HN: Searchable Kubernetes CSI provider listing
on Monday June 17, 2024 @08:45AM (#40705050)
Yep! But I don't have access to any block devices on nodes, only the local paths so I'm not sure OpenEBS or Ceph would work...
Re:Show HN: Searchable Kubernetes CSI provider listing
on Sunday June 16, 2024 @06:31PM (#40700665)
Somewhat related: can anyone recommend a simple solution to share each node’s ephemeral disk/“emptyDir” across the cluster? Speed is more important than durability, this is just for a temporary batch job cluster. It’d be ideal if I could stripe across nodes and expose one big volume to all pods (JBOD style)
Re:The USDA's gardening zones shifted, this map shows you what's changed
on Monday May 13, 2024 @10:41AM (#40343896)
Really nice data visualization... PMTiles! https://apps.npr.org/plant-hardiness-garden-map/assets/synce...
Re:Embeddings are a good starting point for the AI curious app developer
on Thursday April 18, 2024 @07:44AM (#40075141)
One thing I'm not sure of is how much of a larger bit of text should go into an embedding? I assume it's a trade off of context and recall, with one word not meaning much semantically, and the whole document being too much to represent with just numbers. Is there a sweet spot (e.g. split by sentence) or am I missing something here?
Re:Hetzner switches to new billing model
on Thursday February 29, 2024 @06:53AM (#39548219)
Last time I checked, Hetzner doesn’t have any dedicated offerings in the US, only cloud, is this still the case?
Re:The drive stats of Backblaze storage pods
on Wednesday January 03, 2024 @02:32PM (#38858650)
Looks like ~3,087 Petabytes of total storage!
Ask HN: Point Set Matching
Can anyone recommend an algorithm that would find a subset of 2D points in a larger set, with outliers. It's a similar problem to the one presented here: https://stackoverflow.com/questions/27823048/good-algorithm-for-finding-subsets-of-point-sets but after all these years I still haven't found a great solution.
Re:Dropbox Axes Unlimited Cloud Storage for Businesses
on Friday August 25, 2023 @01:44PM (#37264705)
As far as I know, even with the recent increase, Backblaze B2 is still the most cost efficient option at $6/TB/mo... but I'll be watching replies closely.
Re:Vector support in PostgreSQL services to power AI-enabled applications
on Saturday July 01, 2023 @06:53PM (#36556163)
Hopefully DigitalOcean follows soon with pgvector support in its hosted offering.
Re:GPT-4 is phenomenal at Code
on Tuesday March 14, 2023 @08:11PM (#35161635)
I wonder if this could be used to port entire projects/libraries to different languages almost completely automatically? ElasticSearch in Rust? Wondering about the legal/license ramifications of doing so...
Re:Ruby 3.2.0 Is from Another Dimension
on Wednesday January 04, 2023 @01:52PM (#34249745)
Just some anecdata but I'm not seeing such dramatic improvements with YJIT, actually in my limited testing it's much slower...
Ruby 3.2.0, on a M1 MacBook Pro hitting a simple healthcheck route in a production Rails 6.1 app with wrk (`wrk -c8 -t8 -d30s http://localhost:3000/healthcheck`):
- 423 reqs/second with JIT disabled (using 229MB of RAM)
- 74 reqs/second running with `RUBYOPT="--yjit"` (using 385 MB of RAM)
I must be doing something wrong?
Re:Bipartisan Legislation to Ban TikTok
on Tuesday December 13, 2022 @03:00PM (#33974840)
> The Averting the National Threat of Internet Surveillance, Oppressive Censorship and Influence, and Algorithmic Learning by the Chinese Communist Party Act (ANTI-SOCIAL CCP Act)
...that actually is a pretty good name.
Re:Just use Postgres for everything
on Saturday December 10, 2022 @07:12PM (#33938497)
I love Postgres as much as the next dev, but why are COUNTs so slow?
Kindle Scribe
Re:Tabler: Free and open source dashboard HTML/CSS framework
on Friday July 29, 2022 @02:08PM (#32280080)
I love Tabler and have used it for a few projects with great success.
The title of the OP is not really accurate though. It's not so much a framework but a bunch of customization on top of Bootstrap and some pre-built templates for stuff _like_ dashboards, galleries, forms, etc. The site is more like a kitchen sink demo and documentation site for stuff you can pick apart and use in your own application.
Re:Installing a payphone in my house
on Friday June 03, 2022 @11:45AM (#31609889)
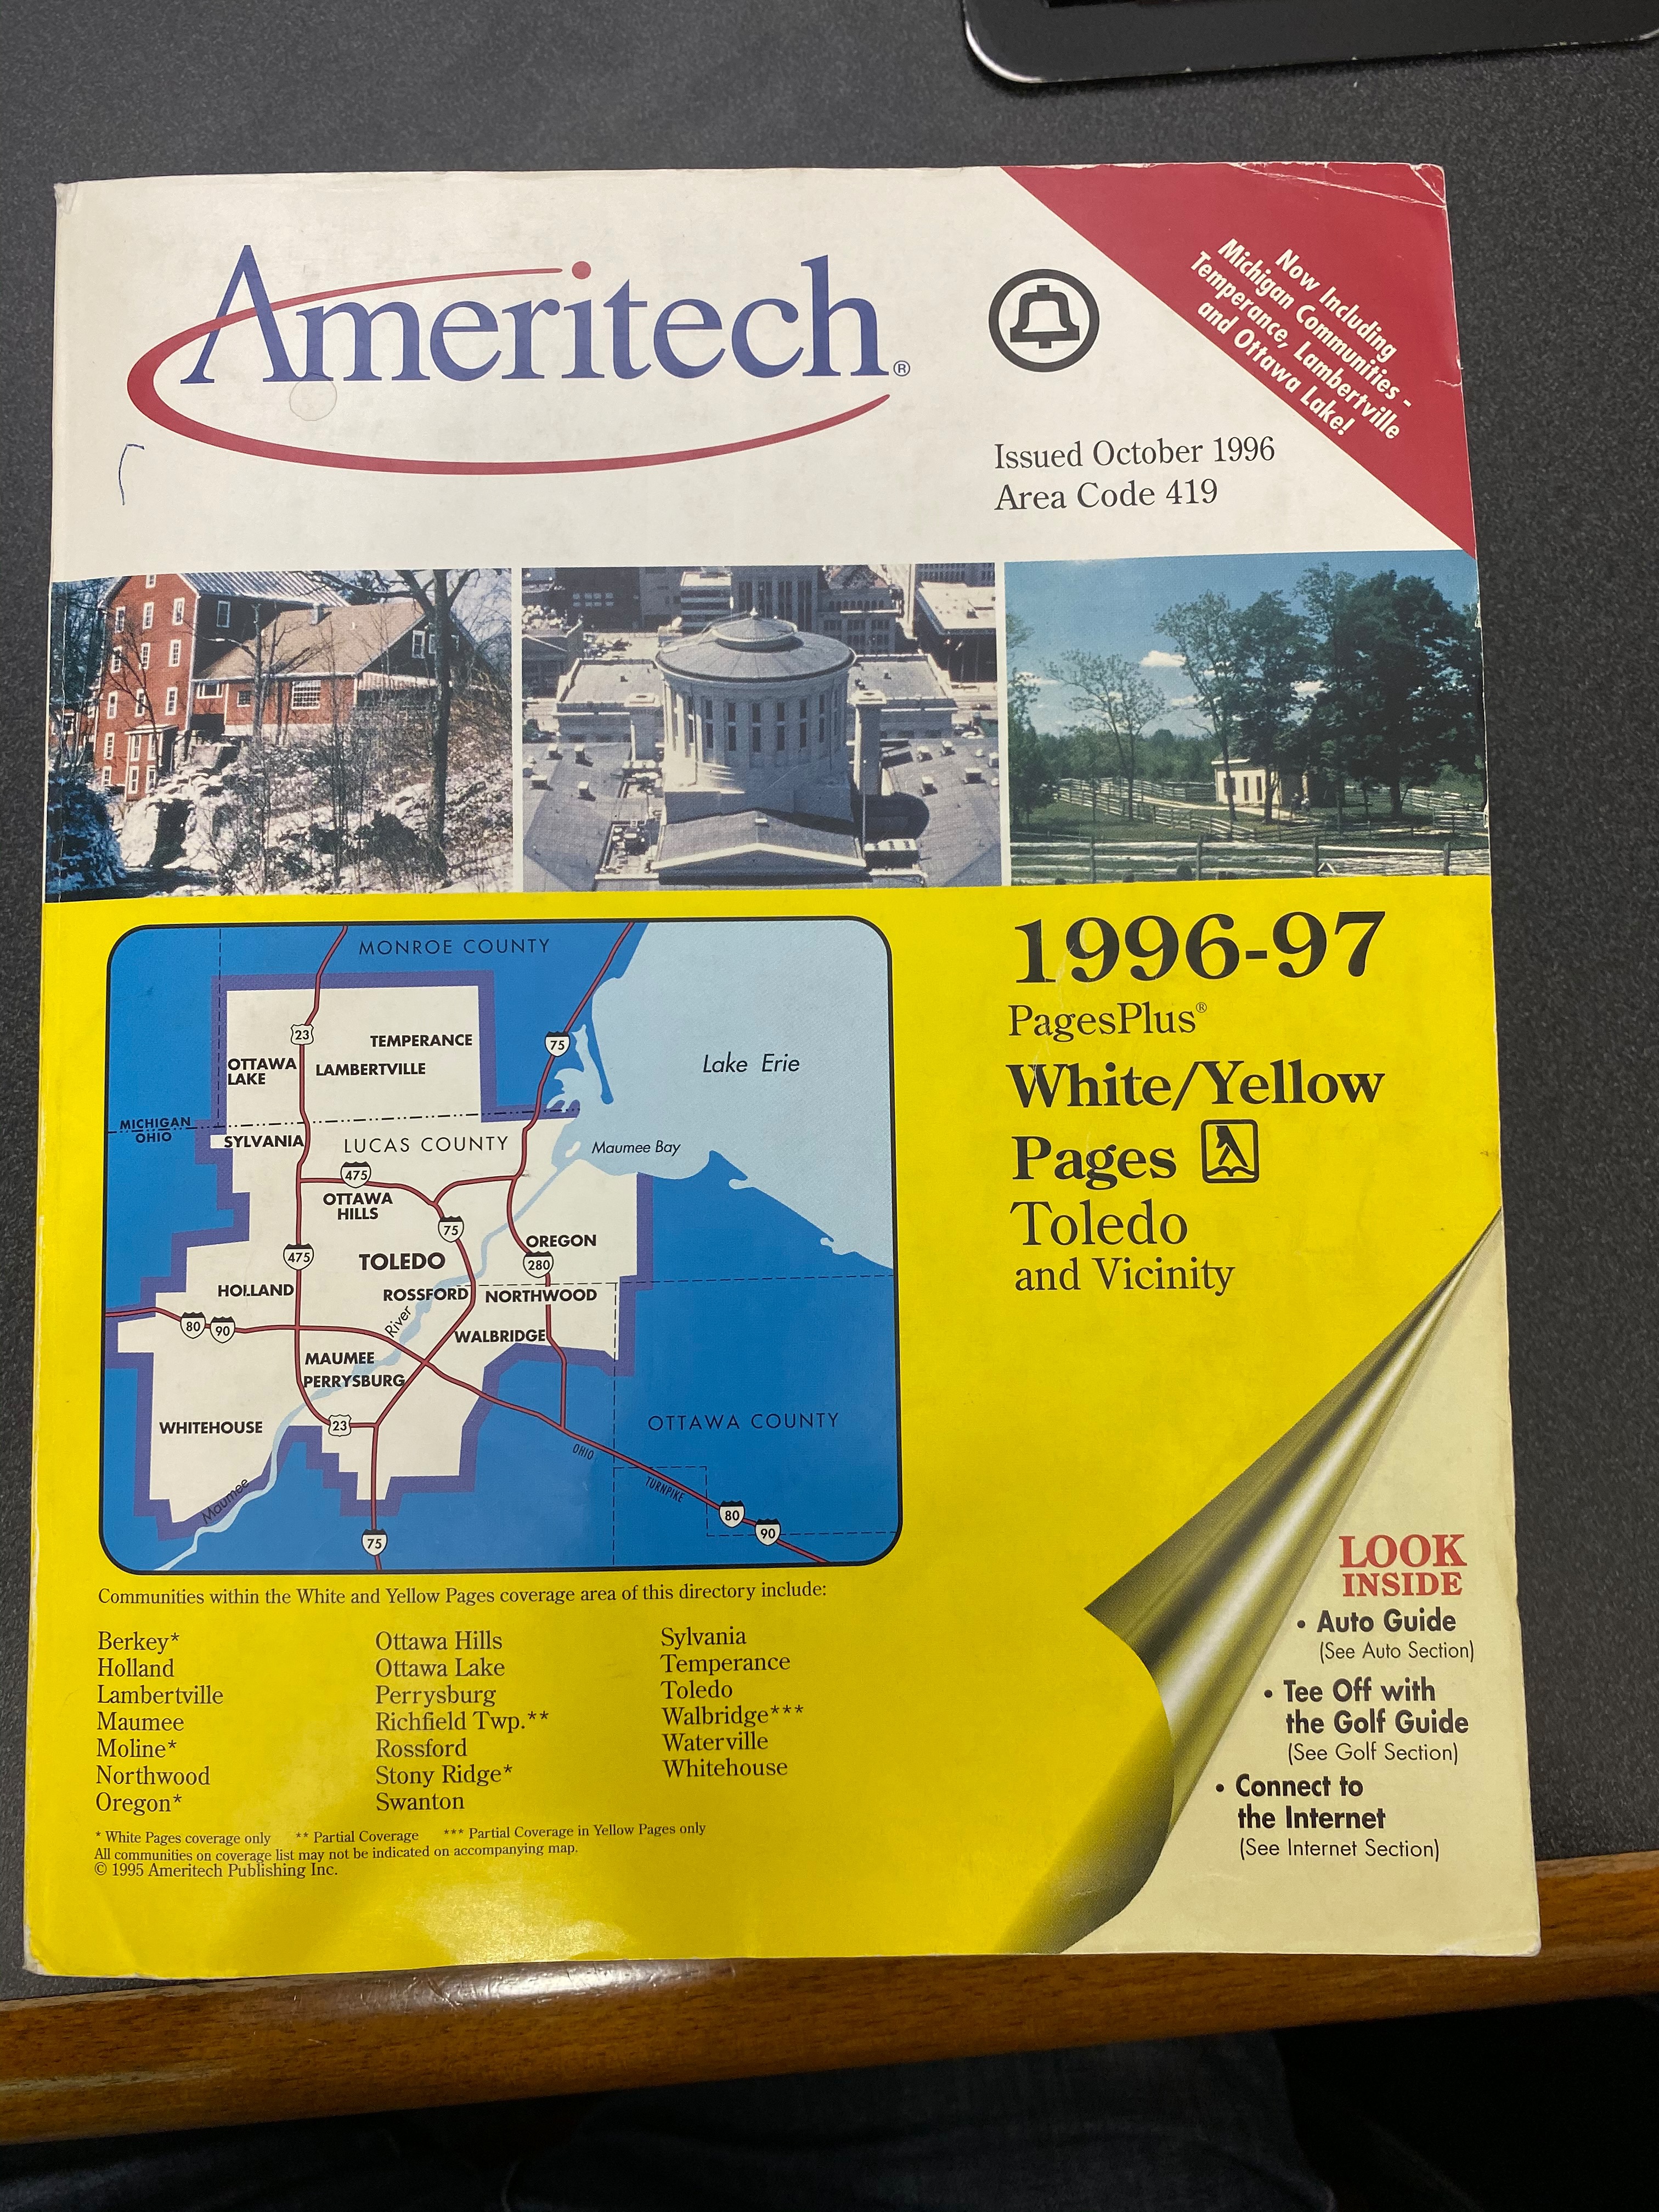
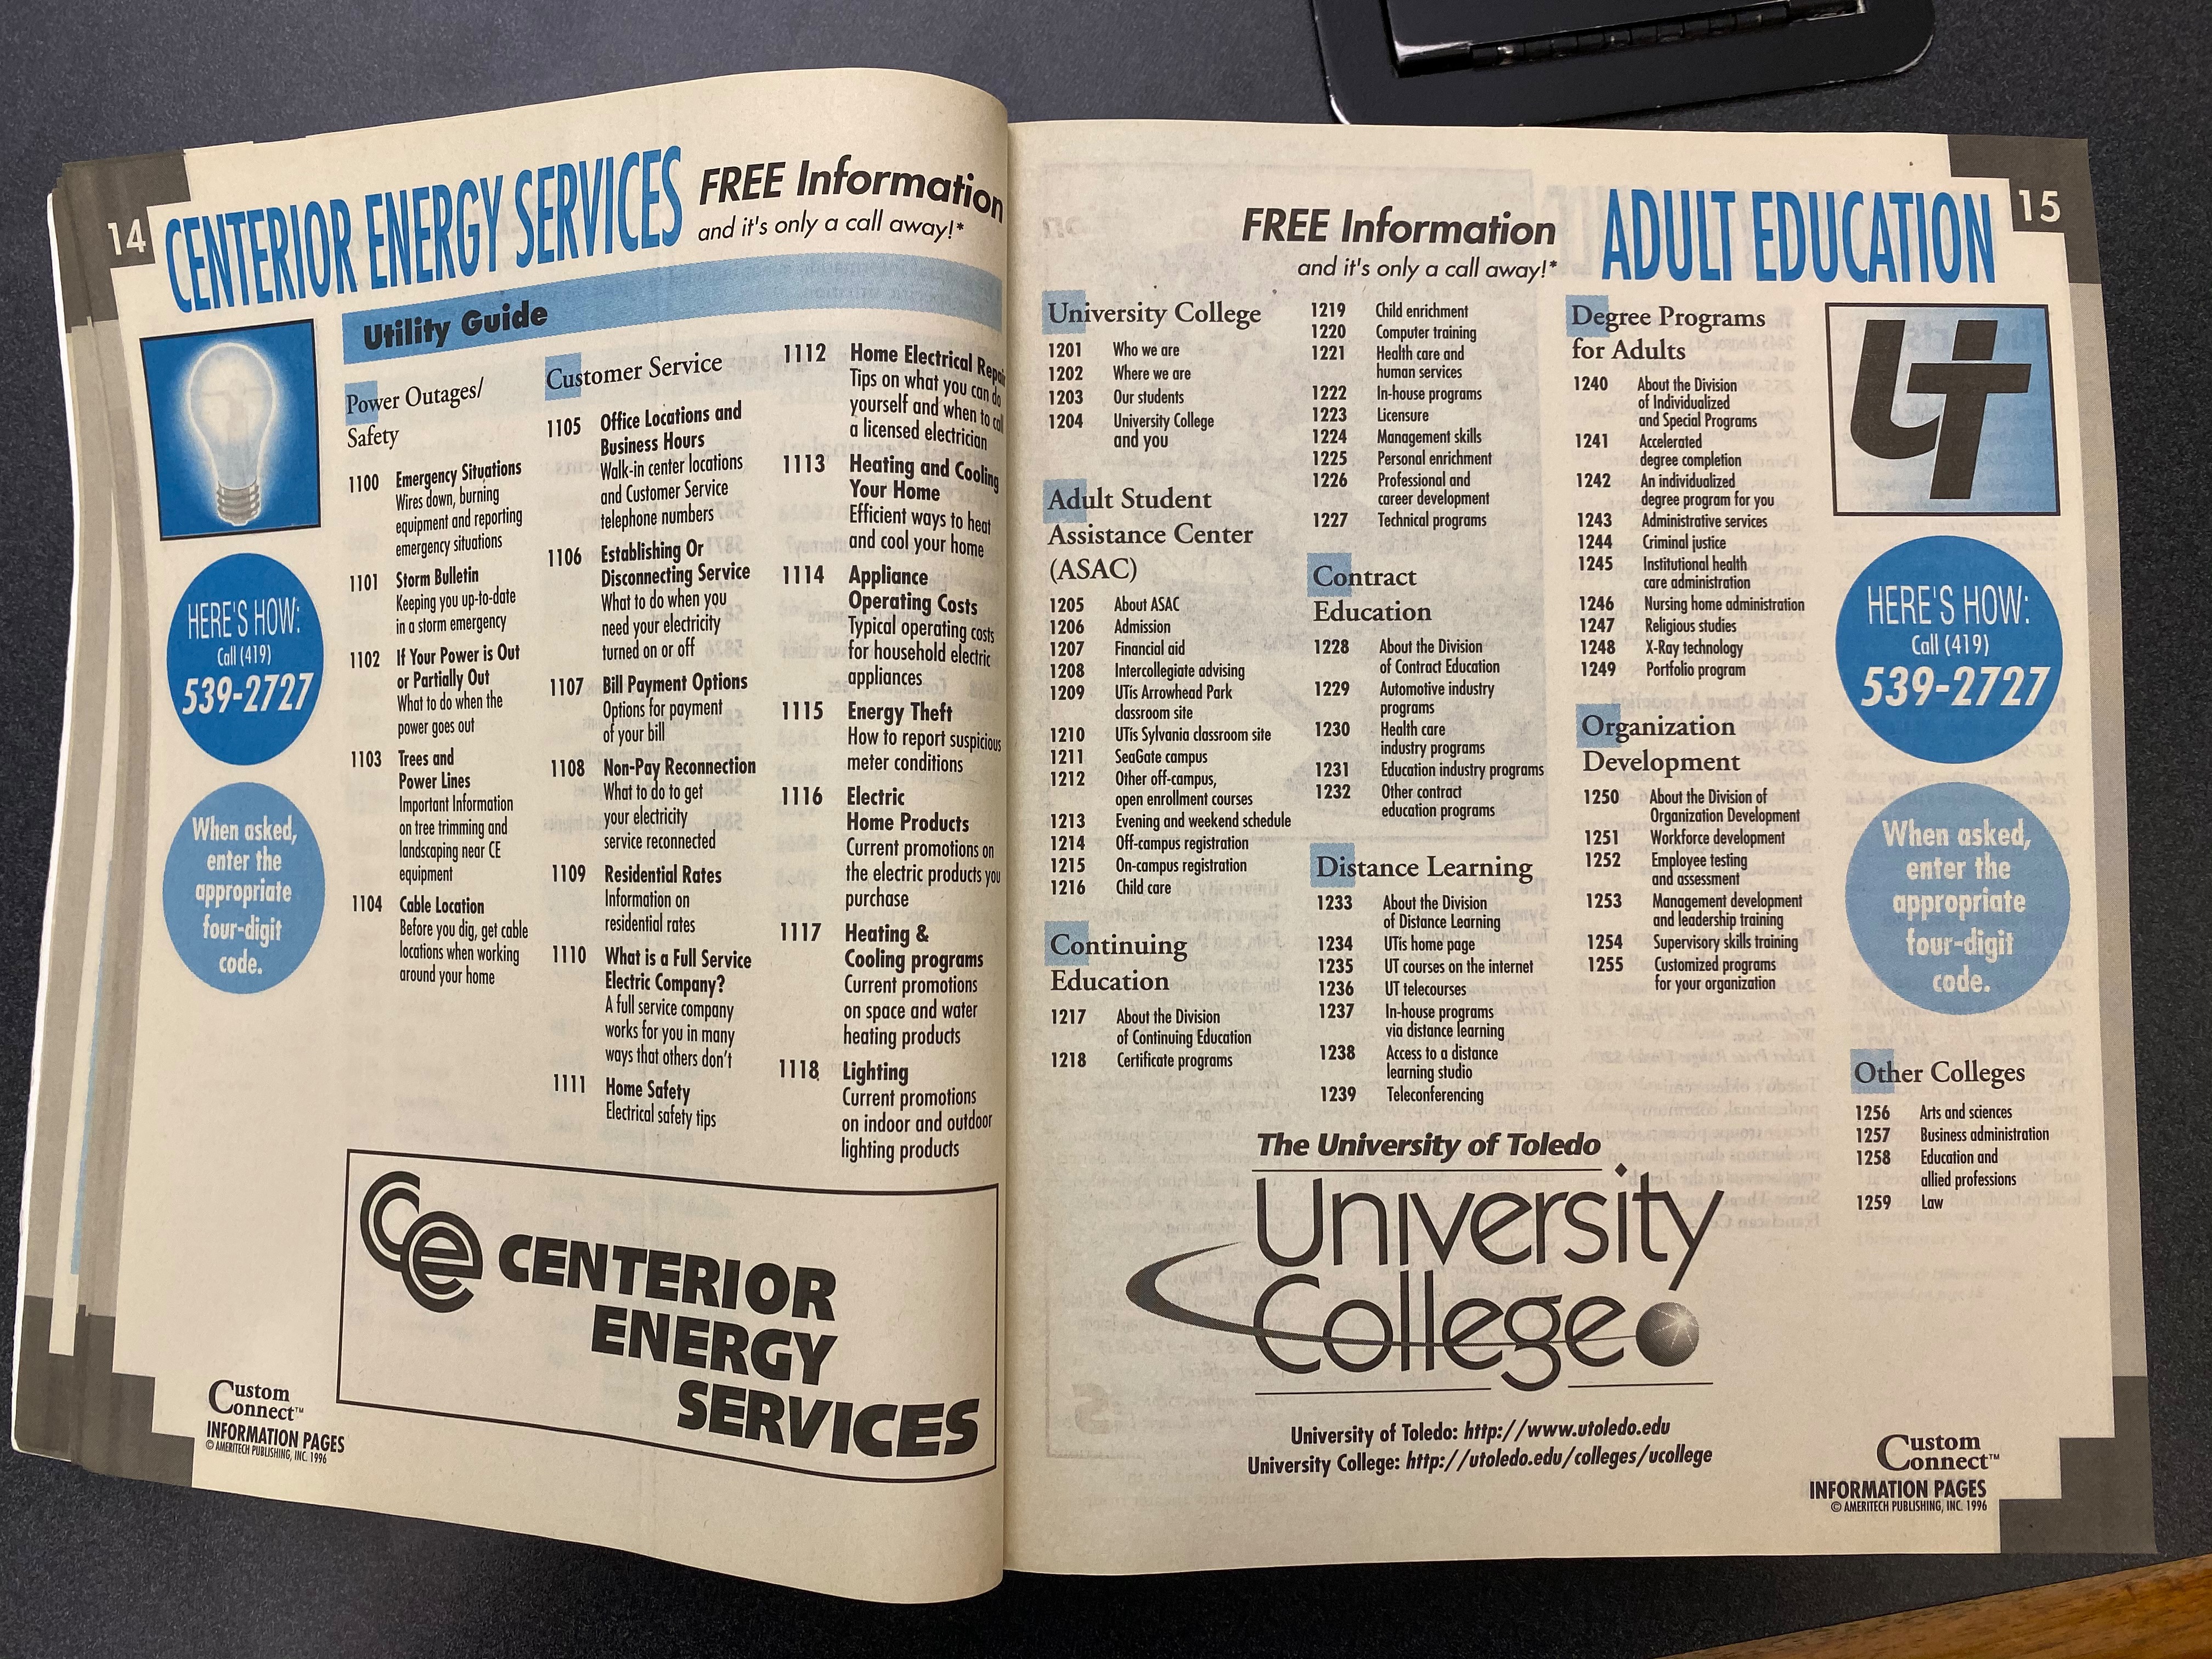
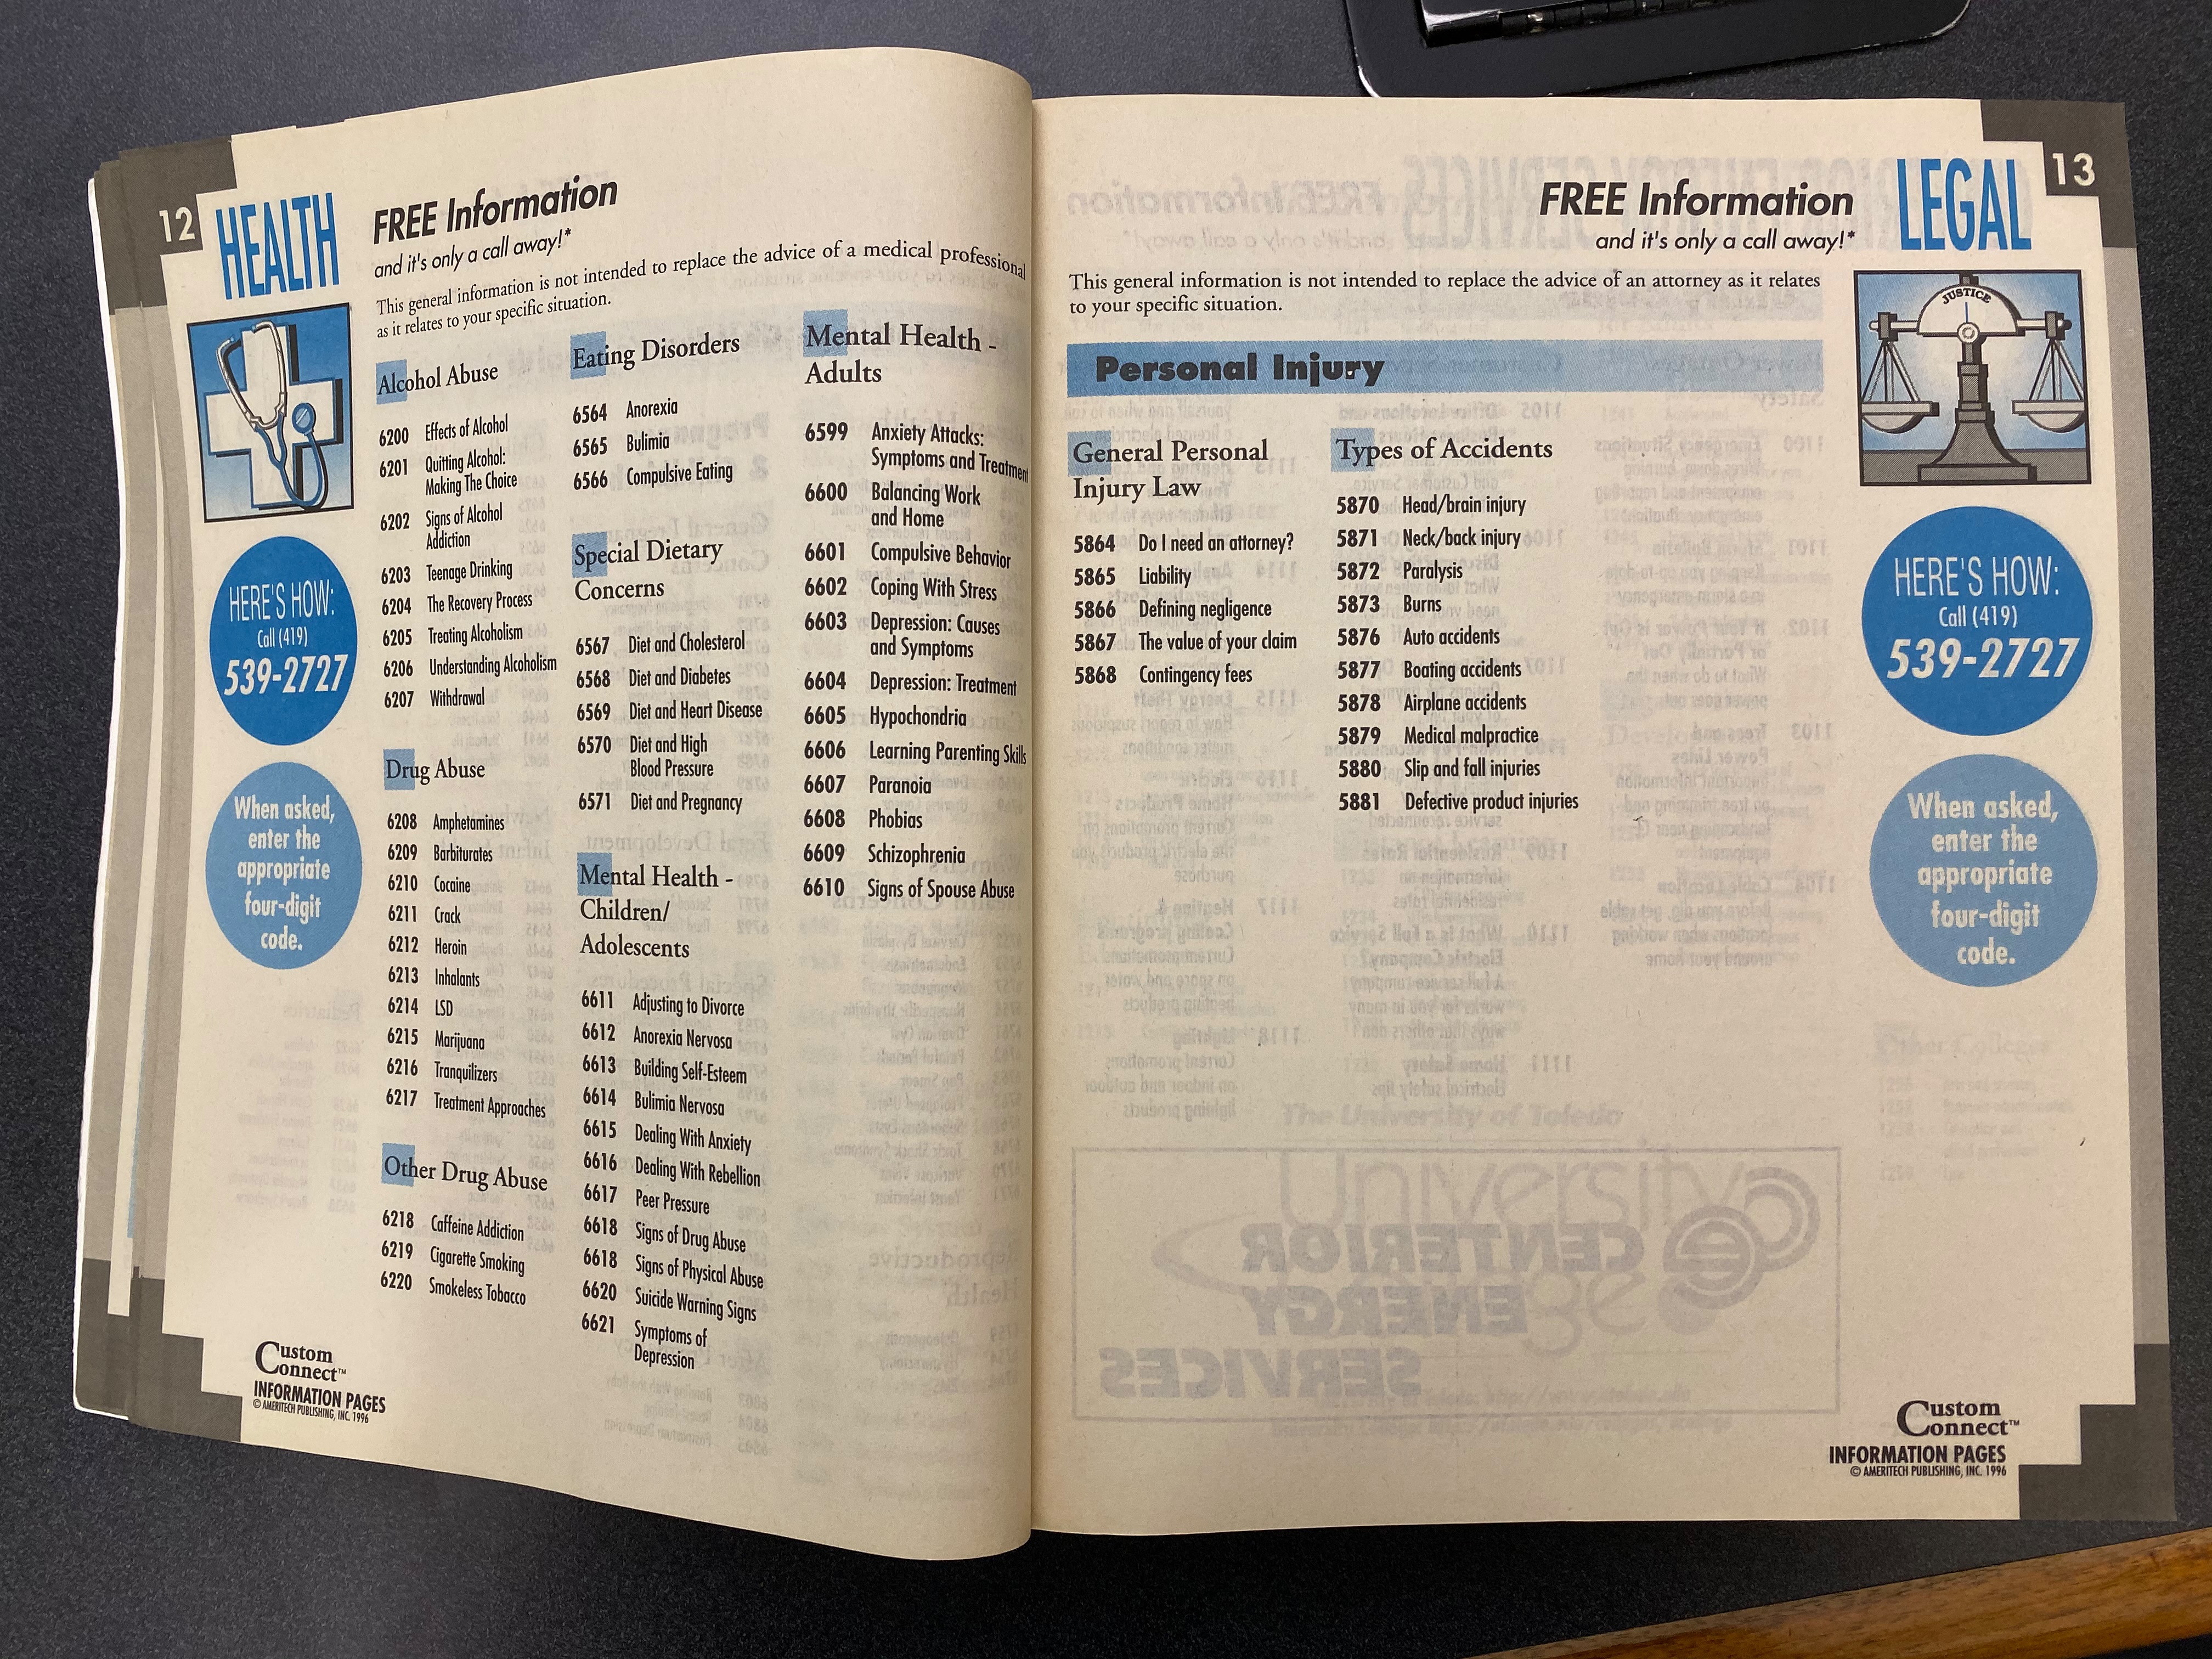
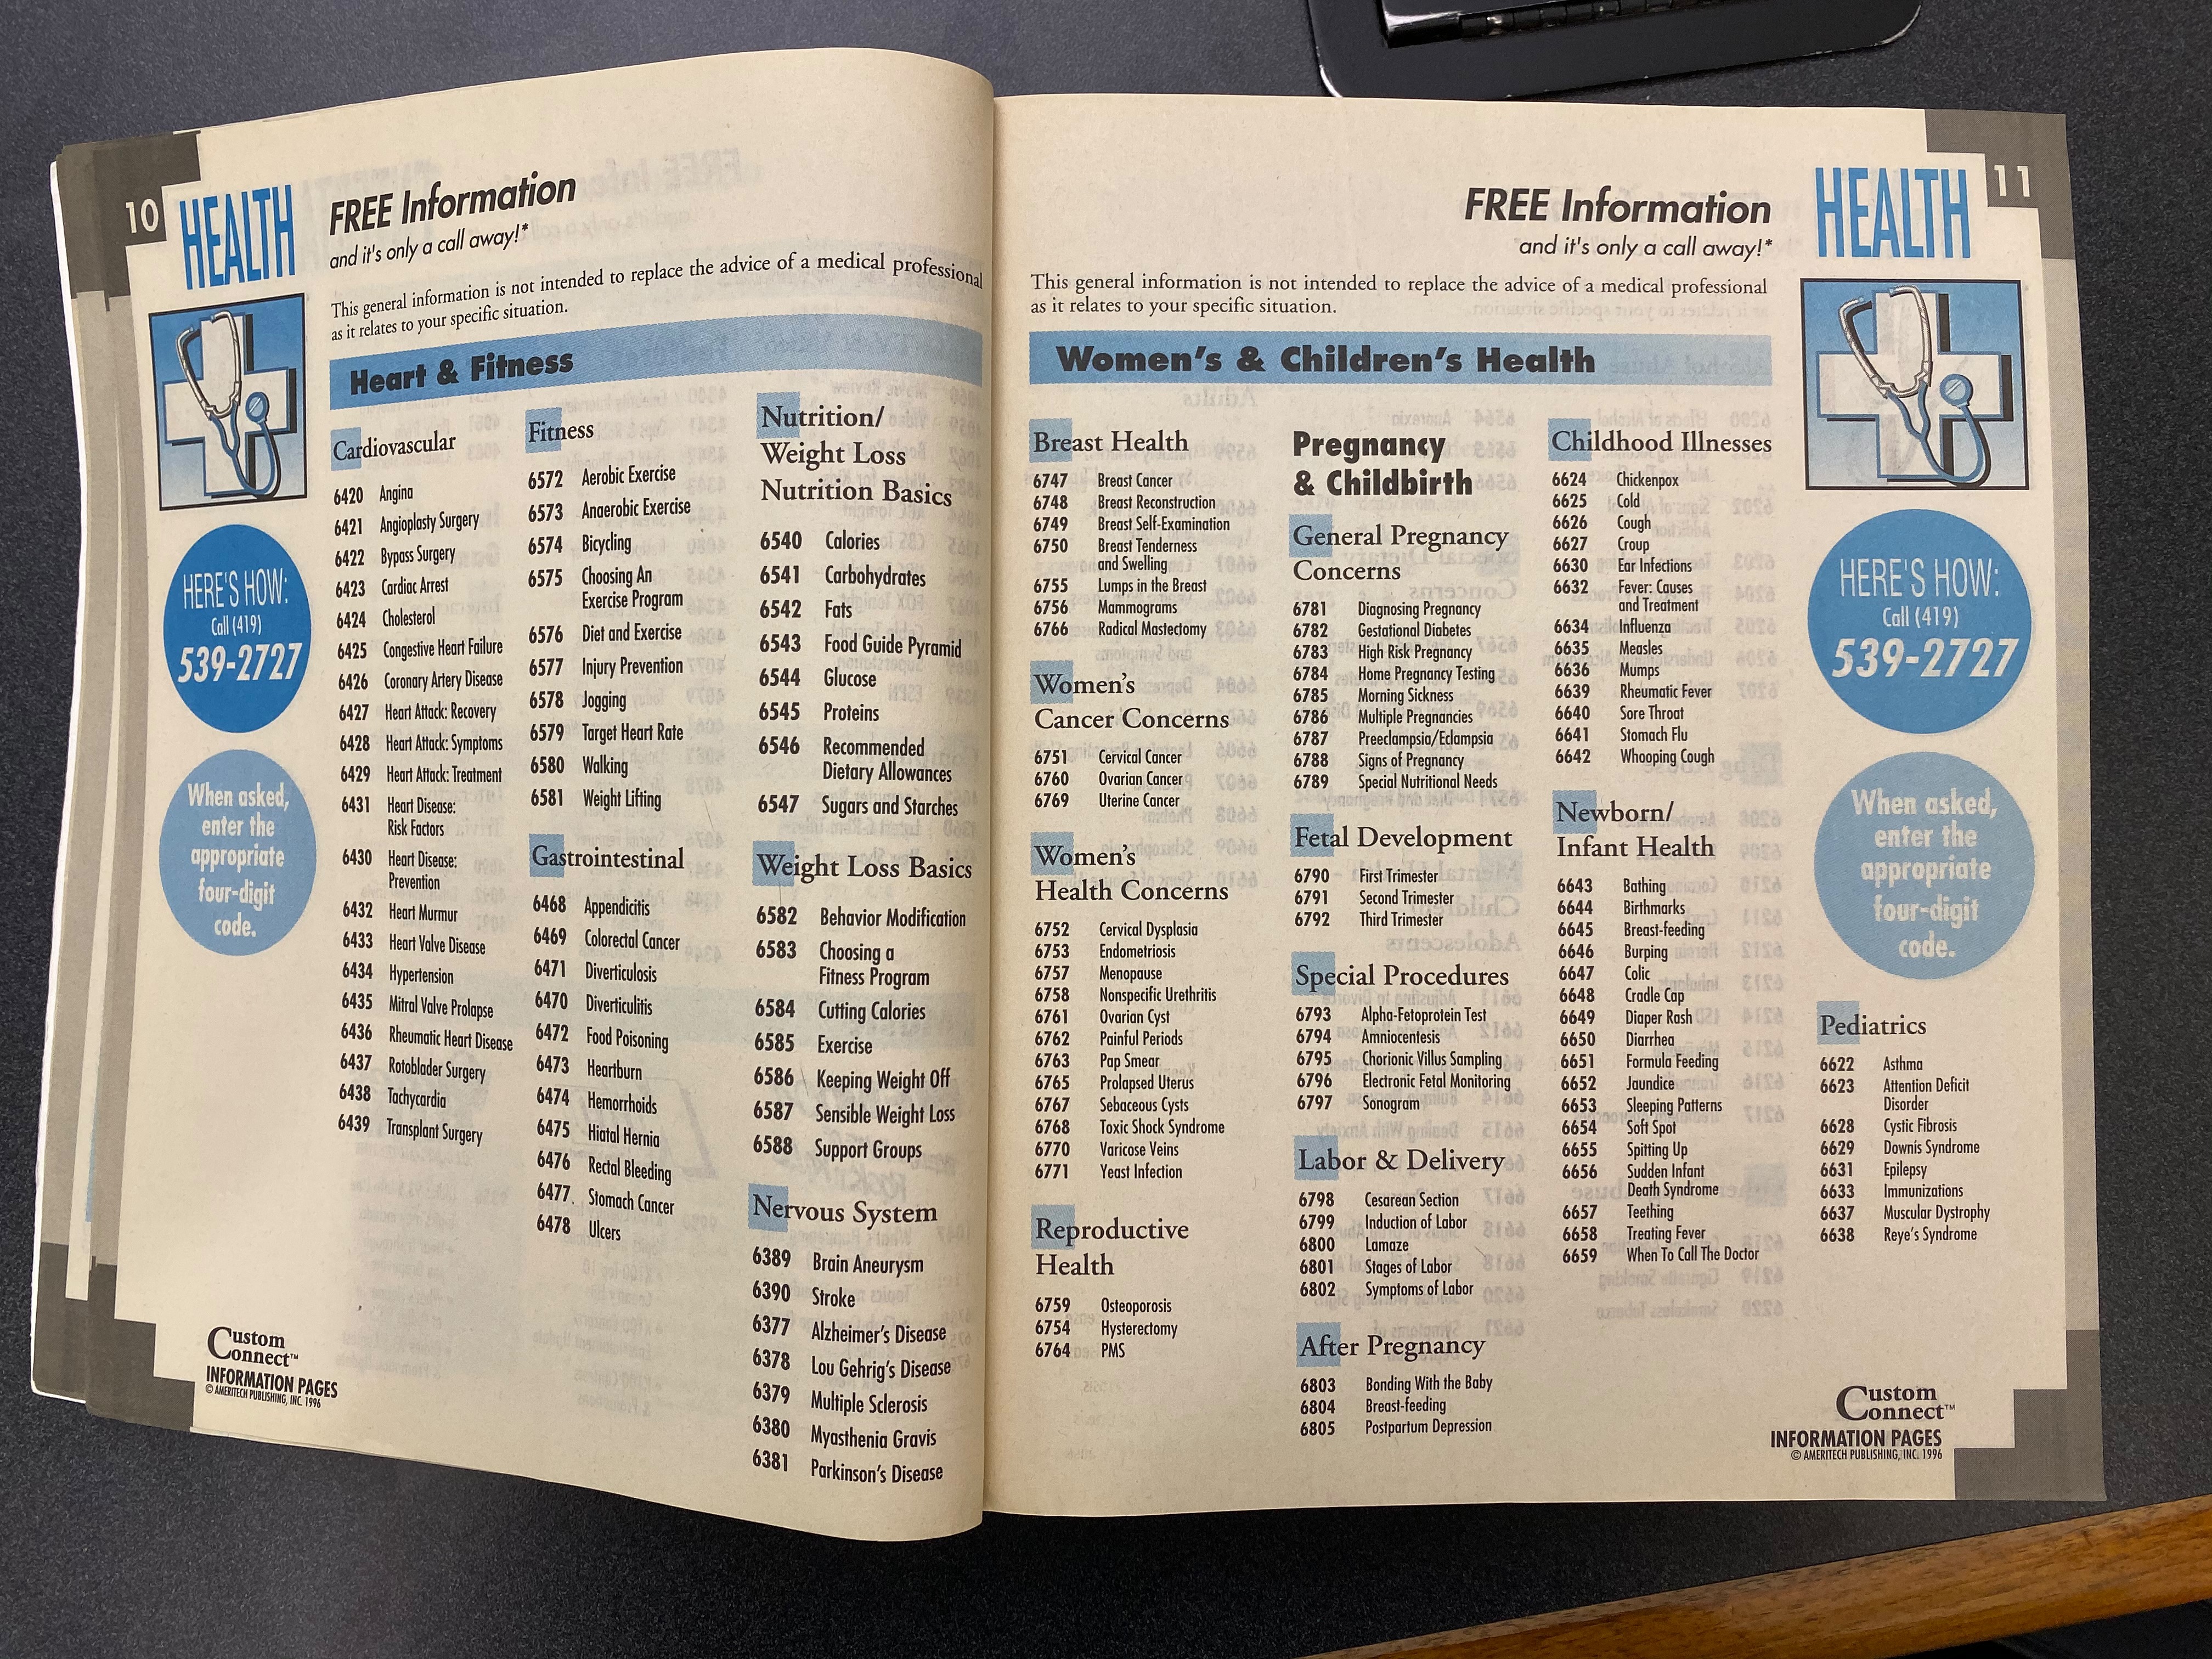
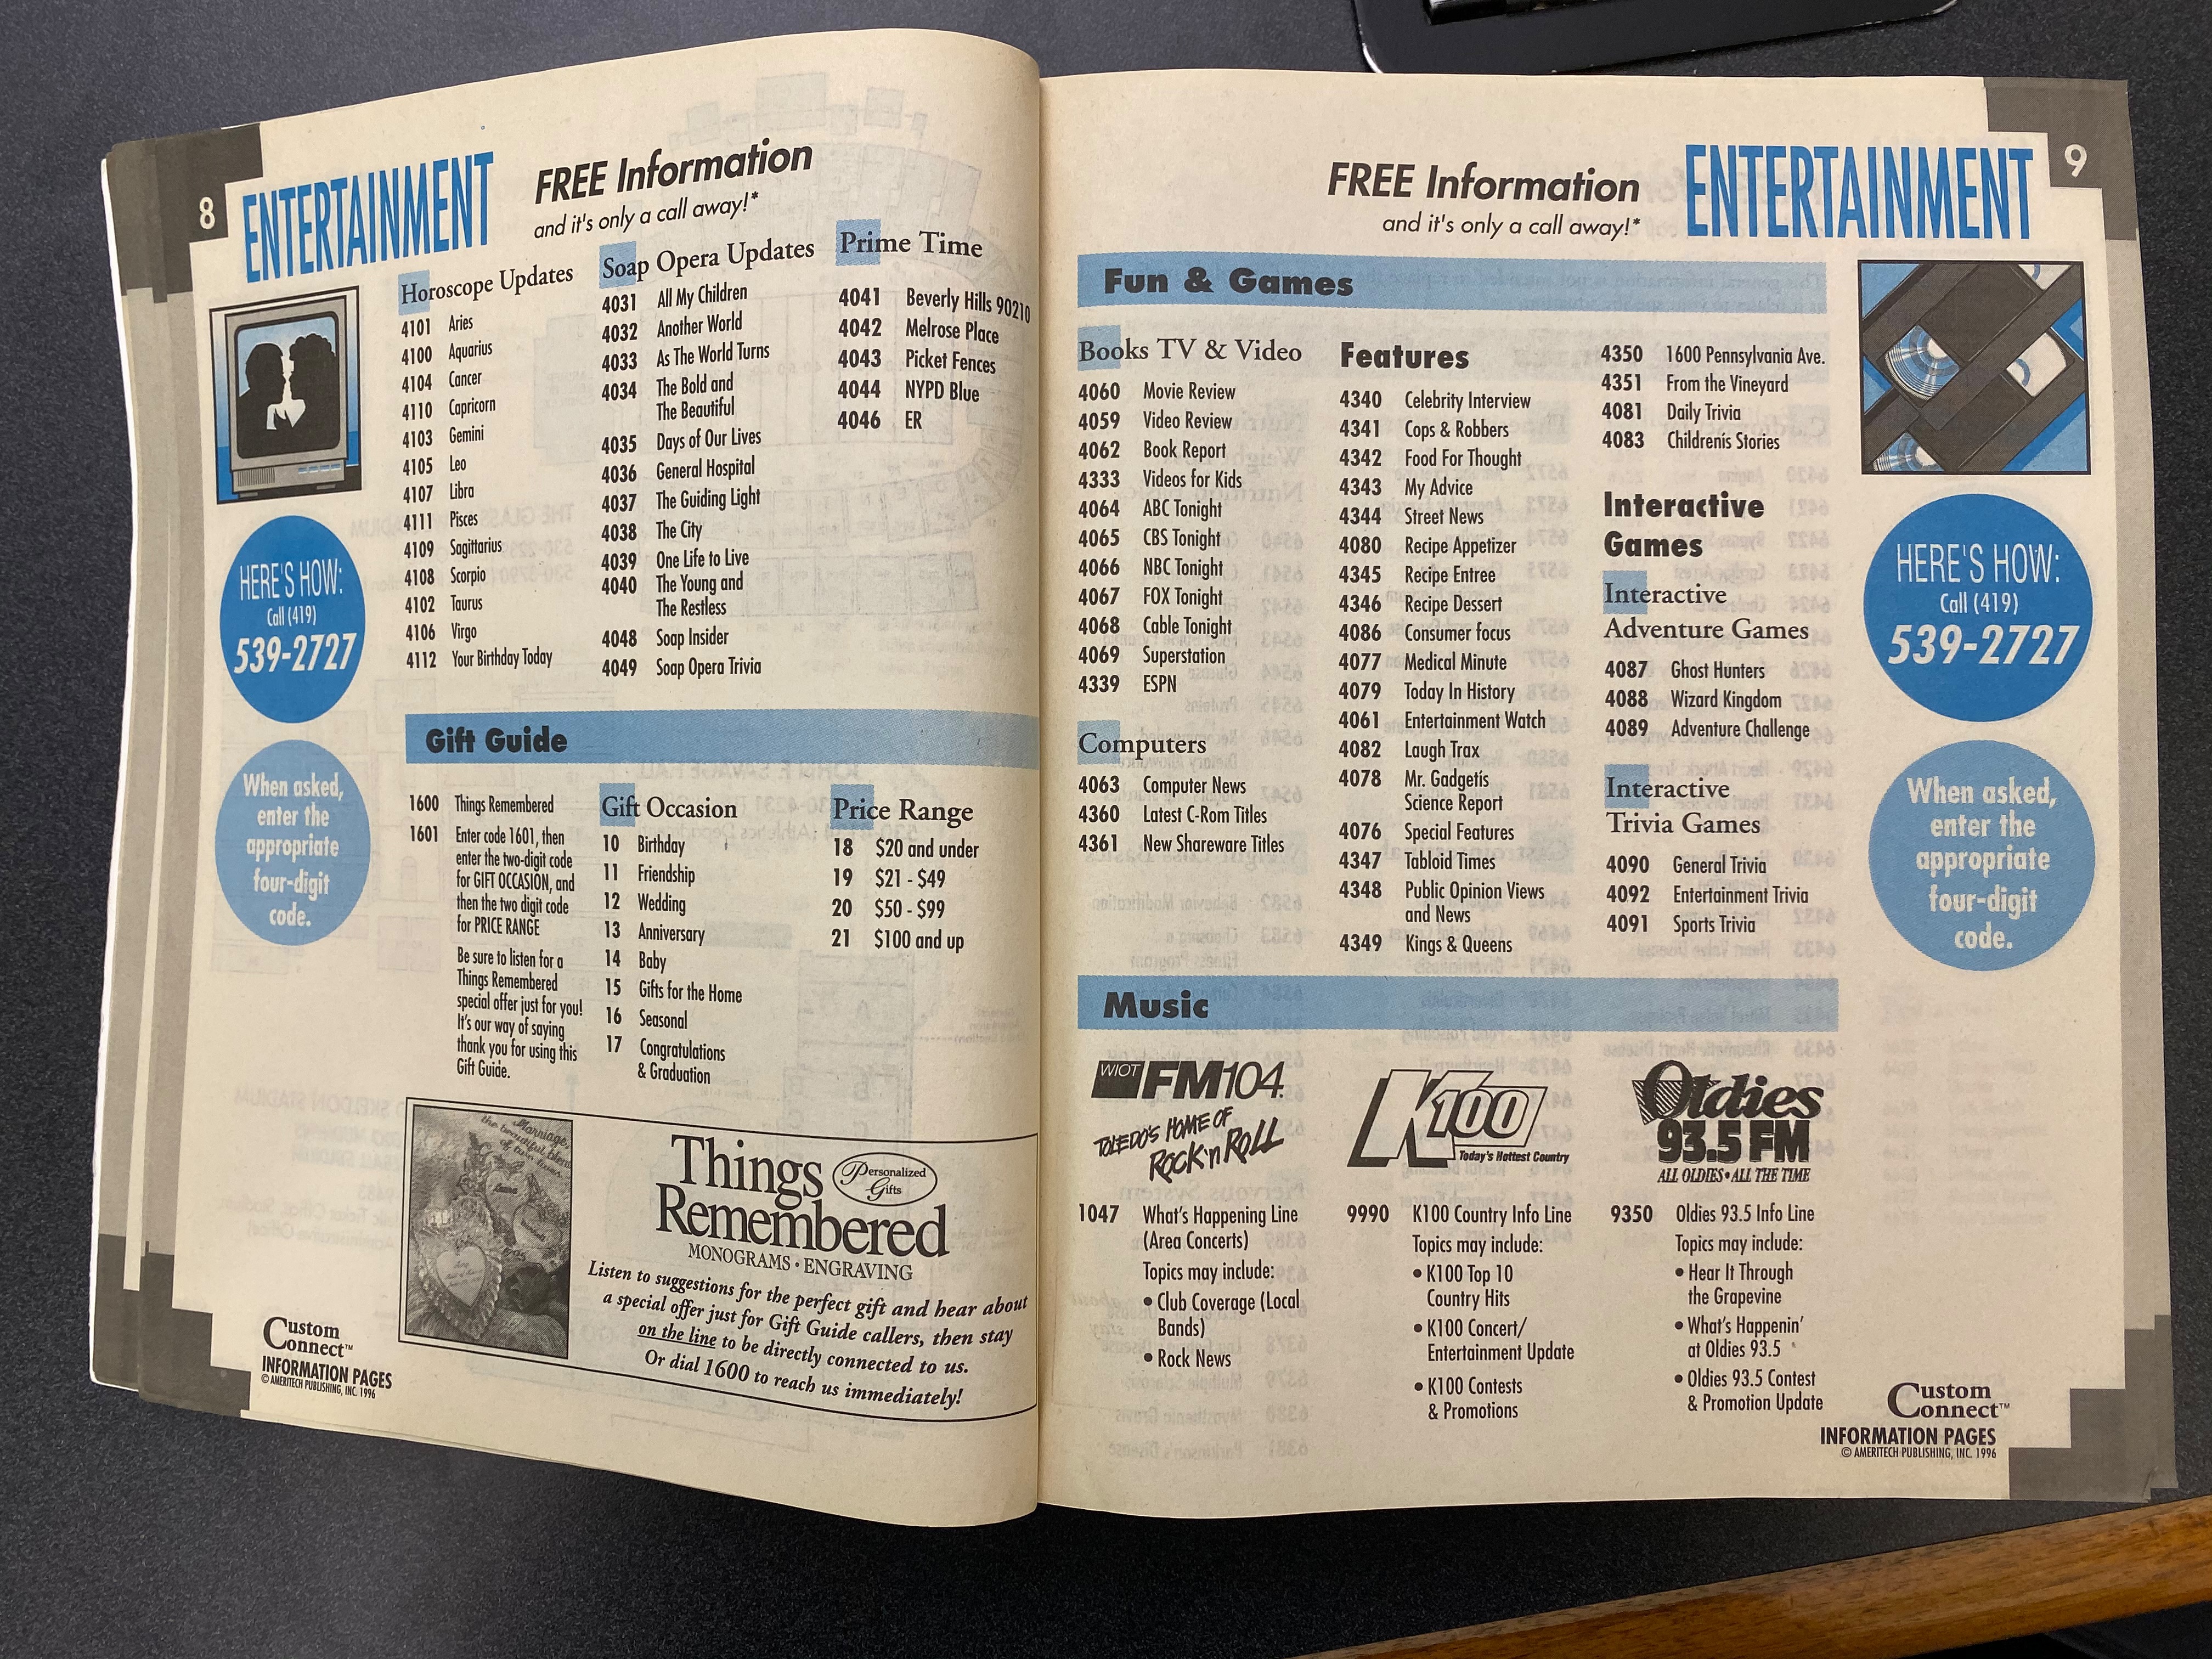
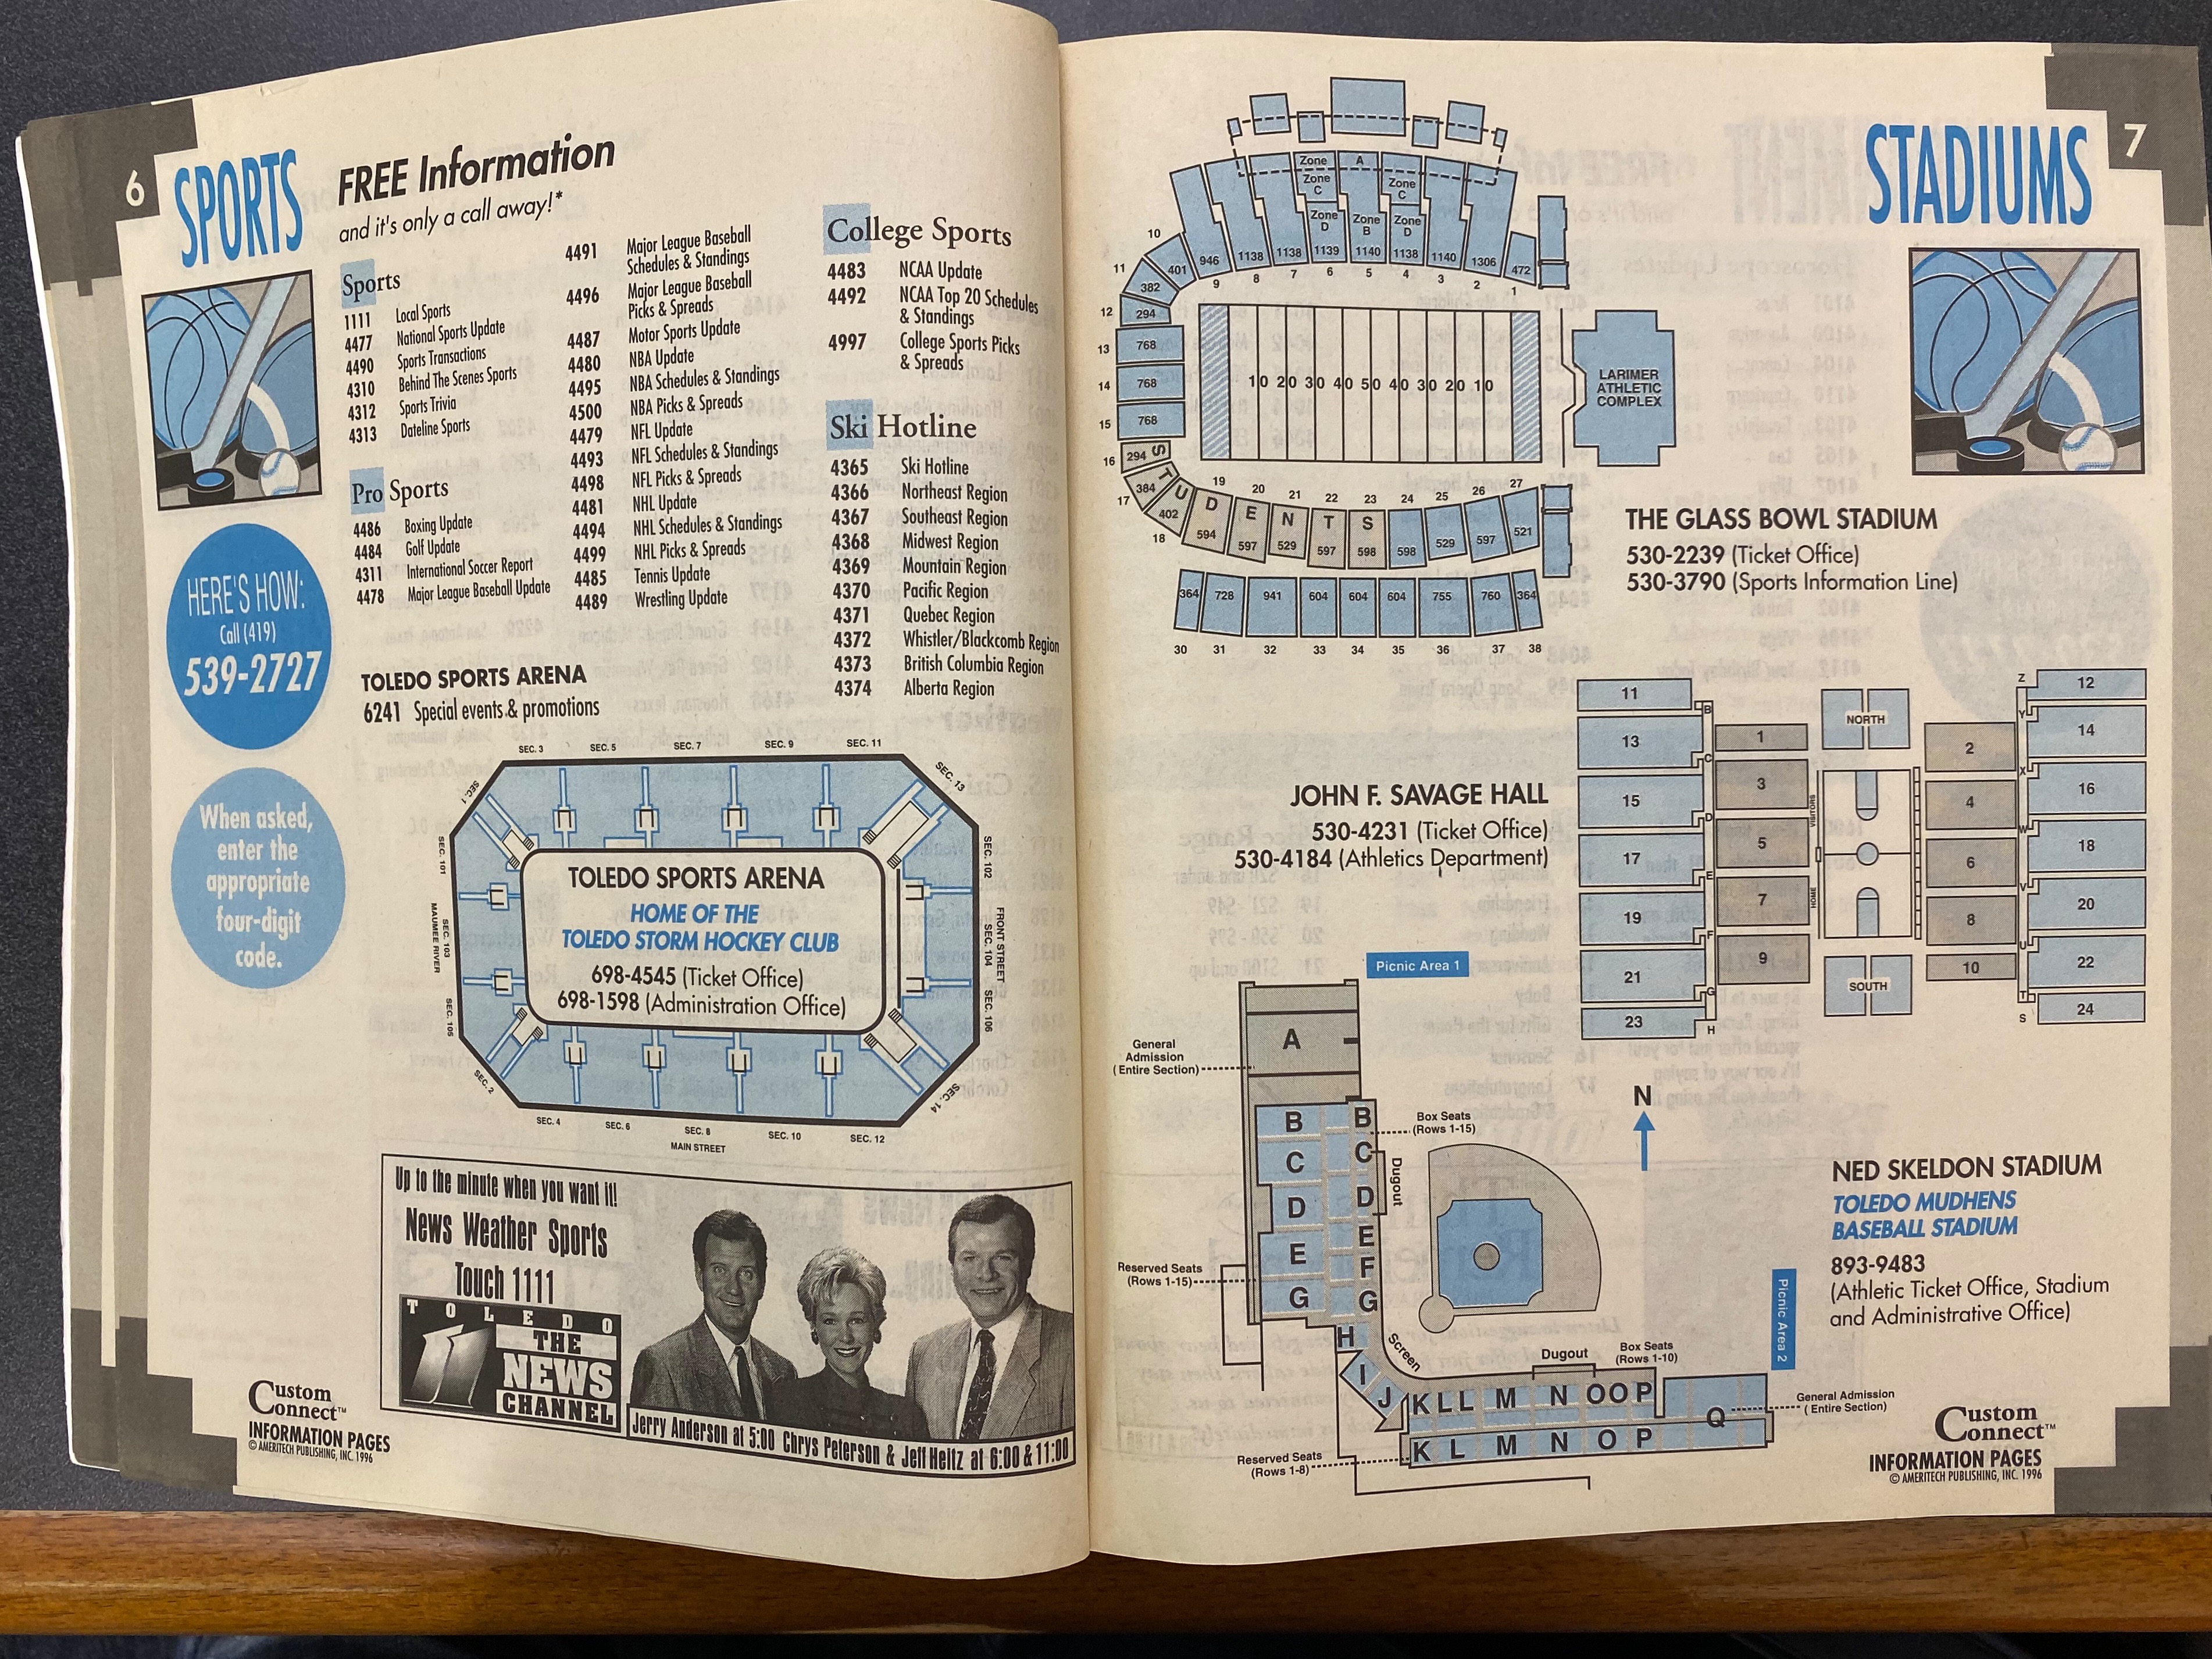
I don't remember the leave-a-message one, but I do remember the dial in service. One day I went down to the local library and found an old phone book from the 90s and sure enough, it had all the codes. Here are some photos from the Toledo, OH Ameritech 1996-7 phone book if anyone else is curious:
https://cdn.remarkedusercontent.com/file/remarked-prod/1/mar... https://cdn.remarkedusercontent.com/file/remarked-prod/1/mar... https://cdn.remarkedusercontent.com/file/remarked-prod/1/mar... https://cdn.remarkedusercontent.com/file/remarked-prod/1/mar... https://cdn.remarkedusercontent.com/file/remarked-prod/1/mar... https://cdn.remarkedusercontent.com/file/remarked-prod/1/mar...