News for hackers. Stuff that matters.

tonyww

Browser use is a token hog

Show HN: A 3-line wrapper that enforces deterministic security for AI agents

If you are building AI agents with frameworks like browser-use, LangChain, or OpenClaw, you've likely hit the "blast radius" problem.A misconfigured prompt or hallucination can cause an agent to navigate to a phishing domain, expose an API key, or confidently claim a task succeeded when it actually clicked a disabled button.The standard fix right now is "LLM-as-a-judge"—taking a screenshot...

( Read More... | 1 comment | on HN )
AI agents currently operate on a flawed security model: they inherit the ambient permissions of the terminal they are spawned in. If an agent gets prompt-injected or hallucinates, a broad blast radius is guaranteed. I built predicate-claw to fix this. It’s a drop-in security plugin for OpenClaw, paired with a lightweight Rust daemon (predicate-authorityd). The core architecture is essentially defense-grade Run Time Assurance (RTA) applied to LLMs. Since you cannot formally verify a non-deterministic black box, you have to physically decouple the "brain" from the "actuators" and drop a hard-coded, deterministic gatekeeper in the middle. How it works:

The Interceptor: We hook into OpenClaw's before_tool_call execution loop. The LLM has no idea the security layer exists. The Sidecar Gate: The tool request is routed to the local Rust daemon, which evaluates the intent against a deterministic YAML policy (e.g., blocking rm -rf, allowing fs.read only in ./src). It fails closed by default. The TUI: The daemon ships with a terminal UI to monitor all agent requests, allows, and denies in real-time. I built this in Rust to get strict memory safety with <1ms of latency overhead. It compiles to a static binary and drops into existing projects with zero friction.

Link to GitHub Repo: https://github.com/PredicateSystems/predicate-claw

Demo (GIF): https://github.com/PredicateSystems/predicate-claw/blob/main...

We already use deterministic post-execution verification for our web agents (DOM snapshot diffing, strictly avoiding the 'LLM-as-judge' trap). Next on the roadmap is bringing that same verifiable state-hashing to the OS level. I’d love to hear your thoughts on the architecture and how you're currently handling local agent sandboxing. Note: If you aren't using OpenClaw, our core engine also supports Python frameworks like LangChain and browser-use in 3 lines of code.

You can read the full architecture and see our enterprise fleet management here: https://predicatesystems.ai/docs/vault

Re:A verification layer for browser agents: Amazon case study on Wednesday January 28, 2026 @05:13PM (#46802326)
Yeah, that’s a pretty good analogy.

The main difference is that the “tests” are predicates over live browser state and are often proposed alongside the plan on the fly, not written upfront by a developer. But conceptually it’s very close: make the expected outcome explicit, try an action, verify, and only move forward if the condition actually holds.

Re:A verification layer for browser agents: Amazon case study on Wednesday January 28, 2026 @02:39PM (#46800487)
Absolutely agree on the compounding error point - that’s exactly what pushed us toward verification.

On “verification wrong”: we try hard to keep predicates grounded and re-evaluated, not “check a cached handle”. Assertions do re-snapshot / re-query during each retry, and we scope them to signals that should change (URL, existence/state of an element, text/value).

If the page is flaky/stale, the assertion just won’t prove the condition within the retry window and we fail with artifacts such as frames of clip (if ffmpeg available) rather than claiming success.

There are still edge cases (virtualized DOM, optimistic UI, async updates), but in those cases the goal is the same: make the failure explicit and debuggable with artifacts and time-travel traces, not silently drift.

Re:A verification layer for browser agents: Amazon case study on Wednesday January 28, 2026 @02:34PM (#46800419)
It’s mostly the former: there’s a small set of generic checks/primitives, and we choose which ones to apply per step.

The binding between “task/step” and “what to verify” can come from either:

the user (explicit assertions), or the planner/executor proposing a post-condition (e.g. “after clicking checkout, URL contains /checkout and a checkout button exists”).

But the verifier itself is not an AI, by design it’s predicate-only

Re:A verification layer for browser agents: Amazon case study on Wednesday January 28, 2026 @02:26PM (#46800324)
I’m absolutely not AI, I dedicate this morning to technical discussion with HN community on my post, which I’ve spent weeks building the technology behind it
Re:A verification layer for browser agents: Amazon case study on Wednesday January 28, 2026 @02:21PM (#46800257)
Totally agree - hybrid approaches can work well, especially on messy pages. We’ve seen the same tradeoff.

On the verification side though, dynamic pages are exactly the reason why we scope assertions narrowly (specific predicates, bounded retries using eventually() function) instead of diffing the whole page. If the expected condition can’t be proven within that window, we fail fast rather than guessing.

Re:A verification layer for browser agents: Amazon case study on Wednesday January 28, 2026 @02:06PM (#46800087)
Importance ranking is just a heuristic pass that scores/prioritizes elements (size, visibility, role, state) so the snapshot stays small and focused. It’s deterministic, not ML.

The verification layer absolutely still exists without it — assertions, predicates, retries, and artifacts all work locally. The API-backed ranking just improves pruning quality on very dense pages, but it’s not required for correctness.

You can set use_api = False in the SnapshotOptions to avoid using the api

Re:A verification layer for browser agents: Amazon case study on Wednesday January 28, 2026 @01:23PM (#46799479)
The WASM pass is fully deterministic: it’s just code running in the page to extract and prune post-rendered elements (roles, geometry, visibility, layout, etc), no agent involved in the chrome extension .

The “deterministic overrides” aren’t generated by a verifier agent either; they’re runtime rules that kick in when assertions or ordinality constraints are explicit (e.g. “first result”). The verifier just checks outcomes — it doesn’t invent actions. Because the nature of ai agents is non-deterministic, which we don’t want to introduce to the verification layer (predicate only).

Re:A verification layer for browser agents: Amazon case study on Wednesday January 28, 2026 @11:42AM (#46797777)
Thanks — that’s exactly our motivation. The key shift for us was moving from “did the agent probably do the right thing?” to “can we prove the state we expected actually holds.”

The property-based testing analogy is a good one — once you make success explicit, failures become actionable instead of mysterious.

Re:A verification layer for browser agents: Amazon case study on Wednesday January 28, 2026 @11:37AM (#46797675)
The accessibility tree is definitely useful, and we do look at it. The issue we ran into is that it’s optimized for assistive consumption, not for action verification or layout reasoning on dynamic SPAs.

In practice we’ve seen cases where AX is incomplete, lags hydration, or doesn’t reflect overlays / grouping accurately. It does not support ordinality queries well. That’s why we anchor on post-rendered DOM + geometry and then verify outcomes explicitly, rather than relying on any single representation.

Re:A verification layer for browser agents: Amazon case study on Tuesday January 27, 2026 @09:58PM (#46790507)
A quick clarification on intent, since “browser automation” means different things to different people:

This isn’t about making scripts smarter or replacing Playwright/Selenium. The problem I’m exploring is reliability: how to make agent-driven browser execution fail deterministically and explainably instead of half-working when layouts change.

Concretely, the agent doesn’t just “click and hope”. Each step is gated by explicit post-conditions, similar to how tests assert outcomes:

---- ## Python Code Example:

ready = runtime.assert_( all_of(url_contains("checkout"), exists("role=button")), "checkout_ready", required=True )

----

If the condition isn’t met, the run stops with artifacts instead of drifting forward. Vision models are optional fallbacks, not the primary control signal.

Happy to answer questions about the design tradeoffs or where this approach falls short

A verification layer for browser agents: Amazon case study

https://sentienceapi.com/blog/verification-layer-amazon-case-study

A common approach to automating Amazon shopping or similar complex websites is to reach for large cloud models (often vision-capable). I wanted to test a contradiction: can a ~3B parameter local LLM model complete the flow using only structural page data (DOM) plus deterministic assertions?This post summarizes four runs of the same task (search → first product → add to cart → checkout on...

( Read More... | 22 comments | on HN )
Sorry for the misunderstanding, I intended to post it as news or engineering article, which is why I didn't include *Show HN* in the title
Good question. On the surface, it does look very similar to the traditional scraper/script, but there's a subtle difference in where the logic lives and how failures are handled.

A traditional scraper/script hard-codes selectors and control flow up front. When the layout changes, it usually breaks at an arbitrary line and you debug it manually.

In this setup, the agent chooses actions at *runtime* from a bounded action space, and the system uses the built-in predicates (e.g. url_changes, drawer_appeared, etc) to verify the outcomes. When it fails, it fails at a specific semantic assertion with artifacts, not a missing selector.

So it’s less “replace scripts” and more “apply test-style verification and recovery to AI-driven decisions instead of static code.”

yes, the repo is publicly available: https://github.com/SentienceAPI/sentience-sdk-playground you can pull it and set up the dependencies including sentience API key, then run the main.py in the planner_executor_local folder
One clarification since a few comments from coworkers/friends are circling this: Amazon isn’t the point here.

We used it because it’s a dynamic, hostile UI, but the design goal is a site-agnostic control plane. That’s why the runtime avoids selectors and screenshots and instead operates on pruned semantic snapshots + verification gates.

If the layout changes, the system doesn’t “half-work” — it fails deterministically with artifacts. That’s the behavior we’re optimizing for.

Amazon shopping automation without vision: verification gate+local model (3B)

A common approach to automating Amazon shopping or similar complex websites is to reach for large cloud models (often vision-capable). I wanted to test a contradiction: can a ~3B parameter local LLM model complete the flow using only structural page data (DOM) plus deterministic assertions?This post summarizes four runs of the same task (search → first product → add to cart → checkout on...

( Read More... | 8 comments | on HN )
A useful way to think about this: browser-use is the runner, Sentience is the assertion layer.

Agents act → Sentience verifies.

If you’ve built flaky E2E tests or agent demos that “usually work”, this is an attempt to make those workflows inspectable and testable.

Show HN: Browser-use, Qwen 2.5 3B, Sentience – Jest assertions for AI web agents

Hi HN,This is an integration between browser-use and Sentience SDK, where Sentience acts like Jest for AI web agents: it lets agents assert what changed on the page, instead of guessing when they’re “done”.Most web agents today rely on screenshots or raw DOM dumps and hope the model infers layout, state, and completion correctly. That can work for demos, but it’s expensive, brittle, and very...

( Read More... | 1 comment | on HN )
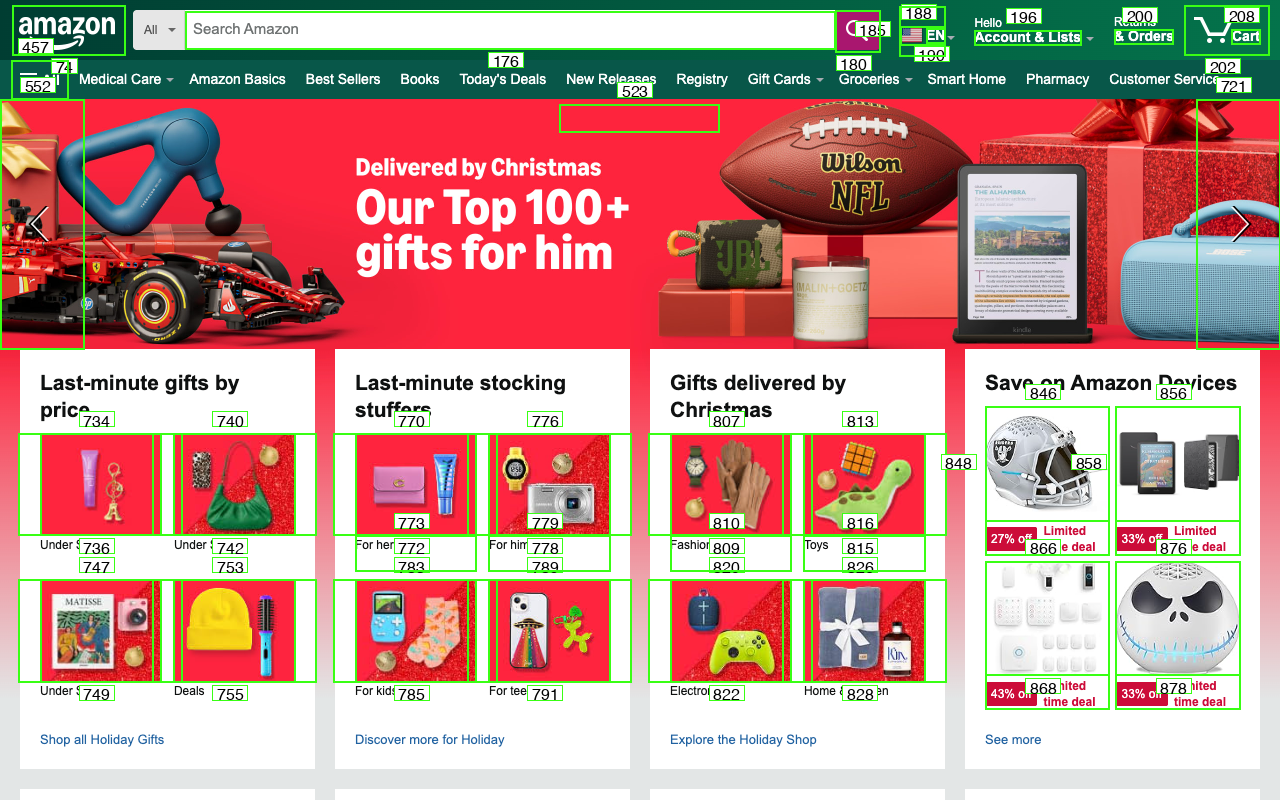
One thing I didn’t emphasize enough in the post: I originally tried the “labeled screenshot + vision model” approach pretty hard. (see this screenshot labeled with bbox + ID: https://sentience-screenshots.sfo3.cdn.digitaloceanspaces.co...)

In practice it performed worse than expected. Once you overlay dense bounding boxes and numeric IDs, the model has to solve a brittle symbol-grounding problem (“which number corresponds to intent?”). On real pages (Amazon, Stripe docs, etc.) this led to more retries and mis-clicks, not fewer.

What worked better for me was moving that grounding step out of the model entirely and giving it a bounded set of executable actions (role + visibility + geometry), then letting the LLM choose which action, not where to click.

Curious if others have seen similar behavior with vision-based agents, especially beyond toy demos.

Show HN: Sentience – Semantic Visual Grounding for AI Agents (WASM and ONNX)

Hi HN, I’m the solo founder behind SentienceAPI. I’ve spent the last December building a browser automation runtime designed specifically for LLM agents.The Problem: Building reliable web agents is painful. You essentially have two bad choices:Raw DOM: Dumping document.body.innerHTML is cheap/fast but overwhelms the context window (100k+ tokens) and lacks spatial context (agents try to click...

( Read More... | 1 comment | 2 points | on HN )
Example JSON Response (Simplified):

```

[ { "id": 42, "role": "button", "text": "Add to Cart", "bbox": { "x": 935, "y": 529, "w": 200, "h": 50 }, "visual_cues": { "cursor": "pointer", "is_primary": true, "color_name": "yellow" } }, { "id": 43, "role": "link", "text": "Privacy Policy", "bbox": { "x": 100, "y": 1200, "w": 80, "h": 20 }, "visual_cues": { "cursor": "pointer", "is_primary": false } } ]

```

This prototype builds on several open-source libraries:

MoviePy – video composition and rendering Pillow (PIL) – image processing and overlays

The demo app (MotionDocs) uses the public SentienceAPI SDK, generated from OpenAPI, which is the same interface used by the system internally.

Show HN: Semantic geometry visual grounding for AI web agents (Amazon demo)

Hi HN,I’m a solo founder working on SentienceAPI, a perception &amp; execution layer that helps LLM agents act reliably on real websites.LLMs are good at planning steps, but they fail a lot when actually interacting with the web. Vision-only agents are expensive and unstable, and DOM-based automation breaks easily on modern pages with overlays, dynamic layouts, and lots of noise.My approach is...

( Read More... | 1 comment | on HN )