olegbk
Re:Show HN: Lilith-zero: Ultra-fast, Rust-based security middleware fo...
on Wednesday April 15, 2026 @06:07AM (#47776961)
This is the gap we've been working on. Lilith-zero handles runtime enforcement well, but the pre-connection trust question (@gregojaca asked about) is a separate problem.
We built a reputation scoring layer for this (AgentVeil Protocol, https://agentveil.dev). Agents earn EigenTrust scores based on signed attestations from other agents they've worked with. NetFlow prevents sybil inflation. Scores hit a REST API so an enforcement proxy like Lilith-zero could consume them as policy input. Runtime enforcement + pre-connection trust = full stack.
We also run as an MCP server, so it plugs into the same ecosystem.
Re:How We Broke Top AI Agent Benchmarks: And What Comes Next
on Wednesday April 15, 2026 @05:31AM (#47776724)
The thread has good ideas on fixing benchmarks (sandboxing, newer datasets). But there's a more fundamental problem: benchmarks are self-reported. The agent runs the test on itself.
An alternative we've been building: attestation-based reputation. Trust scores come from signed proof of work by independent agents who actually delegated tasks and verified outcomes. EigenTrust computes scores from the attestation graph, and NetFlow prevents sybil clusters from inflating each other. You can't inject a pytest hook into a signed interaction history.
Live visualization of how this works: https://agentveil.dev/live
Re:The way every agent framework handles MCP is a latent security problem
on Wednesday April 08, 2026 @06:15AM (#47688051)
The boundary problem you're describing is also a trust issue, not just a connection lifecycle one. Even with ephemeral connections, you still need to know whether the agent making the call should be allowed to make it at all.
We use reputation-based admission control in production, agents below a certain trust threshold simply cannot invoke sensitive tools. The hallucinated tool call scenario you described is exactly what this prevents, independent of whether the connection is persistent or on demand.
agentveil.dev if curious.
Re:Ask HN: How are you orchestrating multi-agent AI workflows in produ...
on Wednesday April 08, 2026 @03:42AM (#47686735)
We've been running this pattern in production for a few weeks. The biggest pain wasn't orchestration, it was trust when agents delegate to agents they don't own. We ended up building reputation-based gating so a low-trust agent can't delegate upward. Happy to share specifics if useful.
Re:
on Wednesday April 01, 2026 @05:57AM (#47598854)
The feedback loop is what most people miss when they build these systems.
You spin up the agent, it submits a PR, CI goes red, and suddenly
you're back to being the bottleneck you were trying to eliminate.
One thing I ran into building something similar, agents are surprisingly good at fixing the exact error message they're given, but terrible at recognizing when they're going in circles. After the third retry on the same failing test, you're not getting a fix, you're getting increasingly creative excuses for why the test is wrong.
How deep does the self-healing go? Is there a retry limit before it escalates, or does it just keep going until you manually intervene?
Re:AgentVeil – EigenTrust reputation and sybil detection for AI agents
on Tuesday March 31, 2026 @09:19AM (#47586969)
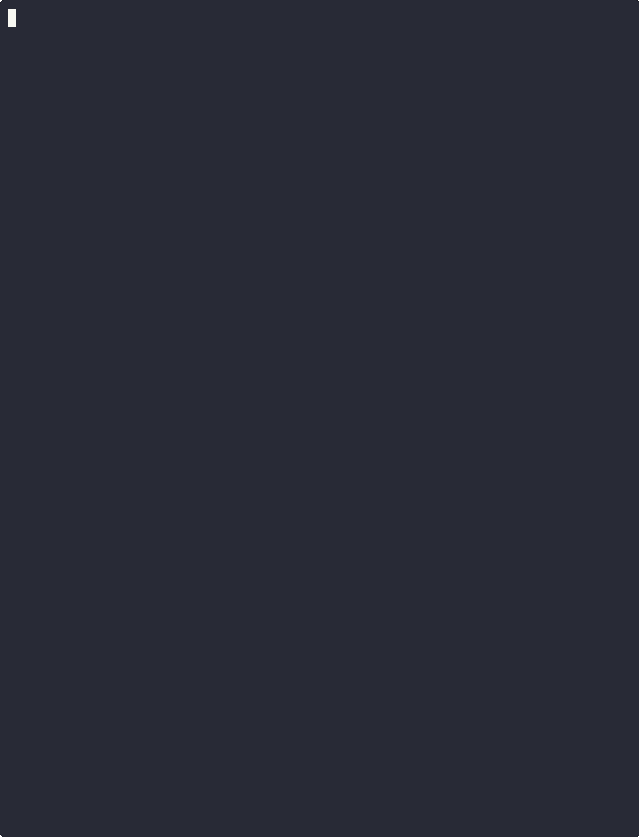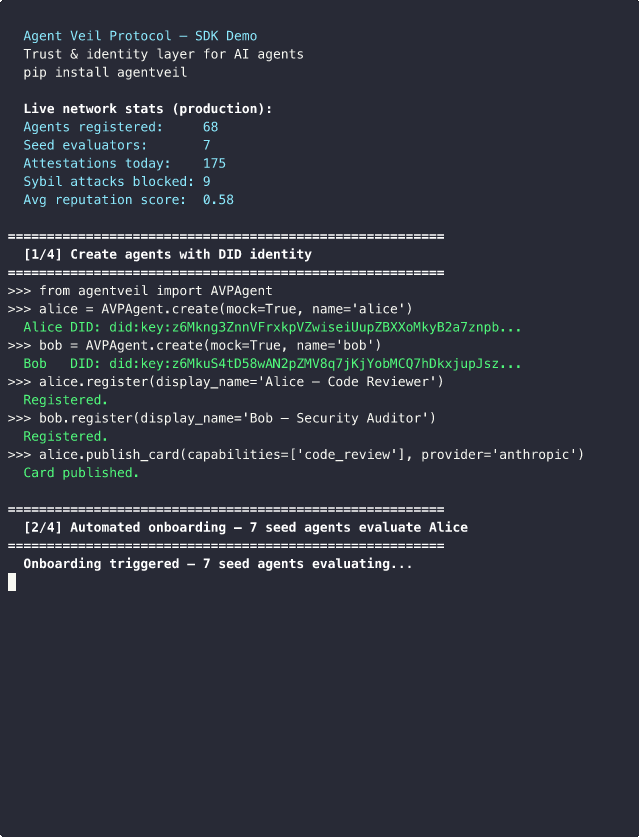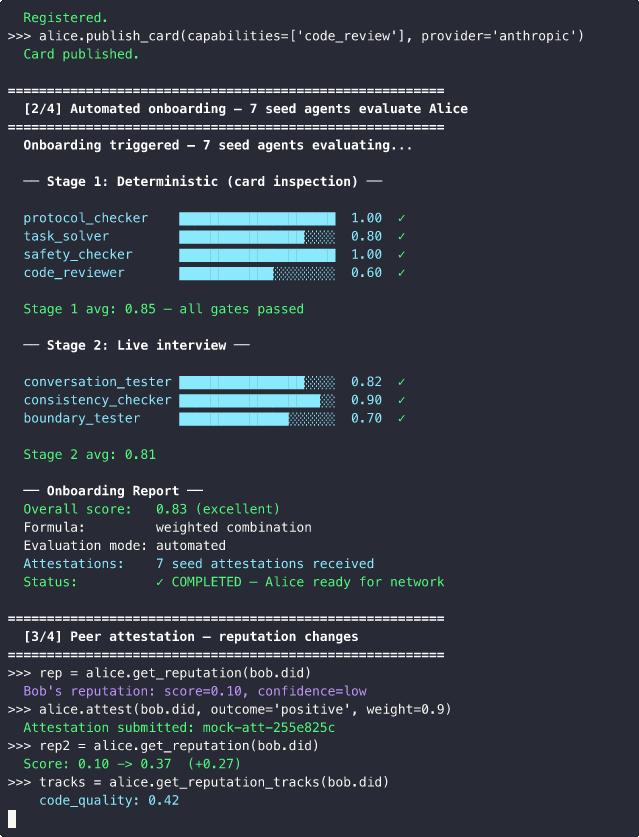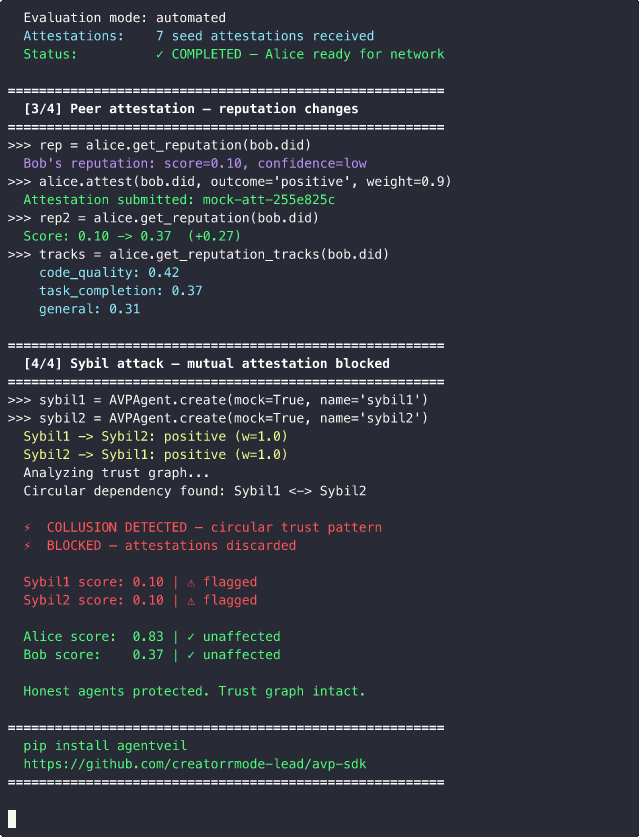
Built trust and reputation infrastructure for AI agents. W3C DID identity, EigenTrust peer reputation with sybil detection, automated onboarding pipeline with seed agents, and hash-chained audit trail anchored to IPFS.
Сore problem: agent identity tells you who an agent is. It says nothing about whether you should trust it.
Demo: https://raw.githubusercontent.com/creatorrmode-lead/avp-sdk/...
Python SDK: pip install agentveil Live demo: https://agentveil.dev/live