oh_no
oh_no on Hacker News
basically every single point here is wrong and most are easily refuted by looking at anthropic's s1
> this full release warrants a major reassessment.
I really don't think it does, the benchmark numbers are dreadful and the cost is higher than Sol. If you have to use an EU model knock yourself out but there are a ton of models that are a lot smarter for a lot less money.
based on Anthropic's S1 no one is serving models at a loss, but cutting your price to keep usage high makes a lot of sense when you have your inference booked for long periods.
AA has limited 1017 benchmarks so some terras versus 1017 Max:
max - 3 points smarter, 50% more expensive
xhigh - same score, 25% cheaper
high - 1 point dumber, 50% cheaper
I kind of expect them to go right to Astra 6.2, 6.1 was cancelled over the cybersecurity hubbub. I eagerly await either one.
the only confusing bit was dropping terra for a bit,
Luna (Small), Terra (Medium), Sol (Big), Astra (Bigger)
is perfectly clear, sol beats astra sometimes because Astra 6.1 was scrapped. and note that opus 5.5 beats fable 5.1 most of the time too without a skipped model.
yes but going back to 2019 staffing with 2026 revenue is a pretty seismic shift
sol 6.1 is wildly cheaper, one reason to use something else
day 1 benchmarks had that for opus and i think also astra but updated numbers have smoothed that out. i can't say for sure what all changed between early runs and now but it seems like max is now the most powerful mode for both models.
that said, with a clock on this benchmark it's very possible that lower reasoning = more iteration = better code.
also a mess on desktop firefox
i mean we use max benchmarks because they have the best coverage, which sucks because very few people use max day to day, but it's what we have. the performance curve is generally pretty similar across models and effort levels, weird outliers are pretty weird. max is generally a big cost bump from most providers (less so from OpenAI)
AA shows Luna at 1/4 the price, 1 point behind on intelligence matrix with a 38.
Haiku 5.5 is 23% cheaper with a 4 point intelligence lead.
I'm on subscription usage so I can't compare Flash 4.1 to them directly but the OP has his head up his ass if he thinks Opus 5.5 is the best point of comparison. Why is anyone using Opus if the new Haiku is indistinguishable /s
Just absolutely terrible post, admits to using Opus for review but claims its intelligence isn't needed, why aren't you using Haiku or Sonnet then?
Luna is 1 point being on AA's index at 1/4 the cost, yes it "doesn't score as well" but paying 4x for 1 point is crazy if you're going off benchmarks.
AA has Haiku 5.5 as cheaper than 4.1 Flash (both on Max, which isn't ideal but what can ya do) and a 4 point intelligence gap.
Why do people like to think open models are more competitive than they are?
then just ask for text-only?
no AA benchmarks yet and the last chart in the announcement makes Haiku look useless vs new Sonnet pricing, interesting to see what 3rd party benchmarks show because i think Anthropic are costpertaskmaxxing here and it's going to look more like that bottom chart than the top ones.
I'm seeing a lot of this and it makes no sense, the internal model solved these but give one of the papers to Astra and Opus and I'm sure it will have no problem recreating it.
no, they did not steal the notes of 100s of people working on these 100s of problems, be serious
yeah and this isn't a long term solution, stand this up, see what value you get out of it, and in a few months you cans witch to whatever the best decision model is
I think releasing something like this makes sense even if it's underbaked, it's still very cheap, and if you have existing enterprise OpenAI relationship it's a lot easier to onboard something like this than set up a new Jev contract.
How these models play out is an open question but existing provider contracts and T&C are important for enterprise.
Yeah, very similar benchmarks at 1/4 the price. I've been pretty happy with Luna 6 though I still think the gap between small and frontier models is larger than many people want to admit.
> Impressive vision benchmarking. If the vision model is truly as good as astra, that would make it best in the world.
Sure, it leads in one unpopular benchmark with internal numbers.
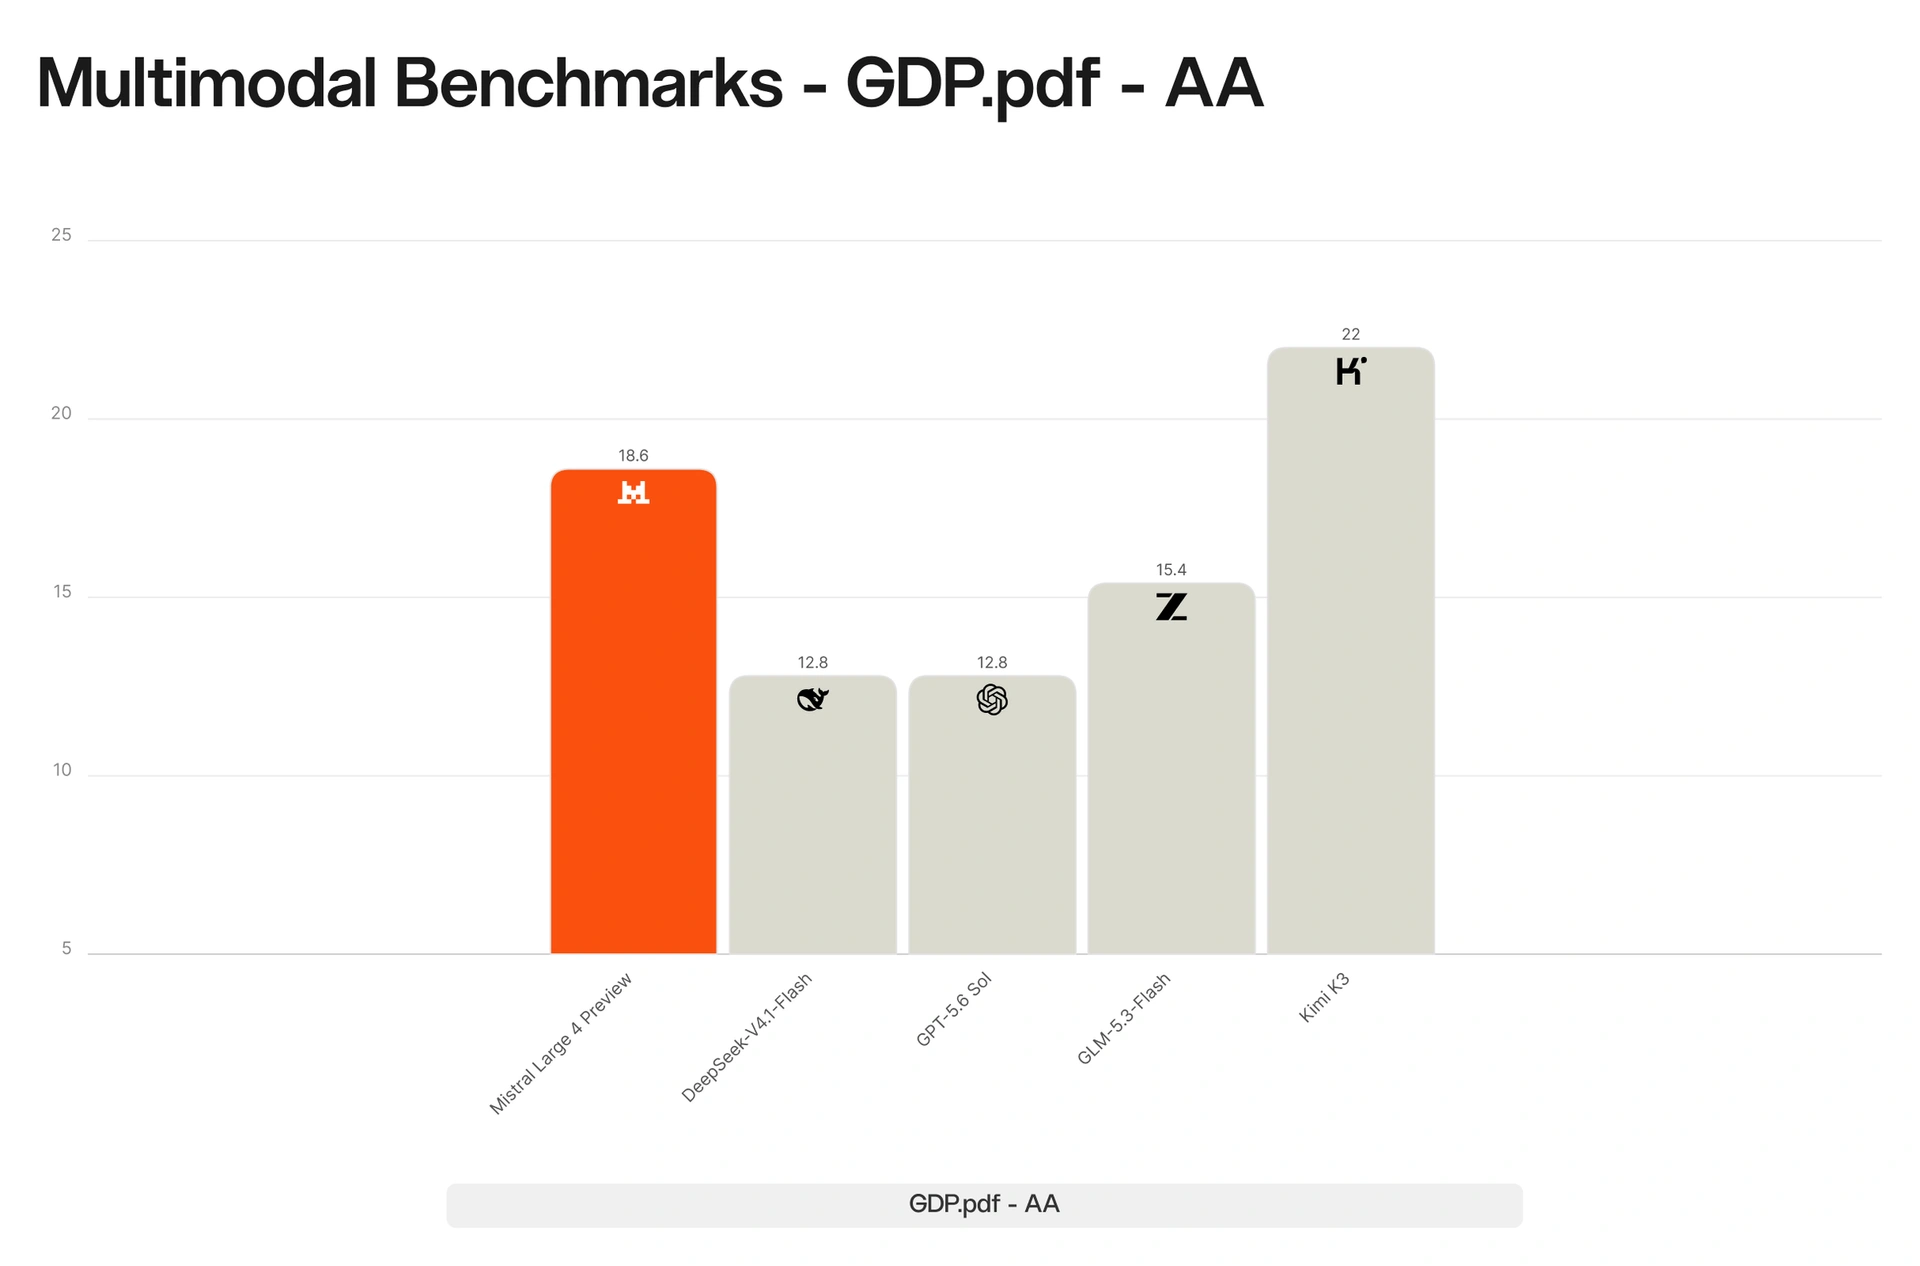
But look at the third benchmark. It only has Sol 5.6 from OpenAI and it shows a 12.8. I don't know this benchmark but AA's GDP.pdf listing has Sol 5.6 Max at a 27, even non-reasoning beats the 12.8. It's extremely weird to cherry pick Sol 5.6 and then also lie about the published third party benchmark score. I'd love AI companies to stop lying about this stuff.
AA - https://artificialanalysis.ai/evaluations/gdp-pdf?models=cla...
Mistral announcement - https://mistral.ai/_astro/multimodal-benchmarks---gdp.pdf---...
you don't explain the advantage of workers over pages for a static site
i've done this several times recently
however now i just have agent do it with CLI and that works well and I don't have to find the secret link
yeah it's 100% the wrong move for them to make, I think there is probably a lot of value in AI driving Figma, and if I can't do that, Figma will fall out of the ecosystem.
i believe they've got inference issue. the phone app never got past 3.6, and they're going to roll this out to Ultra subscribers before other subscribers. none of this screams they're ready to flip a switch and start serving a ton of traffic as OpenAI/Anthropic routinely do.
nothing about this announcement gives me confidence that google is back on track as a model provider.
3.8 flash is more expensive than sol 6.0, google uses a LOT of reasoning tokens
Sol 6 is in there? You may be on Enterprise where it didn't roll out by default and comes out in a week or so. (Which is a weird and bad change to their model releases.)
i'd love to see them re-enter that space but given haiku 5 never happened I wouldn't bet on it
i think they see what openai charges for luna and just don't want to try and compete
it could be that, it could also be that sonnet max looks to burn about 60% more tokens than opus max
AA intelegence index (agent harness doesn't have sonnet data yet) on max:
Astra 27k
Fable 5.1 78k
(Sonnet 5) 118k
Opus 5.5 119k
Sonnet 5.5 193k
Opus 5 was previous record holder so hats off to Anthropic on blowing it away on token churn.