nee1r
Re:I’m leaving OpenAI to build telepathy
on Wednesday August 05, 2026 @12:49PM (#49185421)
are you specifically focused on non-invasive methods/why? seems like you reach a noise barrier which limits things like this
Re:A General Goal-Conditioned Minecraft Model
on Wednesday July 15, 2026 @02:04PM (#48924801)
how do you pick good goal conditioning images/do you have to hand pick a dataset of good goal images? seems hard if you don't have full context. really cool though!
Re:The first general computer action model
on Thursday February 26, 2026 @01:45AM (#47162710)
thanks! a lot of credit to the people who helped write/edit
Re:The first general computer action model
on Thursday February 26, 2026 @01:44AM (#47162706)
giving back to the research community! releasing and talking about research helps everyone
Re:The first general computer action model
on Thursday February 26, 2026 @01:43AM (#47162699)
thanks! i definitely love diffusion + pushed for it, as a non-causal generative method i think its pretty unique
Re:The first general computer action model
on Thursday February 26, 2026 @01:42AM (#47162695)
thanks! got a lot of inspiration from VPT https://arxiv.org/abs/2206.11795 is a great paper, would recommend a read
we all have various backgrounds, me particularly i did a lot of material science x ai research and just fundamental architecture research before
Re:The first general computer action model
on Wednesday February 25, 2026 @08:51PM (#47160779)
we have an alignment blog post dropping soon! scaling up in the next couple of months, then hopefully opening up an API or licensing it.
Benchmarks are really fun—lots of secret ones. Our main thesis is that you should be using the same benchmarks to measure human ability to use a computer, as you would an AI model. Definitely a suite of continuous long term planning tasks (games) and things such as marking emails as spam etc.
definitely! we are looking into more interp + visualizations in general as we scale up.
Re:The first general computer action model
on Wednesday February 25, 2026 @08:19PM (#47160572)
planning on instruct tuning soon!
Re:The first general computer action model
on Wednesday February 25, 2026 @08:19PM (#47160570)
safety was important for the demo, the model didn't have access to the brake or accelerator.
Re:The first general computer action model
on Wednesday February 25, 2026 @08:18PM (#47160557)
thanks! the math and architecture of the FDM (no video encoder) is pretty simple, its a regular transformer with next-token predictions but with frames interleaved.
Re:The first general computer action model
on Wednesday February 25, 2026 @08:17PM (#47160547)
yeah! i love the BCO paper, i think its extremely intuitive and these methods are really interesting in a time where data without labels is abundant. i especially like the idea of iteratively making the inverse dynamics better—might lean closer to that in the future
Re:The first general computer action model
on Wednesday February 25, 2026 @08:14PM (#47160517)
cool thanks for the title idea!! hopefully when we scale up in the next month/two we can update the community
Re:The first general computer action model
on Wednesday February 25, 2026 @08:13PM (#47160502)
collected! no synthetic
Re:The first general computer action model
on Tuesday February 24, 2026 @12:48PM (#47140139)
thanks! the inverse dynamics model is trained first on 40k hours of data and then frozen to label all 11 million hours. yup! the idea is that it should take a small amount of data to generalize environment dynamics, then you can use a lot of data to understand actions.
Re:The first general computer action model
on Tuesday February 24, 2026 @12:46PM (#47140117)
real
Re:The first general computer action model
on Monday February 23, 2026 @01:45PM (#47126804)
this is honestly an issue for the inverse dynamics (for app specific shortcuts etc.) but for general UI learning we still see promising eval trends
Re:The first general computer action model
on Monday February 23, 2026 @01:31PM (#47126573)
no finetuning data for the blender task! we actually think its the opposite, there are a lot of video tutorials for complex tasks like onshape/blender/fusion360 but not as much of people idly browsing.
but also at the 11M hour scales it still sees a substantial amount of data
Re:The first general computer action model
on Monday February 23, 2026 @12:27PM (#47125479)
i actually drove the car (with arrow keys) around south park for around ~45 minutes as finetuning data, no extra labelling other than that. think the car line graph is super cool because you actually see the videegame prior working
Re:The first general computer action model
on Monday February 23, 2026 @12:15PM (#47125292)
the main chain of experiments was trying causal => non-causal => non-causal with ctc and CE. i think a good intuition here is that you need a generative approach fundamentally because there definitely are multiple correct IDM labels.
Re:The first general computer action model
on Monday February 23, 2026 @12:14PM (#47125267)
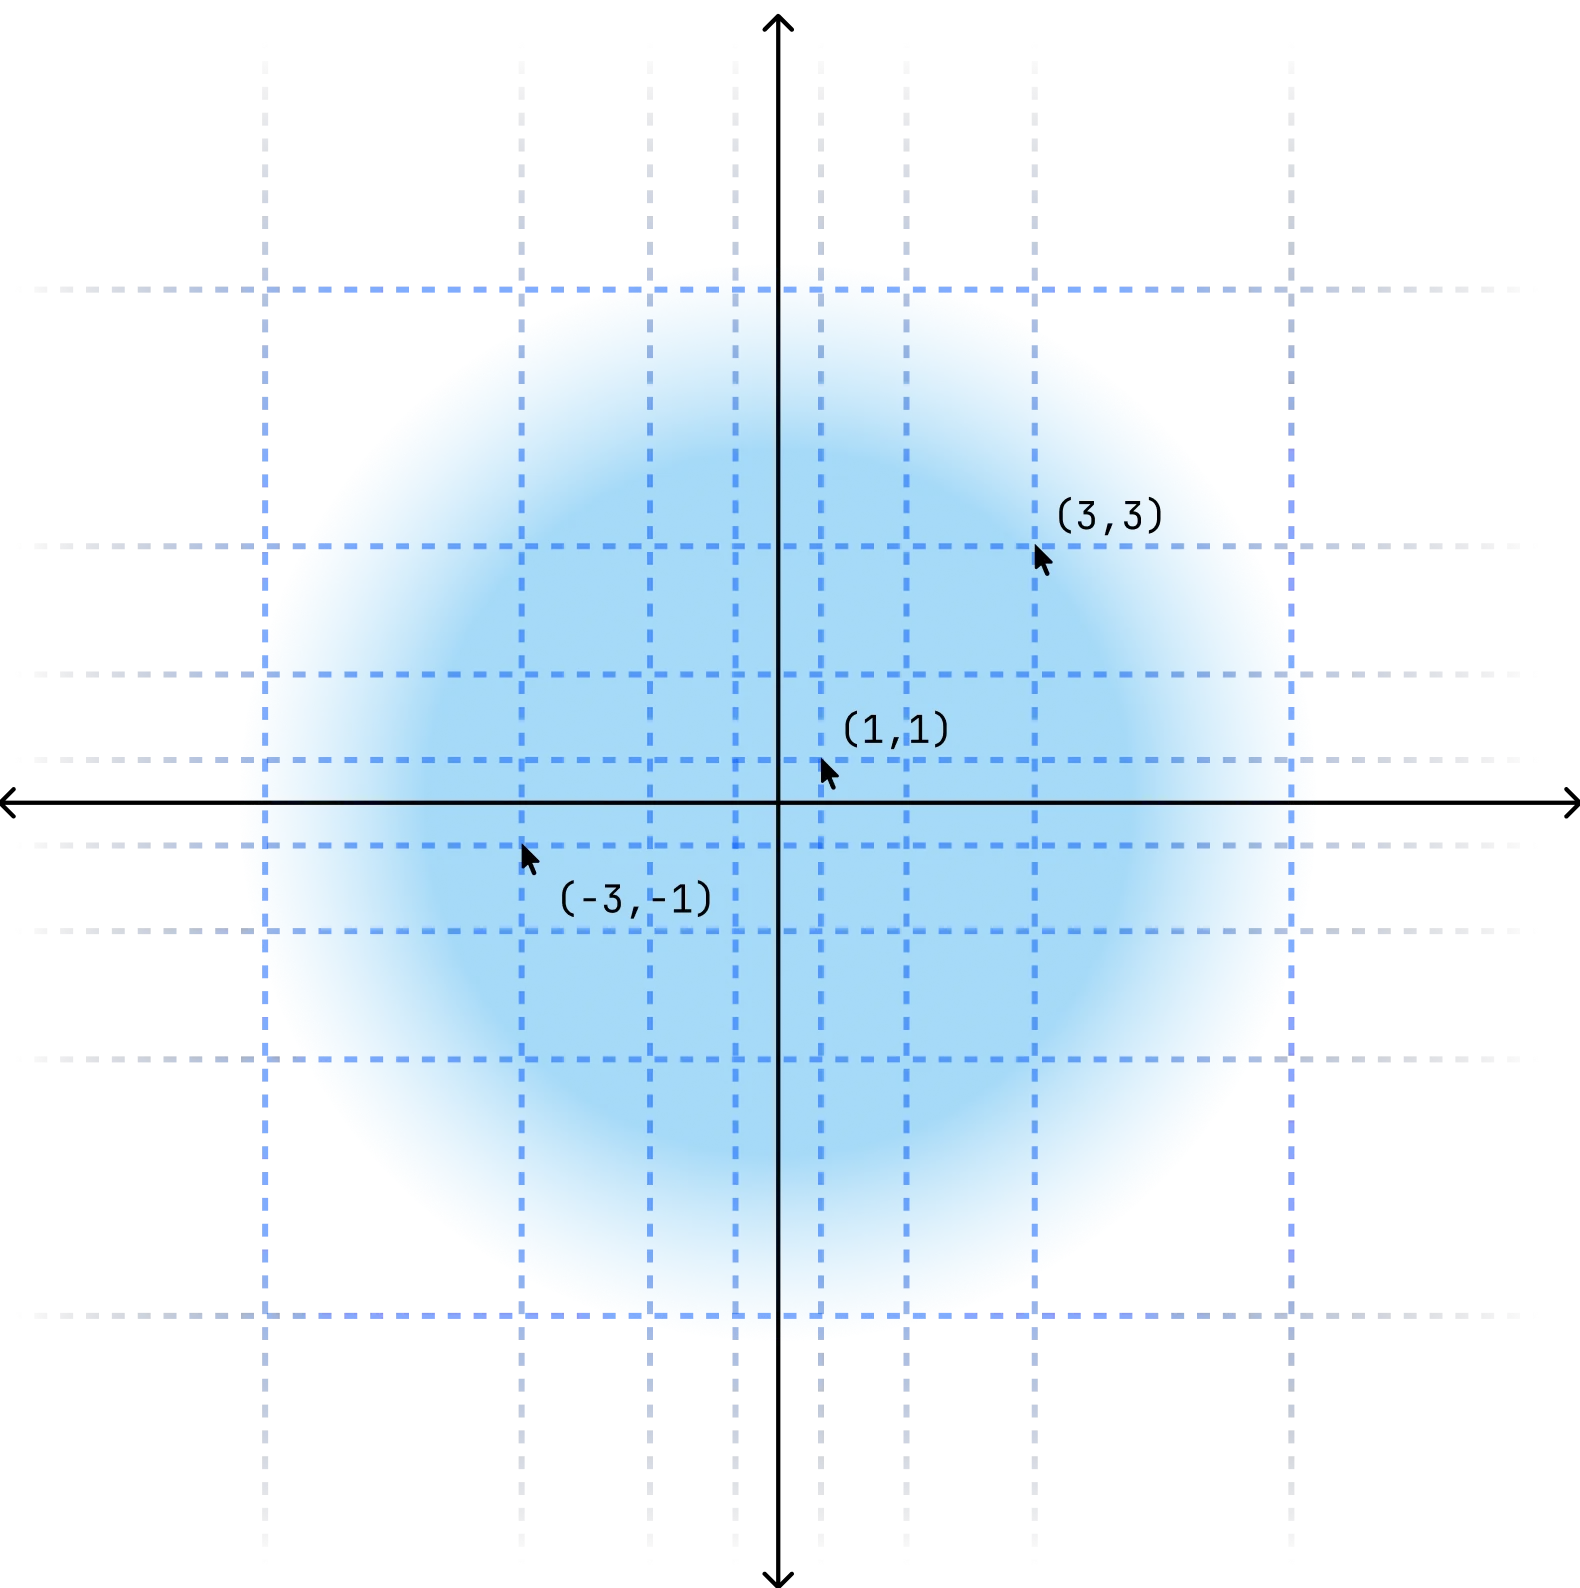
good question! we use exponential binning (map the mouse movements onto a plane with exponentially increasing tick marks https://si.inc/fdm1/exponential_binning.webp) but tried a bunch of other methods (linear creates too many tokens for the model to learn well). Polar coordinates seem like a better solution but empirically didn't work well because the tokens got too coarse too fast.
Re:The first general computer action model
on Monday February 23, 2026 @12:10PM (#47125201)
Hey guys! I’m Neel, been holed up in our south park office for the past year working on model training. excited to share our research!
This is a preview of a very different type of computer use model—we train on the internet. Specifically we have 11 million hours of computer video stored on our storage cluster (previously shared https://news.ycombinator.com/item?id=45438496 !) and the model can work in 30 FPS. Since we match the fundamental form factor of computer-use, we can get our model to do CAD, browse websites, and even drive a car using arrow keys. I’m super excited to see what our model can do as we scale more, it's a fun frontier to work on (not language models :) ).
The team and I will be online responding to the comments, so drop any questions.
Re:The Delete Act
on Wednesday December 31, 2025 @08:51PM (#46450482)
glad the timelines are short and hope its user friendly
Re:Pantograph: Building a Preschool for Robots
on Tuesday December 23, 2025 @04:09PM (#46369490)
how are you planning on getting the robots to learn a base policy from scratch? seems hard without a base model
Re:Jmail: Gmail except it's Epstein Files
on Sunday December 21, 2025 @05:09AM (#46343713)
being able to search through the files when they're purposefully so obfuscated is great
Re:Energy Predictions 2025 – Casey Handmer's blog
on Monday December 08, 2025 @04:28PM (#46197882)
hmmm wonder if decosting is actually linear vs. discrete jumps in ability (ie. we might just nail fusion or boosts in efficiency)
We collected 10k hours of neuro-language data in our basement
Re:Nobel Prize in Chemistry 2025
on Wednesday October 08, 2025 @01:16PM (#45518413)
Love MOFs! Did research about MOFs <=> language modeling a couple years ago and I'm excited to see them getting more coverage https://arxiv.org/abs/2311.07617
Re:Building a 30 PB storage cluster in the heart of SF
on Wednesday October 01, 2025 @09:29PM (#45445528)
We have a custom barebones solution that uses a hashring to route the files!
Re:Building a 30 PB storage cluster in the heart of SF
on Wednesday October 01, 2025 @09:28PM (#45445526)
We use the same nginx rust server to do file writes, it's done via web requests