nabakin
Re:A statement on the Tor Project's relationship with Mullvad
on Friday October 09, 2026 @05:18PM (#50026673)
Re:Jamesob's guide to running SOTA LLMs locally
on Friday July 03, 2026 @03:52PM (#48779207)
Are you running qwen3.6-27b on one 3090 with your KV cache at q4? Ime there is significant long-context recall accuracy degradation at that precision. I prefer putting the KV cache at q8 and working with the 120k context
Re:U.S. DOJ demands Apple and Google unmask over 100k users of car-tin...
on Friday May 15, 2026 @05:29PM (#48154149)
Then you can sandbox
Re:DeepSeek v4
on Sunday April 26, 2026 @08:39AM (#47909849)
I think they were mistaken or maybe they were just referring to inference because I don't see anyone making that claim and it would be quite the news.
Re:DeepSeek v4
on Friday April 24, 2026 @08:38PM (#47897500)
Probably because you said you used DeepSeek. People don't want to see AI in the comments and don't trust AI responses.
Re:DeepSeek v4
on Friday April 24, 2026 @02:01PM (#47893719)
Yes, that's the footnote from citation [5].
Re:DeepSeek v4
on Friday April 24, 2026 @12:55PM (#47892830)
> Also, note that there's zero CUDA dependency. It runs entirely on Huawei chips.
That is a huge claim to make with no evidence.
I researched what you said, and I have found no statement to that effect in their paper[0], on huggingface[1], twitter[2], WeChat[3], or in their news release[4].
They only mention as a footnote in only the Chinese version of their news release that they plan to reduce inference costs with the Ascend 950 supernode when it releases[5]. The only mention of Huawei in their paper is that they validated a technique to lower interconnect bandwidth on Ascend NPUs and Nvidia GPUs[6].
[0] https://huggingface.co/deepseek-ai/DeepSeek-V4-Pro/blob/main...
[1] https://huggingface.co/deepseek-ai/DeepSeek-V4-Pro
[2] https://xcancel.com/deepseek_ai/status/2047516922263285776
[3] https://mp.weixin.qq.com/s/8bxXqS2R8Fx5-1TLDBiEDg
[4] https://api-docs.deepseek.com/news/news260424
[5] https://api-docs.deepseek.com/zh-cn/img/v4-price.png
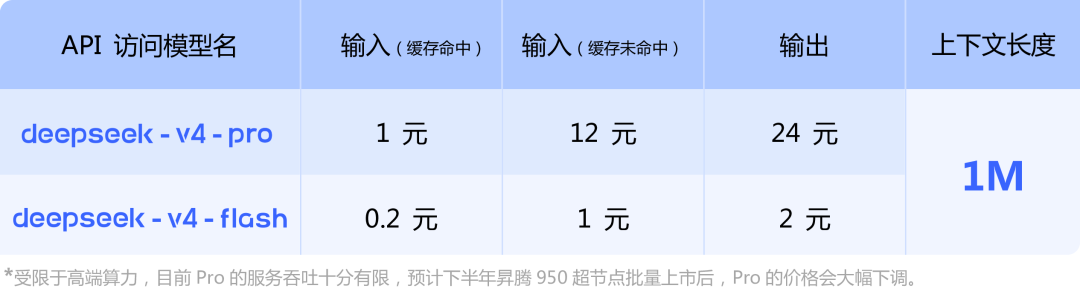
[6] Page 16
Re:NIST scientists create 'any wavelength' lasers
on Saturday April 18, 2026 @08:14PM (#47820684)
> When it comes to information transfer and processing, light can do things that electricity can’t. Photons — particles of light — are far zippier than electrons at working their way through circuits.
Electrons themselves don't move at the speed of light, but communication via electrons does happen close to the speed of light.
A subtle but important distinction that's often confused.
Re:Google releases Gemma 4 open models
on Thursday April 02, 2026 @04:55PM (#47620051)
Dunno but there's a PR for it. Probably also more performant than Modular.
Re:Google releases Gemma 4 open models
on Thursday April 02, 2026 @03:34PM (#47619130)
If OP meant they have the fastest implementation of Gemma 4 on Blackwell at the moment, I guess that is technically true. I doubt that will hold up when TensorRT-LLM finishes their implementation though.
Re:Google releases Gemma 4 open models
on Thursday April 02, 2026 @03:30PM (#47619074)
I know Arc AGI 2 has a private test set and they have a good amount of results[0] but it's not a conventional benchmark.
Looking around, SWE Rebench seems to have decent protection against training data leaks[1]. Kagi has one that is fully private[2]. One on HuggingFace that claims to be fully private[3]. SimpleBench[4]. HLE has a private test set apparently[5]. LiveBench[6]. Scale has some private benchmarks but not a lot of models tested[7]. vals.ai[8]. FrontierMath[9]. Terminal Bench Pro[10]. AA-Omniscience[11].
So I guess we do have some decent private benchmarks out there.
[0] https://arcprize.org/leaderboard
[1] https://swe-rebench.com/about
[2] https://help.kagi.com/kagi/ai/llm-benchmark.html
[3] https://huggingface.co/spaces/DontPlanToEnd/UGI-Leaderboard
[7] https://labs.scale.com/leaderboard
[9] https://epoch.ai/frontiermath/
[10] https://github.com/alibaba/terminal-bench-pro
[11] https://artificialanalysis.ai/articles/aa-omniscience-knowle...
Re:Google releases Gemma 4 open models
on Thursday April 02, 2026 @02:00PM (#47617896)
It's easy to game and human evaluation data has its trade-offs, but it's way easier to fake public benchmark results. I wish we had a source of high quality private benchmark results across a vast number of models like Lmarena. Having high quality human evaluation data would be a plus too.
Re:Google releases Gemma 4 open models
on Thursday April 02, 2026 @01:43PM (#47617646)
Faster than TensorRT-LLM on Blackwell? Or do you not consider TensorRT-LLM open source because some dependencies are closed source?
Re:Google releases Gemma 4 open models
on Thursday April 02, 2026 @01:17PM (#47617258)
It's referring to the Lmsys Leaderboard/Lmarena/Arena.ai[0]. It's very well-known in the LLM community for being one of the few sources of human evaluation data.
Re:Google releases Gemma 4 open models
on Thursday April 02, 2026 @01:00PM (#47617034)
Public benchmarks can be trivially faked. Lmarena is a bit harder to fake and is human-evaluated.
I agree it's misleading for them to hyper-focus on one metric, but public benchmarks are far from the only thing that matters. I place more weight on Lmarena scores and private benchmarks.
Re:Big Data on the Cheapest MacBook
on Thursday March 12, 2026 @12:16PM (#47353103)
And nowadays we have Debian running in a VM on Android [1]
[1] https://www.zdnet.com/article/how-to-use-the-new-linux-termi...
Re:Apple Introduces MacBook Pro with All‑New M5 Pro and M5 Max
on Tuesday March 03, 2026 @11:49AM (#47235140)
I would consider it reasonable if this was 4x TTFT and Throughput, but it seems like it's only for TTFT.
Re:Tesla kills Autopilot, locks lane-keeping behind $99/month fee
on Friday January 23, 2026 @03:11PM (#46737241)
And right to repair
Re:JetBlue flight averts mid-air collision with US Air Force jet
on Tuesday December 16, 2025 @01:02PM (#46291868)
Ty this is great
Re:JetBlue flight averts mid-air collision with US Air Force jet
on Monday December 15, 2025 @09:39PM (#46284104)
TIL Europe still has some presence in the Americas. Thought all of that was gone with the Monroe Doctrine
Re:France threatens GrapheneOS with arrests / server seizure for refus...
on Monday November 24, 2025 @05:11PM (#46039997)
Fyi it doesn't look like this post is listed on the frontpage anymore, even with the points it has. Not sure if it's intentional
Re:France threatens GrapheneOS with arrests / server seizure for refus...
on Monday November 24, 2025 @05:00PM (#46039913)
Ty!
Re:France threatens GrapheneOS with arrests / server seizure for refus...
on Monday November 24, 2025 @12:34PM (#46036675)
I understand they are similar, but I think this post adds new information to the situation. Regardless, appreciate your help moderating the site.
Re:France threatens GrapheneOS with arrests / server seizure for refus...
on Monday November 24, 2025 @12:17PM (#46036421)
Oops, that's correct, ty
Re:France threatens GrapheneOS with arrests / server seizure for refus...
on Monday November 24, 2025 @12:00PM (#46036218)
Google Translate link:
https://translate.google.com/translate?tl=en&hl=en&u=https:/...
Additional context:
https://grapheneos.social/deck/@GrapheneOS/11557599710445618... https://grapheneos.social/@GrapheneOS/115583866253016416 https://grapheneos.social/@[email protected]/11558177594... https://grapheneos.social/@GrapheneOS/115589833471347871 https://grapheneos.social/@GrapheneOS/115594002434998739
France threatens GrapheneOS with arrests / server seizure for refusing backdoors
Re:France threatens GrapheneOS with arrests / server seizure for refus...
on Monday November 24, 2025 @11:40AM (#46035979)
This is a better link from a French privacy non-profit but I can't change it now: https://mamot.fr/@LaQuadrature/115581775965025042
@dang or other mods, could you change it?
I created a separate thread for the new link: https://news.ycombinator.com/item?id=46036217
Google Translate link:
https://translate.google.com/translate?tl=en&hl=en&u=https:/...
Additional context:
https://grapheneos.social/deck/@GrapheneOS/11557599710445618...
https://grapheneos.social/@GrapheneOS/115583866253016416
https://grapheneos.social/@[email protected]/11558177594...
Re:Steam Frame
on Wednesday November 12, 2025 @04:29PM (#45907004)
I haven't bought a VR headset since the Oculus Rift CV1, but this might do it for me
Re:Steam Frame
on Wednesday November 12, 2025 @04:23PM (#45906930)
I don't think a lot of people realize how big of a deal this is. You used to have to choose between wireless and slow or wired and fast. Now you can have both wireless and fast. It's insane.